Compare commits
139 Commits
bug/5671
...
update-3.0
| Author | SHA1 | Date | |
|---|---|---|---|

|
190a68550a | ||
|
|
548823be83 | ||
|
|
a6f7f5dc62 | ||
|
|
f308ea1a31 | ||
|
|
c3f4a028bf | ||
|
|
8e97db2dc5 | ||
|
|
009b80c95a | ||
|
|
a889b62c50 | ||
|
|
084625cb3c | ||
|
|
458df8f4f4 | ||
|
|
73456b0048 | ||
|
|
d491e9f9b2 | ||
|
|
052595ffbf | ||
|
|
cc2ac23c0d | ||
|
|
5a8bc19384 | ||
|
|
0380ac5893 | ||
|
|
9881be25f3 | ||
|
|
9174925916 | ||
|
|
02031e3e14 | ||
|
|
84dc6b66da | ||
|
|
35fc2b387f | ||
|
|
be2f92b9e3 | ||
|
|
64b66b6409 | ||
|
|
5a65a0dab1 | ||
|
|
3046a1eb54 | ||
|
|
a52fe6586c | ||
|
|
f239fe754d | ||
|
|
1003fdf0f2 | ||
|
|
033dfc165d | ||
|
|
bfb202527d | ||
|
|
60339d17ee | ||
|
|
8e07dae0fd | ||
|
|
b22833ce2a | ||
|
|
b8a87e00d7 | ||
|
|
56dd77fc52 | ||
|
|
250b3e5c8c | ||
|
|
efcbe93075 | ||
|
|
b26f4c7f58 | ||
|
|
16bbc7478f | ||
|
|
85a29f1da0 | ||
|
|
241f2b2a6b | ||
|
|
195d628d31 | ||
|
|
7b76bd5866 | ||
|
|
0b4302bb2b | ||
|
|
354ac7ecad | ||
|
|
3bb25a1e0b | ||
|
|
eff932627c | ||
|
|
084fb05d52 | ||
|
|
f554ec7987 | ||
|
|
f1a707d191 | ||
|
|
78fe2f738c | ||
|
|
500dc75c8c | ||
|
|
c7e5c0d2b7 | ||
|
|
4dae8de815 | ||
|
|
ba7c464a03 | ||
|
|
e237a60add | ||
|
|
84d99f01f5 | ||
|
|
973a7b1cd0 | ||
|
|
cfd898fb93 | ||
|
|
7f88aca8f7 | ||
|
|
e70ad25ca1 | ||
|
|
35bdfc78c9 | ||
|
|
5a41febce2 | ||
|
|
233a5da664 | ||
|
|
563d6572f3 | ||
|
|
5f941b3583 | ||
|
|
55e511dd10 | ||
|
|
713f56ea53 | ||
|
|
3d2b337906 | ||
|
|
b2f6173a38 | ||
|
|
2b2a07e3b7 | ||
|
|
715830fe21 | ||
|
|
adb577d5b8 | ||
|
|
569601e233 | ||
|
|
c418c4c4aa | ||
|
|
fd4332916f | ||
|
|
deada71526 | ||
|
|
ed07583f7e | ||
|
|
ecfb85f85e | ||
|
|
9fc765638f | ||
|
|
41fc9ebff7 | ||
|
|
e988e22d0f | ||
|
|
eab12fa029 | ||
|
|
8f33e56c0d | ||
|
|
8000def20c | ||
|
|
c26e82ed87 | ||
|
|
e68dd5dca0 | ||
|
|
a3532632af | ||
|
|
5530091b86 | ||
|
|
d185a40aaf | ||
|
|
aedc0e515d | ||
|
|
b644af0ec7 | ||
|
|
0acbf2b91d | ||
|
|
09ecb718ae | ||
|
|
e668a09490 | ||
|
|
7977cd9808 | ||
|
|
7a2b20cb53 | ||
|
|
4e880b5bbe | ||
|
|
a94b3e4513 | ||
|
|
d9b1cac867 | ||
|
|
14b6f6fad8 | ||
|
|
20ca527751 | ||
|
|
c270845a46 | ||
|
|
d6538d7034 | ||
|
|
0e51e48473 | ||
|
|
789227f5a9 | ||
|
|
be83be2457 | ||
|
|
0d8f38a403 | ||
|
|
66eedec782 | ||
|
|
4dfe7a4885 | ||
|
|
0f930d99f2 | ||
|
|
a0b7bdd187 | ||
|
|
ad4d87437a | ||
|
|
2ce700f9a2 | ||
|
|
d4eb2e9ce1 | ||
|
|
4b60bd4d7b | ||
|
|
c44fb99633 | ||
|
|
5da8a34277 | ||
|
|
6dff2bb71c | ||
|
|
26cf9abfd6 | ||
|
|
d1871fabe9 | ||
|
|
45f110b52d | ||
|
|
1881851e50 | ||
|
|
f8d2fb83a3 | ||
|
|
0c14e84c82 | ||
|
|
ea1cbb3a1d | ||
|
|
aa8c8f3983 | ||
|
|
1024441aee | ||
|
|
9c5ce48ca5 | ||
|
|
f351c1b687 | ||
|
|
91eebb1fb0 | ||
|
|
038b61477c | ||
|
|
4294400733 | ||
|
|
8c4d4f1af3 | ||
|
|
4aa4f82b37 | ||
|
|
ff8153d9c5 | ||
|
|
50a65a7415 | ||
|
|
636b946af5 | ||
|
|
52bc2e57c0 |
1
.github/FUNDING.yml
vendored
@@ -1 +0,0 @@
|
||||
custom: ['https://www.python.org/psf/sponsorship/']
|
||||
34
.github/ISSUE_TEMPLATE/Bug_report.md
vendored
@@ -1,34 +0,0 @@
|
||||
---
|
||||
name: Bug report
|
||||
about: Create a report to help us improve
|
||||
|
||||
---
|
||||
|
||||
Summary.
|
||||
|
||||
## Expected Result
|
||||
|
||||
What you expected.
|
||||
|
||||
## Actual Result
|
||||
|
||||
What happened instead.
|
||||
|
||||
## Reproduction Steps
|
||||
|
||||
```python
|
||||
import requests
|
||||
|
||||
```
|
||||
|
||||
## System Information
|
||||
|
||||
$ python -m requests.help
|
||||
|
||||
```
|
||||
<paste here>
|
||||
```
|
||||
|
||||
This command is only available on Requests v2.16.4 and greater. Otherwise,
|
||||
please provide some basic information about your system (Python version,
|
||||
operating system, &c).
|
||||
7
.github/ISSUE_TEMPLATE/Custom.md
vendored
@@ -1,7 +0,0 @@
|
||||
---
|
||||
name: Request for Help
|
||||
about: Guidance on using Requests.
|
||||
|
||||
---
|
||||
|
||||
Please refer to our [Stack Overflow tag](https://stackoverflow.com/questions/tagged/python-requests) for guidance.
|
||||
7
.github/ISSUE_TEMPLATE/Feature_request.md
vendored
@@ -1,7 +0,0 @@
|
||||
---
|
||||
name: Feature request
|
||||
about: Suggest an idea for this project
|
||||
|
||||
---
|
||||
|
||||
Requests is not accepting feature requests at this time.
|
||||
93
.github/SECURITY.md
vendored
@@ -1,93 +0,0 @@
|
||||
# Vulnerability Disclosure
|
||||
|
||||
If you think you have found a potential security vulnerability in
|
||||
requests, please email [Nate](mailto:nate.prewitt@gmail.com)
|
||||
and [Seth](mailto:sethmichaellarson@gmail.com) directly.
|
||||
**Do not file a public issue.**
|
||||
|
||||
Our PGP Key fingerprints are:
|
||||
|
||||
- 8722 7E29 AD9C FF5C FAC3 EA6A 44D3 FF97 B80D C864 ([@nateprewitt](https://keybase.io/nateprewitt))
|
||||
|
||||
- EDD5 6765 A9D8 4653 CBC8 A134 51B0 6736 1740 F5FC ([@sethmlarson](https://keybase.io/sethmlarson))
|
||||
|
||||
You can also contact us on [Keybase](https://keybase.io) with the
|
||||
profiles above if desired.
|
||||
|
||||
If English is not your first language, please try to describe the
|
||||
problem and its impact to the best of your ability. For greater detail,
|
||||
please use your native language and we will try our best to translate it
|
||||
using online services.
|
||||
|
||||
Please also include the code you used to find the problem and the
|
||||
shortest amount of code necessary to reproduce it.
|
||||
|
||||
Please do not disclose this to anyone else. We will retrieve a CVE
|
||||
identifier if necessary and give you full credit under whatever name or
|
||||
alias you provide. We will only request an identifier when we have a fix
|
||||
and can publish it in a release.
|
||||
|
||||
We will respect your privacy and will only publicize your involvement if
|
||||
you grant us permission.
|
||||
|
||||
## Process
|
||||
|
||||
This following information discusses the process the requests project
|
||||
follows in response to vulnerability disclosures. If you are disclosing
|
||||
a vulnerability, this section of the documentation lets you know how we
|
||||
will respond to your disclosure.
|
||||
|
||||
### Timeline
|
||||
|
||||
When you report an issue, one of the project members will respond to you
|
||||
within two days *at the outside*. In most cases responses will be
|
||||
faster, usually within 12 hours. This initial response will at the very
|
||||
least confirm receipt of the report.
|
||||
|
||||
If we were able to rapidly reproduce the issue, the initial response
|
||||
will also contain confirmation of the issue. If we are not, we will
|
||||
often ask for more information about the reproduction scenario.
|
||||
|
||||
Our goal is to have a fix for any vulnerability released within two
|
||||
weeks of the initial disclosure. This may potentially involve shipping
|
||||
an interim release that simply disables function while a more mature fix
|
||||
can be prepared, but will in the vast majority of cases mean shipping a
|
||||
complete release as soon as possible.
|
||||
|
||||
Throughout the fix process we will keep you up to speed with how the fix
|
||||
is progressing. Once the fix is prepared, we will notify you that we
|
||||
believe we have a fix. Often we will ask you to confirm the fix resolves
|
||||
the problem in your environment, especially if we are not confident of
|
||||
our reproduction scenario.
|
||||
|
||||
At this point, we will prepare for the release. We will obtain a CVE
|
||||
number if one is required, providing you with full credit for the
|
||||
discovery. We will also decide on a planned release date, and let you
|
||||
know when it is. This release date will *always* be on a weekday.
|
||||
|
||||
At this point we will reach out to our major downstream packagers to
|
||||
notify them of an impending security-related patch so they can make
|
||||
arrangements. In addition, these packagers will be provided with the
|
||||
intended patch ahead of time, to ensure that they are able to promptly
|
||||
release their downstream packages. Currently the list of people we
|
||||
actively contact *ahead of a public release* is:
|
||||
|
||||
- Jeremy Cline, Red Hat (@jeremycline)
|
||||
- Daniele Tricoli, Debian (@eriol)
|
||||
|
||||
We will notify these individuals at least a week ahead of our planned
|
||||
release date to ensure that they have sufficient time to prepare. If you
|
||||
believe you should be on this list, please let one of the maintainers
|
||||
know at one of the email addresses at the top of this article.
|
||||
|
||||
On release day, we will push the patch to our public repository, along
|
||||
with an updated changelog that describes the issue and credits you. We
|
||||
will then issue a PyPI release containing the patch.
|
||||
|
||||
At this point, we will publicise the release. This will involve mails to
|
||||
mailing lists, Tweets, and all other communication mechanisms available
|
||||
to the core team.
|
||||
|
||||
We will also explicitly mention which commits contain the fix to make it
|
||||
easier for other distributors and users to easily patch their own
|
||||
versions of requests if upgrading is not an option.
|
||||
66
.github/workflows/codeql-analysis.yml
vendored
@@ -1,66 +0,0 @@
|
||||
# For most projects, this workflow file will not need changing; you simply need
|
||||
# to commit it to your repository.
|
||||
#
|
||||
# You may wish to alter this file to override the set of languages analyzed,
|
||||
# or to provide custom queries or build logic.
|
||||
name: "CodeQL"
|
||||
|
||||
on:
|
||||
push:
|
||||
branches: [master]
|
||||
pull_request:
|
||||
# The branches below must be a subset of the branches above
|
||||
branches: [master]
|
||||
schedule:
|
||||
- cron: '0 23 * * 0'
|
||||
|
||||
jobs:
|
||||
analyze:
|
||||
name: Analyze
|
||||
runs-on: ubuntu-latest
|
||||
|
||||
strategy:
|
||||
fail-fast: false
|
||||
|
||||
|
||||
steps:
|
||||
- name: Checkout repository
|
||||
uses: actions/checkout@v2
|
||||
with:
|
||||
# We must fetch at least the immediate parents so that if this is
|
||||
# a pull request then we can checkout the head.
|
||||
fetch-depth: 2
|
||||
|
||||
# If this run was triggered by a pull request event, then checkout
|
||||
# the head of the pull request instead of the merge commit.
|
||||
- run: git checkout HEAD^2
|
||||
if: ${{ github.event_name == 'pull_request' }}
|
||||
|
||||
# Initializes the CodeQL tools for scanning.
|
||||
- name: Initialize CodeQL
|
||||
uses: github/codeql-action/init@v1
|
||||
with:
|
||||
languages: "python"
|
||||
# If you wish to specify custom queries, you can do so here or in a config file.
|
||||
# By default, queries listed here will override any specified in a config file.
|
||||
# Prefix the list here with "+" to use these queries and those in the config file.
|
||||
# queries: ./path/to/local/query, your-org/your-repo/queries@main
|
||||
|
||||
# Autobuild attempts to build any compiled languages (C/C++, C#, or Java).
|
||||
# If this step fails, then you should remove it and run the build manually (see below)
|
||||
- name: Autobuild
|
||||
uses: github/codeql-action/autobuild@v1
|
||||
|
||||
# ℹ️ Command-line programs to run using the OS shell.
|
||||
# 📚 https://git.io/JvXDl
|
||||
|
||||
# ✏️ If the Autobuild fails above, remove it and uncomment the following three lines
|
||||
# and modify them (or add more) to build your code if your project
|
||||
# uses a compiled language
|
||||
|
||||
#- run: |
|
||||
# make bootstrap
|
||||
# make release
|
||||
|
||||
- name: Perform CodeQL Analysis
|
||||
uses: github/codeql-action/analyze@v1
|
||||
31
.github/workflows/run-tests.yml
vendored
@@ -1,31 +0,0 @@
|
||||
name: Tests
|
||||
|
||||
on: [push, pull_request]
|
||||
|
||||
jobs:
|
||||
build:
|
||||
runs-on: ${{ matrix.os }}
|
||||
|
||||
strategy:
|
||||
fail-fast: false
|
||||
matrix:
|
||||
python-version: [2.7, 3.5, 3.6, 3.7, 3.8, 3.9]
|
||||
os: [ubuntu-18.04, macOS-latest, windows-latest]
|
||||
include:
|
||||
# pypy3 on Mac OS currently fails trying to compile
|
||||
# brotlipy. Moving pypy3 to only test linux.
|
||||
- python-version: pypy3
|
||||
os: ubuntu-latest
|
||||
|
||||
steps:
|
||||
- uses: actions/checkout@v2
|
||||
- name: Set up Python ${{ matrix.python-version }}
|
||||
uses: actions/setup-python@v2
|
||||
with:
|
||||
python-version: ${{ matrix.python-version }}
|
||||
- name: Install dependencies
|
||||
run: |
|
||||
make
|
||||
- name: Run tests
|
||||
run: |
|
||||
make ci
|
||||
9
.gitignore
vendored
@@ -5,7 +5,6 @@ nosetests.xml
|
||||
junit-report.xml
|
||||
pylint.txt
|
||||
toy.py
|
||||
.cache/
|
||||
cover/
|
||||
build/
|
||||
docs/_build
|
||||
@@ -14,12 +13,6 @@ requests.egg-info/
|
||||
*.swp
|
||||
*.egg
|
||||
env/
|
||||
.venv/
|
||||
.eggs/
|
||||
.tox/
|
||||
.pytest_cache/
|
||||
.vscode/
|
||||
.eggs/
|
||||
|
||||
.workon
|
||||
|
||||
@@ -27,5 +20,3 @@ t.py
|
||||
|
||||
t2.py
|
||||
dist
|
||||
|
||||
/.mypy_cache/
|
||||
|
||||
32
.travis.yml
Normal file
@@ -0,0 +1,32 @@
|
||||
sudo: false
|
||||
language: python
|
||||
python:
|
||||
- "2.6"
|
||||
- "2.7"
|
||||
- "3.3"
|
||||
- "3.4"
|
||||
- "3.5"
|
||||
- "3.6"
|
||||
# - "3.7-dev"
|
||||
# - "pypy" -- appears to hang
|
||||
# - "pypy3"
|
||||
# command to install dependencies
|
||||
install: "make"
|
||||
# command to run tests
|
||||
script:
|
||||
- |
|
||||
if [[ "$TRAVIS_PYTHON_VERSION" != "2.6" ]] ; then make test-readme; fi
|
||||
- make ci
|
||||
cache: pip
|
||||
jobs:
|
||||
include:
|
||||
- stage: test
|
||||
script:
|
||||
- |
|
||||
if [[ "$TRAVIS_PYTHON_VERSION" != "2.6" ]] ; then make test-readme; fi
|
||||
- make ci
|
||||
- stage: coverage
|
||||
python: 3.6
|
||||
script: codecov
|
||||
|
||||
|
||||
68
3.0-HISTORY.rst
Normal file
@@ -0,0 +1,68 @@
|
||||
3.0.0 (2017-xx-xx)
|
||||
++++++++++++++++++
|
||||
|
||||
- Simplified logic for determining Content-Length and Transfer-Encoding.
|
||||
Requests will now avoid setting both headers on the same request, and
|
||||
raise an exception if this is done manually by a user.
|
||||
|
||||
- Remove the HTTPProxyAuth class in favor of supporting proxy auth via
|
||||
the proxies parameter.
|
||||
|
||||
- Relax how Requests strips bodies from redirects. 3.0.0 only supports body
|
||||
removal on 301/302 POST redirects and all 303 redirects.
|
||||
|
||||
- Remove support for non-string/bytes parameters in ``_basic_auth_str``.
|
||||
|
||||
- Prevent ``Session.merge_environment`` from erroneously setting the
|
||||
``verify`` parameter to ``None`` instead of ``True``.
|
||||
|
||||
- Streaming responses with ``Response.iter_lines`` or ``Response.iter_content``
|
||||
now requires an encoding to be set if one isn't provided by the server.
|
||||
|
||||
- Raise exception if multiple locations are returned during a redirect.
|
||||
|
||||
- Update ConnectionPool connections when TLS/SSL settings change.
|
||||
|
||||
- Remove simplejson import and only use standard json module.
|
||||
|
||||
- Strip surrounding whitespace from urls.
|
||||
|
||||
- MissingSchema and InvalidSchema renamed to MissingScheme and InvalidScheme
|
||||
respectively.
|
||||
|
||||
- Change merge order for environment settings to avoid excluding Session-level
|
||||
settings.
|
||||
|
||||
- Encode redirect URIs as latin-1 before performing redirects in Python 3 to
|
||||
avoid mangling during the requoting process.
|
||||
|
||||
- Remove the ``__bool__`` and ``__nonzero__`` methods from a ``Response``
|
||||
object.
|
||||
|
||||
This has been a planned feature for over a year. The behaviour is surprising
|
||||
to most people and breaks most of the assumptions that people have about
|
||||
Response objects. This resolves issue `#2002`_
|
||||
|
||||
- Skip over empty chunks in iterators. Empty chunks could prematurely signal
|
||||
the end of a request body's transmission, skipping them allows all of the
|
||||
data through. See `#2631`_ for more details.
|
||||
|
||||
- Rename the ``req`` argument from ``Session.resolve_redirects`` method
|
||||
to ``request``.
|
||||
|
||||
- Rename the ``resp`` argument from ``Session.resolve_redirects`` to
|
||||
``response``.
|
||||
|
||||
- New ``PreparedRequest.send`` method. Now, you can
|
||||
``Request().prepare().send()``.
|
||||
|
||||
- All porcelain API functions (e.g. ``requests.get``, etc) now accept an
|
||||
optional ``session`` parameter. If provided, the session given will be used
|
||||
for the request, in place of one being created for you.
|
||||
|
||||
- URLs are now automatically stripped of leading/trailing whitespace.
|
||||
|
||||
- ``Response.raise_for_status()`` now returns the response object for good responses
|
||||
|
||||
.. _#2002: https://github.com/kennethreitz/requests/issues/2002
|
||||
.. _#2631: https://github.com/kennethreitz/requests/issues/2631
|
||||
41
AUTHORS.rst
Normal file → Executable file
@@ -1,16 +1,20 @@
|
||||
Requests was lovingly created by Kenneth Reitz.
|
||||
Requests is written and maintained by Kenneth Reitz and
|
||||
various contributors:
|
||||
|
||||
Keepers of the Crystals
|
||||
```````````````````````
|
||||
|
||||
- Nate Prewitt `@nateprewitt <https://github.com/nateprewitt>`_.
|
||||
- Seth M. Larson `@sethmlarson <https://github.com/sethmlarson>`_.
|
||||
|
||||
Previous Keepers of Crystals
|
||||
Keepers of the Four Crystals
|
||||
````````````````````````````
|
||||
- Kenneth Reitz <me@kennethreitz.org> `@ken-reitz <https://github.com/ken-reitz>`_, reluctant Keeper of the Master Crystal.
|
||||
|
||||
- Kenneth Reitz <me@kennethreitz.org> `@kennethreitz <https://github.com/kennethreitz>`_, Keeper of the Master Crystal.
|
||||
- Cory Benfield <cory@lukasa.co.uk> `@lukasa <https://github.com/lukasa>`_
|
||||
- Ian Cordasco <graffatcolmingov@gmail.com> `@sigmavirus24 <https://github.com/sigmavirus24>`_.
|
||||
- Ian Cordasco <graffatcolmingov@gmail.com> `@sigmavirus24 <https://github.com/sigmavirus24>`_
|
||||
- Nate Prewitt <nate.prewitt@gmail.com> `@nateprewitt <https://github.com/nateprewitt>`_
|
||||
|
||||
|
||||
|
||||
Urllib3
|
||||
```````
|
||||
|
||||
- Andrey Petrov <andrey.petrov@shazow.net>
|
||||
|
||||
|
||||
Patches and Suggestions
|
||||
@@ -124,7 +128,7 @@ Patches and Suggestions
|
||||
- Bryce Boe <bbzbryce@gmail.com> (`@bboe <https://github.com/bboe>`_)
|
||||
- Colin Dunklau <colin.dunklau@gmail.com> (`@cdunklau <https://github.com/cdunklau>`_)
|
||||
- Bob Carroll <bob.carroll@alum.rit.edu> (`@rcarz <https://github.com/rcarz>`_)
|
||||
- Hugo Osvaldo Barrera <hugo@barrera.io> (`@hobarrera <https://github.com/hobarrera>`_)
|
||||
- Hugo Osvaldo Barrera <hugo@osvaldobarrera.com.ar> (`@hobarrera <https://github.com/hobarrera>`_)
|
||||
- Łukasz Langa <lukasz@langa.pl>
|
||||
- Dave Shawley <daveshawley@gmail.com>
|
||||
- James Clarke (`@jam <https://github.com/jam>`_)
|
||||
@@ -156,16 +160,19 @@ Patches and Suggestions
|
||||
- Muhammad Yasoob Ullah Khalid <yasoob.khld@gmail.com> (`@yasoob <https://github.com/yasoob>`_)
|
||||
- Paul van der Linden (`@pvanderlinden <https://github.com/pvanderlinden>`_)
|
||||
- Colin Dickson (`@colindickson <https://github.com/colindickson>`_)
|
||||
- Sabari Kumar Murugesan (`@neosab <https://github.com/neosab>`_)
|
||||
- Smiley Barry (`@smiley <https://github.com/smiley>`_)
|
||||
- Shagun Sodhani (`@shagunsodhani <https://github.com/shagunsodhani>`_)
|
||||
- Robin Linderborg (`@vienno <https://github.com/vienno>`_)
|
||||
- Brian Samek (`@bsamek <https://github.com/bsamek>`_)
|
||||
- Dmitry Dygalo (`@Stranger6667 <https://github.com/Stranger6667>`_)
|
||||
- Tomáš Heger (`@geckon <https://github.com/geckon>`_)
|
||||
- piotrjurkiewicz
|
||||
- Jesse Shapiro <jesse@jesseshapiro.net> (`@haikuginger <https://github.com/haikuginger>`_)
|
||||
- Nate Prewitt <nate.prewitt@gmail.com> (`@nateprewitt <https://github.com/nateprewitt>`_)
|
||||
- Maik Himstedt
|
||||
- Michael Hunsinger
|
||||
- Jeremy Cline <jcline@redhat.com> (`@jeremycline <https://github.com/jeremycline>`_)
|
||||
- Brian Bamsch <bbamsch32@gmail.com> (`@bbamsch <https://github.com/bbamsch>`_)
|
||||
- Om Prakash Kumar <omprakash070@gmail.com> (`@iamprakashom <https://github.com/iamprakashom>`_)
|
||||
- Philipp Konrad <gardiac2002@gmail.com> (`@gardiac2002 <https://github.com/gardiac2002>`_)
|
||||
@@ -179,15 +186,3 @@ Patches and Suggestions
|
||||
- Shmuel Amar (`@shmuelamar <https://github.com/shmuelamar>`_)
|
||||
- Gary Wu (`@garywu <https://github.com/garywu>`_)
|
||||
- Ryan Pineo (`@ryanpineo <https://github.com/ryanpineo>`_)
|
||||
- Ed Morley (`@edmorley <https://github.com/edmorley>`_)
|
||||
- Matt Liu <liumatt@gmail.com> (`@mlcrazy <https://github.com/mlcrazy>`_)
|
||||
- Taylor Hoff <primdevs@protonmail.com> (`@PrimordialHelios <https://github.com/PrimordialHelios>`_)
|
||||
- Arthur Vigil (`@ahvigil <https://github.com/ahvigil>`_)
|
||||
- Nehal J Wani (`@nehaljwani <https://github.com/nehaljwani>`_)
|
||||
- Demetrios Bairaktaris (`@DemetriosBairaktaris <https://github.com/demetriosbairaktaris>`_)
|
||||
- Darren Dormer (`@ddormer <https://github.com/ddormer>`_)
|
||||
- Rajiv Mayani (`@mayani <https://github.com/mayani>`_)
|
||||
- Antti Kaihola (`@akaihola <https://github.com/akaihola>`_)
|
||||
- "Dull Bananas" <dull.bananas0@gmail.com> (`@dullbananas <https://github.com/dullbananas>`_)
|
||||
- Alessio Izzo (`@aless10 <https://github.com/aless10>`_)
|
||||
- Sylvain Marié (`@smarie <https://github.com/smarie>`_)
|
||||
|
||||
@@ -1,7 +1,10 @@
|
||||
# Contribution Guidelines
|
||||
|
||||
Before opening any issues or proposing any pull requests, please read
|
||||
our [Contributor's Guide](https://requests.readthedocs.io/en/latest/dev/contributing/).
|
||||
Before opening any issues or proposing any pull requests, please do the
|
||||
following:
|
||||
|
||||
1. Read our [Contributor's Guide](http://docs.python-requests.org/en/latest/dev/contributing/).
|
||||
2. Understand our [development philosophy](http://docs.python-requests.org/en/latest/dev/philosophy/).
|
||||
|
||||
To get the greatest chance of helpful responses, please also observe the
|
||||
following additional notes.
|
||||
1699
HISTORY.md
1484
HISTORY.rst
Normal file
182
LICENSE
@@ -1,175 +1,13 @@
|
||||
Copyright 2017 Kenneth Reitz
|
||||
|
||||
Apache License
|
||||
Version 2.0, January 2004
|
||||
http://www.apache.org/licenses/
|
||||
Licensed under the Apache License, Version 2.0 (the "License");
|
||||
you may not use this file except in compliance with the License.
|
||||
You may obtain a copy of the License at
|
||||
|
||||
TERMS AND CONDITIONS FOR USE, REPRODUCTION, AND DISTRIBUTION
|
||||
http://www.apache.org/licenses/LICENSE-2.0
|
||||
|
||||
1. Definitions.
|
||||
|
||||
"License" shall mean the terms and conditions for use, reproduction,
|
||||
and distribution as defined by Sections 1 through 9 of this document.
|
||||
|
||||
"Licensor" shall mean the copyright owner or entity authorized by
|
||||
the copyright owner that is granting the License.
|
||||
|
||||
"Legal Entity" shall mean the union of the acting entity and all
|
||||
other entities that control, are controlled by, or are under common
|
||||
control with that entity. For the purposes of this definition,
|
||||
"control" means (i) the power, direct or indirect, to cause the
|
||||
direction or management of such entity, whether by contract or
|
||||
otherwise, or (ii) ownership of fifty percent (50%) or more of the
|
||||
outstanding shares, or (iii) beneficial ownership of such entity.
|
||||
|
||||
"You" (or "Your") shall mean an individual or Legal Entity
|
||||
exercising permissions granted by this License.
|
||||
|
||||
"Source" form shall mean the preferred form for making modifications,
|
||||
including but not limited to software source code, documentation
|
||||
source, and configuration files.
|
||||
|
||||
"Object" form shall mean any form resulting from mechanical
|
||||
transformation or translation of a Source form, including but
|
||||
not limited to compiled object code, generated documentation,
|
||||
and conversions to other media types.
|
||||
|
||||
"Work" shall mean the work of authorship, whether in Source or
|
||||
Object form, made available under the License, as indicated by a
|
||||
copyright notice that is included in or attached to the work
|
||||
(an example is provided in the Appendix below).
|
||||
|
||||
"Derivative Works" shall mean any work, whether in Source or Object
|
||||
form, that is based on (or derived from) the Work and for which the
|
||||
editorial revisions, annotations, elaborations, or other modifications
|
||||
represent, as a whole, an original work of authorship. For the purposes
|
||||
of this License, Derivative Works shall not include works that remain
|
||||
separable from, or merely link (or bind by name) to the interfaces of,
|
||||
the Work and Derivative Works thereof.
|
||||
|
||||
"Contribution" shall mean any work of authorship, including
|
||||
the original version of the Work and any modifications or additions
|
||||
to that Work or Derivative Works thereof, that is intentionally
|
||||
submitted to Licensor for inclusion in the Work by the copyright owner
|
||||
or by an individual or Legal Entity authorized to submit on behalf of
|
||||
the copyright owner. For the purposes of this definition, "submitted"
|
||||
means any form of electronic, verbal, or written communication sent
|
||||
to the Licensor or its representatives, including but not limited to
|
||||
communication on electronic mailing lists, source code control systems,
|
||||
and issue tracking systems that are managed by, or on behalf of, the
|
||||
Licensor for the purpose of discussing and improving the Work, but
|
||||
excluding communication that is conspicuously marked or otherwise
|
||||
designated in writing by the copyright owner as "Not a Contribution."
|
||||
|
||||
"Contributor" shall mean Licensor and any individual or Legal Entity
|
||||
on behalf of whom a Contribution has been received by Licensor and
|
||||
subsequently incorporated within the Work.
|
||||
|
||||
2. Grant of Copyright License. Subject to the terms and conditions of
|
||||
this License, each Contributor hereby grants to You a perpetual,
|
||||
worldwide, non-exclusive, no-charge, royalty-free, irrevocable
|
||||
copyright license to reproduce, prepare Derivative Works of,
|
||||
publicly display, publicly perform, sublicense, and distribute the
|
||||
Work and such Derivative Works in Source or Object form.
|
||||
|
||||
3. Grant of Patent License. Subject to the terms and conditions of
|
||||
this License, each Contributor hereby grants to You a perpetual,
|
||||
worldwide, non-exclusive, no-charge, royalty-free, irrevocable
|
||||
(except as stated in this section) patent license to make, have made,
|
||||
use, offer to sell, sell, import, and otherwise transfer the Work,
|
||||
where such license applies only to those patent claims licensable
|
||||
by such Contributor that are necessarily infringed by their
|
||||
Contribution(s) alone or by combination of their Contribution(s)
|
||||
with the Work to which such Contribution(s) was submitted. If You
|
||||
institute patent litigation against any entity (including a
|
||||
cross-claim or counterclaim in a lawsuit) alleging that the Work
|
||||
or a Contribution incorporated within the Work constitutes direct
|
||||
or contributory patent infringement, then any patent licenses
|
||||
granted to You under this License for that Work shall terminate
|
||||
as of the date such litigation is filed.
|
||||
|
||||
4. Redistribution. You may reproduce and distribute copies of the
|
||||
Work or Derivative Works thereof in any medium, with or without
|
||||
modifications, and in Source or Object form, provided that You
|
||||
meet the following conditions:
|
||||
|
||||
(a) You must give any other recipients of the Work or
|
||||
Derivative Works a copy of this License; and
|
||||
|
||||
(b) You must cause any modified files to carry prominent notices
|
||||
stating that You changed the files; and
|
||||
|
||||
(c) You must retain, in the Source form of any Derivative Works
|
||||
that You distribute, all copyright, patent, trademark, and
|
||||
attribution notices from the Source form of the Work,
|
||||
excluding those notices that do not pertain to any part of
|
||||
the Derivative Works; and
|
||||
|
||||
(d) If the Work includes a "NOTICE" text file as part of its
|
||||
distribution, then any Derivative Works that You distribute must
|
||||
include a readable copy of the attribution notices contained
|
||||
within such NOTICE file, excluding those notices that do not
|
||||
pertain to any part of the Derivative Works, in at least one
|
||||
of the following places: within a NOTICE text file distributed
|
||||
as part of the Derivative Works; within the Source form or
|
||||
documentation, if provided along with the Derivative Works; or,
|
||||
within a display generated by the Derivative Works, if and
|
||||
wherever such third-party notices normally appear. The contents
|
||||
of the NOTICE file are for informational purposes only and
|
||||
do not modify the License. You may add Your own attribution
|
||||
notices within Derivative Works that You distribute, alongside
|
||||
or as an addendum to the NOTICE text from the Work, provided
|
||||
that such additional attribution notices cannot be construed
|
||||
as modifying the License.
|
||||
|
||||
You may add Your own copyright statement to Your modifications and
|
||||
may provide additional or different license terms and conditions
|
||||
for use, reproduction, or distribution of Your modifications, or
|
||||
for any such Derivative Works as a whole, provided Your use,
|
||||
reproduction, and distribution of the Work otherwise complies with
|
||||
the conditions stated in this License.
|
||||
|
||||
5. Submission of Contributions. Unless You explicitly state otherwise,
|
||||
any Contribution intentionally submitted for inclusion in the Work
|
||||
by You to the Licensor shall be under the terms and conditions of
|
||||
this License, without any additional terms or conditions.
|
||||
Notwithstanding the above, nothing herein shall supersede or modify
|
||||
the terms of any separate license agreement you may have executed
|
||||
with Licensor regarding such Contributions.
|
||||
|
||||
6. Trademarks. This License does not grant permission to use the trade
|
||||
names, trademarks, service marks, or product names of the Licensor,
|
||||
except as required for reasonable and customary use in describing the
|
||||
origin of the Work and reproducing the content of the NOTICE file.
|
||||
|
||||
7. Disclaimer of Warranty. Unless required by applicable law or
|
||||
agreed to in writing, Licensor provides the Work (and each
|
||||
Contributor provides its Contributions) on an "AS IS" BASIS,
|
||||
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or
|
||||
implied, including, without limitation, any warranties or conditions
|
||||
of TITLE, NON-INFRINGEMENT, MERCHANTABILITY, or FITNESS FOR A
|
||||
PARTICULAR PURPOSE. You are solely responsible for determining the
|
||||
appropriateness of using or redistributing the Work and assume any
|
||||
risks associated with Your exercise of permissions under this License.
|
||||
|
||||
8. Limitation of Liability. In no event and under no legal theory,
|
||||
whether in tort (including negligence), contract, or otherwise,
|
||||
unless required by applicable law (such as deliberate and grossly
|
||||
negligent acts) or agreed to in writing, shall any Contributor be
|
||||
liable to You for damages, including any direct, indirect, special,
|
||||
incidental, or consequential damages of any character arising as a
|
||||
result of this License or out of the use or inability to use the
|
||||
Work (including but not limited to damages for loss of goodwill,
|
||||
work stoppage, computer failure or malfunction, or any and all
|
||||
other commercial damages or losses), even if such Contributor
|
||||
has been advised of the possibility of such damages.
|
||||
|
||||
9. Accepting Warranty or Additional Liability. While redistributing
|
||||
the Work or Derivative Works thereof, You may choose to offer,
|
||||
and charge a fee for, acceptance of support, warranty, indemnity,
|
||||
or other liability obligations and/or rights consistent with this
|
||||
License. However, in accepting such obligations, You may act only
|
||||
on Your own behalf and on Your sole responsibility, not on behalf
|
||||
of any other Contributor, and only if You agree to indemnify,
|
||||
defend, and hold each Contributor harmless for any liability
|
||||
incurred by, or claims asserted against, such Contributor by reason
|
||||
of your accepting any such warranty or additional liability.
|
||||
Unless required by applicable law or agreed to in writing, software
|
||||
distributed under the License is distributed on an "AS IS" BASIS,
|
||||
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
See the License for the specific language governing permissions and
|
||||
limitations under the License.
|
||||
|
||||
@@ -1,2 +1,2 @@
|
||||
include README.md LICENSE NOTICE HISTORY.md pytest.ini requirements-dev.txt
|
||||
include README.rst LICENSE NOTICE HISTORY.rst pytest.ini
|
||||
recursive-include tests *.py
|
||||
|
||||
11
Makefile
@@ -1,21 +1,20 @@
|
||||
.PHONY: docs
|
||||
init:
|
||||
pip install -e .[socks]
|
||||
pip install -r requirements-dev.txt
|
||||
pip install -r requirements.txt
|
||||
test:
|
||||
# This runs all of the tests, on both Python 2 and Python 3.
|
||||
detox
|
||||
ci:
|
||||
pytest tests --junitxml=report.xml
|
||||
py.test -n 8 --boxed --junitxml=report.xml
|
||||
|
||||
test-readme:
|
||||
python setup.py check --restructuredtext --strict && ([ $$? -eq 0 ] && echo "README.rst and HISTORY.rst ok") || echo "Invalid markup in README.rst or HISTORY.rst!"
|
||||
python setup.py check -r -s
|
||||
|
||||
flake8:
|
||||
flake8 --ignore=E501,F401,E128,E402,E731,F821 requests
|
||||
|
||||
coverage:
|
||||
pytest --cov-config .coveragerc --verbose --cov-report term --cov-report xml --cov=requests tests
|
||||
py.test --cov-config .coveragerc --verbose --cov-report term --cov-report xml --cov=requests tests
|
||||
|
||||
publish:
|
||||
pip install 'twine>=1.5.0'
|
||||
@@ -25,4 +24,4 @@ publish:
|
||||
|
||||
docs:
|
||||
cd docs && make html
|
||||
@echo "\033[95m\n\nBuild successful! View the docs homepage at docs/_build/html/index.html.\n\033[0m"
|
||||
@echo "\033[95m\n\nBuild successful! View the docs homepage at docs/_build/html/index.html.\n\033[0m"
|
||||
62
README.md
@@ -1,62 +0,0 @@
|
||||
# Requests
|
||||
|
||||
**Requests** is a simple, yet elegant HTTP library.
|
||||
|
||||
```python
|
||||
>>> import requests
|
||||
>>> r = requests.get('https://api.github.com/user', auth=('user', 'pass'))
|
||||
>>> r.status_code
|
||||
200
|
||||
>>> r.headers['content-type']
|
||||
'application/json; charset=utf8'
|
||||
>>> r.encoding
|
||||
'utf-8'
|
||||
>>> r.text
|
||||
'{"type":"User"...'
|
||||
>>> r.json()
|
||||
{'disk_usage': 368627, 'private_gists': 484, ...}
|
||||
```
|
||||
|
||||
Requests allows you to send HTTP/1.1 requests extremely easily. There’s no need to manually add query strings to your URLs, or to form-encode your `PUT` & `POST` data — but nowadays, just use the `json` method!
|
||||
|
||||
Requests is one of the most downloaded Python package today, pulling in around `14M downloads / week`— according to GitHub, Requests is currently [depended upon](https://github.com/psf/requests/network/dependents?package_id=UGFja2FnZS01NzA4OTExNg%3D%3D) by `500,000+` repositories. You may certainly put your trust in this code.
|
||||
|
||||
[](https://pepy.tech/project/requests/month)
|
||||
[](https://pypi.org/project/requests)
|
||||
[](https://github.com/psf/requests/graphs/contributors)
|
||||
|
||||
## Installing Requests and Supported Versions
|
||||
|
||||
Requests is available on PyPI:
|
||||
|
||||
```console
|
||||
$ python -m pip install requests
|
||||
```
|
||||
|
||||
Requests officially supports Python 2.7 & 3.5+.
|
||||
|
||||
## Supported Features & Best–Practices
|
||||
|
||||
Requests is ready for the demands of building robust and reliable HTTP–speaking applications, for the needs of today.
|
||||
|
||||
- Keep-Alive & Connection Pooling
|
||||
- International Domains and URLs
|
||||
- Sessions with Cookie Persistence
|
||||
- Browser-style TLS/SSL Verification
|
||||
- Basic & Digest Authentication
|
||||
- Familiar `dict`–like Cookies
|
||||
- Automatic Content Decompression and Decoding
|
||||
- Multi-part File Uploads
|
||||
- SOCKS Proxy Support
|
||||
- Connection Timeouts
|
||||
- Streaming Downloads
|
||||
- Automatic honoring of `.netrc`
|
||||
- Chunked HTTP Requests
|
||||
|
||||
## API Reference and User Guide available on [Read the Docs](https://requests.readthedocs.io)
|
||||
|
||||
[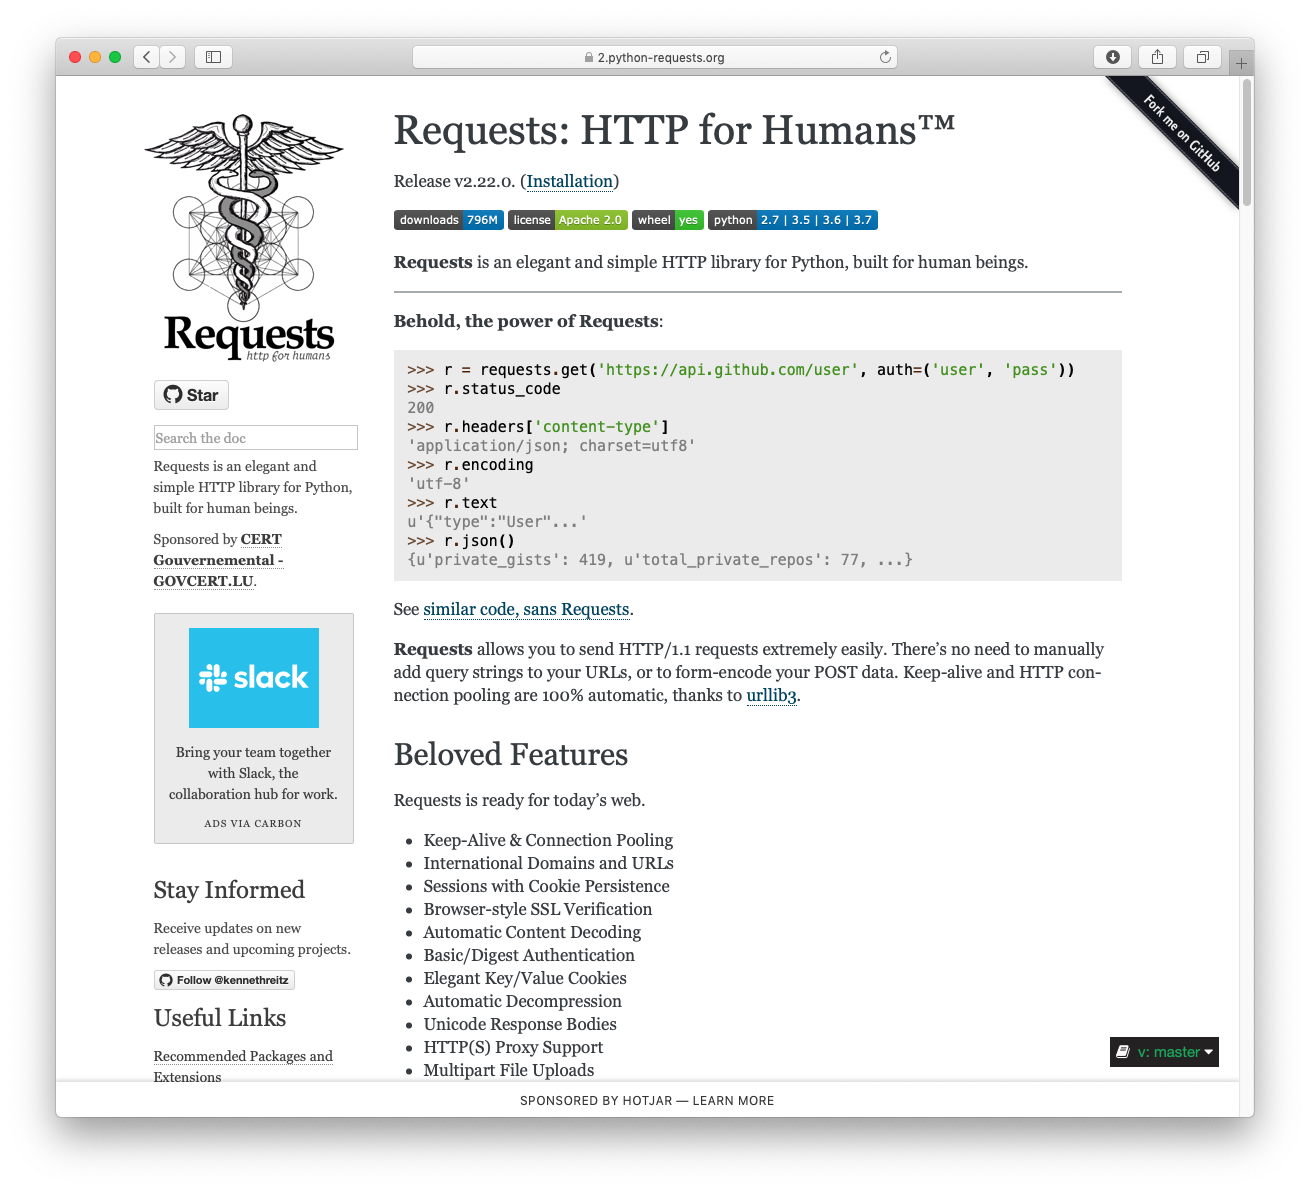](https://requests.readthedocs.io)
|
||||
|
||||
---
|
||||
|
||||
[](https://kennethreitz.org) [](https://www.python.org/psf)
|
||||
114
README.rst
Normal file
@@ -0,0 +1,114 @@
|
||||
Requests: HTTP for Humans
|
||||
=========================
|
||||
|
||||
.. image:: https://img.shields.io/pypi/v/requests.svg
|
||||
:target: https://pypi.python.org/pypi/requests
|
||||
|
||||
.. image:: https://img.shields.io/pypi/l/requests.svg
|
||||
:target: https://pypi.python.org/pypi/requests
|
||||
|
||||
.. image:: https://img.shields.io/pypi/pyversions/requests.svg
|
||||
:target: https://pypi.python.org/pypi/requests
|
||||
|
||||
.. image:: https://codecov.io/github/requests/requests/coverage.svg?branch=master
|
||||
:target: https://codecov.io/github/requests/requests
|
||||
:alt: codecov.io
|
||||
|
||||
.. image:: https://img.shields.io/github/contributors/requests/requests.svg
|
||||
:target: https://github.com/requests/requests/graphs/contributors
|
||||
|
||||
.. image:: https://img.shields.io/badge/Say%20Thanks-!-1EAEDB.svg
|
||||
:target: https://saythanks.io/to/kennethreitz
|
||||
|
||||
|
||||
|
||||
Requests is the only *Non-GMO* HTTP library for Python, safe for human
|
||||
consumption.
|
||||
|
||||
**Warning:** Recreational use of the Python standard library for HTTP may result in dangerous side-effects,
|
||||
including: security vulnerabilities, verbose code, reinventing the wheel,
|
||||
constantly reading documentation, depression, headaches, or even death.
|
||||
|
||||
Behold, the power of Requests:
|
||||
|
||||
.. code-block:: python
|
||||
|
||||
>>> r = requests.get('https://api.github.com/user', auth=('user', 'pass'))
|
||||
>>> r.status_code
|
||||
200
|
||||
>>> r.headers['content-type']
|
||||
'application/json; charset=utf8'
|
||||
>>> r.encoding
|
||||
'utf-8'
|
||||
>>> r.text
|
||||
u'{"type":"User"...'
|
||||
>>> r.json()
|
||||
{u'disk_usage': 368627, u'private_gists': 484, ...}
|
||||
|
||||
See `the similar code, sans Requests <https://gist.github.com/973705>`_.
|
||||
|
||||
.. image:: https://raw.githubusercontent.com/requests/requests/master/docs/_static/requests-logo-small.png
|
||||
:target: http://docs.python-requests.org/
|
||||
|
||||
|
||||
Requests allows you to send *organic, grass-fed* HTTP/1.1 requests, without the
|
||||
need for manual labor. There's no need to manually add query strings to your
|
||||
URLs, or to form-encode your POST data. Keep-alive and HTTP connection pooling
|
||||
are 100% automatic, thanks to `urllib3 <https://github.com/shazow/urllib3>`_.
|
||||
|
||||
Besides, all the cool kids are doing it. Requests is one of the most
|
||||
downloaded Python packages of all time, pulling in over 11,000,000 downloads
|
||||
every month. You don't want to be left out!
|
||||
|
||||
Feature Support
|
||||
---------------
|
||||
|
||||
Requests is ready for today's web.
|
||||
|
||||
- International Domains and URLs
|
||||
- Keep-Alive & Connection Pooling
|
||||
- Sessions with Cookie Persistence
|
||||
- Browser-style SSL Verification
|
||||
- Basic/Digest Authentication
|
||||
- Elegant Key/Value Cookies
|
||||
- Automatic Decompression
|
||||
- Automatic Content Decoding
|
||||
- Unicode Response Bodies
|
||||
- Multipart File Uploads
|
||||
- HTTP(S) Proxy Support
|
||||
- Connection Timeouts
|
||||
- Streaming Downloads
|
||||
- ``.netrc`` Support
|
||||
- Chunked Requests
|
||||
|
||||
Requests officially supports Python 2.6–2.7 & 3.3–3.7, and runs great on PyPy.
|
||||
|
||||
Installation
|
||||
------------
|
||||
|
||||
To install Requests, simply:
|
||||
|
||||
.. code-block:: bash
|
||||
|
||||
$ pip install requests
|
||||
✨🍰✨
|
||||
|
||||
Satisfaction, guaranteed.
|
||||
|
||||
Documentation
|
||||
-------------
|
||||
|
||||
Fantastic documentation is available at http://docs.python-requests.org/, for a limited time only.
|
||||
|
||||
|
||||
How to Contribute
|
||||
-----------------
|
||||
|
||||
#. Check for open issues or open a fresh issue to start a discussion around a feature idea or a bug. There is a `Contributor Friendly`_ tag for issues that should be ideal for people who are not very familiar with the codebase yet.
|
||||
#. Fork `the repository`_ on GitHub to start making your changes to the **master** branch (or branch off of it).
|
||||
#. Write a test which shows that the bug was fixed or that the feature works as expected.
|
||||
#. Send a pull request and bug the maintainer until it gets merged and published. :) Make sure to add yourself to AUTHORS_.
|
||||
|
||||
.. _`the repository`: http://github.com/requests/requests
|
||||
.. _AUTHORS: https://github.com/requests/requests/blob/master/AUTHORS.rst
|
||||
.. _Contributor Friendly: https://github.com/requests/requests/issues?direction=desc&labels=Contributor+Friendly&page=1&sort=updated&state=open
|
||||
229
_appveyor/install.ps1
Normal file
@@ -0,0 +1,229 @@
|
||||
# Sample script to install Python and pip under Windows
|
||||
# Authors: Olivier Grisel, Jonathan Helmus, Kyle Kastner, and Alex Willmer
|
||||
# License: CC0 1.0 Universal: http://creativecommons.org/publicdomain/zero/1.0/
|
||||
|
||||
$MINICONDA_URL = "http://repo.continuum.io/miniconda/"
|
||||
$BASE_URL = "https://www.python.org/ftp/python/"
|
||||
$GET_PIP_URL = "https://bootstrap.pypa.io/get-pip.py"
|
||||
$GET_PIP_PATH = "C:\get-pip.py"
|
||||
|
||||
$PYTHON_PRERELEASE_REGEX = @"
|
||||
(?x)
|
||||
(?<major>\d+)
|
||||
\.
|
||||
(?<minor>\d+)
|
||||
\.
|
||||
(?<micro>\d+)
|
||||
(?<prerelease>[a-z]{1,2}\d+)
|
||||
"@
|
||||
|
||||
|
||||
function Download ($filename, $url) {
|
||||
$webclient = New-Object System.Net.WebClient
|
||||
|
||||
$basedir = $pwd.Path + "\"
|
||||
$filepath = $basedir + $filename
|
||||
if (Test-Path $filename) {
|
||||
Write-Host "Reusing" $filepath
|
||||
return $filepath
|
||||
}
|
||||
|
||||
# Download and retry up to 3 times in case of network transient errors.
|
||||
Write-Host "Downloading" $filename "from" $url
|
||||
$retry_attempts = 2
|
||||
for ($i = 0; $i -lt $retry_attempts; $i++) {
|
||||
try {
|
||||
$webclient.DownloadFile($url, $filepath)
|
||||
break
|
||||
}
|
||||
Catch [Exception]{
|
||||
Start-Sleep 1
|
||||
}
|
||||
}
|
||||
if (Test-Path $filepath) {
|
||||
Write-Host "File saved at" $filepath
|
||||
} else {
|
||||
# Retry once to get the error message if any at the last try
|
||||
$webclient.DownloadFile($url, $filepath)
|
||||
}
|
||||
return $filepath
|
||||
}
|
||||
|
||||
|
||||
function ParsePythonVersion ($python_version) {
|
||||
if ($python_version -match $PYTHON_PRERELEASE_REGEX) {
|
||||
return ([int]$matches.major, [int]$matches.minor, [int]$matches.micro,
|
||||
$matches.prerelease)
|
||||
}
|
||||
$version_obj = [version]$python_version
|
||||
return ($version_obj.major, $version_obj.minor, $version_obj.build, "")
|
||||
}
|
||||
|
||||
|
||||
function DownloadPython ($python_version, $platform_suffix) {
|
||||
$major, $minor, $micro, $prerelease = ParsePythonVersion $python_version
|
||||
|
||||
if (($major -le 2 -and $micro -eq 0) `
|
||||
-or ($major -eq 3 -and $minor -le 2 -and $micro -eq 0) `
|
||||
) {
|
||||
$dir = "$major.$minor"
|
||||
$python_version = "$major.$minor$prerelease"
|
||||
} else {
|
||||
$dir = "$major.$minor.$micro"
|
||||
}
|
||||
|
||||
if ($prerelease) {
|
||||
if (($major -le 2) `
|
||||
-or ($major -eq 3 -and $minor -eq 1) `
|
||||
-or ($major -eq 3 -and $minor -eq 2) `
|
||||
-or ($major -eq 3 -and $minor -eq 3) `
|
||||
) {
|
||||
$dir = "$dir/prev"
|
||||
}
|
||||
}
|
||||
|
||||
if (($major -le 2) -or ($major -le 3 -and $minor -le 4)) {
|
||||
$ext = "msi"
|
||||
if ($platform_suffix) {
|
||||
$platform_suffix = ".$platform_suffix"
|
||||
}
|
||||
} else {
|
||||
$ext = "exe"
|
||||
if ($platform_suffix) {
|
||||
$platform_suffix = "-$platform_suffix"
|
||||
}
|
||||
}
|
||||
|
||||
$filename = "python-$python_version$platform_suffix.$ext"
|
||||
$url = "$BASE_URL$dir/$filename"
|
||||
$filepath = Download $filename $url
|
||||
return $filepath
|
||||
}
|
||||
|
||||
|
||||
function InstallPython ($python_version, $architecture, $python_home) {
|
||||
Write-Host "Installing Python" $python_version "for" $architecture "bit architecture to" $python_home
|
||||
if (Test-Path $python_home) {
|
||||
Write-Host $python_home "already exists, skipping."
|
||||
return $false
|
||||
}
|
||||
if ($architecture -eq "32") {
|
||||
$platform_suffix = ""
|
||||
} else {
|
||||
$platform_suffix = "amd64"
|
||||
}
|
||||
$installer_path = DownloadPython $python_version $platform_suffix
|
||||
$installer_ext = [System.IO.Path]::GetExtension($installer_path)
|
||||
Write-Host "Installing $installer_path to $python_home"
|
||||
$install_log = $python_home + ".log"
|
||||
if ($installer_ext -eq '.msi') {
|
||||
InstallPythonMSI $installer_path $python_home $install_log
|
||||
} else {
|
||||
InstallPythonEXE $installer_path $python_home $install_log
|
||||
}
|
||||
if (Test-Path $python_home) {
|
||||
Write-Host "Python $python_version ($architecture) installation complete"
|
||||
} else {
|
||||
Write-Host "Failed to install Python in $python_home"
|
||||
Get-Content -Path $install_log
|
||||
Exit 1
|
||||
}
|
||||
}
|
||||
|
||||
|
||||
function InstallPythonEXE ($exepath, $python_home, $install_log) {
|
||||
$install_args = "/quiet InstallAllUsers=1 TargetDir=$python_home"
|
||||
RunCommand $exepath $install_args
|
||||
}
|
||||
|
||||
|
||||
function InstallPythonMSI ($msipath, $python_home, $install_log) {
|
||||
$install_args = "/qn /log $install_log /i $msipath TARGETDIR=$python_home"
|
||||
$uninstall_args = "/qn /x $msipath"
|
||||
RunCommand "msiexec.exe" $install_args
|
||||
if (-not(Test-Path $python_home)) {
|
||||
Write-Host "Python seems to be installed else-where, reinstalling."
|
||||
RunCommand "msiexec.exe" $uninstall_args
|
||||
RunCommand "msiexec.exe" $install_args
|
||||
}
|
||||
}
|
||||
|
||||
function RunCommand ($command, $command_args) {
|
||||
Write-Host $command $command_args
|
||||
Start-Process -FilePath $command -ArgumentList $command_args -Wait -Passthru
|
||||
}
|
||||
|
||||
|
||||
function InstallPip ($python_home) {
|
||||
$pip_path = $python_home + "\Scripts\pip.exe"
|
||||
$python_path = $python_home + "\python.exe"
|
||||
if (-not(Test-Path $pip_path)) {
|
||||
Write-Host "Installing pip..."
|
||||
$webclient = New-Object System.Net.WebClient
|
||||
$webclient.DownloadFile($GET_PIP_URL, $GET_PIP_PATH)
|
||||
Write-Host "Executing:" $python_path $GET_PIP_PATH
|
||||
& $python_path $GET_PIP_PATH
|
||||
} else {
|
||||
Write-Host "pip already installed."
|
||||
}
|
||||
}
|
||||
|
||||
|
||||
function DownloadMiniconda ($python_version, $platform_suffix) {
|
||||
if ($python_version -eq "3.4") {
|
||||
$filename = "Miniconda3-3.5.5-Windows-" + $platform_suffix + ".exe"
|
||||
} else {
|
||||
$filename = "Miniconda-3.5.5-Windows-" + $platform_suffix + ".exe"
|
||||
}
|
||||
$url = $MINICONDA_URL + $filename
|
||||
$filepath = Download $filename $url
|
||||
return $filepath
|
||||
}
|
||||
|
||||
|
||||
function InstallMiniconda ($python_version, $architecture, $python_home) {
|
||||
Write-Host "Installing Python" $python_version "for" $architecture "bit architecture to" $python_home
|
||||
if (Test-Path $python_home) {
|
||||
Write-Host $python_home "already exists, skipping."
|
||||
return $false
|
||||
}
|
||||
if ($architecture -eq "32") {
|
||||
$platform_suffix = "x86"
|
||||
} else {
|
||||
$platform_suffix = "x86_64"
|
||||
}
|
||||
$filepath = DownloadMiniconda $python_version $platform_suffix
|
||||
Write-Host "Installing" $filepath "to" $python_home
|
||||
$install_log = $python_home + ".log"
|
||||
$args = "/S /D=$python_home"
|
||||
Write-Host $filepath $args
|
||||
Start-Process -FilePath $filepath -ArgumentList $args -Wait -Passthru
|
||||
if (Test-Path $python_home) {
|
||||
Write-Host "Python $python_version ($architecture) installation complete"
|
||||
} else {
|
||||
Write-Host "Failed to install Python in $python_home"
|
||||
Get-Content -Path $install_log
|
||||
Exit 1
|
||||
}
|
||||
}
|
||||
|
||||
|
||||
function InstallMinicondaPip ($python_home) {
|
||||
$pip_path = $python_home + "\Scripts\pip.exe"
|
||||
$conda_path = $python_home + "\Scripts\conda.exe"
|
||||
if (-not(Test-Path $pip_path)) {
|
||||
Write-Host "Installing pip..."
|
||||
$args = "install --yes pip"
|
||||
Write-Host $conda_path $args
|
||||
Start-Process -FilePath "$conda_path" -ArgumentList $args -Wait -Passthru
|
||||
} else {
|
||||
Write-Host "pip already installed."
|
||||
}
|
||||
}
|
||||
|
||||
function main () {
|
||||
InstallPython $env:PYTHON_VERSION $env:PYTHON_ARCH $env:PYTHON
|
||||
InstallPip $env:PYTHON
|
||||
}
|
||||
|
||||
main
|
||||
56
appveyor.yml
Normal file
@@ -0,0 +1,56 @@
|
||||
# AppVeyor.yml from https://github.com/ogrisel/python-appveyor-demo
|
||||
# License: CC0 1.0 Universal: http://creativecommons.org/publicdomain/zero/1.0/
|
||||
|
||||
build: off
|
||||
|
||||
environment:
|
||||
matrix:
|
||||
- PYTHON: "C:\\Python27-x64"
|
||||
PYTHON_VERSION: "2.7.x"
|
||||
PYTHON_ARCH: "64"
|
||||
TOXENV: "py27"
|
||||
|
||||
- PYTHON: "C:\\Python33-x64"
|
||||
PYTHON_VERSION: "3.3.x"
|
||||
PYTHON_ARCH: "64"
|
||||
TOXENV: "py33"
|
||||
|
||||
- PYTHON: "C:\\Python34-x64"
|
||||
PYTHON_VERSION: "3.4.x"
|
||||
PYTHON_ARCH: "64"
|
||||
TOXENV: "py34"
|
||||
|
||||
- PYTHON: "C:\\Python35-x64"
|
||||
PYTHON_VERSION: "3.5.x"
|
||||
PYTHON_ARCH: "64"
|
||||
TOXENV: "py35"
|
||||
|
||||
- PYTHON: "C:\\Python36-x64"
|
||||
PYTHON_VERSION: "3.6.x"
|
||||
PYTHON_ARCH: "64"
|
||||
TOXENV: "py36"
|
||||
|
||||
install:
|
||||
# Install Python (from the official .msi of http://python.org) and pip when
|
||||
# not already installed.
|
||||
- ps: if (-not(Test-Path($env:PYTHON))) { & _appveyor\install.ps1 }
|
||||
|
||||
# Prepend newly installed Python to the PATH of this build (this cannot be
|
||||
# done from inside the powershell script as it would require to restart
|
||||
# the parent CMD process).
|
||||
- "SET PATH=%PYTHON%;%PYTHON%\\Scripts;%PATH%"
|
||||
|
||||
# Check that we have the expected version and architecture for Python
|
||||
- "python --version"
|
||||
- "python -c \"import struct; print(struct.calcsize('P') * 8)\""
|
||||
|
||||
# Upgrade to the latest version of pip to avoid it displaying warnings
|
||||
# about it being out of date.
|
||||
- "pip install --disable-pip-version-check --user --upgrade pip"
|
||||
- "C:\\MinGW\\bin\\mingw32-make"
|
||||
|
||||
test_script:
|
||||
- "C:\\MinGW\\bin\\mingw32-make coverage"
|
||||
|
||||
on_success:
|
||||
- "codecov -f coverage.xml"
|
||||
@@ -1 +0,0 @@
|
||||
|
||||
177
docs/_static/custom.css
vendored
@@ -1,177 +0,0 @@
|
||||
body > div.document > div.sphinxsidebar > div > form > table > tbody > tr:nth-child(2) > td > select {
|
||||
width: 100%!important;
|
||||
}
|
||||
|
||||
#python27 > a {
|
||||
color: white;
|
||||
}
|
||||
|
||||
/* Carbon by BuySellAds */
|
||||
#carbonads {
|
||||
display: block;
|
||||
overflow: hidden;
|
||||
margin: 1.5em 0 2em;
|
||||
padding: 1em;
|
||||
border: solid 1px #cccccc;
|
||||
border-radius: 2px;
|
||||
background-color: #eeeeee;
|
||||
text-align: center;
|
||||
line-height: 1.5;
|
||||
}
|
||||
|
||||
#carbonads a {
|
||||
border-bottom: 0;
|
||||
}
|
||||
|
||||
#carbonads span {
|
||||
display: block;
|
||||
overflow: hidden;
|
||||
}
|
||||
|
||||
.carbon-img {
|
||||
display: block;
|
||||
margin: 0 auto 1em;
|
||||
text-align: center;
|
||||
}
|
||||
|
||||
.carbon-text {
|
||||
display: block;
|
||||
margin-bottom: 1em;
|
||||
}
|
||||
|
||||
.carbon-poweredby {
|
||||
display: block;
|
||||
text-transform: uppercase;
|
||||
letter-spacing: 1px;
|
||||
font-size: 10px;
|
||||
line-height: 1;
|
||||
}
|
||||
|
||||
|
||||
/* Native CPC by BuySellAds */
|
||||
|
||||
#native-ribbon #_custom_ {
|
||||
position: fixed;
|
||||
right: 0;
|
||||
bottom: 0;
|
||||
left: 0;
|
||||
box-shadow: 0 -1px 4px 1px hsla(0, 0%, 0%, .15);
|
||||
font-family: -apple-system, BlinkMacSystemFont, "Segoe UI", Roboto, Oxygen-Sans, Ubuntu,
|
||||
Cantarell, "Helvetica Neue", Helvetica, Arial, sans-serif;
|
||||
transition: all .25s ease-in-out;
|
||||
transform: translateY(calc(100% - 35px));
|
||||
|
||||
flex-flow: column nowrap;
|
||||
}
|
||||
|
||||
#native-ribbon #_custom_:hover {
|
||||
transform: translateY(0);
|
||||
}
|
||||
|
||||
.native-img {
|
||||
margin-right: 20px;
|
||||
max-height: 50px;
|
||||
border-radius: 3px;
|
||||
}
|
||||
|
||||
.native-sponsor {
|
||||
margin: 10px 20px;
|
||||
text-align: center;
|
||||
text-transform: uppercase;
|
||||
letter-spacing: .5px;
|
||||
font-size: 12px;
|
||||
transition: all .3s ease-in-out;
|
||||
transform-origin: left;
|
||||
}
|
||||
|
||||
#native-ribbon #_custom_:hover .native-sponsor {
|
||||
margin: 0 20px;
|
||||
opacity: 0;
|
||||
transform: scaleY(0);
|
||||
}
|
||||
|
||||
.native-flex {
|
||||
display: flex;
|
||||
padding: 10px 20px 25px;
|
||||
text-decoration: none;
|
||||
|
||||
flex-flow: row nowrap;
|
||||
justify-content: center;
|
||||
align-items: center;
|
||||
}
|
||||
|
||||
.native-main {
|
||||
display: flex;
|
||||
|
||||
flex-flow: row nowrap;
|
||||
align-items: center;
|
||||
}
|
||||
|
||||
.native-details {
|
||||
display: flex;
|
||||
margin-right: 30px;
|
||||
|
||||
flex-flow: column nowrap;
|
||||
}
|
||||
|
||||
.native-company {
|
||||
margin-bottom: 4px;
|
||||
text-transform: uppercase;
|
||||
letter-spacing: 2px;
|
||||
font-size: 10px;
|
||||
}
|
||||
|
||||
.native-desc {
|
||||
letter-spacing: 1px;
|
||||
font-weight: 300;
|
||||
font-size: 14px;
|
||||
line-height: 1.4;
|
||||
}
|
||||
|
||||
.native-cta {
|
||||
padding: 10px 14px;
|
||||
border-radius: 3px;
|
||||
box-shadow: 0 6px 13px 0 hsla(0, 0%, 0%, .15);
|
||||
text-transform: uppercase;
|
||||
white-space: nowrap;
|
||||
letter-spacing: 1px;
|
||||
font-weight: 400;
|
||||
font-size: 12px;
|
||||
transition: all .3s ease-in-out;
|
||||
transform: translateY(-1px);
|
||||
}
|
||||
|
||||
.native-cta:hover {
|
||||
box-shadow: none;
|
||||
transform: translateY(1px);
|
||||
}
|
||||
|
||||
@media only screen and (min-width: 320px) and (max-width: 759px) {
|
||||
.native-flex {
|
||||
padding: 5px 5px 15px;
|
||||
flex-direction: column;
|
||||
|
||||
flex-wrap: wrap;
|
||||
}
|
||||
|
||||
.native-img {
|
||||
margin: 0;
|
||||
display: none;
|
||||
}
|
||||
|
||||
.native-details {
|
||||
margin: 0;
|
||||
}
|
||||
|
||||
.native-main {
|
||||
flex-direction: column;
|
||||
text-align: left;
|
||||
|
||||
flex-wrap: wrap;
|
||||
align-content: center;
|
||||
}
|
||||
|
||||
.native-cta {
|
||||
display: none;
|
||||
}
|
||||
}
|
||||
116
docs/_static/konami.js
vendored
Normal file
@@ -0,0 +1,116 @@
|
||||
/*
|
||||
* Konami-JS ~
|
||||
* :: Now with support for touch events and multiple instances for
|
||||
* :: those situations that call for multiple easter eggs!
|
||||
* Code: http://konami-js.googlecode.com/
|
||||
* Examples: http://www.snaptortoise.com/konami-js
|
||||
* Copyright (c) 2009 George Mandis (georgemandis.com, snaptortoise.com)
|
||||
* Version: 1.4.2 (9/2/2013)
|
||||
* Licensed under the MIT License (http://opensource.org/licenses/MIT)
|
||||
* Tested in: Safari 4+, Google Chrome 4+, Firefox 3+, IE7+, Mobile Safari 2.2.1 and Dolphin Browser
|
||||
*/
|
||||
|
||||
var Konami = function (callback) {
|
||||
var konami = {
|
||||
addEvent: function (obj, type, fn, ref_obj) {
|
||||
if (obj.addEventListener)
|
||||
obj.addEventListener(type, fn, false);
|
||||
else if (obj.attachEvent) {
|
||||
// IE
|
||||
obj["e" + type + fn] = fn;
|
||||
obj[type + fn] = function () {
|
||||
obj["e" + type + fn](window.event, ref_obj);
|
||||
};
|
||||
obj.attachEvent("on" + type, obj[type + fn]);
|
||||
}
|
||||
},
|
||||
input: "",
|
||||
pattern: "38384040373937396665",
|
||||
load: function (link) {
|
||||
this.addEvent(document, "keydown", function (e, ref_obj) {
|
||||
if (ref_obj) konami = ref_obj; // IE
|
||||
konami.input += e ? e.keyCode : event.keyCode;
|
||||
if (konami.input.length > konami.pattern.length)
|
||||
konami.input = konami.input.substr((konami.input.length - konami.pattern.length));
|
||||
if (konami.input == konami.pattern) {
|
||||
konami.code(link);
|
||||
konami.input = "";
|
||||
e.preventDefault();
|
||||
return false;
|
||||
}
|
||||
}, this);
|
||||
this.iphone.load(link);
|
||||
},
|
||||
code: function (link) {
|
||||
window.location = link
|
||||
},
|
||||
iphone: {
|
||||
start_x: 0,
|
||||
start_y: 0,
|
||||
stop_x: 0,
|
||||
stop_y: 0,
|
||||
tapTolerance: 8,
|
||||
capture: false,
|
||||
orig_keys: "",
|
||||
keys: ["UP", "UP", "DOWN", "DOWN", "LEFT", "RIGHT", "LEFT", "RIGHT", "TAP", "TAP"],
|
||||
code: function (link) {
|
||||
konami.code(link);
|
||||
},
|
||||
touchCapture: function(evt) {
|
||||
konami.iphone.start_x = evt.changedTouches[0].pageX;
|
||||
konami.iphone.start_y = evt.changedTouches[0].pageY;
|
||||
konami.iphone.capture = true;
|
||||
},
|
||||
load: function (link) {
|
||||
this.orig_keys = this.keys;
|
||||
konami.addEvent(document, "touchmove", function (e) {
|
||||
if (e.touches.length == 1 && konami.iphone.capture == true) {
|
||||
var touch = e.touches[0];
|
||||
konami.iphone.stop_x = touch.pageX;
|
||||
konami.iphone.stop_y = touch.pageY;
|
||||
konami.iphone.check_direction();
|
||||
}
|
||||
});
|
||||
konami.addEvent(document, "touchend", function (evt) {
|
||||
konami.touchCapture(evt);
|
||||
konami.iphone.check_direction(link);
|
||||
}, false);
|
||||
konami.addEvent(document, "touchstart", function (evt) {
|
||||
konami.touchCapture(evt);
|
||||
});
|
||||
},
|
||||
check_direction: function (link) {
|
||||
var x_magnitude = Math.abs(this.start_x - this.stop_x);
|
||||
var y_magnitude = Math.abs(this.start_y - this.stop_y);
|
||||
var hasMoved = (x_magnitude > this.tapTolerance || y_magnitude > this.tapTolerance);
|
||||
var result;
|
||||
if (this.capture === true && hasMoved) {
|
||||
this.capture = false;
|
||||
var x = ((this.start_x - this.stop_x) < 0) ? "RIGHT" : "LEFT";
|
||||
var y = ((this.start_y - this.stop_y) < 0) ? "DOWN" : "UP";
|
||||
var result = (x_magnitude > y_magnitude) ? x : y;
|
||||
}
|
||||
else if (this.capture === false && !hasMoved) {
|
||||
result = (this.tap == true) ? "TAP" : result;
|
||||
result = "TAP";
|
||||
}
|
||||
if (result) {
|
||||
if (result == this.keys[0]) this.keys = this.keys.slice(1, this.keys.length);
|
||||
else this.keys = this.orig_keys;
|
||||
}
|
||||
if (this.keys.length == 0) {
|
||||
this.keys = this.orig_keys;
|
||||
this.code(link);
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
typeof callback === "string" && konami.load(callback);
|
||||
if (typeof callback === "function") {
|
||||
konami.code = callback;
|
||||
konami.load();
|
||||
}
|
||||
|
||||
return konami;
|
||||
};
|
||||
BIN
docs/_static/requests-logo-small.png
vendored
Normal file

|
After Width: | Height: | Size: 155 KiB |
BIN
docs/_static/requests-sidebar.png
vendored
Normal file

|
After Width: | Height: | Size: 299 KiB |
78
docs/_templates/hacks.html
vendored
@@ -23,58 +23,32 @@
|
||||
/* Have code blocks escape the document right-margin. */
|
||||
div.highlight pre {margin-right: -30px;}
|
||||
}
|
||||
|
||||
</style>
|
||||
|
||||
<!-- Native CPC by BuySellAds -->
|
||||
|
||||
<script type="text/javascript" src="//m.servedby-buysellads.com/monetization.js"></script>
|
||||
|
||||
<div id="native-ribbon">
|
||||
</div>
|
||||
|
||||
<script>
|
||||
_bsa.init('custom', 'CK7D62JU', 'placement:pythonrequestsorg',
|
||||
{
|
||||
target: '#native-ribbon',
|
||||
template: `
|
||||
<div class="native-sponsor">Sponsored by ##company## — Learn More</div>
|
||||
<a href="##link##" class="native-flex">
|
||||
<style>
|
||||
#native-ribbon #_custom_ {
|
||||
background: linear-gradient(-30deg, ##backgroundColor##E5, ##backgroundColor##E5 45%, ##backgroundColor## 45%) #fff;
|
||||
}
|
||||
|
||||
.native-details,
|
||||
.native-sponsor,
|
||||
.native-bsa {
|
||||
color: ##textColor## !important;
|
||||
}
|
||||
|
||||
.native-details:hover {
|
||||
color: ##textColorHover## !important;
|
||||
}
|
||||
|
||||
.native-cta {
|
||||
color: ##ctaTextColor##;
|
||||
background-color: ##ctaBackgroundColor##;
|
||||
}
|
||||
|
||||
.native-cta:hover {
|
||||
color: ##ctaTextColorHover##;
|
||||
background-color: ##ctaBackgroundColorHover##;
|
||||
}
|
||||
</style>
|
||||
<div class="native-main">
|
||||
<img class="native-img" src="##logo##">
|
||||
<div class="native-details">
|
||||
<span class="native-company">##title##</span>
|
||||
<span class="native-desc">##description##</span>
|
||||
</div>
|
||||
</div>
|
||||
<span class="native-cta">##callToAction##</span>
|
||||
</a>
|
||||
</div>
|
||||
`
|
||||
}
|
||||
);
|
||||
<!-- Analytics tracking for Kenneth. -->
|
||||
<script type="text/javascript">
|
||||
var _gauges = _gauges || [];
|
||||
(function() {
|
||||
var t = document.createElement('script');
|
||||
t.type = 'text/javascript';
|
||||
t.async = true;
|
||||
t.id = 'gauges-tracker';
|
||||
t.setAttribute('data-site-id', '56ca7a57c88d9011080024dd');
|
||||
t.setAttribute('data-track-path', 'https://track.gaug.es/track.gif');
|
||||
t.src = 'https://d36ee2fcip1434.cloudfront.net/track.js';
|
||||
var s = document.getElementsByTagName('script')[0];
|
||||
s.parentNode.insertBefore(t, s);
|
||||
})();
|
||||
</script>
|
||||
|
||||
<!-- There are no more hacks. -->
|
||||
<!-- இڿڰۣ-ڰۣ— -->
|
||||
<!-- Love, Kenneth Reitz -->
|
||||
|
||||
<script src="{{ pathto('_static/', 1) }}/konami.js"></script>
|
||||
<script>
|
||||
var easter_egg = new Konami('http://fortunes.herokuapp.com/random/raw');
|
||||
</script>
|
||||
|
||||
<!-- That was not a hack. That was art. -->
|
||||
107
docs/_templates/sidebarintro.html
vendored
@@ -1,73 +1,80 @@
|
||||
<p class="logo">
|
||||
<a href="{{ pathto(master_doc) }}">
|
||||
<img class="logo" src="{{ pathto('_static/requests-sidebar.png', 1) }}" title="https://kennethreitz.org/tattoos"/>
|
||||
</a>
|
||||
</p>
|
||||
|
||||
<p>
|
||||
<iframe src="https://ghbtns.com/github-btn.html?user=psf&repo=requests&type=watch&count=true&size=large"
|
||||
<iframe src="http://ghbtns.com/github-btn.html?user=requests&repo=requests&type=watch&count=true&size=large"
|
||||
allowtransparency="true" frameborder="0" scrolling="0" width="200px" height="35px"></iframe>
|
||||
</p>
|
||||
<link rel="stylesheet" href="https://cdn.jsdelivr.net/npm/docsearch.js@2/dist/cdn/docsearch.min.css" />
|
||||
<style>
|
||||
.algolia-autocomplete {
|
||||
width: 100%;
|
||||
height: 1.5em
|
||||
}
|
||||
|
||||
.algolia-autocomplete a {
|
||||
border-bottom: none !important;
|
||||
}
|
||||
|
||||
#doc_search {
|
||||
width: 100%;
|
||||
height: 100%;
|
||||
}
|
||||
</style>
|
||||
<input id="doc_search" placeholder="Search the doc" autofocus />
|
||||
<script type="text/javascript" src="https://cdn.jsdelivr.net/npm/docsearch.js@2/dist/cdn/docsearch.min.js" onload="docsearch({
|
||||
apiKey: 'f177061e2354c50a97bfc635e827ffab',
|
||||
indexName: 'python-requests',
|
||||
inputSelector: '#doc_search',
|
||||
debug: false // Set debug to true if you want to inspect the dropdown
|
||||
})" async></script>
|
||||
|
||||
<p>
|
||||
Requests is an elegant and simple HTTP library for Python, built for
|
||||
human beings.
|
||||
</p>
|
||||
<p>Sponsored by <strong><a href="https://www.govcert.lu">CERT Gouvernemental - GOVCERT.LU</a></strong>.</p>
|
||||
|
||||
<script async type="text/javascript"
|
||||
src="//cdn.carbonads.com/carbon.js?zoneid=1673&serve=CKYI5K3E&placement=pythonrequestsorg"
|
||||
id="_carbonads_js"></script>
|
||||
|
||||
<h3>The Hitchhiker's Guide to Python</h3>
|
||||
|
||||
<p>This guide is now available in tangible book form!</p>
|
||||
|
||||
<a href="https://www.amazon.com/Hitchhikers-Guide-Python-Practices-Development/dp/1491933178/ref=as_li_ss_il?ie=UTF8&linkCode=li2&tag=bookforkind-20&linkId=804806ebdacaf3b56567347f3afbdbca" target="_blank"><img border="0" src="https://ws-na.amazon-adsystem.com/widgets/q?_encoding=UTF8&ASIN=1491933178&Format=_SL160_&ID=AsinImage&MarketPlace=US&ServiceVersion=20070822&WS=1&tag=bookforkind-20" ></a><img src="//ir-na.amazon-adsystem.com/e/ir?t=bookforkind-20&l=li2&o=1&a=1491933178" width="1" height="1" border="0" alt="" style="border:none !important; margin:0px !important;" />
|
||||
|
||||
<p>All proceeds are being directly donated to the <a href="https://djangogirls.org">DjangoGirls</a> organization.</p>
|
||||
|
||||
|
||||
|
||||
<h3>Stay Informed</h3>
|
||||
<p>Receive updates on new releases and upcoming projects.</p>
|
||||
|
||||
<p><iframe src="http://ghbtns.com/github-btn.html?user=kennethreitz&type=follow&count=false"
|
||||
allowtransparency="true" frameborder="0" scrolling="0" width="200" height="20"></iframe></p>
|
||||
|
||||
<p><a href="https://twitter.com/kennethreitz" class="twitter-follow-button" data-show-count="false">Follow @kennethreitz</a> <script>!function(d,s,id){var js,fjs=d.getElementsByTagName(s)[0],p=/^http:/.test(d.location)?'http':'https';if(!d.getElementById(id)){js=d.createElement(s);js.id=id;js.src=p+'://platform.twitter.com/widgets.js';fjs.parentNode.insertBefore(js,fjs);}}(document, 'script', 'twitter-wjs');</script></p>
|
||||
<p><a href="https://saythanks.io/to/kennethreitz">Say Thanks!</a></p>
|
||||
<p><a href="http://tinyletter.com/kennethreitz">Join Mailing List</a>.</p>
|
||||
|
||||
|
||||
<h3>Other Projects</h3>
|
||||
|
||||
<p>More <a href="http://kennethreitz.org/">Kenneth Reitz</a> projects:</p>
|
||||
<ul>
|
||||
<li><a href="http://edmsynths.com/">edmsynths.com</a></li>
|
||||
<li><a href="http://pipenv.org/">pipenv</a></li>
|
||||
<li><a href="http://pep8.org/">pep8.org</a></li>
|
||||
<li><a href="http://httpbin.org/">httpbin.org</a></li>
|
||||
<li><a href="http://python-guide.org">The Python Guide</a></li>
|
||||
<li><a href="https://github.com/kennethreitz/maya">Maya: Datetimes for Humans</a></li>
|
||||
<li><a href="https://github.com/kennethreitz/records">Records: SQL for Humans</a></li>
|
||||
<li><a href="http://www.git-legit.org">Legit: Git for Humans</a></li>
|
||||
<li><a href="http://docs.python-tablib.org/en/latest/">Tablib: Tabular Datasets</a></li>
|
||||
</ul>
|
||||
|
||||
|
||||
<h3>Useful Links</h3>
|
||||
<ul>
|
||||
<li><a href="https://requests.readthedocs.io/en/latest/user/quickstart/">Quickstart</a></li>
|
||||
<li><a href="https://requests.readthedocs.io/en/latest/user/advanced/">Advanced Usage</a></li>
|
||||
<li><a href="https://requests.readthedocs.io/en/latest/api/">API Reference</a></li>
|
||||
<li><a href="https://requests.readthedocs.io/en/latest/community/updates/#release-history">Release History</a></li>
|
||||
<li><a href="https://requests.readthedocs.io/en/latest/dev/contributing/">Contributors Guide</a></li>
|
||||
<li><a href="http://docs.python-requests.org/en/latest/community/recommended/">Recommended Packages and Extensions</a></li>
|
||||
|
||||
<p></p>
|
||||
|
||||
<li><a href="https://requests.readthedocs.io/en/latest/community/recommended/">Recommended Packages and Extensions</a></li>
|
||||
|
||||
<p></p>
|
||||
|
||||
<li><a href="https://github.com/psf/requests">Requests @ GitHub</a></li>
|
||||
<li><a href="https://pypi.org/project/requests/">Requests @ PyPI</a></li>
|
||||
<li><a href="https://github.com/psf/requests/issues">Issue Tracker</a></li>
|
||||
<li><a href="http://github.com/requests/requests">Requests @ GitHub</a></li>
|
||||
<li><a href="http://pypi.python.org/pypi/requests">Requests @ PyPI</a></li>
|
||||
<li><a href="http://github.com/requests/requests/issues">Issue Tracker</a></li>
|
||||
<li><a href="http://docs.python-requests.org/en/latest/community/updates/#software-updates">Release History</a></li>
|
||||
</ul>
|
||||
|
||||
|
||||
<h3>Translations</h3>
|
||||
|
||||
<ul>
|
||||
<li><a href="https://requests.readthedocs.io/">English</a></li>
|
||||
<li><a href="https://fr.python-requests.org/">French</a></li>
|
||||
<li><a href="https://de.python-requests.org/">German</a></li>
|
||||
<li><a href="https://jp.python-requests.org/">Japanese</a></li>
|
||||
<li><a href="https://cn.python-requests.org/">Chinese</a></li>
|
||||
<li><a href="https://pt.python-requests.org/">Portuguese</a></li>
|
||||
<li><a href="https://it.python-requests.org/">Italian</a></li>
|
||||
<li><a href="https://es.python-requests.org/">Spanish</a></li>
|
||||
<li><a href="http://docs.python-requests.org/">English</a></li>
|
||||
<li><a href="http://fr.python-requests.org/">French</a></li>
|
||||
<li><a href="http://de.python-requests.org/">German</a></li>
|
||||
<li><a href="http://jp.python-requests.org/">Japanese</a></li>
|
||||
<li><a href="http://cn.python-requests.org/">Chinese</a></li>
|
||||
<li><a href="http://pt.python-requests.org/">Portuguese</a></li>
|
||||
<li><a href="http://it.python-requests.org/">Italian</a></li>
|
||||
<li><a href="http://es.python-requests.org/">Spanish</a></li>
|
||||
</ul>
|
||||
|
||||
<div id="native-ribbon">
|
||||
</div>
|
||||
|
||||
112
docs/_templates/sidebarlogo.html
vendored
@@ -1,30 +1,12 @@
|
||||
<p>
|
||||
<iframe src="https://ghbtns.com/github-btn.html?user=psf&repo=requests&type=watch&count=true&size=large"
|
||||
allowtransparency="true" frameborder="0" scrolling="0" width="200px" height="35px"></iframe>
|
||||
<p class="logo">
|
||||
<a href="{{ pathto(master_doc) }}">
|
||||
<img class="logo" src="{{ pathto('_static/requests-sidebar.png', 1) }}" title="https://kennethreitz.org/tattoos"/>
|
||||
</a>
|
||||
</p>
|
||||
<p>
|
||||
<iframe src="http://ghbtns.com/github-btn.html?user=requests&repo=requests&type=watch&count=true&size=large"
|
||||
allowtransparency="true" frameborder="0" scrolling="0" width="200px" height="35px"></iframe>
|
||||
</p>
|
||||
<link rel="stylesheet" href="https://cdn.jsdelivr.net/npm/docsearch.js@2/dist/cdn/docsearch.min.css" />
|
||||
<style>
|
||||
.algolia-autocomplete {
|
||||
width: 100%;
|
||||
height: 1.5em
|
||||
}
|
||||
|
||||
.algolia-autocomplete a {
|
||||
border-bottom: none !important;
|
||||
}
|
||||
|
||||
#doc_search {
|
||||
width: 100%;
|
||||
height: 100%;
|
||||
}
|
||||
</style>
|
||||
<input id="doc_search" placeholder="Search the doc" autofocus />
|
||||
<script type="text/javascript" src="https://cdn.jsdelivr.net/npm/docsearch.js@2/dist/cdn/docsearch.min.js" onload="docsearch({
|
||||
apiKey: 'f177061e2354c50a97bfc635e827ffab',
|
||||
indexName: 'python-requests',
|
||||
inputSelector: '#doc_search',
|
||||
debug: false // Set debug to true if you want to inspect the dropdown
|
||||
})" async></script>
|
||||
|
||||
<p>
|
||||
Requests is an elegant and simple HTTP library for Python, built for
|
||||
@@ -32,40 +14,56 @@
|
||||
development release.
|
||||
</p>
|
||||
|
||||
<p>Sponsored by <strong><a href="https://www.govcert.lu">CERT Gouvernemental - GOVCERT.LU</a></strong>.</p>
|
||||
<h3>Stay Informed</h3>
|
||||
<p>Receive updates on new releases and upcoming projects.</p>
|
||||
|
||||
<script async type="text/javascript"
|
||||
src="//cdn.carbonads.com/carbon.js?zoneid=1673&serve=C6AILKT&placement=pythonrequestsorg"
|
||||
id="_carbonads_js"></script>
|
||||
<p><a href="http://tinyletter.com/kennethreitz">Join Mailing List</a>.</p>
|
||||
|
||||
<h3>Useful Links</h3>
|
||||
<hr/>
|
||||
|
||||
<h3>The Hitchhiker's Guide to Python</h3>
|
||||
|
||||
<p>This guide is now available in tangible book form!</p>
|
||||
|
||||
<a href="https://www.amazon.com/Hitchhikers-Guide-Python-Practices-Development/dp/1491933178/ref=as_li_ss_il?ie=UTF8&linkCode=li2&tag=bookforkind-20&linkId=804806ebdacaf3b56567347f3afbdbca" target="_blank"><img border="0" src="https://ws-na.amazon-adsystem.com/widgets/q?_encoding=UTF8&ASIN=1491933178&Format=_SL160_&ID=AsinImage&MarketPlace=US&ServiceVersion=20070822&WS=1&tag=bookforkind-20" ></a><img src="//ir-na.amazon-adsystem.com/e/ir?t=bookforkind-20&l=li2&o=1&a=1491933178" width="1" height="1" border="0" alt="" style="border:none !important; margin:0px !important;" />
|
||||
|
||||
<p>All proceeds are being directly donated to the <a href="https://djangogirls.org">DjangoGirls</a> organization.</p>
|
||||
|
||||
|
||||
<p>If you enjoy using this project, <a href="https://saythanks.io/to/kennethreitz">Say Thanks!</a></p>
|
||||
|
||||
<p><iframe src="http://ghbtns.com/github-btn.html?user=kennethreitz&type=follow&count=false"
|
||||
allowtransparency="true" frameborder="0" scrolling="0" width="200" height="20"></iframe></p>
|
||||
|
||||
<p><a href="https://twitter.com/kennethreitz" class="twitter-follow-button" data-show-count="false">Follow @kennethreitz</a> <script>!function(d,s,id){var js,fjs=d.getElementsByTagName(s)[0],p=/^http:/.test(d.location)?'http':'https';if(!d.getElementById(id)){js=d.createElement(s);js.id=id;js.src=p+'://platform.twitter.com/widgets.js';fjs.parentNode.insertBefore(js,fjs);}}(document, 'script', 'twitter-wjs');</script></p>
|
||||
|
||||
|
||||
<h3>Other Projects</h3>
|
||||
|
||||
<p>More <a href="http://kennethreitz.org/">Kenneth Reitz</a> projects:</p>
|
||||
<ul>
|
||||
<li><a href="https://requests.readthedocs.io/en/latest/user/quickstart/">Quickstart</a></li>
|
||||
<li><a href="https://requests.readthedocs.io/en/latest/user/advanced/">Advanced Usage</a></li>
|
||||
<li><a href="https://requests.readthedocs.io/en/latest/api/">API Reference</a></li>
|
||||
<li><a href="https://requests.readthedocs.io/en/latest/community/updates/#release-history">Release History</a></li>
|
||||
<li><a href="https://requests.readthedocs.io/en/latest/dev/contributing/">Contributors Guide</a></li>
|
||||
|
||||
<p></p>
|
||||
|
||||
<li><a href="https://requests.readthedocs.io/en/latest/community/recommended/">Recommended Packages and Extensions</a></li>
|
||||
|
||||
<p></p>
|
||||
|
||||
<li><a href="https://github.com/psf/requests">Requests @ GitHub</a></li>
|
||||
<li><a href="https://pypi.org/project/requests/">Requests @ PyPI</a></li>
|
||||
<li><a href="https://github.com/psf/requests/issues">Issue Tracker</a></li>
|
||||
<li><a href="http://edmsynths.com/">edmsynths.com</a></li>
|
||||
<li><a href="http://pipenv.org/">pipenv</a></li>
|
||||
<li><a href="http://pep8.org/">pep8.org</a></li>
|
||||
<li><a href="http://httpbin.org/">httpbin.org</a></li>
|
||||
<li><a href="http://python-guide.org">The Python Guide</a></li>
|
||||
<li><a href="https://github.com/kennethreitz/maya">Maya: Datetimes for Humans</a></li>
|
||||
<li><a href="https://github.com/kennethreitz/records">Records: SQL for Humans</a></li>
|
||||
<li><a href="http://www.git-legit.org">Legit: Git for Humans</a></li>
|
||||
<li><a href="http://docs.python-tablib.org/en/latest/">Tablib: Tabular Datasets</a></li>
|
||||
</ul>
|
||||
|
||||
<h3>Translations</h3>
|
||||
|
||||
<ul>
|
||||
<li><a href="https://requests.readthedocs.io/">English</a></li>
|
||||
<li><a href="https://fr.python-requests.org/">French</a></li>
|
||||
<li><a href="https://de.python-requests.org/">German</a></li>
|
||||
<li><a href="https://jp.python-requests.org/">Japanese</a></li>
|
||||
<li><a href="https://cn.python-requests.org/">Chinese</a></li>
|
||||
<li><a href="https://pt.python-requests.org/">Portuguese</a></li>
|
||||
<li><a href="https://it.python-requests.org/">Italian</a></li>
|
||||
<li><a href="https://es.python-requests.org/">Spanish</a></li>
|
||||
</ul>
|
||||
<h3>Translations</h3>
|
||||
|
||||
<ul>
|
||||
<li><a href="http://docs.python-requests.org/">English</a></li>
|
||||
<li><a href="http://fr.python-requests.org/">French</a></li>
|
||||
<li><a href="http://de.python-requests.org/">German</a></li>
|
||||
<li><a href="http://jp.python-requests.org/">Japanese</a></li>
|
||||
<li><a href="http://cn.python-requests.org/">Chinese</a></li>
|
||||
<li><a href="http://pt.python-requests.org/">Portuguese</a></li>
|
||||
<li><a href="http://it.python-requests.org/">Italian</a></li>
|
||||
<li><a href="http://es.python-requests.org/">Spanish</a></li>
|
||||
</ul>
|
||||
|
||||
|
||||
27
docs/api.rst
@@ -74,7 +74,6 @@ Authentication
|
||||
|
||||
.. autoclass:: requests.auth.AuthBase
|
||||
.. autoclass:: requests.auth.HTTPBasicAuth
|
||||
.. autoclass:: requests.auth.HTTPProxyAuth
|
||||
.. autoclass:: requests.auth.HTTPDigestAuth
|
||||
|
||||
|
||||
@@ -109,7 +108,17 @@ Status Code Lookup
|
||||
|
||||
.. autoclass:: requests.codes
|
||||
|
||||
.. automodule:: requests.status_codes
|
||||
::
|
||||
|
||||
>>> requests.codes['temporary_redirect']
|
||||
307
|
||||
|
||||
>>> requests.codes.teapot
|
||||
418
|
||||
|
||||
>>> requests.codes['\o/']
|
||||
200
|
||||
|
||||
|
||||
|
||||
Migrating to 1.x
|
||||
@@ -139,7 +148,7 @@ API Changes
|
||||
s = requests.Session() # formerly, session took parameters
|
||||
s.auth = auth
|
||||
s.headers.update(headers)
|
||||
r = s.get('https://httpbin.org/headers')
|
||||
r = s.get('http://httpbin.org/headers')
|
||||
|
||||
* All request hooks have been removed except 'response'.
|
||||
|
||||
@@ -181,11 +190,11 @@ API Changes
|
||||
|
||||
logging.basicConfig() # you need to initialize logging, otherwise you will not see anything from requests
|
||||
logging.getLogger().setLevel(logging.DEBUG)
|
||||
requests_log = logging.getLogger("urllib3")
|
||||
requests_log = logging.getLogger("requests.packages.urllib3")
|
||||
requests_log.setLevel(logging.DEBUG)
|
||||
requests_log.propagate = True
|
||||
|
||||
requests.get('https://httpbin.org/headers')
|
||||
requests.get('http://httpbin.org/headers')
|
||||
|
||||
|
||||
|
||||
@@ -197,8 +206,8 @@ license from the ISC_ license to the `Apache 2.0`_ license. The Apache 2.0
|
||||
license ensures that contributions to Requests are also covered by the Apache
|
||||
2.0 license.
|
||||
|
||||
.. _ISC: https://opensource.org/licenses/ISC
|
||||
.. _Apache 2.0: https://opensource.org/licenses/Apache-2.0
|
||||
.. _ISC: http://opensource.org/licenses/ISC
|
||||
.. _Apache 2.0: http://opensource.org/licenses/Apache-2.0
|
||||
|
||||
|
||||
Migrating to 2.x
|
||||
@@ -213,7 +222,7 @@ For more details on the changes in this release including new APIs, links
|
||||
to the relevant GitHub issues and some of the bug fixes, read Cory's blog_
|
||||
on the subject.
|
||||
|
||||
.. _blog: https://lukasa.co.uk/2013/09/Requests_20/
|
||||
.. _blog: http://lukasa.co.uk/2013/09/Requests_20/
|
||||
|
||||
|
||||
API Changes
|
||||
@@ -242,7 +251,7 @@ API Changes
|
||||
}
|
||||
|
||||
# In requests 1.x, this was legal, in requests 2.x,
|
||||
# this raises requests.exceptions.MissingSchema
|
||||
# this raises requests.exceptions.MissingScheme
|
||||
requests.get("http://example.org", proxies=proxies)
|
||||
|
||||
|
||||
|
||||
@@ -19,8 +19,7 @@ Custom User-Agents?
|
||||
-------------------
|
||||
|
||||
Requests allows you to easily override User-Agent strings, along with
|
||||
any other HTTP Header. See `documentation about headers <https://requests.readthedocs.io/en/master/user/quickstart/#custom-headers>`_.
|
||||
|
||||
any other HTTP Header.
|
||||
|
||||
|
||||
Why not Httplib2?
|
||||
@@ -52,20 +51,16 @@ Chris Adams gave an excellent summary on
|
||||
Python 3 Support?
|
||||
-----------------
|
||||
|
||||
Yes! Requests officially supports Python 2.7 & 3.5+ and PyPy.
|
||||
Yes! Here's a list of Python platforms that are officially
|
||||
supported:
|
||||
|
||||
Python 2 Support?
|
||||
-----------------
|
||||
|
||||
Yes! We do not have immediate plans to `sunset
|
||||
<https://www.python.org/doc/sunset-python-2/>`_ our support for Python
|
||||
2.7. We understand that we have a large user base with varying needs,
|
||||
and intend to maintain Python 2.7 support within Requests until `pip
|
||||
stops supporting Python 2.7 (there's no estimated date on that yet)
|
||||
<https://pip.pypa.io/en/latest/development/release-process/#python-2-support>`_.
|
||||
|
||||
That said, it is *highly* recommended users migrate to Python 3.6+ since Python
|
||||
2.7 is no longer receiving bug fixes or security updates as of January 1, 2020.
|
||||
* Python 2.6
|
||||
* Python 2.7
|
||||
* Python 3.3
|
||||
* Python 3.4
|
||||
* Python 3.5
|
||||
* Python 3.6
|
||||
* PyPy
|
||||
|
||||
What are "hostname doesn't match" errors?
|
||||
-----------------------------------------
|
||||
@@ -74,7 +69,7 @@ These errors occur when :ref:`SSL certificate verification <verification>`
|
||||
fails to match the certificate the server responds with to the hostname
|
||||
Requests thinks it's contacting. If you're certain the server's SSL setup is
|
||||
correct (for example, because you can visit the site with your browser) and
|
||||
you're using Python 2.7, a possible explanation is that you need
|
||||
you're using Python 2.6 or 2.7, a possible explanation is that you need
|
||||
Server-Name-Indication.
|
||||
|
||||
`Server-Name-Indication`_, or SNI, is an official extension to SSL where the
|
||||
|
||||
@@ -13,10 +13,10 @@ To give it a try, simply::
|
||||
|
||||
Articles & Talks
|
||||
================
|
||||
- `Python for the Web <https://www.gun.io/blog/python-for-the-web>`_ teaches how to use Python to interact with the web, using Requests.
|
||||
- `Daniel Greenfeld's Review of Requests <https://pydanny.blogspot.com/2011/05/python-http-requests-for-humans.html>`_
|
||||
- `My 'Python for Humans' talk <http://python-for-humans.heroku.com>`_ ( `audio <https://codeconf.s3.amazonaws.com/2011/pycodeconf/talks/PyCodeConf2011%20-%20Kenneth%20Reitz.m4a>`_ )
|
||||
- `Issac Kelly's 'Consuming Web APIs' talk <https://issackelly.github.com/Consuming-Web-APIs-with-Python-Talk/slides/slides.html>`_
|
||||
- `Blog post about Requests via Yum <https://arunsag.wordpress.com/2011/08/17/new-package-python-requests-http-for-humans/>`_
|
||||
- `Russian blog post introducing Requests <https://habr.com/post/126262/>`_
|
||||
- `Python for the Web <http://gun.io/blog/python-for-the-web/>`_ teaches how to use Python to interact with the web, using Requests.
|
||||
- `Daniel Greenfeld's Review of Requests <http://pydanny.blogspot.com/2011/05/python-http-requests-for-humans.html>`_
|
||||
- `My 'Python for Humans' talk <http://python-for-humans.heroku.com>`_ ( `audio <http://codeconf.s3.amazonaws.com/2011/pycodeconf/talks/PyCodeConf2011%20-%20Kenneth%20Reitz.m4a>`_ )
|
||||
- `Issac Kelly's 'Consuming Web APIs' talk <http://issackelly.github.com/Consuming-Web-APIs-with-Python-Talk/slides/slides.html>`_
|
||||
- `Blog post about Requests via Yum <http://arunsag.wordpress.com/2011/08/17/new-package-python-requests-http-for-humans/>`_
|
||||
- `Russian blog post introducing Requests <http://habrahabr.ru/blogs/python/126262/>`_
|
||||
- `Sending JSON in Requests <http://www.coglib.com/~icordasc/blog/2014/11/sending-json-in-requests.html>`_
|
||||
|
||||
@@ -13,7 +13,7 @@ Certifi CA Bundle
|
||||
validating the trustworthiness of SSL certificates while verifying the
|
||||
identity of TLS hosts. It has been extracted from the Requests project.
|
||||
|
||||
.. _Certifi: https://github.com/certifi/python-certifi
|
||||
.. _Certifi: http://certifi.io/en/latest/
|
||||
|
||||
CacheControl
|
||||
------------
|
||||
@@ -32,15 +32,7 @@ but do not belong in Requests proper. This library is actively maintained
|
||||
by members of the Requests core team, and reflects the functionality most
|
||||
requested by users within the community.
|
||||
|
||||
.. _Requests-Toolbelt: https://toolbelt.readthedocs.io/en/latest/index.html
|
||||
|
||||
|
||||
Requests-Threads
|
||||
----------------
|
||||
|
||||
`Requests-Threads`_ is a Requests session that returns the amazing Twisted's awaitable Deferreds instead of Response objects. This allows the use of ``async``/``await`` keyword usage on Python 3, or Twisted's style of programming, if desired.
|
||||
|
||||
.. _Requests-Threads: https://github.com/requests/requests-threads
|
||||
.. _Requests-Toolbelt: http://toolbelt.readthedocs.io/en/latest/index.html
|
||||
|
||||
Requests-OAuthlib
|
||||
-----------------
|
||||
@@ -60,3 +52,6 @@ Betamax
|
||||
A VCR imitation designed only for Python-Requests.
|
||||
|
||||
.. _betamax: https://github.com/sigmavirus24/betamax
|
||||
|
||||
|
||||
|
||||
|
||||
@@ -17,18 +17,19 @@ Breaking changes are changes that break backwards compatibility with prior
|
||||
versions. If the project were to change the ``text`` attribute on a
|
||||
``Response`` object to a method, that would only happen in a Major release.
|
||||
|
||||
Major releases may also include miscellaneous bug fixes. The core developers of
|
||||
Requests are committed to providing a good user experience. This means we're
|
||||
also committed to preserving backwards compatibility as much as possible. Major
|
||||
releases will be infrequent and will need strong justifications before they are
|
||||
considered.
|
||||
Major releases may also include miscellaneous bug fixes and upgrades to
|
||||
vendored packages. The core developers of Requests are committed to providing
|
||||
a good user experience. This means we're also committed to preserving
|
||||
backwards compatibility as much as possible. Major releases will be infrequent
|
||||
and will need strong justifications before they are considered.
|
||||
|
||||
Minor Releases
|
||||
--------------
|
||||
|
||||
A minor release will not include breaking changes but may include miscellaneous
|
||||
bug fixes. If the previous version of Requests released was ``v10.2.7`` a minor
|
||||
release would be versioned as ``v10.3.0``.
|
||||
A minor release will not include breaking changes but may include
|
||||
miscellaneous bug fixes and upgrades to vendored packages. If the previous
|
||||
version of Requests released was ``v10.2.7`` a minor release would be
|
||||
versioned as ``v10.3.0``.
|
||||
|
||||
Minor releases will be backwards compatible with releases that have the same
|
||||
major version number. In other words, all versions that would start with
|
||||
|
||||
@@ -5,27 +5,47 @@ Support
|
||||
|
||||
If you have questions or issues about Requests, there are several options:
|
||||
|
||||
Stack Overflow
|
||||
--------------
|
||||
StackOverflow
|
||||
-------------
|
||||
|
||||
If your question does not contain sensitive (possibly proprietary)
|
||||
information or can be properly anonymized, please ask a question on
|
||||
`Stack Overflow <https://stackoverflow.com/questions/tagged/python-requests>`_
|
||||
`StackOverflow <https://stackoverflow.com/questions/tagged/python-requests>`_
|
||||
and use the tag ``python-requests``.
|
||||
|
||||
Send a Tweet
|
||||
------------
|
||||
|
||||
If your question is less than 140 characters, feel free to send a tweet to
|
||||
`@kennethreitz <https://twitter.com/kennethreitz>`_,
|
||||
`@sigmavirus24 <https://twitter.com/sigmavirus24>`_, or
|
||||
`@lukasaoz <https://twitter.com/lukasaoz>`_.
|
||||
|
||||
File an Issue
|
||||
-------------
|
||||
|
||||
If you notice some unexpected behaviour in Requests, or want to see support
|
||||
for a new feature,
|
||||
`file an issue on GitHub <https://github.com/psf/requests/issues>`_.
|
||||
`file an issue on GitHub <https://github.com/requests/requests/issues>`_.
|
||||
|
||||
|
||||
Send a Tweet
|
||||
------------
|
||||
E-mail
|
||||
------
|
||||
|
||||
If your question is less than 280 characters, feel free to send a tweet to
|
||||
`@nateprewitt <https://twitter.com/nateprewitt>`_,
|
||||
`@sethmlarson <https://twitter.com/sethmlarson>`_, or
|
||||
`@sigmavirus24 <https://twitter.com/sigmavirus24>`_.
|
||||
I'm more than happy to answer any personal or in-depth questions about
|
||||
Requests. Feel free to email
|
||||
`requests@kennethreitz.com <mailto:requests@kennethreitz.com>`_.
|
||||
|
||||
|
||||
IRC
|
||||
---
|
||||
|
||||
The official Freenode channel for Requests is
|
||||
`#python-requests <irc://irc.freenode.net/python-requests>`_
|
||||
|
||||
The core developers of requests are on IRC throughout the day.
|
||||
You can find them in ``#python-requests`` as:
|
||||
|
||||
- kennethreitz
|
||||
- lukasa
|
||||
- sigmavirus24
|
||||
|
||||
@@ -12,7 +12,19 @@ GitHub
|
||||
------
|
||||
|
||||
The best way to track the development of Requests is through
|
||||
`the GitHub repo <https://github.com/psf/requests>`_.
|
||||
`the GitHub repo <https://github.com/requests/requests>`_.
|
||||
|
||||
Twitter
|
||||
-------
|
||||
|
||||
The author, Kenneth Reitz, often tweets about new features and releases of Requests.
|
||||
|
||||
Follow `@kennethreitz <https://twitter.com/kennethreitz>`_ for updates.
|
||||
|
||||
|
||||
.. include:: ../../HISTORY.md
|
||||
|
||||
Release and Version History
|
||||
===========================
|
||||
|
||||
.. include:: ../../HISTORY.rst
|
||||
|
||||
|
||||
@@ -2,16 +2,14 @@ Vulnerability Disclosure
|
||||
========================
|
||||
|
||||
If you think you have found a potential security vulnerability in requests,
|
||||
please email `Nate <mailto:nate.prewitt@gmail.com>`_ and `Seth <mailto:@sethmichaellarson@gmail.com>`_ directly. **Do not file a public issue.**
|
||||
please email `sigmavirus24 <mailto:graffatcolmingov@gmail.com>`_ and
|
||||
`Lukasa <mailto:cory@lukasa.co.uk>`_ directly. **Do not file a public issue.**
|
||||
|
||||
Our PGP Key fingerprints are:
|
||||
|
||||
- 8722 7E29 AD9C FF5C FAC3 EA6A 44D3 FF97 B80D C864 (`@nateprewitt <https://keybase.io/nateprewitt>`_)
|
||||
- 0161 BB7E B208 B5E0 4FDC 9F81 D9DA 0A04 9113 F853 (@sigmavirus24)
|
||||
|
||||
- EDD5 6765 A9D8 4653 CBC8 A134 51B0 6736 1740 F5FC (`@sethmlarson <https://keybase.io/sethmlarson>`_)
|
||||
|
||||
You can also contact us on `Keybase <https://keybase.io/>`_ with the
|
||||
profiles above if desired.
|
||||
- 90DC AE40 FEA7 4B14 9B70 662D F25F 2144 EEC1 373D (@lukasa)
|
||||
|
||||
If English is not your first language, please try to describe the problem and
|
||||
its impact to the best of your ability. For greater detail, please use your
|
||||
@@ -95,16 +93,13 @@ if upgrading is not an option.
|
||||
Previous CVEs
|
||||
-------------
|
||||
|
||||
- Fixed in 2.20.0
|
||||
- `CVE 2018-18074 <https://cve.mitre.org/cgi-bin/cvename.cgi?name=2018-18074>`_
|
||||
|
||||
- Fixed in 2.6.0
|
||||
|
||||
- `CVE 2015-2296 <https://cve.mitre.org/cgi-bin/cvename.cgi?name=2015-2296>`_,
|
||||
- `CVE 2015-2296 <http://www.cve.mitre.org/cgi-bin/cvename.cgi?name=2015-2296>`_,
|
||||
reported by Matthew Daley of `BugFuzz <https://bugfuzz.com/>`_.
|
||||
|
||||
- Fixed in 2.3.0
|
||||
|
||||
- `CVE 2014-1829 <https://cve.mitre.org/cgi-bin/cvename.cgi?name=2014-1829>`_
|
||||
- `CVE 2014-1829 <http://www.cve.mitre.org/cgi-bin/cvename.cgi?name=2014-1829>`_
|
||||
|
||||
- `CVE 2014-1830 <https://cve.mitre.org/cgi-bin/cvename.cgi?name=2014-1830>`_
|
||||
- `CVE 2014-1830 <http://www.cve.mitre.org/cgi-bin/cvename.cgi?name=2014-1830>`_
|
||||
|
||||
210
docs/conf.py
@@ -18,11 +18,11 @@ import os
|
||||
# If extensions (or modules to document with autodoc) are in another directory,
|
||||
# add these directories to sys.path here. If the directory is relative to the
|
||||
# documentation root, use os.path.abspath to make it absolute, like shown here.
|
||||
# sys.path.insert(0, os.path.abspath('.'))
|
||||
#sys.path.insert(0, os.path.abspath('.'))
|
||||
|
||||
# Insert Requests' path into the system.
|
||||
sys.path.insert(0, os.path.abspath(".."))
|
||||
sys.path.insert(0, os.path.abspath("_themes"))
|
||||
sys.path.insert(0, os.path.abspath('..'))
|
||||
sys.path.insert(0, os.path.abspath('_themes'))
|
||||
|
||||
import requests
|
||||
|
||||
@@ -30,36 +30,36 @@ import requests
|
||||
# -- General configuration ------------------------------------------------
|
||||
|
||||
# If your documentation needs a minimal Sphinx version, state it here.
|
||||
# needs_sphinx = '1.0'
|
||||
#needs_sphinx = '1.0'
|
||||
|
||||
# Add any Sphinx extension module names here, as strings. They can be
|
||||
# extensions coming with Sphinx (named 'sphinx.ext.*') or your custom
|
||||
# ones.
|
||||
extensions = [
|
||||
"sphinx.ext.autodoc",
|
||||
"sphinx.ext.intersphinx",
|
||||
"sphinx.ext.todo",
|
||||
"sphinx.ext.viewcode",
|
||||
'sphinx.ext.autodoc',
|
||||
'sphinx.ext.intersphinx',
|
||||
'sphinx.ext.todo',
|
||||
'sphinx.ext.viewcode',
|
||||
]
|
||||
|
||||
# Add any paths that contain templates here, relative to this directory.
|
||||
templates_path = ["_templates"]
|
||||
templates_path = ['_templates']
|
||||
|
||||
# The suffix(es) of source filenames.
|
||||
# You can specify multiple suffix as a list of string:
|
||||
# source_suffix = ['.rst', '.md']
|
||||
source_suffix = ".rst"
|
||||
source_suffix = '.rst'
|
||||
|
||||
# The encoding of source files.
|
||||
# source_encoding = 'utf-8-sig'
|
||||
#source_encoding = 'utf-8-sig'
|
||||
|
||||
# The master toctree document.
|
||||
master_doc = "index"
|
||||
master_doc = 'index'
|
||||
|
||||
# General information about the project.
|
||||
project = u"Requests"
|
||||
copyright = u'MMXVIX. A <a href="https://kenreitz.org/projects">Kenneth Reitz</a> Project'
|
||||
author = u"Kenneth Reitz"
|
||||
project = u'Requests'
|
||||
copyright = u'MMXVII. A <a href="http://kennethreitz.com/pages/open-projects.html">Kenneth Reitz</a> Project'
|
||||
author = u'Kenneth Reitz'
|
||||
|
||||
# The version info for the project you're documenting, acts as replacement for
|
||||
# |version| and |release|, also used in various other places throughout the
|
||||
@@ -79,17 +79,17 @@ language = None
|
||||
|
||||
# There are two options for replacing |today|: either, you set today to some
|
||||
# non-false value, then it is used:
|
||||
# today = ''
|
||||
#today = ''
|
||||
# Else, today_fmt is used as the format for a strftime call.
|
||||
# today_fmt = '%B %d, %Y'
|
||||
#today_fmt = '%B %d, %Y'
|
||||
|
||||
# List of patterns, relative to source directory, that match files and
|
||||
# directories to ignore when looking for source files.
|
||||
exclude_patterns = ["_build"]
|
||||
exclude_patterns = ['_build']
|
||||
|
||||
# The reST default role (used for this markup: `text`) to use for all
|
||||
# documents.
|
||||
# default_role = None
|
||||
#default_role = None
|
||||
|
||||
# If true, '()' will be appended to :func: etc. cross-reference text.
|
||||
add_function_parentheses = False
|
||||
@@ -100,16 +100,16 @@ add_module_names = True
|
||||
|
||||
# If true, sectionauthor and moduleauthor directives will be shown in the
|
||||
# output. They are ignored by default.
|
||||
# show_authors = False
|
||||
#show_authors = False
|
||||
|
||||
# The name of the Pygments (syntax highlighting) style to use.
|
||||
pygments_style = "flask_theme_support.FlaskyStyle"
|
||||
pygments_style = 'flask_theme_support.FlaskyStyle'
|
||||
|
||||
# A list of ignored prefixes for module index sorting.
|
||||
# modindex_common_prefix = []
|
||||
#modindex_common_prefix = []
|
||||
|
||||
# If true, keep warnings as "system message" paragraphs in the built documents.
|
||||
# keep_warnings = False
|
||||
#keep_warnings = False
|
||||
|
||||
# If true, `todo` and `todoList` produce output, else they produce nothing.
|
||||
todo_include_todos = True
|
||||
@@ -119,52 +119,51 @@ todo_include_todos = True
|
||||
|
||||
# The theme to use for HTML and HTML Help pages. See the documentation for
|
||||
# a list of builtin themes.
|
||||
html_theme = "alabaster"
|
||||
html_theme = 'alabaster'
|
||||
|
||||
# Theme options are theme-specific and customize the look and feel of a theme
|
||||
# further. For a list of options available for each theme, see the
|
||||
# documentation.
|
||||
html_theme_options = {
|
||||
"show_powered_by": False,
|
||||
"github_user": "requests",
|
||||
"github_repo": "requests",
|
||||
"github_banner": True,
|
||||
"show_related": False,
|
||||
"note_bg": "#FFF59C",
|
||||
'show_powered_by': False,
|
||||
'github_user': 'requests',
|
||||
'github_repo': 'requests',
|
||||
'github_banner': True,
|
||||
'show_related': False
|
||||
}
|
||||
|
||||
# Add any paths that contain custom themes here, relative to this directory.
|
||||
# html_theme_path = []
|
||||
#html_theme_path = []
|
||||
|
||||
# The name for this set of Sphinx documents. If None, it defaults to
|
||||
# "<project> v<release> documentation".
|
||||
# html_title = None
|
||||
#html_title = None
|
||||
|
||||
# A shorter title for the navigation bar. Default is the same as html_title.
|
||||
# html_short_title = None
|
||||
#html_short_title = None
|
||||
|
||||
# The name of an image file (relative to this directory) to place at the top
|
||||
# of the sidebar.
|
||||
# html_logo = None
|
||||
#html_logo = None
|
||||
|
||||
# The name of an image file (within the static path) to use as favicon of the
|
||||
# docs. This file should be a Windows icon file (.ico) being 16x16 or 32x32
|
||||
# pixels large.
|
||||
# html_favicon = None
|
||||
#html_favicon = None
|
||||
|
||||
# Add any paths that contain custom static files (such as style sheets) here,
|
||||
# relative to this directory. They are copied after the builtin static files,
|
||||
# so a file named "default.css" will overwrite the builtin "default.css".
|
||||
html_static_path = ["_static"]
|
||||
html_static_path = ['_static']
|
||||
|
||||
# Add any extra paths that contain custom files (such as robots.txt or
|
||||
# .htaccess) here, relative to this directory. These files are copied
|
||||
# directly to the root of the documentation.
|
||||
# html_extra_path = []
|
||||
#html_extra_path = []
|
||||
|
||||
# If not '', a 'Last updated on:' timestamp is inserted at every page bottom,
|
||||
# using the given strftime format.
|
||||
# html_last_updated_fmt = '%b %d, %Y'
|
||||
#html_last_updated_fmt = '%b %d, %Y'
|
||||
|
||||
# If true, SmartyPants will be used to convert quotes and dashes to
|
||||
# typographically correct entities.
|
||||
@@ -172,29 +171,24 @@ html_use_smartypants = False
|
||||
|
||||
# Custom sidebar templates, maps document names to template names.
|
||||
html_sidebars = {
|
||||
"index": ["sidebarintro.html", "sourcelink.html", "searchbox.html", "hacks.html"],
|
||||
"**": [
|
||||
"sidebarlogo.html",
|
||||
"localtoc.html",
|
||||
"relations.html",
|
||||
"sourcelink.html",
|
||||
"searchbox.html",
|
||||
"hacks.html",
|
||||
],
|
||||
'index': ['sidebarintro.html', 'sourcelink.html', 'searchbox.html',
|
||||
'hacks.html'],
|
||||
'**': ['sidebarlogo.html', 'localtoc.html', 'relations.html',
|
||||
'sourcelink.html', 'searchbox.html', 'hacks.html']
|
||||
}
|
||||
|
||||
# Additional templates that should be rendered to pages, maps page names to
|
||||
# template names.
|
||||
# html_additional_pages = {}
|
||||
#html_additional_pages = {}
|
||||
|
||||
# If false, no module index is generated.
|
||||
# html_domain_indices = True
|
||||
#html_domain_indices = True
|
||||
|
||||
# If false, no index is generated.
|
||||
# html_use_index = True
|
||||
#html_use_index = True
|
||||
|
||||
# If true, the index is split into individual pages for each letter.
|
||||
# html_split_index = False
|
||||
#html_split_index = False
|
||||
|
||||
# If true, links to the reST sources are added to the pages.
|
||||
html_show_sourcelink = False
|
||||
@@ -208,77 +202,84 @@ html_show_copyright = True
|
||||
# If true, an OpenSearch description file will be output, and all pages will
|
||||
# contain a <link> tag referring to it. The value of this option must be the
|
||||
# base URL from which the finished HTML is served.
|
||||
# html_use_opensearch = ''
|
||||
#html_use_opensearch = ''
|
||||
|
||||
# This is the file name suffix for HTML files (e.g. ".xhtml").
|
||||
# html_file_suffix = None
|
||||
#html_file_suffix = None
|
||||
|
||||
# Language to be used for generating the HTML full-text search index.
|
||||
# Sphinx supports the following languages:
|
||||
# 'da', 'de', 'en', 'es', 'fi', 'fr', 'hu', 'it', 'ja'
|
||||
# 'nl', 'no', 'pt', 'ro', 'ru', 'sv', 'tr'
|
||||
# html_search_language = 'en'
|
||||
#html_search_language = 'en'
|
||||
|
||||
# A dictionary with options for the search language support, empty by default.
|
||||
# Now only 'ja' uses this config value
|
||||
# html_search_options = {'type': 'default'}
|
||||
#html_search_options = {'type': 'default'}
|
||||
|
||||
# The name of a javascript file (relative to the configuration directory) that
|
||||
# implements a search results scorer. If empty, the default will be used.
|
||||
# html_search_scorer = 'scorer.js'
|
||||
#html_search_scorer = 'scorer.js'
|
||||
|
||||
# Output file base name for HTML help builder.
|
||||
htmlhelp_basename = "Requestsdoc"
|
||||
htmlhelp_basename = 'Requestsdoc'
|
||||
|
||||
# -- Options for LaTeX output ---------------------------------------------
|
||||
|
||||
latex_elements = {
|
||||
# The paper size ('letterpaper' or 'a4paper').
|
||||
#'papersize': 'letterpaper',
|
||||
# The font size ('10pt', '11pt' or '12pt').
|
||||
#'pointsize': '10pt',
|
||||
# Additional stuff for the LaTeX preamble.
|
||||
#'preamble': '',
|
||||
# Latex figure (float) alignment
|
||||
#'figure_align': 'htbp',
|
||||
# The paper size ('letterpaper' or 'a4paper').
|
||||
#'papersize': 'letterpaper',
|
||||
|
||||
# The font size ('10pt', '11pt' or '12pt').
|
||||
#'pointsize': '10pt',
|
||||
|
||||
# Additional stuff for the LaTeX preamble.
|
||||
#'preamble': '',
|
||||
|
||||
# Latex figure (float) alignment
|
||||
#'figure_align': 'htbp',
|
||||
}
|
||||
|
||||
# Grouping the document tree into LaTeX files. List of tuples
|
||||
# (source start file, target name, title,
|
||||
# author, documentclass [howto, manual, or own class]).
|
||||
latex_documents = [
|
||||
(master_doc, "Requests.tex", u"Requests Documentation", u"Kenneth Reitz", "manual")
|
||||
(master_doc, 'Requests.tex', u'Requests Documentation',
|
||||
u'Kenneth Reitz', 'manual'),
|
||||
]
|
||||
|
||||
# The name of an image file (relative to this directory) to place at the top of
|
||||
# the title page.
|
||||
# latex_logo = None
|
||||
#latex_logo = None
|
||||
|
||||
# For "manual" documents, if this is true, then toplevel headings are parts,
|
||||
# not chapters.
|
||||
# latex_use_parts = False
|
||||
#latex_use_parts = False
|
||||
|
||||
# If true, show page references after internal links.
|
||||
# latex_show_pagerefs = False
|
||||
#latex_show_pagerefs = False
|
||||
|
||||
# If true, show URL addresses after external links.
|
||||
# latex_show_urls = False
|
||||
#latex_show_urls = False
|
||||
|
||||
# Documents to append as an appendix to all manuals.
|
||||
# latex_appendices = []
|
||||
#latex_appendices = []
|
||||
|
||||
# If false, no module index is generated.
|
||||
# latex_domain_indices = True
|
||||
#latex_domain_indices = True
|
||||
|
||||
|
||||
# -- Options for manual page output ---------------------------------------
|
||||
|
||||
# One entry per manual page. List of tuples
|
||||
# (source start file, name, description, authors, manual section).
|
||||
man_pages = [(master_doc, "requests", u"Requests Documentation", [author], 1)]
|
||||
man_pages = [
|
||||
(master_doc, 'requests', u'Requests Documentation',
|
||||
[author], 1)
|
||||
]
|
||||
|
||||
# If true, show URL addresses after external links.
|
||||
# man_show_urls = False
|
||||
#man_show_urls = False
|
||||
|
||||
|
||||
# -- Options for Texinfo output -------------------------------------------
|
||||
@@ -287,28 +288,22 @@ man_pages = [(master_doc, "requests", u"Requests Documentation", [author], 1)]
|
||||
# (source start file, target name, title, author,
|
||||
# dir menu entry, description, category)
|
||||
texinfo_documents = [
|
||||
(
|
||||
master_doc,
|
||||
"Requests",
|
||||
u"Requests Documentation",
|
||||
author,
|
||||
"Requests",
|
||||
"One line description of project.",
|
||||
"Miscellaneous",
|
||||
)
|
||||
(master_doc, 'Requests', u'Requests Documentation',
|
||||
author, 'Requests', 'One line description of project.',
|
||||
'Miscellaneous'),
|
||||
]
|
||||
|
||||
# Documents to append as an appendix to all manuals.
|
||||
# texinfo_appendices = []
|
||||
#texinfo_appendices = []
|
||||
|
||||
# If false, no module index is generated.
|
||||
# texinfo_domain_indices = True
|
||||
#texinfo_domain_indices = True
|
||||
|
||||
# How to display URL addresses: 'footnote', 'no', or 'inline'.
|
||||
# texinfo_show_urls = 'footnote'
|
||||
#texinfo_show_urls = 'footnote'
|
||||
|
||||
# If true, do not generate a @detailmenu in the "Top" node's menu.
|
||||
# texinfo_no_detailmenu = False
|
||||
#texinfo_no_detailmenu = False
|
||||
|
||||
|
||||
# -- Options for Epub output ----------------------------------------------
|
||||
@@ -320,67 +315,64 @@ epub_publisher = author
|
||||
epub_copyright = copyright
|
||||
|
||||
# The basename for the epub file. It defaults to the project name.
|
||||
# epub_basename = project
|
||||
#epub_basename = project
|
||||
|
||||
# The HTML theme for the epub output. Since the default themes are not
|
||||
# optimized for small screen space, using the same theme for HTML and epub
|
||||
# output is usually not wise. This defaults to 'epub', a theme designed to save
|
||||
# visual space.
|
||||
# epub_theme = 'epub'
|
||||
#epub_theme = 'epub'
|
||||
|
||||
# The language of the text. It defaults to the language option
|
||||
# or 'en' if the language is not set.
|
||||
# epub_language = ''
|
||||
#epub_language = ''
|
||||
|
||||
# The scheme of the identifier. Typical schemes are ISBN or URL.
|
||||
# epub_scheme = ''
|
||||
#epub_scheme = ''
|
||||
|
||||
# The unique identifier of the text. This can be a ISBN number
|
||||
# or the project homepage.
|
||||
# epub_identifier = ''
|
||||
#epub_identifier = ''
|
||||
|
||||
# A unique identification for the text.
|
||||
# epub_uid = ''
|
||||
#epub_uid = ''
|
||||
|
||||
# A tuple containing the cover image and cover page html template filenames.
|
||||
# epub_cover = ()
|
||||
#epub_cover = ()
|
||||
|
||||
# A sequence of (type, uri, title) tuples for the guide element of content.opf.
|
||||
# epub_guide = ()
|
||||
#epub_guide = ()
|
||||
|
||||
# HTML files that should be inserted before the pages created by sphinx.
|
||||
# The format is a list of tuples containing the path and title.
|
||||
# epub_pre_files = []
|
||||
#epub_pre_files = []
|
||||
|
||||
# HTML files that should be inserted after the pages created by sphinx.
|
||||
# The format is a list of tuples containing the path and title.
|
||||
# epub_post_files = []
|
||||
#epub_post_files = []
|
||||
|
||||
# A list of files that should not be packed into the epub file.
|
||||
epub_exclude_files = ["search.html"]
|
||||
epub_exclude_files = ['search.html']
|
||||
|
||||
# The depth of the table of contents in toc.ncx.
|
||||
# epub_tocdepth = 3
|
||||
#epub_tocdepth = 3
|
||||
|
||||
# Allow duplicate toc entries.
|
||||
# epub_tocdup = True
|
||||
#epub_tocdup = True
|
||||
|
||||
# Choose between 'default' and 'includehidden'.
|
||||
# epub_tocscope = 'default'
|
||||
#epub_tocscope = 'default'
|
||||
|
||||
# Fix unsupported image types using the Pillow.
|
||||
# epub_fix_images = False
|
||||
#epub_fix_images = False
|
||||
|
||||
# Scale large images.
|
||||
# epub_max_image_width = 0
|
||||
#epub_max_image_width = 0
|
||||
|
||||
# How to display URL addresses: 'footnote', 'no', or 'inline'.
|
||||
# epub_show_urls = 'inline'
|
||||
#epub_show_urls = 'inline'
|
||||
|
||||
# If false, no index is generated.
|
||||
# epub_use_index = True
|
||||
#epub_use_index = True
|
||||
|
||||
intersphinx_mapping = {
|
||||
"python": ("https://docs.python.org/3/", None),
|
||||
"urllib3": ("https://urllib3.readthedocs.io/en/latest", None),
|
||||
}
|
||||
intersphinx_mapping = {'urllib3': ('http://urllib3.readthedocs.io/en/latest', None)}
|
||||
|
||||
@@ -1,4 +1,5 @@
|
||||
Authors
|
||||
=======
|
||||
|
||||
|
||||
.. include:: ../../AUTHORS.rst
|
||||
|
||||
@@ -11,17 +11,22 @@ contributing to the Requests project is *very* generous of you.
|
||||
This document lays out guidelines and advice for contributing to this project.
|
||||
If you're thinking of contributing, please start by reading this document and
|
||||
getting a feel for how contributing to this project works. If you have any
|
||||
questions, feel free to reach out to either `Nate Prewitt`_, `Ian Cordasco`_,
|
||||
or `Seth Michael Larson`_, the primary maintainers.
|
||||
questions, feel free to reach out to either `Ian Cordasco`_ or `Cory Benfield`_,
|
||||
the primary maintainers.
|
||||
|
||||
.. _Ian Cordasco: http://www.coglib.com/~icordasc/
|
||||
.. _Nate Prewitt: https://www.nateprewitt.com/
|
||||
.. _Seth Michael Larson: https://sethmlarson.dev/
|
||||
.. _Cory Benfield: https://lukasa.co.uk/about
|
||||
|
||||
If you have non-technical feedback, philosophical ponderings, crazy ideas, or
|
||||
other general thoughts about Requests or its position within the Python
|
||||
ecosystem, the BDFL, `Kenneth Reitz`_, would love to hear from you.
|
||||
|
||||
The guide is split into sections based on the type of contribution you're
|
||||
thinking of making, with a section that covers general guidelines for all
|
||||
contributors.
|
||||
|
||||
.. _Kenneth Reitz: mailto:me@kennethreitz.org
|
||||
|
||||
Be Cordial
|
||||
----------
|
||||
|
||||
@@ -34,7 +39,7 @@ including reporting bugs or requesting features. This golden rule is
|
||||
**All contributions are welcome**, as long as
|
||||
everyone involved is treated with respect.
|
||||
|
||||
.. _be cordial or be on your way: https://www.kennethreitz.org/essays/be-cordial-or-be-on-your-way
|
||||
.. _be cordial or be on your way: http://kennethreitz.org/be-cordial-or-be-on-your-way/
|
||||
|
||||
.. _early-feedback:
|
||||
|
||||
@@ -122,14 +127,7 @@ the Requests codebase::
|
||||
foo = long_function_name(var_one, var_two,
|
||||
var_three, var_four)
|
||||
|
||||
No. Just don't. Please. This is much better::
|
||||
|
||||
foo = long_function_name(
|
||||
var_one,
|
||||
var_two,
|
||||
var_three,
|
||||
var_four,
|
||||
)
|
||||
No. Just don't. Please.
|
||||
|
||||
Docstrings are to follow the following syntaxes::
|
||||
|
||||
@@ -157,7 +155,7 @@ model methods (e.g. ``__repr__``) are typically the exception to this rule.
|
||||
|
||||
Thanks for helping to make the world a better place!
|
||||
|
||||
.. _PEP 8: https://pep8.org/
|
||||
.. _PEP 8: http://pep8.org
|
||||
.. _line continuations: https://www.python.org/dev/peps/pep-0008/#indentation
|
||||
|
||||
Documentation Contributions
|
||||
@@ -189,7 +187,7 @@ through the `GitHub issues`_, **both open and closed**, to confirm that the bug
|
||||
hasn't been reported before. Duplicate bug reports are a huge drain on the time
|
||||
of other contributors, and should be avoided as much as possible.
|
||||
|
||||
.. _GitHub issues: https://github.com/psf/requests/issues
|
||||
.. _GitHub issues: https://github.com/requests/requests/issues
|
||||
|
||||
|
||||
Feature Requests
|
||||
@@ -205,4 +203,4 @@ while keeping an open ear and mind.
|
||||
|
||||
If you believe there is a feature missing, feel free to raise a feature
|
||||
request, but please do be aware that the overwhelming likelihood is that your
|
||||
feature request will not be accepted.
|
||||
feature request will not be accepted.
|
||||
41
docs/dev/philosophy.rst
Normal file
@@ -0,0 +1,41 @@
|
||||
Development Philosophy
|
||||
======================
|
||||
|
||||
Requests is an open but opinionated library, created by an open but opinionated developer.
|
||||
|
||||
|
||||
Management Style
|
||||
~~~~~~~~~~~~~~~~
|
||||
|
||||
`Kenneth Reitz <http://kennethreitz.org>`_ is the BDFL. He has final say in any decision related to the Requests project. Kenneth is responsible for the direction and form of the library, as well as its presentation. In addition to making decisions based on technical merit, he is responsible for making decisions based on the development philosophy of Requests.
|
||||
|
||||
`Ian Cordasco <http://www.coglib.com/~icordasc/>`_ and `Cory Benfield <https://lukasa.co.uk/about/>`_ are the core contributors. They are responsible for triaging bug reports, reviewing pull requests and ensuring that Kenneth is kept up to speed with developments around the library. The day-to-day managing of the project is done by the core contributors. They are responsible for making judgements about whether or not a feature request is likely to be accepted by Kenneth. Their word is, in some ways, more final than Kenneth's.
|
||||
|
||||
Values
|
||||
~~~~~~
|
||||
|
||||
- Simplicity is always better than functionality.
|
||||
- Listen to everyone, then disregard it.
|
||||
- The API is all that matters. Everything else is secondary.
|
||||
- Fit the 90% use-case. Ignore the nay-sayers.
|
||||
|
||||
Semantic Versioning
|
||||
~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
For many years, the open source community has been plagued with version number dystonia. Numbers vary so greatly from project to project, they are practically meaningless.
|
||||
|
||||
Requests uses `Semantic Versioning <http://semver.org>`_. This specification seeks to put an end to this madness with a small set of practical guidelines for you and your colleagues to use in your next project.
|
||||
|
||||
Standard Library?
|
||||
~~~~~~~~~~~~~~~~~
|
||||
|
||||
Requests has no *active* plans to be included in the standard library. This decision has been discussed at length with Guido as well as numerous core developers.
|
||||
|
||||
Essentially, the standard library is where a library goes to die. It is appropriate for a module to be included when active development is no longer necessary.
|
||||
|
||||
Linux Distro Packages
|
||||
~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
Distributions have been made for many Linux repositories, including: Ubuntu, Debian, RHEL, and Arch.
|
||||
|
||||
These distributions are sometimes divergent forks, or are otherwise not kept up-to-date with the latest code and bugfixes. PyPI (and its mirrors) and GitHub are the official distribution sources; alternatives are not supported by the Requests project.
|
||||
64
docs/dev/todo.rst
Normal file
@@ -0,0 +1,64 @@
|
||||
How to Help
|
||||
===========
|
||||
|
||||
Requests is under active development, and contributions are more than welcome!
|
||||
|
||||
#. Check for open issues or open a fresh issue to start a discussion around a bug.
|
||||
There is a Contributor Friendly tag for issues that should be ideal for people who are not very
|
||||
familiar with the codebase yet.
|
||||
#. Fork `the repository <https://github.com/requests/requests>`_ on GitHub and start making your
|
||||
changes to a new branch.
|
||||
#. Write a test which shows that the bug was fixed.
|
||||
#. Send a pull request and bug the maintainer until it gets merged and published. :)
|
||||
Make sure to add yourself to `AUTHORS <https://github.com/requests/requests/blob/master/AUTHORS.rst>`_.
|
||||
|
||||
Feature Freeze
|
||||
--------------
|
||||
|
||||
As of v1.0.0, Requests has now entered a feature freeze. Requests for new
|
||||
features and Pull Requests implementing those features will not be accepted.
|
||||
|
||||
Development Dependencies
|
||||
------------------------
|
||||
|
||||
You'll need to install py.test in order to run the Requests' test suite::
|
||||
|
||||
$ venv .venv
|
||||
$ source .venv/bin/activate
|
||||
|
||||
$ make
|
||||
$ python setup.py test
|
||||
============================= test session starts ==============================
|
||||
platform darwin -- Python 3.4.4, pytest-3.0.6, py-1.4.32, pluggy-0.4.0
|
||||
...
|
||||
collected 445 items
|
||||
|
||||
tests/test_hooks.py ...
|
||||
tests/test_lowlevel.py ............
|
||||
tests/test_requests.py ...........................................................
|
||||
tests/test_structures.py ....................
|
||||
tests/test_testserver.py ...........
|
||||
tests/test_utils.py ..s...........................................................
|
||||
|
||||
============== 442 passed, 1 skipped, 2 xpassed in 46.48 seconds ===============
|
||||
|
||||
You can also run ``$ make tests`` to run against all supported Python versions, using tox/detox.
|
||||
|
||||
Runtime Environments
|
||||
--------------------
|
||||
|
||||
Requests currently supports the following versions of Python:
|
||||
|
||||
- Python 2.6
|
||||
- Python 2.7
|
||||
- Python 3.3
|
||||
- Python 3.4
|
||||
- Python 3.5
|
||||
- Python 3.6
|
||||
- PyPy
|
||||
|
||||
Google AppEngine is not officially supported although support is available
|
||||
with the `Requests-Toolbelt`_.
|
||||
|
||||
.. _Requests-Toolbelt: http://toolbelt.readthedocs.io/
|
||||
|
||||
@@ -3,25 +3,34 @@
|
||||
You can adapt this file completely to your liking, but it should at least
|
||||
contain the root `toctree` directive.
|
||||
|
||||
Requests: HTTP for Humans™
|
||||
==========================
|
||||
Requests: HTTP for Humans
|
||||
=========================
|
||||
|
||||
Release v\ |version|. (:ref:`Installation <install>`)
|
||||
|
||||
|
||||
.. image:: https://pepy.tech/badge/requests
|
||||
:target: https://pepy.tech/project/requests
|
||||
|
||||
.. image:: https://img.shields.io/pypi/l/requests.svg
|
||||
:target: https://pypi.org/project/requests/
|
||||
:target: https://pypi.python.org/pypi/requests
|
||||
|
||||
.. image:: https://img.shields.io/pypi/wheel/requests.svg
|
||||
:target: https://pypi.org/project/requests/
|
||||
:target: https://pypi.python.org/pypi/requests
|
||||
|
||||
.. image:: https://img.shields.io/pypi/pyversions/requests.svg
|
||||
:target: https://pypi.org/project/requests/
|
||||
:target: https://pypi.python.org/pypi/requests
|
||||
|
||||
**Requests** is an elegant and simple HTTP library for Python, built for human beings.
|
||||
.. image:: https://codecov.io/github/requests/requests/coverage.svg?branch=master
|
||||
:target: https://codecov.io/github/requests/requests
|
||||
:alt: codecov.io
|
||||
|
||||
.. image:: https://img.shields.io/badge/Say%20Thanks!-🦉-1EAEDB.svg
|
||||
:target: https://saythanks.io/to/kennethreitz
|
||||
|
||||
|
||||
**Requests** is the only *Non-GMO* HTTP library for Python, safe for human
|
||||
consumption.
|
||||
|
||||
*Warning: Recreational use of the Python standard library for HTTP may result in dangerous side-effects,
|
||||
including: security vulnerabilities, verbose code, reinventing the wheel,
|
||||
constantly reading documentation, depression, headaches, or even death.*
|
||||
|
||||
-------------------
|
||||
|
||||
@@ -35,17 +44,44 @@ Release v\ |version|. (:ref:`Installation <install>`)
|
||||
>>> r.encoding
|
||||
'utf-8'
|
||||
>>> r.text
|
||||
'{"type":"User"...'
|
||||
u'{"type":"User"...'
|
||||
>>> r.json()
|
||||
{'private_gists': 419, 'total_private_repos': 77, ...}
|
||||
{u'private_gists': 419, u'total_private_repos': 77, ...}
|
||||
|
||||
See `similar code, sans Requests <https://gist.github.com/973705>`_.
|
||||
|
||||
|
||||
**Requests** allows you to send HTTP/1.1 requests extremely easily.
|
||||
There's no need to manually add query strings to your
|
||||
**Requests** allows you to send *organic, grass-fed* HTTP/1.1 requests, without the
|
||||
need for manual labor. There's no need to manually add query strings to your
|
||||
URLs, or to form-encode your POST data. Keep-alive and HTTP connection pooling
|
||||
are 100% automatic, thanks to `urllib3 <https://github.com/urllib3/urllib3>`_.
|
||||
are 100% automatic, thanks to `urllib3 <https://github.com/shazow/urllib3>`_.
|
||||
|
||||
User Testimonials
|
||||
-----------------
|
||||
|
||||
Twitter, Spotify, Microsoft, Amazon, Lyft, BuzzFeed, Reddit, The NSA, Her Majesty's Government, Google, Twilio, Runscope, Mozilla, Heroku,
|
||||
PayPal, NPR, Obama for America, Transifex, Native Instruments, The Washington
|
||||
Post, SoundCloud, Kippt, Sony, and Federal U.S.
|
||||
Institutions that prefer to be unnamed claim to use Requests internally.
|
||||
|
||||
**Armin Ronacher**—
|
||||
*Requests is the perfect example how beautiful an API can be with the
|
||||
right level of abstraction.*
|
||||
|
||||
**Matt DeBoard**—
|
||||
*I'm going to get Kenneth Reitz's Python requests module tattooed
|
||||
on my body, somehow. The whole thing.*
|
||||
|
||||
**Daniel Greenfeld**—
|
||||
*Nuked a 1200 LOC spaghetti code library with 10 lines of code thanks to
|
||||
Kenneth Reitz's request library. Today has been AWESOME.*
|
||||
|
||||
**Kenny Meyers**—
|
||||
*Python HTTP: When in doubt, or when not in doubt, use Requests. Beautiful,
|
||||
simple, Pythonic.*
|
||||
|
||||
Requests is one of the most downloaded Python packages of all time, pulling in
|
||||
over 11,000,000 downloads every month. All the cool kids are doing it!
|
||||
|
||||
Beloved Features
|
||||
----------------
|
||||
@@ -68,7 +104,7 @@ Requests is ready for today's web.
|
||||
- Chunked Requests
|
||||
- ``.netrc`` Support
|
||||
|
||||
Requests officially supports Python 2.7 & 3.5+, and runs great on PyPy.
|
||||
Requests officially supports Python 2.6–2.7 & 3.3–3.7, and runs great on PyPy.
|
||||
|
||||
|
||||
The User Guide
|
||||
@@ -81,6 +117,7 @@ instructions for getting the most out of Requests.
|
||||
.. toctree::
|
||||
:maxdepth: 2
|
||||
|
||||
user/intro
|
||||
user/install
|
||||
user/quickstart
|
||||
user/advanced
|
||||
@@ -94,19 +131,15 @@ This part of the documentation, which is mostly prose, details the
|
||||
Requests ecosystem and community.
|
||||
|
||||
.. toctree::
|
||||
:maxdepth: 2
|
||||
:maxdepth: 1
|
||||
|
||||
community/recommended
|
||||
community/faq
|
||||
community/recommended
|
||||
community/out-there
|
||||
community/support
|
||||
community/vulnerabilities
|
||||
community/release-process
|
||||
|
||||
.. toctree::
|
||||
:maxdepth: 1
|
||||
|
||||
community/updates
|
||||
community/release-process
|
||||
|
||||
The API Documentation / Guide
|
||||
-----------------------------
|
||||
@@ -130,6 +163,8 @@ you.
|
||||
:maxdepth: 3
|
||||
|
||||
dev/contributing
|
||||
dev/philosophy
|
||||
dev/todo
|
||||
dev/authors
|
||||
|
||||
There are no more guides. You are now guideless.
|
||||
|
||||
@@ -23,8 +23,8 @@ Let's persist some cookies across requests::
|
||||
|
||||
s = requests.Session()
|
||||
|
||||
s.get('https://httpbin.org/cookies/set/sessioncookie/123456789')
|
||||
r = s.get('https://httpbin.org/cookies')
|
||||
s.get('http://httpbin.org/cookies/set/sessioncookie/123456789')
|
||||
r = s.get('http://httpbin.org/cookies')
|
||||
|
||||
print(r.text)
|
||||
# '{"cookies": {"sessioncookie": "123456789"}}'
|
||||
@@ -38,7 +38,7 @@ is done by providing data to the properties on a Session object::
|
||||
s.headers.update({'x-test': 'true'})
|
||||
|
||||
# both 'x-test' and 'x-test2' are sent
|
||||
s.get('https://httpbin.org/headers', headers={'x-test2': 'true'})
|
||||
s.get('http://httpbin.org/headers', headers={'x-test2': 'true'})
|
||||
|
||||
|
||||
Any dictionaries that you pass to a request method will be merged with the
|
||||
@@ -51,11 +51,11 @@ with the first request, but not the second::
|
||||
|
||||
s = requests.Session()
|
||||
|
||||
r = s.get('https://httpbin.org/cookies', cookies={'from-my': 'browser'})
|
||||
r = s.get('http://httpbin.org/cookies', cookies={'from-my': 'browser'})
|
||||
print(r.text)
|
||||
# '{"cookies": {"from-my": "browser"}}'
|
||||
|
||||
r = s.get('https://httpbin.org/cookies')
|
||||
r = s.get('http://httpbin.org/cookies')
|
||||
print(r.text)
|
||||
# '{"cookies": {}}'
|
||||
|
||||
@@ -67,7 +67,7 @@ If you want to manually add cookies to your session, use the
|
||||
Sessions can also be used as context managers::
|
||||
|
||||
with requests.Session() as s:
|
||||
s.get('https://httpbin.org/cookies/set/sessioncookie/123456789')
|
||||
s.get('http://httpbin.org/cookies/set/sessioncookie/123456789')
|
||||
|
||||
This will make sure the session is closed as soon as the ``with`` block is
|
||||
exited, even if unhandled exceptions occurred.
|
||||
@@ -95,7 +95,7 @@ The ``Response`` object contains all of the information returned by the server a
|
||||
also contains the ``Request`` object you created originally. Here is a simple
|
||||
request to get some very important information from Wikipedia's servers::
|
||||
|
||||
>>> r = requests.get('https://en.wikipedia.org/wiki/Monty_Python')
|
||||
>>> r = requests.get('http://en.wikipedia.org/wiki/Monty_Python')
|
||||
|
||||
If we want to access the headers the server sent back to us, we do this::
|
||||
|
||||
@@ -187,25 +187,6 @@ applied, replace the call to :meth:`Request.prepare()
|
||||
|
||||
print(resp.status_code)
|
||||
|
||||
When you are using the prepared request flow, keep in mind that it does not take into account the environment.
|
||||
This can cause problems if you are using environment variables to change the behaviour of requests.
|
||||
For example: Self-signed SSL certificates specified in ``REQUESTS_CA_BUNDLE`` will not be taken into account.
|
||||
As a result an ``SSL: CERTIFICATE_VERIFY_FAILED`` is thrown.
|
||||
You can get around this behaviour by explicitly merging the environment settings into your session::
|
||||
|
||||
from requests import Request, Session
|
||||
|
||||
s = Session()
|
||||
req = Request('GET', url)
|
||||
|
||||
prepped = s.prepare_request(req)
|
||||
|
||||
# Merge environment settings into session
|
||||
settings = s.merge_environment_settings(prepped.url, {}, None, None, None)
|
||||
resp = s.send(prepped, **settings)
|
||||
|
||||
print(resp.status_code)
|
||||
|
||||
.. _verification:
|
||||
|
||||
SSL Cert Verification
|
||||
@@ -236,19 +217,12 @@ or persistent::
|
||||
the c_rehash utility supplied with OpenSSL.
|
||||
|
||||
This list of trusted CAs can also be specified through the ``REQUESTS_CA_BUNDLE`` environment variable.
|
||||
If ``REQUESTS_CA_BUNDLE`` is not set, ``CURL_CA_BUNDLE`` will be used as fallback.
|
||||
|
||||
Requests can also ignore verifying the SSL certificate if you set ``verify`` to False::
|
||||
|
||||
>>> requests.get('https://kennethreitz.org', verify=False)
|
||||
<Response [200]>
|
||||
|
||||
Note that when ``verify`` is set to ``False``, requests will accept any TLS
|
||||
certificate presented by the server, and will ignore hostname mismatches
|
||||
and/or expired certificates, which will make your application vulnerable to
|
||||
man-in-the-middle (MitM) attacks. Setting verify to ``False`` may be useful
|
||||
during local development or testing.
|
||||
|
||||
By default, ``verify`` is set to True. Option ``verify`` only applies to host certs.
|
||||
|
||||
Client Side Certificates
|
||||
@@ -279,20 +253,21 @@ If you specify a wrong path or an invalid cert, you'll get a SSLError::
|
||||
CA Certificates
|
||||
---------------
|
||||
|
||||
Requests uses certificates from the package `certifi`_. This allows for users
|
||||
to update their trusted certificates without changing the version of Requests.
|
||||
By default, Requests bundles a set of root CAs that it trusts, sourced from the
|
||||
`Mozilla trust store`_. However, these are only updated once for each Requests
|
||||
version. This means that if you pin a Requests version your certificates can
|
||||
become extremely out of date.
|
||||
|
||||
Before version 2.16, Requests bundled a set of root CAs that it trusted,
|
||||
sourced from the `Mozilla trust store`_. The certificates were only updated
|
||||
once for each Requests version. When ``certifi`` was not installed, this led to
|
||||
extremely out-of-date certificate bundles when using significantly older
|
||||
versions of Requests.
|
||||
From Requests version 2.4.0 onwards, Requests will attempt to use certificates
|
||||
from `certifi`_ if it is present on the system. This allows for users to update
|
||||
their trusted certificates without having to change the code that runs on their
|
||||
system.
|
||||
|
||||
For the sake of security we recommend upgrading certifi frequently!
|
||||
|
||||
.. _HTTP persistent connection: https://en.wikipedia.org/wiki/HTTP_persistent_connection
|
||||
.. _connection pooling: https://urllib3.readthedocs.io/en/latest/reference/index.html#module-urllib3.connectionpool
|
||||
.. _certifi: https://certifiio.readthedocs.io/
|
||||
.. _connection pooling: http://urllib3.readthedocs.io/en/latest/reference/index.html#module-urllib3.connectionpool
|
||||
.. _certifi: http://certifi.io/
|
||||
.. _Mozilla trust store: https://hg.mozilla.org/mozilla-central/raw-file/tip/security/nss/lib/ckfw/builtins/certdata.txt
|
||||
|
||||
.. _body-content-workflow:
|
||||
@@ -305,7 +280,7 @@ immediately. You can override this behaviour and defer downloading the response
|
||||
body until you access the :attr:`Response.content <requests.Response.content>`
|
||||
attribute with the ``stream`` parameter::
|
||||
|
||||
tarball_url = 'https://github.com/psf/requests/tarball/master'
|
||||
tarball_url = 'https://github.com/requests/requests/tarball/master'
|
||||
r = requests.get(tarball_url, stream=True)
|
||||
|
||||
At this point only the response headers have been downloaded and the connection
|
||||
@@ -326,11 +301,15 @@ release the connection back to the pool unless you consume all the data or call
|
||||
:meth:`Response.close <requests.Response.close>`. This can lead to
|
||||
inefficiency with connections. If you find yourself partially reading request
|
||||
bodies (or not reading them at all) while using ``stream=True``, you should
|
||||
make the request within a ``with`` statement to ensure it's always closed::
|
||||
consider using ``contextlib.closing`` (`documented here`_), like this::
|
||||
|
||||
with requests.get('https://httpbin.org/get', stream=True) as r:
|
||||
from contextlib import closing
|
||||
|
||||
with closing(requests.get('http://httpbin.org/get', stream=True)) as r:
|
||||
# Do things with the response here.
|
||||
|
||||
.. _`documented here`: http://docs.python.org/2/library/contextlib.html#contextlib.closing
|
||||
|
||||
.. _keep-alive:
|
||||
|
||||
Keep-Alive
|
||||
@@ -356,11 +335,13 @@ file-like object for your body::
|
||||
with open('massive-body', 'rb') as f:
|
||||
requests.post('http://some.url/streamed', data=f)
|
||||
|
||||
.. warning:: It is strongly recommended that you open files in :ref:`binary
|
||||
mode <tut-files>`. This is because Requests may attempt to provide
|
||||
the ``Content-Length`` header for you, and if it does this value
|
||||
will be set to the number of *bytes* in the file. Errors may occur
|
||||
if you open the file in *text mode*.
|
||||
.. warning:: It is strongly recommended that you open files in `binary mode`_.
|
||||
This is because Requests may attempt to provide the
|
||||
``Content-Length`` header for you, and if it does this value will
|
||||
be set to the number of *bytes* in the file. Errors may occur if
|
||||
you open the file in *text mode*.
|
||||
|
||||
.. _binary mode: https://docs.python.org/2/tutorial/inputoutput.html#reading-and-writing-files
|
||||
|
||||
|
||||
.. _chunk-encoding:
|
||||
@@ -398,10 +379,10 @@ upload image files to an HTML form with a multiple file field 'images'::
|
||||
|
||||
To do that, just set files to a list of tuples of ``(form_field_name, file_info)``::
|
||||
|
||||
>>> url = 'https://httpbin.org/post'
|
||||
>>> url = 'http://httpbin.org/post'
|
||||
>>> multiple_files = [
|
||||
... ('images', ('foo.png', open('foo.png', 'rb'), 'image/png')),
|
||||
... ('images', ('bar.png', open('bar.png', 'rb'), 'image/png'))]
|
||||
('images', ('foo.png', open('foo.png', 'rb'), 'image/png')),
|
||||
('images', ('bar.png', open('bar.png', 'rb'), 'image/png'))]
|
||||
>>> r = requests.post(url, files=multiple_files)
|
||||
>>> r.text
|
||||
{
|
||||
@@ -411,11 +392,13 @@ To do that, just set files to a list of tuples of ``(form_field_name, file_info)
|
||||
...
|
||||
}
|
||||
|
||||
.. warning:: It is strongly recommended that you open files in :ref:`binary
|
||||
mode <tut-files>`. This is because Requests may attempt to provide
|
||||
the ``Content-Length`` header for you, and if it does this value
|
||||
will be set to the number of *bytes* in the file. Errors may occur
|
||||
if you open the file in *text mode*.
|
||||
.. warning:: It is strongly recommended that you open files in `binary mode`_.
|
||||
This is because Requests may attempt to provide the
|
||||
``Content-Length`` header for you, and if it does this value will
|
||||
be set to the number of *bytes* in the file. Errors may occur if
|
||||
you open the file in *text mode*.
|
||||
|
||||
.. _binary mode: https://docs.python.org/2/tutorial/inputoutput.html#reading-and-writing-files
|
||||
|
||||
|
||||
.. _event-hooks:
|
||||
@@ -436,7 +419,7 @@ You can assign a hook function on a per-request basis by passing a
|
||||
``{hook_name: callback_function}`` dictionary to the ``hooks`` request
|
||||
parameter::
|
||||
|
||||
hooks={'response': print_url}
|
||||
hooks=dict(response=print_url)
|
||||
|
||||
That ``callback_function`` will receive a chunk of data as its first
|
||||
argument.
|
||||
@@ -450,44 +433,20 @@ If an error occurs while executing your callback, a warning is given.
|
||||
|
||||
If the callback function returns a value, it is assumed that it is to
|
||||
replace the data that was passed in. If the function doesn't return
|
||||
anything, nothing else is affected.
|
||||
|
||||
::
|
||||
|
||||
def record_hook(r, *args, **kwargs):
|
||||
r.hook_called = True
|
||||
return r
|
||||
anything, nothing else is effected.
|
||||
|
||||
Let's print some request method arguments at runtime::
|
||||
|
||||
>>> requests.get('https://httpbin.org/', hooks={'response': print_url})
|
||||
https://httpbin.org/
|
||||
>>> requests.get('http://httpbin.org', hooks=dict(response=print_url))
|
||||
http://httpbin.org
|
||||
<Response [200]>
|
||||
|
||||
You can add multiple hooks to a single request. Let's call two hooks at once::
|
||||
|
||||
>>> r = requests.get('https://httpbin.org/', hooks={'response': [print_url, record_hook]})
|
||||
>>> r.hook_called
|
||||
True
|
||||
|
||||
You can also add hooks to a ``Session`` instance. Any hooks you add will then
|
||||
be called on every request made to the session. For example::
|
||||
|
||||
>>> s = requests.Session()
|
||||
>>> s.hooks['response'].append(print_url)
|
||||
>>> s.get('https://httpbin.org/')
|
||||
https://httpbin.org/
|
||||
<Response [200]>
|
||||
|
||||
A ``Session`` can have multiple hooks, which will be called in the order
|
||||
they are added.
|
||||
|
||||
.. _custom-auth:
|
||||
|
||||
Custom Authentication
|
||||
---------------------
|
||||
|
||||
Requests allows you to specify your own authentication mechanism.
|
||||
Requests allows you to use specify your own authentication mechanism.
|
||||
|
||||
Any callable which is passed as the ``auth`` argument to a request method will
|
||||
have the opportunity to modify the request before it is dispatched.
|
||||
@@ -534,7 +493,7 @@ set ``stream`` to ``True`` and iterate over the response with
|
||||
import json
|
||||
import requests
|
||||
|
||||
r = requests.get('https://httpbin.org/stream/20', stream=True)
|
||||
r = requests.get('http://httpbin.org/stream/20', stream=True)
|
||||
|
||||
for line in r.iter_lines():
|
||||
|
||||
@@ -548,7 +507,7 @@ When using `decode_unicode=True` with
|
||||
:meth:`Response.iter_content() <requests.Response.iter_content>`, you'll want
|
||||
to provide a fallback encoding in the event the server doesn't provide one::
|
||||
|
||||
r = requests.get('https://httpbin.org/stream/20', stream=True)
|
||||
r = requests.get('http://httpbin.org/stream/20', stream=True)
|
||||
|
||||
if r.encoding is None:
|
||||
r.encoding = 'utf-8'
|
||||
@@ -589,26 +548,10 @@ If you need to use a proxy, you can configure individual requests with the
|
||||
|
||||
requests.get('http://example.org', proxies=proxies)
|
||||
|
||||
Alternatively you can configure it once for an entire
|
||||
:class:`Session <requests.Session>`::
|
||||
You can also configure proxies by setting the environment variables
|
||||
``HTTP_PROXY`` and ``HTTPS_PROXY``.
|
||||
|
||||
import requests
|
||||
|
||||
proxies = {
|
||||
'http': 'http://10.10.1.10:3128',
|
||||
'https': 'http://10.10.1.10:1080',
|
||||
}
|
||||
session = request.Session()
|
||||
session.proxies.update(proxies)
|
||||
|
||||
session.get('http://example.org')
|
||||
|
||||
When the proxies configuration is not overridden in python as shown above,
|
||||
by default Requests relies on the proxy configuration defined by standard
|
||||
environment variables ``http_proxy``, ``https_proxy``, ``no_proxy`` and
|
||||
``curl_ca_bundle``. Uppercase variants of these variables are also supported.
|
||||
You can therefore set them to configure Requests (only set the ones relevant
|
||||
to your needs)::
|
||||
::
|
||||
|
||||
$ export HTTP_PROXY="http://10.10.1.10:3128"
|
||||
$ export HTTPS_PROXY="http://10.10.1.10:1080"
|
||||
@@ -617,17 +560,9 @@ to your needs)::
|
||||
>>> import requests
|
||||
>>> requests.get('http://example.org')
|
||||
|
||||
To use HTTP Basic Auth with your proxy, use the `http://user:password@host/`
|
||||
syntax in any of the above configuration entries::
|
||||
To use HTTP Basic Auth with your proxy, use the `http://user:password@host/` syntax::
|
||||
|
||||
$ export HTTPS_PROXY="http://user:pass@10.10.1.10:1080"
|
||||
|
||||
$ python
|
||||
>>> proxies = {'http': 'http://user:pass@10.10.1.10:3128/'}
|
||||
|
||||
.. warning:: Storing sensitive username and password information in an
|
||||
environment variable or a version-controled file is a security risk and is
|
||||
highly discouraged.
|
||||
proxies = {'http': 'http://user:pass@10.10.1.10:3128/'}
|
||||
|
||||
To give a proxy for a specific scheme and host, use the
|
||||
`scheme://hostname` form for the key. This will match for
|
||||
@@ -639,23 +574,6 @@ any request to the given scheme and exact hostname.
|
||||
|
||||
Note that proxy URLs must include the scheme.
|
||||
|
||||
Finally, note that using a proxy for https connections typically requires your
|
||||
local machine to trust the proxy's root certificate. By default the list of
|
||||
certificates trusted by Requests can be found with::
|
||||
|
||||
from requests.utils import DEFAULT_CA_BUNDLE_PATH
|
||||
print(DEFAULT_CA_BUNDLE_PATH)
|
||||
|
||||
You override this default certificate bundle by setting the standard
|
||||
``curl_ca_bundle`` environment variable to another file path::
|
||||
|
||||
$ export curl_ca_bundle="/usr/local/myproxy_info/cacert.pem"
|
||||
$ export https_proxy="http://10.10.1.10:1080"
|
||||
|
||||
$ python
|
||||
>>> import requests
|
||||
>>> requests.get('https://example.org')
|
||||
|
||||
SOCKS
|
||||
^^^^^
|
||||
|
||||
@@ -669,7 +587,7 @@ You can get the dependencies for this feature from ``pip``:
|
||||
|
||||
.. code-block:: bash
|
||||
|
||||
$ python -m pip install requests[socks]
|
||||
$ pip install requests[socks]
|
||||
|
||||
Once you've installed those dependencies, using a SOCKS proxy is just as easy
|
||||
as using a HTTP one::
|
||||
@@ -679,8 +597,6 @@ as using a HTTP one::
|
||||
'https': 'socks5://user:pass@host:port'
|
||||
}
|
||||
|
||||
Using the scheme ``socks5`` causes the DNS resolution to happen on the client, rather than on the proxy server. This is in line with curl, which uses the scheme to decide whether to do the DNS resolution on the client or proxy. If you want to resolve the domains on the proxy server, use ``socks5h`` as the scheme.
|
||||
|
||||
.. _compliance:
|
||||
|
||||
Compliance
|
||||
@@ -698,12 +614,12 @@ When you receive a response, Requests makes a guess at the encoding to
|
||||
use for decoding the response when you access the :attr:`Response.text
|
||||
<requests.Response.text>` attribute. Requests will first check for an
|
||||
encoding in the HTTP header, and if none is present, will use `chardet
|
||||
<https://pypi.org/project/chardet/>`_ to attempt to guess the encoding.
|
||||
<http://pypi.python.org/pypi/chardet>`_ to attempt to guess the encoding.
|
||||
|
||||
The only time Requests will not do this is if no explicit charset
|
||||
is present in the HTTP headers **and** the ``Content-Type``
|
||||
header contains ``text``. In this situation, `RFC 2616
|
||||
<https://www.w3.org/Protocols/rfc2616/rfc2616-sec3.html#sec3.7.1>`_ specifies
|
||||
<http://www.w3.org/Protocols/rfc2616/rfc2616-sec3.html#sec3.7.1>`_ specifies
|
||||
that the default charset must be ``ISO-8859-1``. Requests follows the
|
||||
specification in this case. If you require a different encoding, you can
|
||||
manually set the :attr:`Response.encoding <requests.Response.encoding>`
|
||||
@@ -726,7 +642,7 @@ from GitHub. Suppose we wanted commit ``a050faf`` on Requests. We would get it
|
||||
like so::
|
||||
|
||||
>>> import requests
|
||||
>>> r = requests.get('https://api.github.com/repos/psf/requests/git/commits/a050faf084662f3a352dd1a941f2c7c9f886d4ad')
|
||||
>>> r = requests.get('https://api.github.com/repos/requests/requests/git/commits/a050faf084662f3a352dd1a941f2c7c9f886d4ad')
|
||||
|
||||
We should confirm that GitHub responded correctly. If it has, we want to work
|
||||
out what type of content it is. Do this like so::
|
||||
@@ -744,12 +660,12 @@ So, GitHub returns JSON. That's great, we can use the :meth:`r.json
|
||||
>>> commit_data = r.json()
|
||||
|
||||
>>> print(commit_data.keys())
|
||||
['committer', 'author', 'url', 'tree', 'sha', 'parents', 'message']
|
||||
[u'committer', u'author', u'url', u'tree', u'sha', u'parents', u'message']
|
||||
|
||||
>>> print(commit_data['committer'])
|
||||
{'date': '2012-05-10T11:10:50-07:00', 'email': 'me@kennethreitz.com', 'name': 'Kenneth Reitz'}
|
||||
>>> print(commit_data[u'committer'])
|
||||
{u'date': u'2012-05-10T11:10:50-07:00', u'email': u'me@kennethreitz.com', u'name': u'Kenneth Reitz'}
|
||||
|
||||
>>> print(commit_data['message'])
|
||||
>>> print(commit_data[u'message'])
|
||||
makin' history
|
||||
|
||||
So far, so simple. Well, let's investigate the GitHub API a little bit. Now,
|
||||
@@ -781,37 +697,37 @@ we should probably avoid making ham-handed POSTS to it. Instead, let's play
|
||||
with the Issues feature of GitHub.
|
||||
|
||||
This documentation was added in response to
|
||||
`Issue #482 <https://github.com/psf/requests/issues/482>`_. Given that
|
||||
`Issue #482 <https://github.com/requests/requests/issues/482>`_. Given that
|
||||
this issue already exists, we will use it as an example. Let's start by getting it.
|
||||
|
||||
::
|
||||
|
||||
>>> r = requests.get('https://api.github.com/repos/psf/requests/issues/482')
|
||||
>>> r = requests.get('https://api.github.com/repos/requests/requests/issues/482')
|
||||
>>> r.status_code
|
||||
200
|
||||
|
||||
>>> issue = json.loads(r.text)
|
||||
|
||||
>>> print(issue['title'])
|
||||
>>> print(issue[u'title'])
|
||||
Feature any http verb in docs
|
||||
|
||||
>>> print(issue['comments'])
|
||||
>>> print(issue[u'comments'])
|
||||
3
|
||||
|
||||
Cool, we have three comments. Let's take a look at the last of them.
|
||||
|
||||
::
|
||||
|
||||
>>> r = requests.get(r.url + '/comments')
|
||||
>>> r = requests.get(r.url + u'/comments')
|
||||
>>> r.status_code
|
||||
200
|
||||
|
||||
>>> comments = r.json()
|
||||
|
||||
>>> print(comments[0].keys())
|
||||
['body', 'url', 'created_at', 'updated_at', 'user', 'id']
|
||||
[u'body', u'url', u'created_at', u'updated_at', u'user', u'id']
|
||||
|
||||
>>> print(comments[2]['body'])
|
||||
>>> print(comments[2][u'body'])
|
||||
Probably in the "advanced" section
|
||||
|
||||
Well, that seems like a silly place. Let's post a comment telling the poster
|
||||
@@ -819,7 +735,7 @@ that he's silly. Who is the poster, anyway?
|
||||
|
||||
::
|
||||
|
||||
>>> print(comments[2]['user']['login'])
|
||||
>>> print(comments[2][u'user'][u'login'])
|
||||
kennethreitz
|
||||
|
||||
OK, so let's tell this Kenneth guy that we think this example should go in the
|
||||
@@ -829,7 +745,7 @@ is to POST to the thread. Let's do it.
|
||||
::
|
||||
|
||||
>>> body = json.dumps({u"body": u"Sounds great! I'll get right on it!"})
|
||||
>>> url = u"https://api.github.com/repos/psf/requests/issues/482/comments"
|
||||
>>> url = u"https://api.github.com/repos/requests/requests/issues/482/comments"
|
||||
|
||||
>>> r = requests.post(url=url, data=body)
|
||||
>>> r.status_code
|
||||
@@ -849,7 +765,7 @@ the very common Basic Auth.
|
||||
201
|
||||
|
||||
>>> content = r.json()
|
||||
>>> print(content['body'])
|
||||
>>> print(content[u'body'])
|
||||
Sounds great! I'll get right on it.
|
||||
|
||||
Brilliant. Oh, wait, no! I meant to add that it would take me a while, because
|
||||
@@ -863,7 +779,7 @@ that.
|
||||
5804413
|
||||
|
||||
>>> body = json.dumps({u"body": u"Sounds great! I'll get right on it once I feed my cat."})
|
||||
>>> url = u"https://api.github.com/repos/psf/requests/issues/comments/5804413"
|
||||
>>> url = u"https://api.github.com/repos/requests/requests/issues/comments/5804413"
|
||||
|
||||
>>> r = requests.patch(url=url, data=body, auth=auth)
|
||||
>>> r.status_code
|
||||
@@ -925,7 +841,7 @@ Link Headers
|
||||
Many HTTP APIs feature Link headers. They make APIs more self describing and
|
||||
discoverable.
|
||||
|
||||
GitHub uses these for `pagination <https://developer.github.com/v3/#pagination>`_
|
||||
GitHub uses these for `pagination <http://developer.github.com/v3/#pagination>`_
|
||||
in their API, for example::
|
||||
|
||||
>>> url = 'https://api.github.com/users/kennethreitz/repos?page=1&per_page=10'
|
||||
@@ -967,7 +883,7 @@ it should apply to.
|
||||
::
|
||||
|
||||
>>> s = requests.Session()
|
||||
>>> s.mount('https://github.com/', MyAdapter())
|
||||
>>> s.mount('http://www.github.com', MyAdapter())
|
||||
|
||||
The mount call registers a specific instance of a Transport Adapter to a
|
||||
prefix. Once mounted, any HTTP request made using that session whose URL starts
|
||||
@@ -992,9 +908,9 @@ passed-through to `urllib3`. We'll make a Transport Adapter that instructs the
|
||||
library to use SSLv3::
|
||||
|
||||
import ssl
|
||||
from urllib3.poolmanager import PoolManager
|
||||
|
||||
from requests.adapters import HTTPAdapter
|
||||
from requests.packages.urllib3.poolmanager import PoolManager
|
||||
|
||||
|
||||
class Ssl3HttpAdapter(HTTPAdapter):
|
||||
@@ -1005,7 +921,7 @@ library to use SSLv3::
|
||||
num_pools=connections, maxsize=maxsize,
|
||||
block=block, ssl_version=ssl.PROTOCOL_SSLv3)
|
||||
|
||||
.. _`described here`: https://www.kennethreitz.org/essays/the-future-of-python-http
|
||||
.. _`described here`: http://www.kennethreitz.org/essays/the-future-of-python-http
|
||||
.. _`urllib3`: https://github.com/shazow/urllib3
|
||||
|
||||
.. _blocking-or-nonblocking:
|
||||
@@ -1022,12 +938,10 @@ response at a time. However, these calls will still block.
|
||||
|
||||
If you are concerned about the use of blocking IO, there are lots of projects
|
||||
out there that combine Requests with one of Python's asynchronicity frameworks.
|
||||
Some excellent examples are `requests-threads`_, `grequests`_, `requests-futures`_, and `httpx`_.
|
||||
Two excellent examples are `grequests`_ and `requests-futures`_.
|
||||
|
||||
.. _`requests-threads`: https://github.com/requests/requests-threads
|
||||
.. _`grequests`: https://github.com/kennethreitz/grequests
|
||||
.. _`requests-futures`: https://github.com/ross/requests-futures
|
||||
.. _`httpx`: https://github.com/encode/httpx
|
||||
|
||||
Header Ordering
|
||||
---------------
|
||||
@@ -1050,7 +964,7 @@ The **connect** timeout is the number of seconds Requests will wait for your
|
||||
client to establish a connection to a remote machine (corresponding to the
|
||||
`connect()`_) call on the socket. It's a good practice to set connect timeouts
|
||||
to slightly larger than a multiple of 3, which is the default `TCP packet
|
||||
retransmission window <https://www.hjp.at/doc/rfc/rfc2988.txt>`_.
|
||||
retransmission window <http://www.hjp.at/doc/rfc/rfc2988.txt>`_.
|
||||
|
||||
Once your client has connected to the server and sent the HTTP request, the
|
||||
**read** timeout is the number of seconds the client will wait for the server
|
||||
@@ -1075,4 +989,4 @@ coffee.
|
||||
|
||||
r = requests.get('https://github.com', timeout=None)
|
||||
|
||||
.. _`connect()`: https://linux.die.net/man/2/connect
|
||||
.. _`connect()`: http://linux.die.net/man/2/connect
|
||||
|
||||
@@ -51,7 +51,7 @@ Another very popular form of HTTP Authentication is Digest Authentication,
|
||||
and Requests supports this out of the box as well::
|
||||
|
||||
>>> from requests.auth import HTTPDigestAuth
|
||||
>>> url = 'https://httpbin.org/digest-auth/auth/user/pass'
|
||||
>>> url = 'http://httpbin.org/digest-auth/auth/user/pass'
|
||||
>>> requests.get(url, auth=HTTPDigestAuth('user', 'pass'))
|
||||
<Response [200]>
|
||||
|
||||
@@ -120,7 +120,7 @@ To do so, subclass :class:`AuthBase <requests.auth.AuthBase>` and implement the
|
||||
... # Implement my authentication
|
||||
... return r
|
||||
...
|
||||
>>> url = 'https://httpbin.org/get'
|
||||
>>> url = 'http://httpbin.org/get'
|
||||
>>> requests.get(url, auth=MyAuth())
|
||||
<Response [200]>
|
||||
|
||||
@@ -132,13 +132,13 @@ authentication will additionally add hooks to provide further functionality.
|
||||
Further examples can be found under the `Requests organization`_ and in the
|
||||
``auth.py`` file.
|
||||
|
||||
.. _OAuth: https://oauth.net/
|
||||
.. _OAuth: http://oauth.net/
|
||||
.. _requests_oauthlib: https://github.com/requests/requests-oauthlib
|
||||
.. _requests-oauthlib OAuth2 documentation: https://requests-oauthlib.readthedocs.io/en/latest/oauth2_workflow.html
|
||||
.. _Web Application Flow: https://requests-oauthlib.readthedocs.io/en/latest/oauth2_workflow.html#web-application-flow
|
||||
.. _Mobile Application Flow: https://requests-oauthlib.readthedocs.io/en/latest/oauth2_workflow.html#mobile-application-flow
|
||||
.. _Legacy Application Flow: https://requests-oauthlib.readthedocs.io/en/latest/oauth2_workflow.html#legacy-application-flow
|
||||
.. _Backend Application Flow: https://requests-oauthlib.readthedocs.io/en/latest/oauth2_workflow.html#backend-application-flow
|
||||
.. _requests-oauthlib OAuth2 documentation: http://requests-oauthlib.readthedocs.io/en/latest/oauth2_workflow.html
|
||||
.. _Web Application Flow: http://requests-oauthlib.readthedocs.io/en/latest/oauth2_workflow.html#web-application-flow
|
||||
.. _Mobile Application Flow: http://requests-oauthlib.readthedocs.io/en/latest/oauth2_workflow.html#mobile-application-flow
|
||||
.. _Legacy Application Flow: http://requests-oauthlib.readthedocs.io/en/latest/oauth2_workflow.html#legacy-application-flow
|
||||
.. _Backend Application Flow: http://requests-oauthlib.readthedocs.io/en/latest/oauth2_workflow.html#backend-application-flow
|
||||
.. _Kerberos: https://github.com/requests/requests-kerberos
|
||||
.. _NTLM: https://github.com/requests/requests-ntlm
|
||||
.. _Requests organization: https://github.com/requests
|
||||
|
||||
@@ -7,30 +7,34 @@ This part of the documentation covers the installation of Requests.
|
||||
The first step to using any software package is getting it properly installed.
|
||||
|
||||
|
||||
$ python -m pip install requests
|
||||
--------------------------------
|
||||
$ pip install requests
|
||||
----------------------
|
||||
|
||||
To install Requests, simply run this simple command in your terminal of choice::
|
||||
|
||||
$ python -m pip install requests
|
||||
$ pip install requests
|
||||
|
||||
If you don't have `pip <https://pip.pypa.io>`_ installed (tisk tisk!),
|
||||
`this Python installation guide <http://docs.python-guide.org/en/latest/starting/installation/>`_
|
||||
can guide you through the process.
|
||||
|
||||
Get the Source Code
|
||||
-------------------
|
||||
|
||||
Requests is actively developed on GitHub, where the code is
|
||||
`always available <https://github.com/psf/requests>`_.
|
||||
`always available <https://github.com/requests/requests>`_.
|
||||
|
||||
You can either clone the public repository::
|
||||
|
||||
$ git clone git://github.com/psf/requests.git
|
||||
$ git clone git://github.com/requests/requests.git
|
||||
|
||||
Or, download the `tarball <https://github.com/psf/requests/tarball/master>`_::
|
||||
Or, download the `tarball <https://github.com/requests/requests/tarball/master>`_::
|
||||
|
||||
$ curl -OL https://github.com/psf/requests/tarball/master
|
||||
$ curl -OL https://github.com/requests/requests/tarball/master
|
||||
# optionally, zipball is also available (for Windows users).
|
||||
|
||||
Once you have a copy of the source, you can embed it in your own Python
|
||||
package, or install it into your site-packages easily::
|
||||
|
||||
$ cd requests
|
||||
$ python -m pip install .
|
||||
$ pip install .
|
||||
|
||||
45
docs/user/intro.rst
Normal file
@@ -0,0 +1,45 @@
|
||||
.. _introduction:
|
||||
|
||||
Introduction
|
||||
============
|
||||
|
||||
Philosophy
|
||||
----------
|
||||
|
||||
Requests was developed with a few :pep:`20` idioms in mind.
|
||||
|
||||
|
||||
#. Beautiful is better than ugly.
|
||||
#. Explicit is better than implicit.
|
||||
#. Simple is better than complex.
|
||||
#. Complex is better than complicated.
|
||||
#. Readability counts.
|
||||
|
||||
All contributions to Requests should keep these important rules in mind.
|
||||
|
||||
.. _`apache2`:
|
||||
|
||||
Apache2 License
|
||||
---------------
|
||||
|
||||
A large number of open source projects you find today are `GPL Licensed`_.
|
||||
While the GPL has its time and place, it should most certainly not be your
|
||||
go-to license for your next open source project.
|
||||
|
||||
A project that is released as GPL cannot be used in any commercial product
|
||||
without the product itself also being offered as open source.
|
||||
|
||||
The MIT, BSD, ISC, and Apache2 licenses are great alternatives to the GPL
|
||||
that allow your open-source software to be used freely in proprietary,
|
||||
closed-source software.
|
||||
|
||||
Requests is released under terms of `Apache2 License`_.
|
||||
|
||||
.. _`GPL Licensed`: http://www.opensource.org/licenses/gpl-license.php
|
||||
.. _`Apache2 License`: http://opensource.org/licenses/Apache-2.0
|
||||
|
||||
|
||||
Requests License
|
||||
----------------
|
||||
|
||||
.. include:: ../../LICENSE
|
||||
@@ -37,15 +37,15 @@ get all the information we need from this object.
|
||||
Requests' simple API means that all forms of HTTP request are as obvious. For
|
||||
example, this is how you make an HTTP POST request::
|
||||
|
||||
>>> r = requests.post('https://httpbin.org/post', data = {'key':'value'})
|
||||
>>> r = requests.post('http://httpbin.org/post', data = {'key':'value'})
|
||||
|
||||
Nice, right? What about the other HTTP request types: PUT, DELETE, HEAD and
|
||||
OPTIONS? These are all just as simple::
|
||||
|
||||
>>> r = requests.put('https://httpbin.org/put', data = {'key':'value'})
|
||||
>>> r = requests.delete('https://httpbin.org/delete')
|
||||
>>> r = requests.head('https://httpbin.org/get')
|
||||
>>> r = requests.options('https://httpbin.org/get')
|
||||
>>> r = requests.put('http://httpbin.org/put', data = {'key':'value'})
|
||||
>>> r = requests.delete('http://httpbin.org/delete')
|
||||
>>> r = requests.head('http://httpbin.org/get')
|
||||
>>> r = requests.options('http://httpbin.org/get')
|
||||
|
||||
That's all well and good, but it's also only the start of what Requests can
|
||||
do.
|
||||
@@ -63,12 +63,12 @@ using the ``params`` keyword argument. As an example, if you wanted to pass
|
||||
following code::
|
||||
|
||||
>>> payload = {'key1': 'value1', 'key2': 'value2'}
|
||||
>>> r = requests.get('https://httpbin.org/get', params=payload)
|
||||
>>> r = requests.get('http://httpbin.org/get', params=payload)
|
||||
|
||||
You can see that the URL has been correctly encoded by printing the URL::
|
||||
|
||||
>>> print(r.url)
|
||||
https://httpbin.org/get?key2=value2&key1=value1
|
||||
http://httpbin.org/get?key2=value2&key1=value1
|
||||
|
||||
Note that any dictionary key whose value is ``None`` will not be added to the
|
||||
URL's query string.
|
||||
@@ -77,9 +77,9 @@ You can also pass a list of items as a value::
|
||||
|
||||
>>> payload = {'key1': 'value1', 'key2': ['value2', 'value3']}
|
||||
|
||||
>>> r = requests.get('https://httpbin.org/get', params=payload)
|
||||
>>> r = requests.get('http://httpbin.org/get', params=payload)
|
||||
>>> print(r.url)
|
||||
https://httpbin.org/get?key1=value1&key2=value2&key2=value3
|
||||
http://httpbin.org/get?key1=value1&key2=value2&key2=value3
|
||||
|
||||
Response Content
|
||||
----------------
|
||||
@@ -91,7 +91,7 @@ again::
|
||||
|
||||
>>> r = requests.get('https://api.github.com/events')
|
||||
>>> r.text
|
||||
'[{"repository":{"open_issues":0,"url":"https://github.com/...
|
||||
u'[{"repository":{"open_issues":0,"url":"https://github.com/...
|
||||
|
||||
Requests will automatically decode content from the server. Most unicode
|
||||
charsets are seamlessly decoded.
|
||||
@@ -108,7 +108,7 @@ using, and change it, using the ``r.encoding`` property::
|
||||
If you change the encoding, Requests will use the new value of ``r.encoding``
|
||||
whenever you call ``r.text``. You might want to do this in any situation where
|
||||
you can apply special logic to work out what the encoding of the content will
|
||||
be. For example, HTML and XML have the ability to specify their encoding in
|
||||
be. For example, HTTP and XML have the ability to specify their encoding in
|
||||
their body. In situations like this, you should use ``r.content`` to find the
|
||||
encoding, and then set ``r.encoding``. This will let you use ``r.text`` with
|
||||
the correct encoding.
|
||||
@@ -146,7 +146,7 @@ There's also a builtin JSON decoder, in case you're dealing with JSON data::
|
||||
|
||||
>>> r = requests.get('https://api.github.com/events')
|
||||
>>> r.json()
|
||||
[{'repository': {'open_issues': 0, 'url': 'https://github.com/...
|
||||
[{u'repository': {u'open_issues': 0, u'url': 'https://github.com/...
|
||||
|
||||
In case the JSON decoding fails, ``r.json()`` raises an exception. For example, if
|
||||
the response gets a 204 (No Content), or if the response contains invalid JSON,
|
||||
@@ -169,7 +169,7 @@ server, you can access ``r.raw``. If you want to do this, make sure you set
|
||||
>>> r = requests.get('https://api.github.com/events', stream=True)
|
||||
|
||||
>>> r.raw
|
||||
<urllib3.response.HTTPResponse object at 0x101194810>
|
||||
<requests.packages.urllib3.response.HTTPResponse object at 0x101194810>
|
||||
|
||||
>>> r.raw.read(10)
|
||||
'\x1f\x8b\x08\x00\x00\x00\x00\x00\x00\x03'
|
||||
@@ -187,14 +187,6 @@ download, the above is the preferred and recommended way to retrieve the
|
||||
content. Note that ``chunk_size`` can be freely adjusted to a number that
|
||||
may better fit your use cases.
|
||||
|
||||
.. note::
|
||||
|
||||
An important note about using ``Response.iter_content`` versus ``Response.raw``.
|
||||
``Response.iter_content`` will automatically decode the ``gzip`` and ``deflate``
|
||||
transfer-encodings. ``Response.raw`` is a raw stream of bytes -- it does not
|
||||
transform the response content. If you really need access to the bytes as they
|
||||
were returned, use ``Response.raw``.
|
||||
|
||||
|
||||
Custom Headers
|
||||
--------------
|
||||
@@ -213,8 +205,7 @@ Note: Custom headers are given less precedence than more specific sources of inf
|
||||
|
||||
* Authorization headers set with `headers=` will be overridden if credentials
|
||||
are specified in ``.netrc``, which in turn will be overridden by the ``auth=``
|
||||
parameter. Requests will search for the netrc file at `~/.netrc`, `~/_netrc`,
|
||||
or at the path specified by the `NETRC` environment variable.
|
||||
parameter.
|
||||
* Authorization headers will be removed if you get redirected off-host.
|
||||
* Proxy-Authorization headers will be overridden by proxy credentials provided in the URL.
|
||||
* Content-Length headers will be overridden when we can determine the length of the content.
|
||||
@@ -232,7 +223,7 @@ dictionary of data will automatically be form-encoded when the request is made::
|
||||
|
||||
>>> payload = {'key1': 'value1', 'key2': 'value2'}
|
||||
|
||||
>>> r = requests.post("https://httpbin.org/post", data=payload)
|
||||
>>> r = requests.post("http://httpbin.org/post", data=payload)
|
||||
>>> print(r.text)
|
||||
{
|
||||
...
|
||||
@@ -243,16 +234,12 @@ dictionary of data will automatically be form-encoded when the request is made::
|
||||
...
|
||||
}
|
||||
|
||||
The ``data`` argument can also have multiple values for each key. This can be
|
||||
done by making ``data`` either a list of tuples or a dictionary with lists
|
||||
as values. This is particularly useful when the form has multiple elements that
|
||||
use the same key::
|
||||
You can also pass a list of tuples to the ``data`` argument. This is particularly
|
||||
useful when the form has multiple elements that use the same key::
|
||||
|
||||
>>> payload_tuples = [('key1', 'value1'), ('key1', 'value2')]
|
||||
>>> r1 = requests.post('https://httpbin.org/post', data=payload_tuples)
|
||||
>>> payload_dict = {'key1': ['value1', 'value2']}
|
||||
>>> r2 = requests.post('https://httpbin.org/post', data=payload_dict)
|
||||
>>> print(r1.text)
|
||||
>>> payload = (('key1', 'value1'), ('key1', 'value2'))
|
||||
>>> r = requests.post('http://httpbin.org/post', data=payload)
|
||||
>>> print(r.text)
|
||||
{
|
||||
...
|
||||
"form": {
|
||||
@@ -263,8 +250,6 @@ use the same key::
|
||||
},
|
||||
...
|
||||
}
|
||||
>>> r1.text == r2.text
|
||||
True
|
||||
|
||||
There are times that you may want to send data that is not form-encoded. If
|
||||
you pass in a ``string`` instead of a ``dict``, that data will be posted directly.
|
||||
@@ -286,16 +271,13 @@ the ``json`` parameter (added in version 2.4.2) and it will be encoded automatic
|
||||
|
||||
>>> r = requests.post(url, json=payload)
|
||||
|
||||
Note, the ``json`` parameter is ignored if either ``data`` or ``files`` is passed.
|
||||
|
||||
Using the ``json`` parameter in the request will change the ``Content-Type`` in the header to ``application/json``.
|
||||
|
||||
POST a Multipart-Encoded File
|
||||
-----------------------------
|
||||
|
||||
Requests makes it simple to upload Multipart-encoded files::
|
||||
|
||||
>>> url = 'https://httpbin.org/post'
|
||||
>>> url = 'http://httpbin.org/post'
|
||||
>>> files = {'file': open('report.xls', 'rb')}
|
||||
|
||||
>>> r = requests.post(url, files=files)
|
||||
@@ -310,7 +292,7 @@ Requests makes it simple to upload Multipart-encoded files::
|
||||
|
||||
You can set the filename, content_type and headers explicitly::
|
||||
|
||||
>>> url = 'https://httpbin.org/post'
|
||||
>>> url = 'http://httpbin.org/post'
|
||||
>>> files = {'file': ('report.xls', open('report.xls', 'rb'), 'application/vnd.ms-excel', {'Expires': '0'})}
|
||||
|
||||
>>> r = requests.post(url, files=files)
|
||||
@@ -325,7 +307,7 @@ You can set the filename, content_type and headers explicitly::
|
||||
|
||||
If you want, you can send strings to be received as files::
|
||||
|
||||
>>> url = 'https://httpbin.org/post'
|
||||
>>> url = 'http://httpbin.org/post'
|
||||
>>> files = {'file': ('report.csv', 'some,data,to,send\nanother,row,to,send\n')}
|
||||
|
||||
>>> r = requests.post(url, files=files)
|
||||
@@ -347,11 +329,13 @@ support this, but there is a separate package which does -
|
||||
For sending multiple files in one request refer to the :ref:`advanced <advanced>`
|
||||
section.
|
||||
|
||||
.. warning:: It is strongly recommended that you open files in :ref:`binary
|
||||
mode <tut-files>`. This is because Requests may attempt to provide
|
||||
the ``Content-Length`` header for you, and if it does this value
|
||||
will be set to the number of *bytes* in the file. Errors may occur
|
||||
if you open the file in *text mode*.
|
||||
.. warning:: It is strongly recommended that you open files in `binary mode`_.
|
||||
This is because Requests may attempt to provide the
|
||||
``Content-Length`` header for you, and if it does this value will
|
||||
be set to the number of *bytes* in the file. Errors may occur if
|
||||
you open the file in *text mode*.
|
||||
|
||||
.. _binary mode: https://docs.python.org/2/tutorial/inputoutput.html#reading-and-writing-files
|
||||
|
||||
|
||||
Response Status Codes
|
||||
@@ -359,7 +343,7 @@ Response Status Codes
|
||||
|
||||
We can check the response status code::
|
||||
|
||||
>>> r = requests.get('https://httpbin.org/get')
|
||||
>>> r = requests.get('http://httpbin.org/get')
|
||||
>>> r.status_code
|
||||
200
|
||||
|
||||
@@ -373,7 +357,7 @@ If we made a bad request (a 4XX client error or 5XX server error response), we
|
||||
can raise it with
|
||||
:meth:`Response.raise_for_status() <requests.Response.raise_for_status>`::
|
||||
|
||||
>>> bad_r = requests.get('https://httpbin.org/status/404')
|
||||
>>> bad_r = requests.get('http://httpbin.org/status/404')
|
||||
>>> bad_r.status_code
|
||||
404
|
||||
|
||||
@@ -387,10 +371,14 @@ But, since our ``status_code`` for ``r`` was ``200``, when we call
|
||||
``raise_for_status()`` we get::
|
||||
|
||||
>>> r.raise_for_status()
|
||||
None
|
||||
<Response [200]>
|
||||
|
||||
All is well.
|
||||
|
||||
.. note:: ``raise_for_status`` returns the response object for a successful response. This eases chaining in trivial cases, where we want bad codes to raise an exception, but use the response otherwise:
|
||||
|
||||
>>> value = requests.get('http://httpbin.org/ip').raise_for_status().json()['origin']
|
||||
|
||||
|
||||
Response Headers
|
||||
----------------
|
||||
@@ -409,7 +397,7 @@ We can view the server's response headers using a Python dictionary::
|
||||
}
|
||||
|
||||
The dictionary is special, though: it's made just for HTTP headers. According to
|
||||
`RFC 7230 <https://tools.ietf.org/html/rfc7230#section-3.2>`_, HTTP Header names
|
||||
`RFC 7230 <http://tools.ietf.org/html/rfc7230#section-3.2>`_, HTTP Header names
|
||||
are case-insensitive.
|
||||
|
||||
So, we can access the headers using any capitalization we want::
|
||||
@@ -423,7 +411,7 @@ So, we can access the headers using any capitalization we want::
|
||||
It is also special in that the server could have sent the same header multiple
|
||||
times with different values, but requests combines them so they can be
|
||||
represented in the dictionary within a single mapping, as per
|
||||
`RFC 7230 <https://tools.ietf.org/html/rfc7230#section-3.2>`_:
|
||||
`RFC 7230 <http://tools.ietf.org/html/rfc7230#section-3.2>`_:
|
||||
|
||||
A recipient MAY combine multiple header fields with the same field name
|
||||
into one "field-name: field-value" pair, without changing the semantics
|
||||
@@ -444,7 +432,7 @@ If a response contains some Cookies, you can quickly access them::
|
||||
To send your own cookies to the server, you can use the ``cookies``
|
||||
parameter::
|
||||
|
||||
>>> url = 'https://httpbin.org/cookies'
|
||||
>>> url = 'http://httpbin.org/cookies'
|
||||
>>> cookies = dict(cookies_are='working')
|
||||
|
||||
>>> r = requests.get(url, cookies=cookies)
|
||||
@@ -459,7 +447,7 @@ also be passed in to requests::
|
||||
>>> jar = requests.cookies.RequestsCookieJar()
|
||||
>>> jar.set('tasty_cookie', 'yum', domain='httpbin.org', path='/cookies')
|
||||
>>> jar.set('gross_cookie', 'blech', domain='httpbin.org', path='/elsewhere')
|
||||
>>> url = 'https://httpbin.org/cookies'
|
||||
>>> url = 'http://httpbin.org/cookies'
|
||||
>>> r = requests.get(url, cookies=jar)
|
||||
>>> r.text
|
||||
'{"cookies": {"tasty_cookie": "yum"}}'
|
||||
@@ -480,7 +468,7 @@ response.
|
||||
|
||||
For example, GitHub redirects all HTTP requests to HTTPS::
|
||||
|
||||
>>> r = requests.get('http://github.com/')
|
||||
>>> r = requests.get('http://github.com')
|
||||
|
||||
>>> r.url
|
||||
'https://github.com/'
|
||||
@@ -495,7 +483,7 @@ For example, GitHub redirects all HTTP requests to HTTPS::
|
||||
If you're using GET, OPTIONS, POST, PUT, PATCH or DELETE, you can disable
|
||||
redirection handling with the ``allow_redirects`` parameter::
|
||||
|
||||
>>> r = requests.get('http://github.com/', allow_redirects=False)
|
||||
>>> r = requests.get('http://github.com', allow_redirects=False)
|
||||
|
||||
>>> r.status_code
|
||||
301
|
||||
@@ -505,7 +493,7 @@ redirection handling with the ``allow_redirects`` parameter::
|
||||
|
||||
If you're using HEAD, you can enable redirection as well::
|
||||
|
||||
>>> r = requests.head('http://github.com/', allow_redirects=True)
|
||||
>>> r = requests.head('http://github.com', allow_redirects=True)
|
||||
|
||||
>>> r.url
|
||||
'https://github.com/'
|
||||
@@ -522,7 +510,7 @@ seconds with the ``timeout`` parameter. Nearly all production code should use
|
||||
this parameter in nearly all requests. Failure to do so can cause your program
|
||||
to hang indefinitely::
|
||||
|
||||
>>> requests.get('https://github.com/', timeout=0.001)
|
||||
>>> requests.get('http://github.com', timeout=0.001)
|
||||
Traceback (most recent call last):
|
||||
File "<stdin>", line 1, in <module>
|
||||
requests.exceptions.Timeout: HTTPConnectionPool(host='github.com', port=80): Request timed out. (timeout=0.001)
|
||||
@@ -559,6 +547,3 @@ All exceptions that Requests explicitly raises inherit from
|
||||
-----------------------
|
||||
|
||||
Ready for more? Check out the :ref:`advanced <advanced>` section.
|
||||
|
||||
|
||||
If you're on the job market, consider taking `this programming quiz <https://triplebyte.com/a/b1i2FB8/requests-docs-1>`_. A substantial donation will be made to this project, if you find a job through this platform.
|
||||
|
||||
@@ -1 +0,0 @@
|
||||
Copyright 2019 Kenneth Reitz. All rights reserved.
|
||||

|
Before Width: | Height: | Size: 14 KiB |

|
Before Width: | Height: | Size: 5.8 KiB |
BIN
ext/kr.png

|
Before Width: | Height: | Size: 9.2 KiB |

|
Before Width: | Height: | Size: 12 KiB |
BIN
ext/psf.png

|
Before Width: | Height: | Size: 14 KiB |

|
Before Width: | Height: | Size: 188 KiB |

|
Before Width: | Height: | Size: 188 KiB |

|
Before Width: | Height: | Size: 363 KiB |
BIN
ext/ss.png

|
Before Width: | Height: | Size: 363 KiB |
@@ -1,3 +1,2 @@
|
||||
[pytest]
|
||||
addopts = -p no:warnings --doctest-modules
|
||||
doctest_optionflags= NORMALIZE_WHITESPACE ELLIPSIS
|
||||
addopts = -p no:warnings
|
||||
@@ -9,106 +9,75 @@
|
||||
Requests HTTP Library
|
||||
~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
Requests is an HTTP library, written in Python, for human beings.
|
||||
Basic GET usage:
|
||||
Requests is an HTTP library, written in Python, for human beings. Basic GET
|
||||
usage:
|
||||
|
||||
>>> import requests
|
||||
>>> r = requests.get('https://www.python.org')
|
||||
>>> r.status_code
|
||||
200
|
||||
>>> b'Python is a programming language' in r.content
|
||||
>>> 'Python is a programming language' in r.content
|
||||
True
|
||||
|
||||
... or POST:
|
||||
|
||||
>>> payload = dict(key1='value1', key2='value2')
|
||||
>>> r = requests.post('https://httpbin.org/post', data=payload)
|
||||
>>> r = requests.post('http://httpbin.org/post', data=payload)
|
||||
>>> print(r.text)
|
||||
{
|
||||
...
|
||||
"form": {
|
||||
"key1": "value1",
|
||||
"key2": "value2"
|
||||
"key2": "value2",
|
||||
"key1": "value1"
|
||||
},
|
||||
...
|
||||
}
|
||||
|
||||
The other HTTP methods are supported - see `requests.api`. Full documentation
|
||||
is at <https://requests.readthedocs.io>.
|
||||
is at <http://python-requests.org>.
|
||||
|
||||
:copyright: (c) 2017 by Kenneth Reitz.
|
||||
:license: Apache 2.0, see LICENSE for more details.
|
||||
"""
|
||||
|
||||
# Check urllib3 for compatibility.
|
||||
import urllib3
|
||||
import chardet
|
||||
import warnings
|
||||
from .exceptions import RequestsDependencyWarning
|
||||
|
||||
|
||||
def check_compatibility(urllib3_version, chardet_version):
|
||||
urllib3_version = urllib3_version.split('.')
|
||||
assert urllib3_version != ['dev'] # Verify urllib3 isn't installed from git.
|
||||
|
||||
# Sometimes, urllib3 only reports its version as 16.1.
|
||||
if len(urllib3_version) == 2:
|
||||
urllib3_version.append('0')
|
||||
|
||||
# Check urllib3 for compatibility.
|
||||
major, minor, patch = urllib3_version # noqa: F811
|
||||
major, minor, patch = int(major), int(minor), int(patch)
|
||||
# urllib3 >= 1.21.1, <= 1.26
|
||||
urllib3_version = urllib3.__version__.split('.')
|
||||
# Sometimes, urllib3 only reports its version as 16.1.
|
||||
if len(urllib3_version) == 2:
|
||||
urllib3_version.append('0')
|
||||
major, minor, patch = urllib3_version
|
||||
major, minor, patch = int(major), int(minor), int(patch)
|
||||
# urllib3 >= 1.21.1, < 1.22
|
||||
try:
|
||||
assert major == 1
|
||||
assert minor >= 21
|
||||
assert minor <= 26
|
||||
assert minor <= 22
|
||||
except AssertionError:
|
||||
raise RuntimeError('Requests dependency \'urllib3\' must be version >= 1.21.1, < 1.22!')
|
||||
|
||||
# Check chardet for compatibility.
|
||||
major, minor, patch = chardet_version.split('.')[:3]
|
||||
major, minor, patch = int(major), int(minor), int(patch)
|
||||
# chardet >= 3.0.2, < 3.1.0
|
||||
|
||||
# Check chardet for compatibility.
|
||||
import chardet
|
||||
major, minor, patch = chardet.__version__.split('.')[:3]
|
||||
major, minor, patch = int(major), int(minor), int(patch)
|
||||
# chardet >= 3.0.2, < 3.1.0
|
||||
try:
|
||||
assert major == 3
|
||||
assert minor < 1
|
||||
assert patch >= 2
|
||||
except AssertionError:
|
||||
raise RuntimeError('Requests dependency \'chardet\' must be version >= 3.0.2, < 3.1.0!')
|
||||
|
||||
|
||||
def _check_cryptography(cryptography_version):
|
||||
# cryptography < 1.3.4
|
||||
try:
|
||||
cryptography_version = list(map(int, cryptography_version.split('.')))
|
||||
except ValueError:
|
||||
return
|
||||
|
||||
if cryptography_version < [1, 3, 4]:
|
||||
warning = 'Old version of cryptography ({}) may cause slowdown.'.format(cryptography_version)
|
||||
warnings.warn(warning, RequestsDependencyWarning)
|
||||
|
||||
# Check imported dependencies for compatibility.
|
||||
# Attempt to enable urllib3's SNI support, if possible
|
||||
try:
|
||||
check_compatibility(urllib3.__version__, chardet.__version__)
|
||||
except (AssertionError, ValueError):
|
||||
warnings.warn("urllib3 ({}) or chardet ({}) doesn't match a supported "
|
||||
"version!".format(urllib3.__version__, chardet.__version__),
|
||||
RequestsDependencyWarning)
|
||||
|
||||
# Attempt to enable urllib3's fallback for SNI support
|
||||
# if the standard library doesn't support SNI or the
|
||||
# 'ssl' library isn't available.
|
||||
try:
|
||||
try:
|
||||
import ssl
|
||||
except ImportError:
|
||||
ssl = None
|
||||
|
||||
if not getattr(ssl, "HAS_SNI", False):
|
||||
from urllib3.contrib import pyopenssl
|
||||
pyopenssl.inject_into_urllib3()
|
||||
|
||||
# Check cryptography version
|
||||
from cryptography import __version__ as cryptography_version
|
||||
_check_cryptography(cryptography_version)
|
||||
from urllib3.contrib import pyopenssl
|
||||
pyopenssl.inject_into_urllib3()
|
||||
except ImportError:
|
||||
pass
|
||||
|
||||
import warnings
|
||||
|
||||
# urllib3's DependencyWarnings should be silenced.
|
||||
from urllib3.exceptions import DependencyWarning
|
||||
warnings.simplefilter('ignore', DependencyWarning)
|
||||
@@ -131,7 +100,12 @@ from .exceptions import (
|
||||
|
||||
# Set default logging handler to avoid "No handler found" warnings.
|
||||
import logging
|
||||
from logging import NullHandler
|
||||
try: # Python 2.7+
|
||||
from logging import NullHandler
|
||||
except ImportError:
|
||||
class NullHandler(logging.Handler):
|
||||
def emit(self, record):
|
||||
pass
|
||||
|
||||
logging.getLogger(__name__).addHandler(NullHandler())
|
||||
|
||||
|
||||
@@ -4,11 +4,11 @@
|
||||
|
||||
__title__ = 'requests'
|
||||
__description__ = 'Python HTTP for Humans.'
|
||||
__url__ = 'https://requests.readthedocs.io'
|
||||
__version__ = '2.25.0'
|
||||
__build__ = 0x022500
|
||||
__url__ = 'http://python-requests.org'
|
||||
__version__ = '3.0.0'
|
||||
__build__ = 0x030000
|
||||
__author__ = 'Kenneth Reitz'
|
||||
__author_email__ = 'me@kennethreitz.org'
|
||||
__license__ = 'Apache 2.0'
|
||||
__copyright__ = 'Copyright 2020 Kenneth Reitz'
|
||||
__copyright__ = 'Copyright 2017 Kenneth Reitz'
|
||||
__cake__ = u'\u2728 \U0001f370 \u2728'
|
||||
|
||||
@@ -10,10 +10,13 @@ and maintain connections.
|
||||
|
||||
import os.path
|
||||
import socket
|
||||
try:
|
||||
from threading import RLock
|
||||
except ImportError: # threading is an optional module and may not be present.
|
||||
from dummy_threading import RLock
|
||||
|
||||
from urllib3.poolmanager import PoolManager, proxy_from_url
|
||||
from urllib3.response import HTTPResponse
|
||||
from urllib3.util import parse_url
|
||||
from urllib3.util import Timeout as TimeoutSauce
|
||||
from urllib3.util.retry import Retry
|
||||
from urllib3.exceptions import ClosedPoolError
|
||||
@@ -26,25 +29,23 @@ from urllib3.exceptions import ProtocolError
|
||||
from urllib3.exceptions import ReadTimeoutError
|
||||
from urllib3.exceptions import SSLError as _SSLError
|
||||
from urllib3.exceptions import ResponseError
|
||||
from urllib3.exceptions import LocationValueError
|
||||
|
||||
from .models import Response
|
||||
from .compat import urlparse, basestring
|
||||
from .utils import (DEFAULT_CA_BUNDLE_PATH, extract_zipped_paths,
|
||||
get_encoding_from_headers, prepend_scheme_if_needed,
|
||||
get_auth_from_url, urldefragauth, select_proxy)
|
||||
from .utils import (DEFAULT_CA_BUNDLE_PATH, get_encoding_from_headers,
|
||||
prepend_scheme_if_needed, get_auth_from_url, urldefragauth,
|
||||
select_proxy)
|
||||
from .structures import CaseInsensitiveDict
|
||||
from .cookies import extract_cookies_to_jar
|
||||
from .exceptions import (ConnectionError, ConnectTimeout, ReadTimeout, SSLError,
|
||||
ProxyError, RetryError, InvalidSchema, InvalidProxyURL,
|
||||
InvalidURL)
|
||||
ProxyError, RetryError, InvalidScheme)
|
||||
from .auth import _basic_auth_str
|
||||
|
||||
try:
|
||||
from urllib3.contrib.socks import SOCKSProxyManager
|
||||
except ImportError:
|
||||
def SOCKSProxyManager(*args, **kwargs):
|
||||
raise InvalidSchema("Missing dependencies for SOCKS support.")
|
||||
raise InvalidScheme("Missing dependencies for SOCKS support.")
|
||||
|
||||
DEFAULT_POOLBLOCK = False
|
||||
DEFAULT_POOLSIZE = 10
|
||||
@@ -125,17 +126,20 @@ class HTTPAdapter(BaseAdapter):
|
||||
self._pool_connections = pool_connections
|
||||
self._pool_maxsize = pool_maxsize
|
||||
self._pool_block = pool_block
|
||||
self._pool_kw_lock = RLock()
|
||||
|
||||
self.init_poolmanager(pool_connections, pool_maxsize, block=pool_block)
|
||||
|
||||
def __getstate__(self):
|
||||
return {attr: getattr(self, attr, None) for attr in self.__attrs__}
|
||||
return dict((attr, getattr(self, attr, None)) for attr in
|
||||
self.__attrs__)
|
||||
|
||||
def __setstate__(self, state):
|
||||
# Can't handle by adding 'proxy_manager' to self.__attrs__ because
|
||||
# self.poolmanager uses a lambda function, which isn't pickleable.
|
||||
self.proxy_manager = {}
|
||||
self.config = {}
|
||||
self._pool_kw_lock = RLock()
|
||||
|
||||
for attr, value in state.items():
|
||||
setattr(self, attr, value)
|
||||
@@ -200,19 +204,21 @@ class HTTPAdapter(BaseAdapter):
|
||||
|
||||
return manager
|
||||
|
||||
def cert_verify(self, conn, url, verify, cert):
|
||||
"""Verify a SSL certificate. This method should not be called from user
|
||||
code, and is only exposed for use when subclassing the
|
||||
:class:`HTTPAdapter <requests.adapters.HTTPAdapter>`.
|
||||
def _update_poolmanager_ssl_kw(self, verify, cert):
|
||||
"""Update the :class:`PoolManager <urllib3.poolmanager.PoolManager>`
|
||||
connection_pool_kw with the necessary SSL configuration. This method
|
||||
should not be called from user code, and is only exposed for use when
|
||||
subclassing the :class:`HTTPAdapter <requests.adapters.HTTPAdapter>`.
|
||||
|
||||
:param conn: The urllib3 connection object associated with the cert.
|
||||
:param url: The requested URL.
|
||||
:param verify: Either a boolean, in which case it controls whether we verify
|
||||
the server's TLS certificate, or a string, in which case it must be a path
|
||||
to a CA bundle to use
|
||||
:param cert: The SSL certificate to verify.
|
||||
:param verify: Whether we should actually verify the certificate;
|
||||
optionally a path to a CA certificate bundle or
|
||||
directory of CA certificates.
|
||||
:param cert: The path to the client certificate and key, if any.
|
||||
This can either be the path to the certificate and
|
||||
key concatenated in a single file, or as a tuple of
|
||||
(cert_file, key_file).
|
||||
"""
|
||||
if url.lower().startswith('https') and verify:
|
||||
if verify:
|
||||
|
||||
cert_loc = None
|
||||
|
||||
@@ -221,36 +227,41 @@ class HTTPAdapter(BaseAdapter):
|
||||
cert_loc = verify
|
||||
|
||||
if not cert_loc:
|
||||
cert_loc = extract_zipped_paths(DEFAULT_CA_BUNDLE_PATH)
|
||||
cert_loc = DEFAULT_CA_BUNDLE_PATH
|
||||
|
||||
if not cert_loc or not os.path.exists(cert_loc):
|
||||
raise IOError("Could not find a suitable TLS CA certificate bundle, "
|
||||
"invalid path: {}".format(cert_loc))
|
||||
"invalid path: {0}".format(cert_loc))
|
||||
|
||||
conn.cert_reqs = 'CERT_REQUIRED'
|
||||
self.poolmanager.connection_pool_kw['cert_reqs'] = 'CERT_REQUIRED'
|
||||
|
||||
if not os.path.isdir(cert_loc):
|
||||
conn.ca_certs = cert_loc
|
||||
self.poolmanager.connection_pool_kw['ca_certs'] = cert_loc
|
||||
self.poolmanager.connection_pool_kw['ca_cert_dir'] = None
|
||||
else:
|
||||
conn.ca_cert_dir = cert_loc
|
||||
self.poolmanager.connection_pool_kw['ca_cert_dir'] = cert_loc
|
||||
self.poolmanager.connection_pool_kw['ca_certs'] = None
|
||||
else:
|
||||
conn.cert_reqs = 'CERT_NONE'
|
||||
conn.ca_certs = None
|
||||
conn.ca_cert_dir = None
|
||||
self.poolmanager.connection_pool_kw['cert_reqs'] = 'CERT_NONE'
|
||||
self.poolmanager.connection_pool_kw['ca_certs'] = None
|
||||
self.poolmanager.connection_pool_kw['ca_cert_dir'] = None
|
||||
|
||||
if cert:
|
||||
if not isinstance(cert, basestring):
|
||||
conn.cert_file = cert[0]
|
||||
conn.key_file = cert[1]
|
||||
self.poolmanager.connection_pool_kw['cert_file'] = cert[0]
|
||||
self.poolmanager.connection_pool_kw['key_file'] = cert[1]
|
||||
else:
|
||||
conn.cert_file = cert
|
||||
conn.key_file = None
|
||||
if conn.cert_file and not os.path.exists(conn.cert_file):
|
||||
self.poolmanager.connection_pool_kw['cert_file'] = cert
|
||||
self.poolmanager.connection_pool_kw['key_file'] = None
|
||||
|
||||
cert_file = self.poolmanager.connection_pool_kw['cert_file']
|
||||
key_file = self.poolmanager.connection_pool_kw['key_file']
|
||||
if cert_file and not os.path.exists(cert_file):
|
||||
raise IOError("Could not find the TLS certificate file, "
|
||||
"invalid path: {}".format(conn.cert_file))
|
||||
if conn.key_file and not os.path.exists(conn.key_file):
|
||||
"invalid path: {0}".format(cert_file))
|
||||
if key_file and not os.path.exists(key_file):
|
||||
raise IOError("Could not find the TLS key file, "
|
||||
"invalid path: {}".format(conn.key_file))
|
||||
"invalid path: {0}".format(key_file))
|
||||
|
||||
def build_response(self, req, resp):
|
||||
"""Builds a :class:`Response <requests.Response>` object from a urllib3
|
||||
@@ -289,7 +300,7 @@ class HTTPAdapter(BaseAdapter):
|
||||
|
||||
return response
|
||||
|
||||
def get_connection(self, url, proxies=None):
|
||||
def get_connection(self, url, proxies=None, verify=None, cert=None):
|
||||
"""Returns a urllib3 connection for the given URL. This should not be
|
||||
called from user code, and is only exposed for use when subclassing the
|
||||
:class:`HTTPAdapter <requests.adapters.HTTPAdapter>`.
|
||||
@@ -298,21 +309,21 @@ class HTTPAdapter(BaseAdapter):
|
||||
:param proxies: (optional) A Requests-style dictionary of proxies used on this request.
|
||||
:rtype: urllib3.ConnectionPool
|
||||
"""
|
||||
proxy = select_proxy(url, proxies)
|
||||
with self._pool_kw_lock:
|
||||
if url.lower().startswith('https'):
|
||||
self._update_poolmanager_ssl_kw(verify, cert)
|
||||
|
||||
if proxy:
|
||||
proxy = prepend_scheme_if_needed(proxy, 'http')
|
||||
proxy_url = parse_url(proxy)
|
||||
if not proxy_url.host:
|
||||
raise InvalidProxyURL("Please check proxy URL. It is malformed"
|
||||
" and could be missing the host.")
|
||||
proxy_manager = self.proxy_manager_for(proxy)
|
||||
conn = proxy_manager.connection_from_url(url)
|
||||
else:
|
||||
# Only scheme should be lower case
|
||||
parsed = urlparse(url)
|
||||
url = parsed.geturl()
|
||||
conn = self.poolmanager.connection_from_url(url)
|
||||
proxy = select_proxy(url, proxies)
|
||||
|
||||
if proxy:
|
||||
proxy = prepend_scheme_if_needed(proxy, 'http')
|
||||
proxy_manager = self.proxy_manager_for(proxy)
|
||||
conn = proxy_manager.connection_from_url(url)
|
||||
else:
|
||||
# Only scheme should be lower case
|
||||
parsed = urlparse(url)
|
||||
url = parsed.geturl()
|
||||
conn = self.poolmanager.connection_from_url(url)
|
||||
|
||||
return conn
|
||||
|
||||
@@ -379,7 +390,7 @@ class HTTPAdapter(BaseAdapter):
|
||||
when subclassing the
|
||||
:class:`HTTPAdapter <requests.adapters.HTTPAdapter>`.
|
||||
|
||||
:param proxy: The url of the proxy being used for this request.
|
||||
:param proxies: The url of the proxy being used for this request.
|
||||
:rtype: dict
|
||||
"""
|
||||
headers = {}
|
||||
@@ -407,15 +418,10 @@ class HTTPAdapter(BaseAdapter):
|
||||
:param proxies: (optional) The proxies dictionary to apply to the request.
|
||||
:rtype: requests.Response
|
||||
"""
|
||||
conn = self.get_connection(request.url, proxies, verify, cert)
|
||||
|
||||
try:
|
||||
conn = self.get_connection(request.url, proxies)
|
||||
except LocationValueError as e:
|
||||
raise InvalidURL(e, request=request)
|
||||
|
||||
self.cert_verify(conn, request.url, verify, cert)
|
||||
url = self.request_url(request, proxies)
|
||||
self.add_headers(request, stream=stream, timeout=timeout, verify=verify, cert=cert, proxies=proxies)
|
||||
self.add_headers(request)
|
||||
|
||||
chunked = not (request.body is None or 'Content-Length' in request.headers)
|
||||
|
||||
@@ -425,7 +431,7 @@ class HTTPAdapter(BaseAdapter):
|
||||
timeout = TimeoutSauce(connect=connect, read=read)
|
||||
except ValueError as e:
|
||||
# this may raise a string formatting error.
|
||||
err = ("Invalid timeout {}. Pass a (connect, read) "
|
||||
err = ("Invalid timeout {0}. Pass a (connect, read) "
|
||||
"timeout tuple, or a single float to set "
|
||||
"both timeouts to the same value".format(timeout))
|
||||
raise ValueError(err)
|
||||
@@ -446,7 +452,8 @@ class HTTPAdapter(BaseAdapter):
|
||||
preload_content=False,
|
||||
decode_content=False,
|
||||
retries=self.max_retries,
|
||||
timeout=timeout
|
||||
timeout=timeout,
|
||||
enforce_content_length=True
|
||||
)
|
||||
|
||||
# Send the request.
|
||||
@@ -467,7 +474,10 @@ class HTTPAdapter(BaseAdapter):
|
||||
low_conn.endheaders()
|
||||
|
||||
for i in request.body:
|
||||
low_conn.send(hex(len(i))[2:].encode('utf-8'))
|
||||
chunk_size = len(i)
|
||||
if chunk_size == 0:
|
||||
continue
|
||||
low_conn.send(hex(chunk_size)[2:].encode('utf-8'))
|
||||
low_conn.send(b'\r\n')
|
||||
low_conn.send(i)
|
||||
low_conn.send(b'\r\n')
|
||||
@@ -475,10 +485,11 @@ class HTTPAdapter(BaseAdapter):
|
||||
|
||||
# Receive the response from the server
|
||||
try:
|
||||
# For Python 2.7, use buffering of HTTP responses
|
||||
# For Python 2.7+ versions, use buffering of HTTP
|
||||
# responses
|
||||
r = low_conn.getresponse(buffering=True)
|
||||
except TypeError:
|
||||
# For compatibility with Python 3.3+
|
||||
# For compatibility with Python 2.6 versions and back
|
||||
r = low_conn.getresponse()
|
||||
|
||||
resp = HTTPResponse.from_httplib(
|
||||
@@ -486,7 +497,9 @@ class HTTPAdapter(BaseAdapter):
|
||||
pool=conn,
|
||||
connection=low_conn,
|
||||
preload_content=False,
|
||||
decode_content=False
|
||||
decode_content=False,
|
||||
enforce_content_length=True,
|
||||
request_method=request.method
|
||||
)
|
||||
except:
|
||||
# If we hit any problems here, clean up the connection.
|
||||
@@ -509,10 +522,6 @@ class HTTPAdapter(BaseAdapter):
|
||||
if isinstance(e.reason, _ProxyError):
|
||||
raise ProxyError(e, request=request)
|
||||
|
||||
if isinstance(e.reason, _SSLError):
|
||||
# This branch is for urllib3 v1.22 and later.
|
||||
raise SSLError(e, request=request)
|
||||
|
||||
raise ConnectionError(e, request=request)
|
||||
|
||||
except ClosedPoolError as e:
|
||||
@@ -523,7 +532,6 @@ class HTTPAdapter(BaseAdapter):
|
||||
|
||||
except (_SSLError, _HTTPError) as e:
|
||||
if isinstance(e, _SSLError):
|
||||
# This branch is for urllib3 versions earlier than v1.22
|
||||
raise SSLError(e, request=request)
|
||||
elif isinstance(e, ReadTimeoutError):
|
||||
raise ReadTimeout(e, request=request)
|
||||
|
||||
@@ -13,16 +13,15 @@ This module implements the Requests API.
|
||||
from . import sessions
|
||||
|
||||
|
||||
def request(method, url, **kwargs):
|
||||
def request(method, url, session=None, **kwargs):
|
||||
"""Constructs and sends a :class:`Request <Request>`.
|
||||
|
||||
:param method: method for the new :class:`Request` object: ``GET``, ``OPTIONS``, ``HEAD``, ``POST``, ``PUT``, ``PATCH``, or ``DELETE``.
|
||||
:param method: method for the new :class:`Request` object.
|
||||
:param url: URL for the new :class:`Request` object.
|
||||
:param params: (optional) Dictionary, list of tuples or bytes to send
|
||||
in the query string for the :class:`Request`.
|
||||
:param data: (optional) Dictionary, list of tuples, bytes, or file-like
|
||||
object to send in the body of the :class:`Request`.
|
||||
:param json: (optional) A JSON serializable Python object to send in the body of the :class:`Request`.
|
||||
:param session: :class:`Session` object to use for this request. If none is given, one will be provided.
|
||||
:param params: (optional) Dictionary or bytes to be sent in the query string for the :class:`Request`.
|
||||
:param data: (optional) Dictionary or list of tuples ``[(key, value)]`` (will be form-encoded), bytes, or file-like object to send in the body of the :class:`Request`.
|
||||
:param json: (optional) json data to send in the body of the :class:`Request`.
|
||||
:param headers: (optional) Dictionary of HTTP Headers to send with the :class:`Request`.
|
||||
:param cookies: (optional) Dict or CookieJar object to send with the :class:`Request`.
|
||||
:param files: (optional) Dictionary of ``'name': file-like-objects`` (or ``{'name': file-tuple}``) for multipart encoding upload.
|
||||
@@ -49,15 +48,17 @@ def request(method, url, **kwargs):
|
||||
Usage::
|
||||
|
||||
>>> import requests
|
||||
>>> req = requests.request('GET', 'https://httpbin.org/get')
|
||||
>>> req
|
||||
>>> req = requests.request('GET', 'http://httpbin.org/get')
|
||||
<Response [200]>
|
||||
"""
|
||||
|
||||
# By using the 'with' statement we are sure the session is closed, thus we
|
||||
# avoid leaving sockets open which can trigger a ResourceWarning in some
|
||||
# cases, and look like a memory leak in others.
|
||||
with sessions.Session() as session:
|
||||
|
||||
session = sessions.Session() if session is None else session
|
||||
|
||||
with session:
|
||||
return session.request(method=method, url=url, **kwargs)
|
||||
|
||||
|
||||
@@ -65,8 +66,7 @@ def get(url, params=None, **kwargs):
|
||||
r"""Sends a GET request.
|
||||
|
||||
:param url: URL for the new :class:`Request` object.
|
||||
:param params: (optional) Dictionary, list of tuples or bytes to send
|
||||
in the query string for the :class:`Request`.
|
||||
:param params: (optional) Dictionary or bytes to be sent in the query string for the :class:`Request`.
|
||||
:param \*\*kwargs: Optional arguments that ``request`` takes.
|
||||
:return: :class:`Response <Response>` object
|
||||
:rtype: requests.Response
|
||||
@@ -77,7 +77,7 @@ def get(url, params=None, **kwargs):
|
||||
|
||||
|
||||
def options(url, **kwargs):
|
||||
r"""Sends an OPTIONS request.
|
||||
r"""Sends a OPTIONS request.
|
||||
|
||||
:param url: URL for the new :class:`Request` object.
|
||||
:param \*\*kwargs: Optional arguments that ``request`` takes.
|
||||
@@ -93,9 +93,7 @@ def head(url, **kwargs):
|
||||
r"""Sends a HEAD request.
|
||||
|
||||
:param url: URL for the new :class:`Request` object.
|
||||
:param \*\*kwargs: Optional arguments that ``request`` takes. If
|
||||
`allow_redirects` is not provided, it will be set to `False` (as
|
||||
opposed to the default :meth:`request` behavior).
|
||||
:param \*\*kwargs: Optional arguments that ``request`` takes.
|
||||
:return: :class:`Response <Response>` object
|
||||
:rtype: requests.Response
|
||||
"""
|
||||
@@ -108,8 +106,7 @@ def post(url, data=None, json=None, **kwargs):
|
||||
r"""Sends a POST request.
|
||||
|
||||
:param url: URL for the new :class:`Request` object.
|
||||
:param data: (optional) Dictionary, list of tuples, bytes, or file-like
|
||||
object to send in the body of the :class:`Request`.
|
||||
:param data: (optional) Dictionary (will be form-encoded), bytes, or file-like object to send in the body of the :class:`Request`.
|
||||
:param json: (optional) json data to send in the body of the :class:`Request`.
|
||||
:param \*\*kwargs: Optional arguments that ``request`` takes.
|
||||
:return: :class:`Response <Response>` object
|
||||
@@ -123,8 +120,7 @@ def put(url, data=None, **kwargs):
|
||||
r"""Sends a PUT request.
|
||||
|
||||
:param url: URL for the new :class:`Request` object.
|
||||
:param data: (optional) Dictionary, list of tuples, bytes, or file-like
|
||||
object to send in the body of the :class:`Request`.
|
||||
:param data: (optional) Dictionary (will be form-encoded), bytes, or file-like object to send in the body of the :class:`Request`.
|
||||
:param json: (optional) json data to send in the body of the :class:`Request`.
|
||||
:param \*\*kwargs: Optional arguments that ``request`` takes.
|
||||
:return: :class:`Response <Response>` object
|
||||
@@ -138,8 +134,7 @@ def patch(url, data=None, **kwargs):
|
||||
r"""Sends a PATCH request.
|
||||
|
||||
:param url: URL for the new :class:`Request` object.
|
||||
:param data: (optional) Dictionary, list of tuples, bytes, or file-like
|
||||
object to send in the body of the :class:`Request`.
|
||||
:param data: (optional) Dictionary (will be form-encoded), bytes, or file-like object to send in the body of the :class:`Request`.
|
||||
:param json: (optional) json data to send in the body of the :class:`Request`.
|
||||
:param \*\*kwargs: Optional arguments that ``request`` takes.
|
||||
:return: :class:`Response <Response>` object
|
||||
|
||||
@@ -12,7 +12,6 @@ import re
|
||||
import time
|
||||
import hashlib
|
||||
import threading
|
||||
import warnings
|
||||
|
||||
from base64 import b64encode
|
||||
|
||||
@@ -28,33 +27,13 @@ CONTENT_TYPE_MULTI_PART = 'multipart/form-data'
|
||||
def _basic_auth_str(username, password):
|
||||
"""Returns a Basic Auth string."""
|
||||
|
||||
# "I want us to put a big-ol' comment on top of it that
|
||||
# says that this behaviour is dumb but we need to preserve
|
||||
# it because people are relying on it."
|
||||
# - Lukasa
|
||||
#
|
||||
# These are here solely to maintain backwards compatibility
|
||||
# for things like ints. This will be removed in 3.0.0.
|
||||
if not isinstance(username, basestring):
|
||||
warnings.warn(
|
||||
"Non-string usernames will no longer be supported in Requests "
|
||||
"3.0.0. Please convert the object you've passed in ({!r}) to "
|
||||
"a string or bytes object in the near future to avoid "
|
||||
"problems.".format(username),
|
||||
category=DeprecationWarning,
|
||||
)
|
||||
username = str(username)
|
||||
raise TypeError('username must be of type str or bytes, '
|
||||
'instead it was %s' % type(username))
|
||||
|
||||
if not isinstance(password, basestring):
|
||||
warnings.warn(
|
||||
"Non-string passwords will no longer be supported in Requests "
|
||||
"3.0.0. Please convert the object you've passed in ({!r}) to "
|
||||
"a string or bytes object in the near future to avoid "
|
||||
"problems.".format(type(password)),
|
||||
category=DeprecationWarning,
|
||||
)
|
||||
password = str(password)
|
||||
# -- End Removal --
|
||||
raise TypeError('password must be of type str or bytes, '
|
||||
'instead it was %s' % type(password))
|
||||
|
||||
if isinstance(username, str):
|
||||
username = username.encode('latin1')
|
||||
@@ -97,14 +76,6 @@ class HTTPBasicAuth(AuthBase):
|
||||
return r
|
||||
|
||||
|
||||
class HTTPProxyAuth(HTTPBasicAuth):
|
||||
"""Attaches HTTP Proxy Authentication to a given Request object."""
|
||||
|
||||
def __call__(self, r):
|
||||
r.headers['Proxy-Authorization'] = _basic_auth_str(self.username, self.password)
|
||||
return r
|
||||
|
||||
|
||||
class HTTPDigestAuth(AuthBase):
|
||||
"""Attaches HTTP Digest Authentication to the given Request object."""
|
||||
|
||||
@@ -153,18 +124,6 @@ class HTTPDigestAuth(AuthBase):
|
||||
x = x.encode('utf-8')
|
||||
return hashlib.sha1(x).hexdigest()
|
||||
hash_utf8 = sha_utf8
|
||||
elif _algorithm == 'SHA-256':
|
||||
def sha256_utf8(x):
|
||||
if isinstance(x, str):
|
||||
x = x.encode('utf-8')
|
||||
return hashlib.sha256(x).hexdigest()
|
||||
hash_utf8 = sha256_utf8
|
||||
elif _algorithm == 'SHA-512':
|
||||
def sha512_utf8(x):
|
||||
if isinstance(x, str):
|
||||
x = x.encode('utf-8')
|
||||
return hashlib.sha512(x).hexdigest()
|
||||
hash_utf8 = sha512_utf8
|
||||
|
||||
KD = lambda s, d: hash_utf8("%s:%s" % (s, d))
|
||||
|
||||
@@ -239,7 +198,7 @@ class HTTPDigestAuth(AuthBase):
|
||||
"""
|
||||
|
||||
# If response is not 4xx, do not auth
|
||||
# See https://github.com/psf/requests/issues/3772
|
||||
# See https://github.com/requests/requests/issues/3772
|
||||
if not 400 <= r.status_code < 500:
|
||||
self._thread_local.num_401_calls = 1
|
||||
return r
|
||||
|
||||
@@ -25,20 +25,6 @@ is_py2 = (_ver[0] == 2)
|
||||
#: Python 3.x?
|
||||
is_py3 = (_ver[0] == 3)
|
||||
|
||||
try:
|
||||
import simplejson as json
|
||||
except ImportError:
|
||||
import json
|
||||
|
||||
|
||||
import urllib3
|
||||
|
||||
try:
|
||||
SKIP_HEADER = urllib3.util.SKIP_HEADER
|
||||
SKIPPABLE_HEADERS = urllib3.util.SKIPPABLE_HEADERS
|
||||
except AttributeError:
|
||||
SKIP_HEADER = None
|
||||
SKIPPABLE_HEADERS = frozenset([])
|
||||
|
||||
# ---------
|
||||
# Specifics
|
||||
@@ -53,9 +39,8 @@ if is_py2:
|
||||
import cookielib
|
||||
from Cookie import Morsel
|
||||
from StringIO import StringIO
|
||||
# Keep OrderedDict for backwards compatibility.
|
||||
from collections import Callable, Mapping, MutableMapping, OrderedDict
|
||||
|
||||
from urllib3.packages.ordered_dict import OrderedDict
|
||||
|
||||
builtin_str = str
|
||||
bytes = str
|
||||
@@ -70,9 +55,7 @@ elif is_py3:
|
||||
from http import cookiejar as cookielib
|
||||
from http.cookies import Morsel
|
||||
from io import StringIO
|
||||
# Keep OrderedDict for backwards compatibility.
|
||||
from collections import OrderedDict
|
||||
from collections.abc import Callable, Mapping, MutableMapping
|
||||
|
||||
builtin_str = str
|
||||
str = str
|
||||
|
||||
@@ -12,9 +12,10 @@ requests.utils imports from here, so be careful with imports.
|
||||
import copy
|
||||
import time
|
||||
import calendar
|
||||
import collections
|
||||
|
||||
from ._internal_utils import to_native_string
|
||||
from .compat import cookielib, urlparse, urlunparse, Morsel, MutableMapping
|
||||
from .compat import cookielib, urlparse, urlunparse, Morsel
|
||||
|
||||
try:
|
||||
import threading
|
||||
@@ -168,7 +169,7 @@ class CookieConflictError(RuntimeError):
|
||||
"""
|
||||
|
||||
|
||||
class RequestsCookieJar(cookielib.CookieJar, MutableMapping):
|
||||
class RequestsCookieJar(cookielib.CookieJar, collections.MutableMapping):
|
||||
"""Compatibility class; is a cookielib.CookieJar, but exposes a dict
|
||||
interface.
|
||||
|
||||
@@ -413,15 +414,10 @@ class RequestsCookieJar(cookielib.CookieJar, MutableMapping):
|
||||
|
||||
def copy(self):
|
||||
"""Return a copy of this RequestsCookieJar."""
|
||||
new_cj = RequestsCookieJar()
|
||||
new_cj.set_policy(self.get_policy())
|
||||
new_cj = RequestsCookieJar(self._policy)
|
||||
new_cj.update(self)
|
||||
return new_cj
|
||||
|
||||
def get_policy(self):
|
||||
"""Return the CookiePolicy instance used."""
|
||||
return self._policy
|
||||
|
||||
|
||||
def _copy_cookie_jar(jar):
|
||||
if jar is None:
|
||||
@@ -444,21 +440,20 @@ def create_cookie(name, value, **kwargs):
|
||||
By default, the pair of `name` and `value` will be set for the domain ''
|
||||
and sent on every request (this is sometimes called a "supercookie").
|
||||
"""
|
||||
result = {
|
||||
'version': 0,
|
||||
'name': name,
|
||||
'value': value,
|
||||
'port': None,
|
||||
'domain': '',
|
||||
'path': '/',
|
||||
'secure': False,
|
||||
'expires': None,
|
||||
'discard': True,
|
||||
'comment': None,
|
||||
'comment_url': None,
|
||||
'rest': {'HttpOnly': None},
|
||||
'rfc2109': False,
|
||||
}
|
||||
result = dict(
|
||||
version=0,
|
||||
name=name,
|
||||
value=value,
|
||||
port=None,
|
||||
domain='',
|
||||
path='/',
|
||||
secure=False,
|
||||
expires=None,
|
||||
discard=True,
|
||||
comment=None,
|
||||
comment_url=None,
|
||||
rest={'HttpOnly': None},
|
||||
rfc2109=False,)
|
||||
|
||||
badargs = set(kwargs) - set(result)
|
||||
if badargs:
|
||||
@@ -512,7 +507,6 @@ def cookiejar_from_dict(cookie_dict, cookiejar=None, overwrite=True):
|
||||
:param cookiejar: (optional) A cookiejar to add the cookies to.
|
||||
:param overwrite: (optional) If False, will not replace cookies
|
||||
already in the jar with new ones.
|
||||
:rtype: CookieJar
|
||||
"""
|
||||
if cookiejar is None:
|
||||
cookiejar = RequestsCookieJar()
|
||||
@@ -531,7 +525,6 @@ def merge_cookies(cookiejar, cookies):
|
||||
|
||||
:param cookiejar: CookieJar object to add the cookies to.
|
||||
:param cookies: Dictionary or CookieJar object to be added.
|
||||
:rtype: CookieJar
|
||||
"""
|
||||
if not isinstance(cookiejar, cookielib.CookieJar):
|
||||
raise ValueError('You can only merge into CookieJar')
|
||||
|
||||
@@ -69,12 +69,12 @@ class TooManyRedirects(RequestException):
|
||||
"""Too many redirects."""
|
||||
|
||||
|
||||
class MissingSchema(RequestException, ValueError):
|
||||
"""The URL schema (e.g. http or https) is missing."""
|
||||
class MissingScheme(RequestException, ValueError):
|
||||
"""The URL scheme (e.g. http or https) is missing."""
|
||||
|
||||
|
||||
class InvalidSchema(RequestException, ValueError):
|
||||
"""See defaults.py for valid schemas."""
|
||||
class InvalidScheme(RequestException, ValueError):
|
||||
"""See defaults.py for valid schemes."""
|
||||
|
||||
|
||||
class InvalidURL(RequestException, ValueError):
|
||||
@@ -85,20 +85,16 @@ class InvalidHeader(RequestException, ValueError):
|
||||
"""The header value provided was somehow invalid."""
|
||||
|
||||
|
||||
class InvalidProxyURL(InvalidURL):
|
||||
"""The proxy URL provided is invalid."""
|
||||
|
||||
|
||||
class ChunkedEncodingError(RequestException):
|
||||
"""The server declared chunked encoding but sent an invalid chunk."""
|
||||
|
||||
|
||||
class ContentDecodingError(RequestException, BaseHTTPError):
|
||||
"""Failed to decode response content."""
|
||||
"""Failed to decode response content"""
|
||||
|
||||
|
||||
class StreamConsumedError(RequestException, TypeError):
|
||||
"""The content for this response was already consumed."""
|
||||
"""The content for this response was already consumed"""
|
||||
|
||||
|
||||
class RetryError(RequestException):
|
||||
@@ -106,18 +102,20 @@ class RetryError(RequestException):
|
||||
|
||||
|
||||
class UnrewindableBodyError(RequestException):
|
||||
"""Requests encountered an error when trying to rewind a body."""
|
||||
"""Requests encountered an error when trying to rewind a body"""
|
||||
|
||||
|
||||
class InvalidBodyError(RequestException, ValueError):
|
||||
"""An invalid request body was specified"""
|
||||
|
||||
# Warnings
|
||||
|
||||
|
||||
class RequestsWarning(Warning):
|
||||
"""Base warning for Requests."""
|
||||
pass
|
||||
|
||||
|
||||
class FileModeWarning(RequestsWarning, DeprecationWarning):
|
||||
"""A file was opened in text mode, but Requests determined its binary length."""
|
||||
|
||||
|
||||
class RequestsDependencyWarning(RequestsWarning):
|
||||
"""An imported dependency doesn't match the expected version range."""
|
||||
pass
|
||||
|
||||
@@ -6,14 +6,13 @@ import platform
|
||||
import sys
|
||||
import ssl
|
||||
|
||||
import idna
|
||||
import urllib3
|
||||
import chardet
|
||||
|
||||
from . import __version__ as requests_version
|
||||
|
||||
try:
|
||||
from urllib3.contrib import pyopenssl
|
||||
from .packages.urllib3.contrib import pyopenssl
|
||||
except ImportError:
|
||||
pyopenssl = None
|
||||
OpenSSL = None
|
||||
@@ -24,7 +23,7 @@ else:
|
||||
|
||||
|
||||
def _implementation():
|
||||
"""Return a dict with the Python implementation and version.
|
||||
"""Return a dict with the Python implementation and verison.
|
||||
|
||||
Provide both the name and the version of the Python implementation
|
||||
currently running. For example, on CPython 2.7.5 it will return
|
||||
@@ -85,25 +84,18 @@ def info():
|
||||
cryptography_info = {
|
||||
'version': getattr(cryptography, '__version__', ''),
|
||||
}
|
||||
idna_info = {
|
||||
'version': getattr(idna, '__version__', ''),
|
||||
}
|
||||
|
||||
system_ssl = ssl.OPENSSL_VERSION_NUMBER
|
||||
system_ssl_info = {
|
||||
'version': '%x' % system_ssl if system_ssl is not None else ''
|
||||
}
|
||||
|
||||
return {
|
||||
'platform': platform_info,
|
||||
'implementation': implementation_info,
|
||||
'system_ssl': system_ssl_info,
|
||||
'system_ssl': {
|
||||
'version': '%x' % ssl.OPENSSL_VERSION_NUMBER,
|
||||
},
|
||||
'using_pyopenssl': pyopenssl is not None,
|
||||
'pyOpenSSL': pyopenssl_info,
|
||||
'urllib3': urllib3_info,
|
||||
'chardet': chardet_info,
|
||||
'cryptography': cryptography_info,
|
||||
'idna': idna_info,
|
||||
'requests': {
|
||||
'version': requests_version,
|
||||
},
|
||||
|
||||
@@ -15,14 +15,14 @@ HOOKS = ['response']
|
||||
|
||||
|
||||
def default_hooks():
|
||||
return {event: [] for event in HOOKS}
|
||||
return dict((event, []) for event in HOOKS)
|
||||
|
||||
# TODO: response is the only one
|
||||
|
||||
|
||||
def dispatch_hook(key, hooks, hook_data, **kwargs):
|
||||
"""Dispatches a hook dictionary on a given piece of data."""
|
||||
hooks = hooks or {}
|
||||
hooks = hooks or dict()
|
||||
hooks = hooks.get(key)
|
||||
if hooks:
|
||||
if hasattr(hooks, '__call__'):
|
||||
|
||||
@@ -7,15 +7,16 @@ requests.models
|
||||
This module contains the primary objects that power Requests.
|
||||
"""
|
||||
|
||||
import collections
|
||||
import datetime
|
||||
import codecs
|
||||
import sys
|
||||
|
||||
# Import encoding now, to avoid implicit import later.
|
||||
# Implicit import within threads may cause LookupError when standard library is in a ZIP,
|
||||
# such as in Embedded Python. See https://github.com/psf/requests/issues/3578.
|
||||
# such as in Embedded Python. See https://github.com/requests/requests/issues/3578.
|
||||
import encodings.idna
|
||||
|
||||
import urllib3
|
||||
from urllib3.fields import RequestField
|
||||
from urllib3.filepost import encode_multipart_formdata
|
||||
from urllib3.util import parse_url
|
||||
@@ -26,33 +27,23 @@ from io import UnsupportedOperation
|
||||
from .hooks import default_hooks
|
||||
from .structures import CaseInsensitiveDict
|
||||
|
||||
import requests
|
||||
from .auth import HTTPBasicAuth
|
||||
from .cookies import cookiejar_from_dict, get_cookie_header, _copy_cookie_jar
|
||||
from .exceptions import (
|
||||
HTTPError, MissingSchema, InvalidURL, ChunkedEncodingError,
|
||||
ContentDecodingError, ConnectionError, StreamConsumedError)
|
||||
HTTPError, MissingScheme, InvalidURL, ChunkedEncodingError,
|
||||
ContentDecodingError, ConnectionError, StreamConsumedError,
|
||||
InvalidHeader, InvalidBodyError)
|
||||
from ._internal_utils import to_native_string, unicode_is_ascii
|
||||
from .utils import (
|
||||
guess_filename, get_auth_from_url, requote_uri,
|
||||
stream_decode_response_unicode, to_key_val_list, parse_header_links,
|
||||
iter_slices, guess_json_utf, super_len, check_header_validity)
|
||||
iter_slices, guess_json_utf, super_len, check_header_validity,
|
||||
is_stream)
|
||||
from .compat import (
|
||||
SKIP_HEADER,
|
||||
SKIPPABLE_HEADERS,
|
||||
Callable,
|
||||
Mapping,
|
||||
cookielib,
|
||||
urlunparse,
|
||||
urlsplit,
|
||||
urlencode,
|
||||
str,
|
||||
bytes,
|
||||
is_py2,
|
||||
chardet,
|
||||
builtin_str,
|
||||
basestring,
|
||||
)
|
||||
from .compat import json as complexjson
|
||||
cookielib, urlunparse, urlsplit, urlencode, str, bytes,
|
||||
is_py2, chardet, builtin_str, basestring)
|
||||
import json as complexjson
|
||||
from .status_codes import codes
|
||||
|
||||
#: The set of HTTP status codes that indicate an automatically
|
||||
@@ -168,12 +159,8 @@ class RequestEncodingMixin(object):
|
||||
|
||||
if isinstance(fp, (str, bytes, bytearray)):
|
||||
fdata = fp
|
||||
elif hasattr(fp, 'read'):
|
||||
fdata = fp.read()
|
||||
elif fp is None:
|
||||
continue
|
||||
else:
|
||||
fdata = fp
|
||||
fdata = fp.read()
|
||||
|
||||
rf = RequestField(name=k, data=fdata, filename=fn, headers=fh)
|
||||
rf.make_multipart(content_type=ft)
|
||||
@@ -191,10 +178,10 @@ class RequestHooksMixin(object):
|
||||
if event not in self.hooks:
|
||||
raise ValueError('Unsupported event specified, with event name "%s"' % (event))
|
||||
|
||||
if isinstance(hook, Callable):
|
||||
if isinstance(hook, collections.Callable):
|
||||
self.hooks[event].append(hook)
|
||||
elif hasattr(hook, '__iter__'):
|
||||
self.hooks[event].extend(h for h in hook if isinstance(h, Callable))
|
||||
self.hooks[event].extend(h for h in hook if isinstance(h, collections.Callable))
|
||||
|
||||
def deregister_hook(self, event, hook):
|
||||
"""Deregister a previously registered hook.
|
||||
@@ -217,13 +204,9 @@ class Request(RequestHooksMixin):
|
||||
:param url: URL to send.
|
||||
:param headers: dictionary of headers to send.
|
||||
:param files: dictionary of {filename: fileobject} files to multipart upload.
|
||||
:param data: the body to attach to the request. If a dictionary or
|
||||
list of tuples ``[(key, value)]`` is provided, form-encoding will
|
||||
take place.
|
||||
:param data: the body to attach to the request. If a dictionary is provided, form-encoding will take place.
|
||||
:param json: json for the body to attach to the request (if files or data is not specified).
|
||||
:param params: URL parameters to append to the URL. If a dictionary or
|
||||
list of tuples ``[(key, value)]`` is provided, form-encoding will
|
||||
take place.
|
||||
:param params: dictionary of URL parameters to append to the URL.
|
||||
:param auth: Auth handler or (user, pass) tuple.
|
||||
:param cookies: dictionary or CookieJar of cookies to attach to this request.
|
||||
:param hooks: dictionary of callback hooks, for internal usage.
|
||||
@@ -231,7 +214,7 @@ class Request(RequestHooksMixin):
|
||||
Usage::
|
||||
|
||||
>>> import requests
|
||||
>>> req = requests.Request('GET', 'https://httpbin.org/get')
|
||||
>>> req = requests.Request('GET', 'http://httpbin.org/get')
|
||||
>>> req.prepare()
|
||||
<PreparedRequest [GET]>
|
||||
"""
|
||||
@@ -286,16 +269,13 @@ class PreparedRequest(RequestEncodingMixin, RequestHooksMixin):
|
||||
"""The fully mutable :class:`PreparedRequest <PreparedRequest>` object,
|
||||
containing the exact bytes that will be sent to the server.
|
||||
|
||||
Instances are generated from a :class:`Request <Request>` object, and
|
||||
should not be instantiated manually; doing so may produce undesirable
|
||||
effects.
|
||||
Generated from either a :class:`Request <Request>` object or manually.
|
||||
|
||||
Usage::
|
||||
|
||||
>>> import requests
|
||||
>>> req = requests.Request('GET', 'https://httpbin.org/get')
|
||||
>>> req = requests.Request('GET', 'http://httpbin.org/get')
|
||||
>>> r = req.prepare()
|
||||
>>> r
|
||||
<PreparedRequest [GET]>
|
||||
|
||||
>>> s = requests.Session()
|
||||
@@ -355,8 +335,9 @@ class PreparedRequest(RequestEncodingMixin, RequestHooksMixin):
|
||||
def prepare_method(self, method):
|
||||
"""Prepares the given HTTP method."""
|
||||
self.method = method
|
||||
if self.method is not None:
|
||||
self.method = to_native_string(self.method.upper())
|
||||
if self.method is None:
|
||||
raise ValueError('Request method cannot be "None"')
|
||||
self.method = to_native_string(self.method.upper())
|
||||
|
||||
@staticmethod
|
||||
def _get_idna_encoded_host(host):
|
||||
@@ -374,14 +355,14 @@ class PreparedRequest(RequestEncodingMixin, RequestHooksMixin):
|
||||
#: We're unable to blindly call unicode/str functions
|
||||
#: as this will include the bytestring indicator (b'')
|
||||
#: on python 3.x.
|
||||
#: https://github.com/psf/requests/pull/2238
|
||||
#: https://github.com/requests/requests/pull/2238
|
||||
if isinstance(url, bytes):
|
||||
url = url.decode('utf8')
|
||||
else:
|
||||
url = unicode(url) if is_py2 else str(url)
|
||||
|
||||
# Remove leading whitespaces from url
|
||||
url = url.lstrip()
|
||||
# Ignore any leading and trailing whitespace characters.
|
||||
url = url.strip()
|
||||
|
||||
# Don't do any URL preparation for non-HTTP schemes like `mailto`,
|
||||
# `data` etc to work around exceptions from `url_parse`, which
|
||||
@@ -397,10 +378,10 @@ class PreparedRequest(RequestEncodingMixin, RequestHooksMixin):
|
||||
raise InvalidURL(*e.args)
|
||||
|
||||
if not scheme:
|
||||
error = ("Invalid URL {0!r}: No schema supplied. Perhaps you meant http://{0}?")
|
||||
error = ("Invalid URL {0!r}: No scheme supplied. Perhaps you meant http://{0}?")
|
||||
error = error.format(to_native_string(url, 'utf8'))
|
||||
|
||||
raise MissingSchema(error)
|
||||
raise MissingScheme(error)
|
||||
|
||||
if not host:
|
||||
raise InvalidURL("Invalid URL %r: No host supplied" % url)
|
||||
@@ -460,14 +441,9 @@ class PreparedRequest(RequestEncodingMixin, RequestHooksMixin):
|
||||
self.headers = CaseInsensitiveDict()
|
||||
if headers:
|
||||
for header in headers.items():
|
||||
name, value = header
|
||||
if value is None:
|
||||
if name.lower() in SKIPPABLE_HEADERS:
|
||||
value = SKIP_HEADER
|
||||
else:
|
||||
continue
|
||||
# Raise exception on invalid header value.
|
||||
check_header_validity(header)
|
||||
name, value = header
|
||||
self.headers[to_native_string(name)] = value
|
||||
|
||||
def prepare_body(self, data, files, json=None):
|
||||
@@ -488,17 +464,7 @@ class PreparedRequest(RequestEncodingMixin, RequestHooksMixin):
|
||||
if not isinstance(body, bytes):
|
||||
body = body.encode('utf-8')
|
||||
|
||||
is_stream = all([
|
||||
hasattr(data, '__iter__'),
|
||||
not isinstance(data, (basestring, list, tuple, Mapping))
|
||||
])
|
||||
|
||||
if is_stream:
|
||||
try:
|
||||
length = super_len(data)
|
||||
except (TypeError, AttributeError, UnsupportedOperation):
|
||||
length = None
|
||||
|
||||
if is_stream(data):
|
||||
body = data
|
||||
|
||||
if getattr(body, 'tell', None) is not None:
|
||||
@@ -515,10 +481,6 @@ class PreparedRequest(RequestEncodingMixin, RequestHooksMixin):
|
||||
if files:
|
||||
raise NotImplementedError('Streamed bodies and files are mutually exclusive.')
|
||||
|
||||
if length:
|
||||
self.headers['Content-Length'] = builtin_str(length)
|
||||
else:
|
||||
self.headers['Transfer-Encoding'] = 'chunked'
|
||||
else:
|
||||
# Multi-part file uploads.
|
||||
if files:
|
||||
@@ -531,27 +493,40 @@ class PreparedRequest(RequestEncodingMixin, RequestHooksMixin):
|
||||
else:
|
||||
content_type = 'application/x-www-form-urlencoded'
|
||||
|
||||
self.prepare_content_length(body)
|
||||
|
||||
# Add content-type if it wasn't explicitly provided.
|
||||
if content_type and ('content-type' not in self.headers):
|
||||
self.headers['Content-Type'] = content_type
|
||||
|
||||
self.prepare_content_length(body)
|
||||
self.body = body
|
||||
|
||||
def prepare_content_length(self, body):
|
||||
"""Prepare Content-Length header based on request method and body"""
|
||||
"""Prepares Content-Length header.
|
||||
|
||||
If the length of the body of the request can be computed, Content-Length
|
||||
is set using ``super_len``. If user has manually set either a
|
||||
Transfer-Encoding or Content-Length header when it should not be set
|
||||
(they should be mutually exclusive) an InvalidHeader
|
||||
error will be raised.
|
||||
"""
|
||||
if body is not None:
|
||||
length = super_len(body)
|
||||
|
||||
if length:
|
||||
# If length exists, set it. Otherwise, we fallback
|
||||
# to Transfer-Encoding: chunked.
|
||||
self.headers['Content-Length'] = builtin_str(length)
|
||||
elif is_stream(body):
|
||||
self.headers['Transfer-Encoding'] = 'chunked'
|
||||
else:
|
||||
raise InvalidBodyError('Non-null body must have length or be streamable.')
|
||||
elif self.method not in ('GET', 'HEAD') and self.headers.get('Content-Length') is None:
|
||||
# Set Content-Length to 0 for methods that can have a body
|
||||
# but don't provide one. (i.e. not GET or HEAD)
|
||||
self.headers['Content-Length'] = '0'
|
||||
|
||||
if 'Transfer-Encoding' in self.headers and 'Content-Length' in self.headers:
|
||||
raise InvalidHeader('Conflicting Headers: Both Transfer-Encoding and '
|
||||
'Content-Length are set.')
|
||||
|
||||
def prepare_auth(self, auth, url=''):
|
||||
"""Prepares the given HTTP auth data."""
|
||||
|
||||
@@ -603,6 +578,14 @@ class PreparedRequest(RequestEncodingMixin, RequestHooksMixin):
|
||||
for event in hooks:
|
||||
self.register_hook(event, hooks[event])
|
||||
|
||||
def send(self, session=None, **send_kwargs):
|
||||
"""Sends the PreparedRequest to the given Session.
|
||||
If none is provided, one is created for you."""
|
||||
session = requests.Session() if session is None else session
|
||||
|
||||
with session:
|
||||
return session.send(self, **send_kwargs)
|
||||
|
||||
|
||||
class Response(object):
|
||||
"""The :class:`Response <Response>` object, which contains a
|
||||
@@ -615,6 +598,8 @@ class Response(object):
|
||||
]
|
||||
|
||||
def __init__(self):
|
||||
super(Response, self).__init__()
|
||||
|
||||
self._content = False
|
||||
self._content_consumed = False
|
||||
self._next = None
|
||||
@@ -629,13 +614,14 @@ class Response(object):
|
||||
|
||||
#: File-like object representation of response (for advanced usage).
|
||||
#: Use of ``raw`` requires that ``stream=True`` be set on the request.
|
||||
#: This requirement does not apply for use internally to Requests.
|
||||
# This requirement does not apply for use internally to Requests.
|
||||
self.raw = None
|
||||
|
||||
#: Final URL location of Response.
|
||||
self.url = None
|
||||
|
||||
#: Encoding to decode with when accessing r.text.
|
||||
#: Encoding to decode with when accessing r.text or
|
||||
#: r.iter_content(decode_unicode=True)
|
||||
self.encoding = None
|
||||
|
||||
#: A list of :class:`Response <Response>` objects from
|
||||
@@ -661,19 +647,16 @@ class Response(object):
|
||||
#: is a response.
|
||||
self.request = None
|
||||
|
||||
def __enter__(self):
|
||||
return self
|
||||
|
||||
def __exit__(self, *args):
|
||||
self.close()
|
||||
|
||||
def __getstate__(self):
|
||||
# Consume everything; accessing the content attribute makes
|
||||
# sure the content has been fully read.
|
||||
if not self._content_consumed:
|
||||
self.content
|
||||
|
||||
return {attr: getattr(self, attr, None) for attr in self.__attrs__}
|
||||
return dict(
|
||||
(attr, getattr(self, attr, None))
|
||||
for attr in self.__attrs__
|
||||
)
|
||||
|
||||
def __setstate__(self, state):
|
||||
for name, value in state.items():
|
||||
@@ -686,37 +669,17 @@ class Response(object):
|
||||
def __repr__(self):
|
||||
return '<Response [%s]>' % (self.status_code)
|
||||
|
||||
def __bool__(self):
|
||||
"""Returns True if :attr:`status_code` is less than 400.
|
||||
|
||||
This attribute checks if the status code of the response is between
|
||||
400 and 600 to see if there was a client error or a server error. If
|
||||
the status code, is between 200 and 400, this will return True. This
|
||||
is **not** a check to see if the response code is ``200 OK``.
|
||||
"""
|
||||
return self.ok
|
||||
|
||||
def __nonzero__(self):
|
||||
"""Returns True if :attr:`status_code` is less than 400.
|
||||
|
||||
This attribute checks if the status code of the response is between
|
||||
400 and 600 to see if there was a client error or a server error. If
|
||||
the status code, is between 200 and 400, this will return True. This
|
||||
is **not** a check to see if the response code is ``200 OK``.
|
||||
"""
|
||||
return self.ok
|
||||
|
||||
def __iter__(self):
|
||||
"""Allows you to use a response as an iterator."""
|
||||
return self.iter_content(128)
|
||||
|
||||
@property
|
||||
def ok(self):
|
||||
"""Returns True if :attr:`status_code` is less than 400, False if not.
|
||||
"""Returns True if :attr:`status_code` is less than 400.
|
||||
|
||||
This attribute checks if the status code of the response is between
|
||||
400 and 600 to see if there was a client error or a server error. If
|
||||
the status code is between 200 and 400, this will return True. This
|
||||
the status code, is between 200 and 400, this will return True. This
|
||||
is **not** a check to see if the response code is ``200 OK``.
|
||||
"""
|
||||
try:
|
||||
@@ -760,8 +723,8 @@ class Response(object):
|
||||
chunks are received. If stream=False, data is returned as
|
||||
a single chunk.
|
||||
|
||||
If decode_unicode is True, content will be decoded using the best
|
||||
available encoding based on the response.
|
||||
If using decode_unicode, the encoding must be set to a valid encoding
|
||||
enumeration before invoking iter_content.
|
||||
"""
|
||||
|
||||
def generate():
|
||||
@@ -771,7 +734,10 @@ class Response(object):
|
||||
for chunk in self.raw.stream(chunk_size, decode_content=True):
|
||||
yield chunk
|
||||
except ProtocolError as e:
|
||||
raise ChunkedEncodingError(e)
|
||||
if self.headers.get('Transfer-Encoding') == 'chunked':
|
||||
raise ChunkedEncodingError(e)
|
||||
else:
|
||||
raise ConnectionError(e)
|
||||
except DecodeError as e:
|
||||
raise ContentDecodingError(e)
|
||||
except ReadTimeoutError as e:
|
||||
@@ -798,34 +764,88 @@ class Response(object):
|
||||
chunks = reused_chunks if self._content_consumed else stream_chunks
|
||||
|
||||
if decode_unicode:
|
||||
if self.encoding is None:
|
||||
raise TypeError(
|
||||
'encoding must be set before consuming streaming '
|
||||
'responses'
|
||||
)
|
||||
|
||||
# check encoding value here, don't wait for the generator to be
|
||||
# consumed before raising an exception
|
||||
codecs.lookup(self.encoding)
|
||||
|
||||
chunks = stream_decode_response_unicode(chunks, self)
|
||||
|
||||
return chunks
|
||||
|
||||
def iter_lines(self, chunk_size=ITER_CHUNK_SIZE, decode_unicode=False, delimiter=None):
|
||||
def iter_lines(self, chunk_size=ITER_CHUNK_SIZE, decode_unicode=None, delimiter=None):
|
||||
"""Iterates over the response data, one line at a time. When
|
||||
stream=True is set on the request, this avoids reading the
|
||||
content at once into memory for large responses.
|
||||
|
||||
.. note:: This method is not reentrant safe.
|
||||
"""
|
||||
carriage_return = u'\r' if decode_unicode else b'\r'
|
||||
line_feed = u'\n' if decode_unicode else b'\n'
|
||||
|
||||
pending = None
|
||||
last_chunk_ends_with_cr = False
|
||||
|
||||
for chunk in self.iter_content(chunk_size=chunk_size, decode_unicode=decode_unicode):
|
||||
for chunk in self.iter_content(chunk_size=chunk_size,
|
||||
decode_unicode=decode_unicode):
|
||||
# Skip any null responses: if there is pending data it is necessarily an
|
||||
# incomplete chunk, so if we don't have more data we don't want to bother
|
||||
# trying to get it. Unconsumed pending data will be yielded anyway in the
|
||||
# end of the loop if the stream ends.
|
||||
if not chunk:
|
||||
continue
|
||||
|
||||
# Consume any pending data
|
||||
if pending is not None:
|
||||
chunk = pending + chunk
|
||||
pending = None
|
||||
|
||||
# Either split on a line, or split on a specified delimiter
|
||||
if delimiter:
|
||||
lines = chunk.split(delimiter)
|
||||
else:
|
||||
# Python splitlines() supports the universal newline (PEP 278).
|
||||
# That means, '\r', '\n', and '\r\n' are all treated as end of
|
||||
# line. If the last chunk ends with '\r', and the current chunk
|
||||
# starts with '\n', they should be merged and treated as only
|
||||
# *one* new line separator '\r\n' by splitlines().
|
||||
# This rule only applies when splitlines() is used.
|
||||
|
||||
# The last chunk ends with '\r', so the '\n' at chunk[0]
|
||||
# is just the second half of a '\r\n' pair rather than a
|
||||
# new line break. Just skip it.
|
||||
skip_first_char = last_chunk_ends_with_cr and chunk.startswith(line_feed)
|
||||
last_chunk_ends_with_cr = chunk.endswith(carriage_return)
|
||||
if skip_first_char:
|
||||
chunk = chunk[1:]
|
||||
# it's possible that after stripping the '\n' then chunk becomes empty
|
||||
if not chunk:
|
||||
continue
|
||||
lines = chunk.splitlines()
|
||||
|
||||
if lines and lines[-1] and chunk and lines[-1][-1] == chunk[-1]:
|
||||
# Calling `.split(delimiter)` will always end with whatever text
|
||||
# remains beyond the delimiter, or '' if the delimiter is the end
|
||||
# of the text. On the other hand, `.splitlines()` doesn't include
|
||||
# a '' if the text ends in a line delimiter.
|
||||
#
|
||||
# For example:
|
||||
#
|
||||
# 'abc\ndef\n'.split('\n') ~> ['abc', 'def', '']
|
||||
# 'abc\ndef\n'.splitlines() ~> ['abc', 'def']
|
||||
#
|
||||
# So if we have a specified delimiter, we always pop the final
|
||||
# item and prepend it to the next chunk.
|
||||
#
|
||||
# If we're using `splitlines()`, we only do this if the chunk
|
||||
# ended midway through a line.
|
||||
incomplete_line = lines[-1] and lines[-1][-1] == chunk[-1]
|
||||
if delimiter or incomplete_line:
|
||||
pending = lines.pop()
|
||||
else:
|
||||
pending = None
|
||||
|
||||
for line in lines:
|
||||
yield line
|
||||
@@ -846,7 +866,7 @@ class Response(object):
|
||||
if self.status_code == 0 or self.raw is None:
|
||||
self._content = None
|
||||
else:
|
||||
self._content = b''.join(self.iter_content(CONTENT_CHUNK_SIZE)) or b''
|
||||
self._content = bytes().join(self.iter_content(CONTENT_CHUNK_SIZE)) or bytes()
|
||||
|
||||
self._content_consumed = True
|
||||
# don't need to release the connection; that's been handled by urllib3
|
||||
@@ -936,7 +956,8 @@ class Response(object):
|
||||
return l
|
||||
|
||||
def raise_for_status(self):
|
||||
"""Raises :class:`HTTPError`, if one occurred."""
|
||||
"""Raises stored :class:`HTTPError`, if one occurred.
|
||||
Otherwise, returns the response object (self)."""
|
||||
|
||||
http_error_msg = ''
|
||||
if isinstance(self.reason, bytes):
|
||||
@@ -960,6 +981,8 @@ class Response(object):
|
||||
if http_error_msg:
|
||||
raise HTTPError(http_error_msg, response=self)
|
||||
|
||||
return self
|
||||
|
||||
def close(self):
|
||||
"""Releases the connection back to the pool. Once this method has been
|
||||
called the underlying ``raw`` object must not be accessed again.
|
||||
|
||||
341
requests/sessions.py
Normal file → Executable file
@@ -8,28 +8,30 @@ This module provides a Session object to manage and persist settings across
|
||||
requests (cookies, auth, proxies).
|
||||
"""
|
||||
import os
|
||||
import sys
|
||||
import platform
|
||||
import time
|
||||
from collections import Mapping
|
||||
from datetime import timedelta
|
||||
from collections import OrderedDict
|
||||
|
||||
from .auth import _basic_auth_str
|
||||
from .compat import cookielib, is_py3, urljoin, urlparse, Mapping
|
||||
from .compat import cookielib, OrderedDict, urljoin, urlparse, is_py3, str
|
||||
from .cookies import (
|
||||
cookiejar_from_dict, extract_cookies_to_jar, RequestsCookieJar, merge_cookies)
|
||||
cookiejar_from_dict, extract_cookies_to_jar, RequestsCookieJar,
|
||||
merge_cookies, _copy_cookie_jar)
|
||||
from .models import Request, PreparedRequest, DEFAULT_REDIRECT_LIMIT
|
||||
from .hooks import default_hooks, dispatch_hook
|
||||
from ._internal_utils import to_native_string
|
||||
from .utils import to_key_val_list, default_headers, DEFAULT_PORTS
|
||||
from .utils import to_key_val_list, default_headers
|
||||
from .exceptions import (
|
||||
TooManyRedirects, InvalidSchema, ChunkedEncodingError, ContentDecodingError)
|
||||
TooManyRedirects, InvalidScheme, ChunkedEncodingError,
|
||||
ConnectionError, ContentDecodingError, InvalidHeader)
|
||||
|
||||
from .structures import CaseInsensitiveDict
|
||||
from .adapters import HTTPAdapter
|
||||
|
||||
from .utils import (
|
||||
requote_uri, get_environ_proxies, get_netrc_auth, should_bypass_proxies,
|
||||
get_auth_from_url, rewind_body
|
||||
get_auth_from_url, is_valid_location, rewind_body
|
||||
)
|
||||
|
||||
from .status_codes import codes
|
||||
@@ -38,8 +40,8 @@ from .status_codes import codes
|
||||
from .models import REDIRECT_STATI
|
||||
|
||||
# Preferred clock, based on which one is more accurate on a given system.
|
||||
if sys.platform == 'win32':
|
||||
try: # Python 3.4+
|
||||
if platform.system() == 'Windows':
|
||||
try: # Python 3.3+
|
||||
preferred_clock = time.perf_counter
|
||||
except AttributeError: # Earlier than Python 3.
|
||||
preferred_clock = time.clock
|
||||
@@ -47,12 +49,10 @@ else:
|
||||
preferred_clock = time.time
|
||||
|
||||
|
||||
def merge_setting(
|
||||
request_setting, session_setting, dict_class=OrderedDict, delete_none=True
|
||||
):
|
||||
def merge_setting(request_setting, session_setting, dict_class=OrderedDict):
|
||||
"""Determines appropriate setting for a given request, taking into account
|
||||
the explicit setting on that request, and the setting in the session. If a
|
||||
setting is a dictionary, they will be merged together using `dict_class`
|
||||
setting is a dictionary, they will be merged together using `dict_class`.
|
||||
"""
|
||||
|
||||
if session_setting is None:
|
||||
@@ -71,12 +71,11 @@ def merge_setting(
|
||||
merged_setting = dict_class(to_key_val_list(session_setting))
|
||||
merged_setting.update(to_key_val_list(request_setting))
|
||||
|
||||
if delete_none:
|
||||
# Remove keys that are set to None. Extract keys first to avoid altering
|
||||
# the dictionary during iteration.
|
||||
none_keys = [k for (k, v) in merged_setting.items() if v is None]
|
||||
for key in none_keys:
|
||||
del merged_setting[key]
|
||||
# Remove keys that are set to None. Extract keys first to avoid altering
|
||||
# the dictionary during iteration.
|
||||
none_keys = [k for (k, v) in merged_setting.items() if v is None]
|
||||
for key in none_keys:
|
||||
del merged_setting[key]
|
||||
|
||||
return merged_setting
|
||||
|
||||
@@ -98,16 +97,14 @@ def merge_hooks(request_hooks, session_hooks, dict_class=OrderedDict):
|
||||
|
||||
class SessionRedirectMixin(object):
|
||||
|
||||
def get_redirect_target(self, resp):
|
||||
def get_redirect_target(self, response):
|
||||
"""Receives a Response. Returns a redirect URI or ``None``"""
|
||||
# Due to the nature of how requests processes redirects this method will
|
||||
# be called at least once upon the original response and at least twice
|
||||
# on each subsequent redirect response (if any).
|
||||
# If a custom mixin is used to handle this logic, it may be advantageous
|
||||
# to cache the redirect location onto the response object as a private
|
||||
# attribute.
|
||||
if resp.is_redirect:
|
||||
location = resp.headers['location']
|
||||
if response.is_redirect:
|
||||
if not is_valid_location(response):
|
||||
raise InvalidHeader('Response contains multiple Location headers. '
|
||||
'Unable to perform redirect.')
|
||||
|
||||
location = response.headers['location']
|
||||
# Currently the underlying http module on py3 decode headers
|
||||
# in latin1, but empirical evidence suggests that latin1 is very
|
||||
# rarely used with non-ASCII characters in HTTP headers.
|
||||
@@ -119,104 +116,78 @@ class SessionRedirectMixin(object):
|
||||
return to_native_string(location, 'utf8')
|
||||
return None
|
||||
|
||||
def should_strip_auth(self, old_url, new_url):
|
||||
"""Decide whether Authorization header should be removed when redirecting"""
|
||||
old_parsed = urlparse(old_url)
|
||||
new_parsed = urlparse(new_url)
|
||||
if old_parsed.hostname != new_parsed.hostname:
|
||||
return True
|
||||
# Special case: allow http -> https redirect when using the standard
|
||||
# ports. This isn't specified by RFC 7235, but is kept to avoid
|
||||
# breaking backwards compatibility with older versions of requests
|
||||
# that allowed any redirects on the same host.
|
||||
if (old_parsed.scheme == 'http' and old_parsed.port in (80, None)
|
||||
and new_parsed.scheme == 'https' and new_parsed.port in (443, None)):
|
||||
return False
|
||||
def resolve_redirects(self, response, request, stream=False, timeout=None,
|
||||
verify=True, cert=None, proxies=None,
|
||||
yield_requests=False, **adapter_kwargs):
|
||||
"""Given a Response, yields Responses until 'Location' header-based
|
||||
redirection ceases, or the Session.max_redirects limit has been
|
||||
reached.
|
||||
"""
|
||||
|
||||
# Handle default port usage corresponding to scheme.
|
||||
changed_port = old_parsed.port != new_parsed.port
|
||||
changed_scheme = old_parsed.scheme != new_parsed.scheme
|
||||
default_port = (DEFAULT_PORTS.get(old_parsed.scheme, None), None)
|
||||
if (not changed_scheme and old_parsed.port in default_port
|
||||
and new_parsed.port in default_port):
|
||||
return False
|
||||
history = [response] # keep track of history; seed it with the original response
|
||||
|
||||
# Standard case: root URI must match
|
||||
return changed_port or changed_scheme
|
||||
location_url = self.get_redirect_target(response)
|
||||
|
||||
def resolve_redirects(self, resp, req, stream=False, timeout=None,
|
||||
verify=True, cert=None, proxies=None, yield_requests=False, **adapter_kwargs):
|
||||
"""Receives a Response. Returns a generator of Responses or Requests."""
|
||||
|
||||
hist = [] # keep track of history
|
||||
|
||||
url = self.get_redirect_target(resp)
|
||||
previous_fragment = urlparse(req.url).fragment
|
||||
while url:
|
||||
prepared_request = req.copy()
|
||||
|
||||
# Update history and keep track of redirects.
|
||||
# resp.history must ignore the original request in this loop
|
||||
hist.append(resp)
|
||||
resp.history = hist[1:]
|
||||
while location_url:
|
||||
prepared_request = request.copy()
|
||||
|
||||
try:
|
||||
resp.content # Consume socket so it can be released
|
||||
except (ChunkedEncodingError, ContentDecodingError, RuntimeError):
|
||||
resp.raw.read(decode_content=False)
|
||||
response.content # Consume socket so it can be released
|
||||
except (ChunkedEncodingError, ConnectionError, ContentDecodingError, RuntimeError):
|
||||
response.raw.read(decode_content=False)
|
||||
|
||||
if len(resp.history) >= self.max_redirects:
|
||||
raise TooManyRedirects('Exceeded {} redirects.'.format(self.max_redirects), response=resp)
|
||||
if len(response.history) >= self.max_redirects:
|
||||
raise TooManyRedirects('Exceeded %s redirects.' % self.max_redirects, response=response)
|
||||
|
||||
# Release the connection back into the pool.
|
||||
resp.close()
|
||||
response.close()
|
||||
|
||||
# Handle redirection without scheme (see: RFC 1808 Section 4)
|
||||
if url.startswith('//'):
|
||||
parsed_rurl = urlparse(resp.url)
|
||||
url = ':'.join([to_native_string(parsed_rurl.scheme), url])
|
||||
if location_url.startswith('//'):
|
||||
parsed_rurl = urlparse(response.url)
|
||||
location_url = '%s:%s' % (to_native_string(parsed_rurl.scheme), location_url)
|
||||
|
||||
# Normalize url case and attach previous fragment if needed (RFC 7231 7.1.2)
|
||||
parsed = urlparse(url)
|
||||
if parsed.fragment == '' and previous_fragment:
|
||||
parsed = parsed._replace(fragment=previous_fragment)
|
||||
elif parsed.fragment:
|
||||
previous_fragment = parsed.fragment
|
||||
url = parsed.geturl()
|
||||
# The scheme should be lower case...
|
||||
parsed = urlparse(location_url)
|
||||
location_url = parsed.geturl()
|
||||
|
||||
# Facilitate relative 'location' headers, as allowed by RFC 7231.
|
||||
# (e.g. '/path/to/resource' instead of 'http://domain.tld/path/to/resource')
|
||||
# Compliant with RFC3986, we percent encode the url.
|
||||
if not parsed.netloc:
|
||||
url = urljoin(resp.url, requote_uri(url))
|
||||
location_url = urljoin(response.url, requote_uri(location_url))
|
||||
else:
|
||||
url = requote_uri(url)
|
||||
location_url = requote_uri(location_url)
|
||||
|
||||
prepared_request.url = to_native_string(url)
|
||||
prepared_request.url = to_native_string(location_url)
|
||||
|
||||
self.rebuild_method(prepared_request, resp)
|
||||
method_changed = self.rebuild_method(prepared_request, response)
|
||||
|
||||
# https://github.com/psf/requests/issues/1084
|
||||
if resp.status_code not in (codes.temporary_redirect, codes.permanent_redirect):
|
||||
# https://github.com/psf/requests/issues/3490
|
||||
# https://github.com/kennethreitz/requests/issues/2590
|
||||
# If method is changed to GET we need to remove body and associated headers.
|
||||
if method_changed and prepared_request.method == 'GET':
|
||||
# https://github.com/requests/requests/issues/3490
|
||||
purged_headers = ('Content-Length', 'Content-Type', 'Transfer-Encoding')
|
||||
for header in purged_headers:
|
||||
prepared_request.headers.pop(header, None)
|
||||
prepared_request.body = None
|
||||
|
||||
headers = prepared_request.headers
|
||||
headers.pop('Cookie', None)
|
||||
try:
|
||||
del headers['Cookie']
|
||||
except KeyError:
|
||||
pass
|
||||
|
||||
# Extract any cookies sent on the response to the cookiejar
|
||||
# in the new request. Because we've mutated our copied prepared
|
||||
# request, use the old one that we haven't yet touched.
|
||||
extract_cookies_to_jar(prepared_request._cookies, req, resp.raw)
|
||||
extract_cookies_to_jar(prepared_request._cookies, request, response.raw)
|
||||
merge_cookies(prepared_request._cookies, self.cookies)
|
||||
prepared_request.prepare_cookies(prepared_request._cookies)
|
||||
|
||||
# Rebuild auth and proxy information.
|
||||
proxies = self.rebuild_proxies(prepared_request, proxies)
|
||||
self.rebuild_auth(prepared_request, resp)
|
||||
self.rebuild_auth(prepared_request, response)
|
||||
|
||||
# A failed tell() sets `_body_position` to `object()`. This non-None
|
||||
# value ensures `rewindable` will be True, allowing us to raise an
|
||||
@@ -231,14 +202,14 @@ class SessionRedirectMixin(object):
|
||||
rewind_body(prepared_request)
|
||||
|
||||
# Override the original request.
|
||||
req = prepared_request
|
||||
request = prepared_request
|
||||
|
||||
if yield_requests:
|
||||
yield req
|
||||
yield request
|
||||
else:
|
||||
|
||||
resp = self.send(
|
||||
req,
|
||||
response = self.send(
|
||||
request,
|
||||
stream=stream,
|
||||
timeout=timeout,
|
||||
verify=verify,
|
||||
@@ -247,38 +218,48 @@ class SessionRedirectMixin(object):
|
||||
allow_redirects=False,
|
||||
**adapter_kwargs
|
||||
)
|
||||
# copy our history tracker into the response
|
||||
response.history = history[:]
|
||||
# append the new response to the history tracker for the next iteration
|
||||
history.append(response)
|
||||
|
||||
extract_cookies_to_jar(self.cookies, prepared_request, resp.raw)
|
||||
extract_cookies_to_jar(self.cookies, prepared_request, response.raw)
|
||||
|
||||
# extract redirect url, if any, for the next loop
|
||||
url = self.get_redirect_target(resp)
|
||||
yield resp
|
||||
location_url = self.get_redirect_target(response)
|
||||
yield response
|
||||
|
||||
def rebuild_auth(self, prepared_request, response):
|
||||
"""When being redirected we may want to strip authentication from the
|
||||
request to avoid leaking credentials. This method intelligently removes
|
||||
request to avoid leaking credentials. This method intelligently
|
||||
removes
|
||||
and reapplies authentication where possible to avoid credential loss.
|
||||
"""
|
||||
headers = prepared_request.headers
|
||||
url = prepared_request.url
|
||||
|
||||
if 'Authorization' in headers and self.should_strip_auth(response.request.url, url):
|
||||
if 'Authorization' in headers:
|
||||
# If we get redirected to a new host, we should strip out any
|
||||
# authentication headers.
|
||||
del headers['Authorization']
|
||||
original_parsed = urlparse(response.request.url)
|
||||
redirect_parsed = urlparse(url)
|
||||
|
||||
if (original_parsed.hostname != redirect_parsed.hostname):
|
||||
del headers['Authorization']
|
||||
|
||||
# .netrc might have more auth for us on our new host.
|
||||
new_auth = get_netrc_auth(url) if self.trust_env else None
|
||||
if new_auth is not None:
|
||||
prepared_request.prepare_auth(new_auth)
|
||||
|
||||
return
|
||||
|
||||
def rebuild_proxies(self, prepared_request, proxies):
|
||||
"""This method re-evaluates the proxy configuration by considering the
|
||||
environment variables. If we are redirected to a URL covered by
|
||||
NO_PROXY, we strip the proxy configuration. Otherwise, we set missing
|
||||
proxy keys for this URL (in case they were stripped by a previous
|
||||
redirect).
|
||||
"""This method re-evaluates the proxy configuration by
|
||||
considering the environment variables. If we are redirected to a
|
||||
URL covered by NO_PROXY, we strip the proxy configuration.
|
||||
Otherwise, we set missing proxy keys for this URL (in case they
|
||||
were stripped by a previous redirect).
|
||||
|
||||
This method also replaces the Proxy-Authorization header where
|
||||
necessary.
|
||||
@@ -317,24 +298,26 @@ class SessionRedirectMixin(object):
|
||||
def rebuild_method(self, prepared_request, response):
|
||||
"""When being redirected we may want to change the method of the request
|
||||
based on certain specs or browser behavior.
|
||||
"""
|
||||
method = prepared_request.method
|
||||
|
||||
# https://tools.ietf.org/html/rfc7231#section-6.4.4
|
||||
:rtype bool:
|
||||
:return: boolean expressing if the method changed during rebuild.
|
||||
"""
|
||||
method = original_method = prepared_request.method
|
||||
|
||||
# http://tools.ietf.org/html/rfc7231#section-6.4.4
|
||||
if response.status_code == codes.see_other and method != 'HEAD':
|
||||
method = 'GET'
|
||||
|
||||
# Do what the browsers do, despite standards...
|
||||
# First, turn 302s into GETs.
|
||||
if response.status_code == codes.found and method != 'HEAD':
|
||||
method = 'GET'
|
||||
|
||||
# Second, if a POST is responded to with a 301, turn it into a GET.
|
||||
# This bizarre behaviour is explained in Issue 1704.
|
||||
if response.status_code == codes.moved and method == 'POST':
|
||||
# If a POST is responded to with a 301 or 302, turn it into a GET. This has
|
||||
# become a common pattern in browsers and was introduced into later versions
|
||||
# of HTTP RFCs. While some browsers transform other methods to GET, little of
|
||||
# that has been standardized. For that reason, we're using curl as a model
|
||||
# which only supports POST->GET.
|
||||
if response.status_code in (codes.found, codes.moved) and method == 'POST':
|
||||
method = 'GET'
|
||||
|
||||
prepared_request.method = method
|
||||
return method != original_method
|
||||
|
||||
|
||||
class Session(SessionRedirectMixin):
|
||||
@@ -346,19 +329,19 @@ class Session(SessionRedirectMixin):
|
||||
|
||||
>>> import requests
|
||||
>>> s = requests.Session()
|
||||
>>> s.get('https://httpbin.org/get')
|
||||
>>> s.get('http://httpbin.org/get')
|
||||
<Response [200]>
|
||||
|
||||
Or as a context manager::
|
||||
|
||||
>>> with requests.Session() as s:
|
||||
... s.get('https://httpbin.org/get')
|
||||
>>> s.get('http://httpbin.org/get')
|
||||
<Response [200]>
|
||||
"""
|
||||
|
||||
__attrs__ = [
|
||||
'headers', 'cookies', 'auth', 'proxies', 'hooks', 'params', 'verify',
|
||||
'cert', 'adapters', 'stream', 'trust_env',
|
||||
'cert', 'prefetch', 'adapters', 'stream', 'trust_env',
|
||||
'max_redirects',
|
||||
]
|
||||
|
||||
@@ -390,13 +373,6 @@ class Session(SessionRedirectMixin):
|
||||
self.stream = False
|
||||
|
||||
#: SSL Verification default.
|
||||
#: Defaults to `True`, requiring requests to verify the TLS certificate at the
|
||||
#: remote end.
|
||||
#: If verify is set to `False`, requests will accept any TLS certificate
|
||||
#: presented by the server, and will ignore hostname mismatches and/or
|
||||
#: expired certificates, which will make your application vulnerable to
|
||||
#: man-in-the-middle (MitM) attacks.
|
||||
#: Only set this to `False` for testing.
|
||||
self.verify = True
|
||||
|
||||
#: SSL client certificate default, if String, path to ssl client
|
||||
@@ -437,7 +413,7 @@ class Session(SessionRedirectMixin):
|
||||
:class:`Session`.
|
||||
|
||||
:param request: :class:`Request` instance to prepare with this
|
||||
session's settings.
|
||||
Session's settings.
|
||||
:rtype: requests.PreparedRequest
|
||||
"""
|
||||
cookies = request.cookies or {}
|
||||
@@ -447,8 +423,8 @@ class Session(SessionRedirectMixin):
|
||||
cookies = cookiejar_from_dict(cookies)
|
||||
|
||||
# Merge with session cookies
|
||||
merged_cookies = merge_cookies(
|
||||
merge_cookies(RequestsCookieJar(), self.cookies), cookies)
|
||||
session_cookies = _copy_cookie_jar(self.cookies)
|
||||
merged_cookies = merge_cookies(session_cookies, cookies)
|
||||
|
||||
# Set environment's basic authentication if not explicitly set.
|
||||
auth = request.auth
|
||||
@@ -462,12 +438,7 @@ class Session(SessionRedirectMixin):
|
||||
files=request.files,
|
||||
data=request.data,
|
||||
json=request.json,
|
||||
headers=merge_setting(
|
||||
request.headers,
|
||||
self.headers,
|
||||
dict_class=CaseInsensitiveDict,
|
||||
delete_none=False,
|
||||
),
|
||||
headers=merge_setting(request.headers, self.headers, dict_class=CaseInsensitiveDict),
|
||||
params=merge_setting(request.params, self.params),
|
||||
auth=merge_setting(auth, self.auth),
|
||||
cookies=merged_cookies,
|
||||
@@ -479,15 +450,15 @@ class Session(SessionRedirectMixin):
|
||||
params=None, data=None, headers=None, cookies=None, files=None,
|
||||
auth=None, timeout=None, allow_redirects=True, proxies=None,
|
||||
hooks=None, stream=None, verify=None, cert=None, json=None):
|
||||
"""Constructs a :class:`Request <Request>`, prepares it and sends it.
|
||||
"""Constructs a :class:`Request <Request>`, prepares it, and sends it.
|
||||
Returns :class:`Response <Response>` object.
|
||||
|
||||
:param method: method for the new :class:`Request` object.
|
||||
:param url: URL for the new :class:`Request` object.
|
||||
:param params: (optional) Dictionary or bytes to be sent in the query
|
||||
string for the :class:`Request`.
|
||||
:param data: (optional) Dictionary, list of tuples, bytes, or file-like
|
||||
object to send in the body of the :class:`Request`.
|
||||
:param data: (optional) Dictionary, bytes, or file-like object to send
|
||||
in the body of the :class:`Request`.
|
||||
:param json: (optional) json to send in the body of the
|
||||
:class:`Request`.
|
||||
:param headers: (optional) Dictionary of HTTP Headers to send with the
|
||||
@@ -510,12 +481,7 @@ class Session(SessionRedirectMixin):
|
||||
content. Defaults to ``False``.
|
||||
:param verify: (optional) Either a boolean, in which case it controls whether we verify
|
||||
the server's TLS certificate, or a string, in which case it must be a path
|
||||
to a CA bundle to use. Defaults to ``True``. When set to
|
||||
``False``, requests will accept any TLS certificate presented by
|
||||
the server, and will ignore hostname mismatches and/or expired
|
||||
certificates, which will make your application vulnerable to
|
||||
man-in-the-middle (MitM) attacks. Setting verify to ``False``
|
||||
may be useful during local development or testing.
|
||||
to a CA bundle to use. Defaults to ``True``.
|
||||
:param cert: (optional) if String, path to ssl client cert file (.pem).
|
||||
If Tuple, ('cert', 'key') pair.
|
||||
:rtype: requests.Response
|
||||
@@ -588,8 +554,7 @@ class Session(SessionRedirectMixin):
|
||||
r"""Sends a POST request. Returns :class:`Response` object.
|
||||
|
||||
:param url: URL for the new :class:`Request` object.
|
||||
:param data: (optional) Dictionary, list of tuples, bytes, or file-like
|
||||
object to send in the body of the :class:`Request`.
|
||||
:param data: (optional) Dictionary, bytes, or file-like object to send in the body of the :class:`Request`.
|
||||
:param json: (optional) json to send in the body of the :class:`Request`.
|
||||
:param \*\*kwargs: Optional arguments that ``request`` takes.
|
||||
:rtype: requests.Response
|
||||
@@ -601,8 +566,7 @@ class Session(SessionRedirectMixin):
|
||||
r"""Sends a PUT request. Returns :class:`Response` object.
|
||||
|
||||
:param url: URL for the new :class:`Request` object.
|
||||
:param data: (optional) Dictionary, list of tuples, bytes, or file-like
|
||||
object to send in the body of the :class:`Request`.
|
||||
:param data: (optional) Dictionary, bytes, or file-like object to send in the body of the :class:`Request`.
|
||||
:param \*\*kwargs: Optional arguments that ``request`` takes.
|
||||
:rtype: requests.Response
|
||||
"""
|
||||
@@ -613,8 +577,7 @@ class Session(SessionRedirectMixin):
|
||||
r"""Sends a PATCH request. Returns :class:`Response` object.
|
||||
|
||||
:param url: URL for the new :class:`Request` object.
|
||||
:param data: (optional) Dictionary, list of tuples, bytes, or file-like
|
||||
object to send in the body of the :class:`Request`.
|
||||
:param data: (optional) Dictionary, bytes, or file-like object to send in the body of the :class:`Request`.
|
||||
:param \*\*kwargs: Optional arguments that ``request`` takes.
|
||||
:rtype: requests.Response
|
||||
"""
|
||||
@@ -648,7 +611,8 @@ class Session(SessionRedirectMixin):
|
||||
if isinstance(request, Request):
|
||||
raise ValueError('You can only send PreparedRequests.')
|
||||
|
||||
# Set up variables needed for resolve_redirects and dispatching of hooks
|
||||
# Set up variables needed for resolve_redirects and dispatching of
|
||||
# hooks
|
||||
allow_redirects = kwargs.pop('allow_redirects', True)
|
||||
stream = kwargs.get('stream')
|
||||
hooks = request.hooks
|
||||
@@ -666,7 +630,7 @@ class Session(SessionRedirectMixin):
|
||||
elapsed = preferred_clock() - start
|
||||
r.elapsed = timedelta(seconds=elapsed)
|
||||
|
||||
# Response manipulation hooks
|
||||
# Response manipulation hooks.
|
||||
r = dispatch_hook('response', hooks, r, **kwargs)
|
||||
|
||||
# Persist cookies
|
||||
@@ -678,21 +642,15 @@ class Session(SessionRedirectMixin):
|
||||
|
||||
extract_cookies_to_jar(self.cookies, request, r.raw)
|
||||
|
||||
# Resolve redirects if allowed.
|
||||
if allow_redirects:
|
||||
# Redirect resolving generator.
|
||||
gen = self.resolve_redirects(r, request, **kwargs)
|
||||
history = [resp for resp in gen]
|
||||
else:
|
||||
history = []
|
||||
# Redirect resolving generator.
|
||||
gen = self.resolve_redirects(r, request, **kwargs)
|
||||
|
||||
# Shuffle things around if there's history.
|
||||
# Resolve redirects, if allowed.
|
||||
history = [resp for resp in gen] if allow_redirects else []
|
||||
|
||||
# If there is a history, replace ``r`` with the last response
|
||||
if history:
|
||||
# Insert the first (original) request at the start
|
||||
history.insert(0, r)
|
||||
# Get the last request made
|
||||
r = history.pop()
|
||||
r.history = history
|
||||
|
||||
# If redirects aren't being followed, store the response on the Request for Response.next().
|
||||
if not allow_redirects:
|
||||
@@ -712,25 +670,37 @@ class Session(SessionRedirectMixin):
|
||||
|
||||
:rtype: dict
|
||||
"""
|
||||
# Merge all the kwargs except for proxies.
|
||||
stream = merge_setting(stream, self.stream)
|
||||
verify = merge_setting(verify, self.verify)
|
||||
cert = merge_setting(cert, self.cert)
|
||||
# Gather clues from the surrounding environment.
|
||||
# We do this after merging the Session values to make sure we don't
|
||||
# accidentally exclude them.
|
||||
if self.trust_env:
|
||||
# Set environment's proxies.
|
||||
no_proxy = proxies.get('no_proxy') if proxies is not None else None
|
||||
env_proxies = get_environ_proxies(url, no_proxy=no_proxy)
|
||||
for (k, v) in env_proxies.items():
|
||||
proxies.setdefault(k, v)
|
||||
|
||||
# Look for requests environment configuration and be compatible
|
||||
# with cURL.
|
||||
if verify is True or verify is None:
|
||||
verify = (os.environ.get('REQUESTS_CA_BUNDLE') or
|
||||
os.environ.get('CURL_CA_BUNDLE'))
|
||||
os.environ.get('CURL_CA_BUNDLE') or
|
||||
verify)
|
||||
|
||||
# Merge all the kwargs.
|
||||
proxies = merge_setting(proxies, self.proxies)
|
||||
stream = merge_setting(stream, self.stream)
|
||||
verify = merge_setting(verify, self.verify)
|
||||
cert = merge_setting(cert, self.cert)
|
||||
# Now we handle proxies.
|
||||
# Proxies need to be built up backwards. This is because None values
|
||||
# can delete proxy information, which can then be re-added by a more
|
||||
# specific layer. So we begin by getting the environment's proxies,
|
||||
# then add the Session, then add the request.
|
||||
no_proxy = proxies.get('no_proxy') if proxies is not None else None
|
||||
if no_proxy is None:
|
||||
no_proxy = self.proxies.get('no_proxy')
|
||||
|
||||
env_proxies = {}
|
||||
|
||||
if self.trust_env:
|
||||
env_proxies = get_environ_proxies(url, no_proxy=no_proxy) or {}
|
||||
|
||||
new_proxies = merge_setting(self.proxies, env_proxies)
|
||||
proxies = merge_setting(proxies, new_proxies)
|
||||
|
||||
return {'verify': verify, 'proxies': proxies, 'stream': stream,
|
||||
'cert': cert}
|
||||
@@ -743,21 +713,21 @@ class Session(SessionRedirectMixin):
|
||||
"""
|
||||
for (prefix, adapter) in self.adapters.items():
|
||||
|
||||
if url.lower().startswith(prefix.lower()):
|
||||
if url.lower().startswith(prefix):
|
||||
return adapter
|
||||
|
||||
# Nothing matches :-/
|
||||
raise InvalidSchema("No connection adapters were found for {!r}".format(url))
|
||||
raise InvalidScheme("No connection adapters were found for '%s'" % url)
|
||||
|
||||
def close(self):
|
||||
"""Closes all adapters and as such the session"""
|
||||
"""Closes all adapters and, as such, the Session."""
|
||||
for v in self.adapters.values():
|
||||
v.close()
|
||||
|
||||
def mount(self, prefix, adapter):
|
||||
"""Registers a connection adapter to a prefix.
|
||||
|
||||
Adapters are sorted in descending order by prefix length.
|
||||
Adapters are sorted in descending order by key length.
|
||||
"""
|
||||
self.adapters[prefix] = adapter
|
||||
keys_to_move = [k for k in self.adapters if len(k) < len(prefix)]
|
||||
@@ -766,7 +736,7 @@ class Session(SessionRedirectMixin):
|
||||
self.adapters[key] = self.adapters.pop(key)
|
||||
|
||||
def __getstate__(self):
|
||||
state = {attr: getattr(self, attr, None) for attr in self.__attrs__}
|
||||
state = dict((attr, getattr(self, attr, None)) for attr in self.__attrs__)
|
||||
return state
|
||||
|
||||
def __setstate__(self, state):
|
||||
@@ -778,12 +748,7 @@ def session():
|
||||
"""
|
||||
Returns a :class:`Session` for context-management.
|
||||
|
||||
.. deprecated:: 1.0.0
|
||||
|
||||
This method has been deprecated since version 1.0.0 and is only kept for
|
||||
backwards compatibility. New code should use :class:`~requests.sessions.Session`
|
||||
to create a session. This may be removed at a future date.
|
||||
|
||||
:rtype: Session
|
||||
"""
|
||||
|
||||
return Session()
|
||||
|
||||
@@ -1,25 +1,5 @@
|
||||
# -*- coding: utf-8 -*-
|
||||
|
||||
r"""
|
||||
The ``codes`` object defines a mapping from common names for HTTP statuses
|
||||
to their numerical codes, accessible either as attributes or as dictionary
|
||||
items.
|
||||
|
||||
Example::
|
||||
|
||||
>>> import requests
|
||||
>>> requests.codes['temporary_redirect']
|
||||
307
|
||||
>>> requests.codes.teapot
|
||||
418
|
||||
>>> requests.codes['\o/']
|
||||
200
|
||||
|
||||
Some codes have multiple names, and both upper- and lower-case versions of
|
||||
the names are allowed. For example, ``codes.ok``, ``codes.OK``, and
|
||||
``codes.okay`` all correspond to the HTTP status code 200.
|
||||
"""
|
||||
|
||||
from .structures import LookupDict
|
||||
|
||||
_codes = {
|
||||
@@ -104,20 +84,8 @@ _codes = {
|
||||
|
||||
codes = LookupDict(name='status_codes')
|
||||
|
||||
def _init():
|
||||
for code, titles in _codes.items():
|
||||
for title in titles:
|
||||
setattr(codes, title, code)
|
||||
if not title.startswith(('\\', '/')):
|
||||
setattr(codes, title.upper(), code)
|
||||
|
||||
def doc(code):
|
||||
names = ', '.join('``%s``' % n for n in _codes[code])
|
||||
return '* %d: %s' % (code, names)
|
||||
|
||||
global __doc__
|
||||
__doc__ = (__doc__ + '\n' +
|
||||
'\n'.join(doc(code) for code in sorted(_codes))
|
||||
if __doc__ is not None else None)
|
||||
|
||||
_init()
|
||||
for code, titles in _codes.items():
|
||||
for title in titles:
|
||||
setattr(codes, title, code)
|
||||
if not title.startswith(('\\', '/')):
|
||||
setattr(codes, title.upper(), code)
|
||||
|
||||
@@ -7,16 +7,16 @@ requests.structures
|
||||
Data structures that power Requests.
|
||||
"""
|
||||
|
||||
from collections import OrderedDict
|
||||
import collections
|
||||
|
||||
from .compat import Mapping, MutableMapping
|
||||
from .compat import OrderedDict
|
||||
|
||||
|
||||
class CaseInsensitiveDict(MutableMapping):
|
||||
class CaseInsensitiveDict(collections.MutableMapping):
|
||||
"""A case-insensitive ``dict``-like object.
|
||||
|
||||
Implements all methods and operations of
|
||||
``MutableMapping`` as well as dict's ``copy``. Also
|
||||
``collections.MutableMapping`` as well as dict's ``copy``. Also
|
||||
provides ``lower_items``.
|
||||
|
||||
All keys are expected to be strings. The structure remembers the
|
||||
@@ -71,7 +71,7 @@ class CaseInsensitiveDict(MutableMapping):
|
||||
)
|
||||
|
||||
def __eq__(self, other):
|
||||
if isinstance(other, Mapping):
|
||||
if isinstance(other, collections.Mapping):
|
||||
other = CaseInsensitiveDict(other)
|
||||
else:
|
||||
return NotImplemented
|
||||
|
||||
@@ -8,18 +8,17 @@ This module provides utility functions that are used within Requests
|
||||
that are also useful for external consumption.
|
||||
"""
|
||||
|
||||
import cgi
|
||||
import codecs
|
||||
import collections
|
||||
import contextlib
|
||||
import io
|
||||
import os
|
||||
import platform
|
||||
import re
|
||||
import socket
|
||||
import struct
|
||||
import sys
|
||||
import tempfile
|
||||
import warnings
|
||||
import zipfile
|
||||
from collections import OrderedDict
|
||||
|
||||
from .__version__ import __version__
|
||||
from . import certs
|
||||
@@ -27,9 +26,9 @@ from . import certs
|
||||
from ._internal_utils import to_native_string
|
||||
from .compat import parse_http_list as _parse_list_header
|
||||
from .compat import (
|
||||
quote, urlparse, bytes, str, unquote, getproxies,
|
||||
proxy_bypass, urlunparse, basestring, integer_types, is_py3,
|
||||
proxy_bypass_environment, getproxies_environment, Mapping)
|
||||
quote, urlparse, bytes, str, OrderedDict, unquote, getproxies,
|
||||
proxy_bypass, urlunparse, basestring, integer_types, is_py2, is_py3,
|
||||
proxy_bypass_environment, getproxies_environment)
|
||||
from .cookies import cookiejar_from_dict
|
||||
from .structures import CaseInsensitiveDict
|
||||
from .exceptions import (
|
||||
@@ -39,28 +38,20 @@ NETRC_FILES = ('.netrc', '_netrc')
|
||||
|
||||
DEFAULT_CA_BUNDLE_PATH = certs.where()
|
||||
|
||||
DEFAULT_PORTS = {'http': 80, 'https': 443}
|
||||
|
||||
|
||||
if sys.platform == 'win32':
|
||||
if platform.system() == 'Windows':
|
||||
# provide a proxy_bypass version on Windows without DNS lookups
|
||||
|
||||
def proxy_bypass_registry(host):
|
||||
try:
|
||||
if is_py3:
|
||||
import winreg
|
||||
else:
|
||||
import _winreg as winreg
|
||||
except ImportError:
|
||||
return False
|
||||
|
||||
if is_py3:
|
||||
import winreg
|
||||
else:
|
||||
import _winreg as winreg
|
||||
try:
|
||||
internetSettings = winreg.OpenKey(winreg.HKEY_CURRENT_USER,
|
||||
r'Software\Microsoft\Windows\CurrentVersion\Internet Settings')
|
||||
# ProxyEnable could be REG_SZ or REG_DWORD, normalizing it
|
||||
proxyEnable = int(winreg.QueryValueEx(internetSettings,
|
||||
'ProxyEnable')[0])
|
||||
# ProxyOverride is almost always a string
|
||||
proxyEnable = winreg.QueryValueEx(internetSettings,
|
||||
'ProxyEnable')[0]
|
||||
proxyOverride = winreg.QueryValueEx(internetSettings,
|
||||
'ProxyOverride')[0]
|
||||
except OSError:
|
||||
@@ -169,24 +160,18 @@ def super_len(o):
|
||||
def get_netrc_auth(url, raise_errors=False):
|
||||
"""Returns the Requests tuple auth for a given url from netrc."""
|
||||
|
||||
netrc_file = os.environ.get('NETRC')
|
||||
if netrc_file is not None:
|
||||
netrc_locations = (netrc_file,)
|
||||
else:
|
||||
netrc_locations = ('~/{}'.format(f) for f in NETRC_FILES)
|
||||
|
||||
try:
|
||||
from netrc import netrc, NetrcParseError
|
||||
|
||||
netrc_path = None
|
||||
|
||||
for f in netrc_locations:
|
||||
for f in NETRC_FILES:
|
||||
try:
|
||||
loc = os.path.expanduser(f)
|
||||
loc = os.path.expanduser('~/{0}'.format(f))
|
||||
except KeyError:
|
||||
# os.path.expanduser can fail when $HOME is undefined and
|
||||
# getpwuid fails. See https://bugs.python.org/issue20164 &
|
||||
# https://github.com/psf/requests/issues/1846
|
||||
# getpwuid fails. See http://bugs.python.org/issue20164 &
|
||||
# https://github.com/requests/requests/issues/1846
|
||||
return
|
||||
|
||||
if os.path.exists(loc):
|
||||
@@ -218,7 +203,7 @@ def get_netrc_auth(url, raise_errors=False):
|
||||
if raise_errors:
|
||||
raise
|
||||
|
||||
# App Engine hackiness.
|
||||
# AppEngine hackiness.
|
||||
except (ImportError, AttributeError):
|
||||
pass
|
||||
|
||||
@@ -231,38 +216,6 @@ def guess_filename(obj):
|
||||
return os.path.basename(name)
|
||||
|
||||
|
||||
def extract_zipped_paths(path):
|
||||
"""Replace nonexistent paths that look like they refer to a member of a zip
|
||||
archive with the location of an extracted copy of the target, or else
|
||||
just return the provided path unchanged.
|
||||
"""
|
||||
if os.path.exists(path):
|
||||
# this is already a valid path, no need to do anything further
|
||||
return path
|
||||
|
||||
# find the first valid part of the provided path and treat that as a zip archive
|
||||
# assume the rest of the path is the name of a member in the archive
|
||||
archive, member = os.path.split(path)
|
||||
while archive and not os.path.exists(archive):
|
||||
archive, prefix = os.path.split(archive)
|
||||
member = '/'.join([prefix, member])
|
||||
|
||||
if not zipfile.is_zipfile(archive):
|
||||
return path
|
||||
|
||||
zip_file = zipfile.ZipFile(archive)
|
||||
if member not in zip_file.namelist():
|
||||
return path
|
||||
|
||||
# we have a valid zip archive and a valid member of that archive
|
||||
tmp = tempfile.gettempdir()
|
||||
extracted_path = os.path.join(tmp, *member.split('/'))
|
||||
if not os.path.exists(extracted_path):
|
||||
extracted_path = zip_file.extract(member, path=tmp)
|
||||
|
||||
return extracted_path
|
||||
|
||||
|
||||
def from_key_val_list(value):
|
||||
"""Take an object and test to see if it can be represented as a
|
||||
dictionary. Unless it can not be represented as such, return an
|
||||
@@ -273,9 +226,7 @@ def from_key_val_list(value):
|
||||
>>> from_key_val_list([('key', 'val')])
|
||||
OrderedDict([('key', 'val')])
|
||||
>>> from_key_val_list('string')
|
||||
Traceback (most recent call last):
|
||||
...
|
||||
ValueError: cannot encode objects that are not 2-tuples
|
||||
ValueError: need more than 1 value to unpack
|
||||
>>> from_key_val_list({'key': 'val'})
|
||||
OrderedDict([('key', 'val')])
|
||||
|
||||
@@ -301,9 +252,7 @@ def to_key_val_list(value):
|
||||
>>> to_key_val_list({'key': 'val'})
|
||||
[('key', 'val')]
|
||||
>>> to_key_val_list('string')
|
||||
Traceback (most recent call last):
|
||||
...
|
||||
ValueError: cannot encode objects that are not 2-tuples
|
||||
ValueError: cannot encode objects that are not 2-tuples.
|
||||
|
||||
:rtype: list
|
||||
"""
|
||||
@@ -313,7 +262,7 @@ def to_key_val_list(value):
|
||||
if isinstance(value, (str, bytes, bool, int)):
|
||||
raise ValueError('cannot encode objects that are not 2-tuples')
|
||||
|
||||
if isinstance(value, Mapping):
|
||||
if isinstance(value, collections.Mapping):
|
||||
value = value.items()
|
||||
|
||||
return list(value)
|
||||
@@ -458,31 +407,6 @@ def get_encodings_from_content(content):
|
||||
xml_re.findall(content))
|
||||
|
||||
|
||||
def _parse_content_type_header(header):
|
||||
"""Returns content type and parameters from given header
|
||||
|
||||
:param header: string
|
||||
:return: tuple containing content type and dictionary of
|
||||
parameters
|
||||
"""
|
||||
|
||||
tokens = header.split(';')
|
||||
content_type, params = tokens[0].strip(), tokens[1:]
|
||||
params_dict = {}
|
||||
items_to_strip = "\"' "
|
||||
|
||||
for param in params:
|
||||
param = param.strip()
|
||||
if param:
|
||||
key, value = param, True
|
||||
index_of_equals = param.find("=")
|
||||
if index_of_equals != -1:
|
||||
key = param[:index_of_equals].strip(items_to_strip)
|
||||
value = param[index_of_equals + 1:].strip(items_to_strip)
|
||||
params_dict[key.lower()] = value
|
||||
return content_type, params_dict
|
||||
|
||||
|
||||
def get_encoding_from_headers(headers):
|
||||
"""Returns encodings from given HTTP Header Dict.
|
||||
|
||||
@@ -495,7 +419,7 @@ def get_encoding_from_headers(headers):
|
||||
if not content_type:
|
||||
return None
|
||||
|
||||
content_type, params = _parse_content_type_header(content_type)
|
||||
content_type, params = cgi.parse_header(content_type)
|
||||
|
||||
if 'charset' in params:
|
||||
return params['charset'].strip("'\"")
|
||||
@@ -503,19 +427,10 @@ def get_encoding_from_headers(headers):
|
||||
if 'text' in content_type:
|
||||
return 'ISO-8859-1'
|
||||
|
||||
if 'application/json' in content_type:
|
||||
# Assume UTF-8 based on RFC 4627: https://www.ietf.org/rfc/rfc4627.txt since the charset was unset
|
||||
return 'utf-8'
|
||||
|
||||
|
||||
def stream_decode_response_unicode(iterator, r):
|
||||
"""Stream decodes a iterator."""
|
||||
|
||||
if r.encoding is None:
|
||||
for item in iterator:
|
||||
yield item
|
||||
return
|
||||
|
||||
decoder = codecs.getincrementaldecoder(r.encoding)(errors='replace')
|
||||
for chunk in iterator:
|
||||
rv = decoder.decode(chunk)
|
||||
@@ -583,7 +498,26 @@ def unquote_unreserved(uri):
|
||||
|
||||
:rtype: str
|
||||
"""
|
||||
parts = uri.split('%')
|
||||
# This convert function is used to optionally convert the output of `chr`.
|
||||
# In Python 3, `chr` returns a unicode string, while in Python 2 it returns
|
||||
# a bytestring. Here we deal with that by optionally converting.
|
||||
def convert(is_bytes, c):
|
||||
if is_py2 and not is_bytes:
|
||||
return c.decode('ascii')
|
||||
elif is_py3 and is_bytes:
|
||||
return c.encode('ascii')
|
||||
else:
|
||||
return c
|
||||
|
||||
# Handle both bytestrings and unicode strings.
|
||||
is_bytes = isinstance(uri, bytes)
|
||||
splitchar = u'%'
|
||||
base = u''
|
||||
if is_bytes:
|
||||
splitchar = splitchar.encode('ascii')
|
||||
base = base.encode('ascii')
|
||||
|
||||
parts = uri.split(splitchar)
|
||||
for i in range(1, len(parts)):
|
||||
h = parts[i][0:2]
|
||||
if len(h) == 2 and h.isalnum():
|
||||
@@ -593,12 +527,12 @@ def unquote_unreserved(uri):
|
||||
raise InvalidURL("Invalid percent-escape sequence: '%s'" % h)
|
||||
|
||||
if c in UNRESERVED_SET:
|
||||
parts[i] = c + parts[i][2:]
|
||||
parts[i] = convert(is_bytes, c) + parts[i][2:]
|
||||
else:
|
||||
parts[i] = '%' + parts[i]
|
||||
parts[i] = splitchar + parts[i]
|
||||
else:
|
||||
parts[i] = '%' + parts[i]
|
||||
return ''.join(parts)
|
||||
parts[i] = splitchar + parts[i]
|
||||
return base.join(parts)
|
||||
|
||||
|
||||
def requote_uri(uri):
|
||||
@@ -692,18 +626,18 @@ def set_environ(env_name, value):
|
||||
the environment variable 'env_name'.
|
||||
|
||||
If 'value' is None, do nothing"""
|
||||
value_changed = value is not None
|
||||
if value_changed:
|
||||
if value is not None:
|
||||
old_value = os.environ.get(env_name)
|
||||
os.environ[env_name] = value
|
||||
try:
|
||||
yield
|
||||
finally:
|
||||
if value_changed:
|
||||
if old_value is None:
|
||||
del os.environ[env_name]
|
||||
else:
|
||||
os.environ[env_name] = old_value
|
||||
if value is None:
|
||||
return
|
||||
if old_value is None:
|
||||
del os.environ[env_name]
|
||||
else:
|
||||
os.environ[env_name] = old_value
|
||||
|
||||
|
||||
def should_bypass_proxies(url, no_proxy):
|
||||
@@ -712,8 +646,6 @@ def should_bypass_proxies(url, no_proxy):
|
||||
|
||||
:rtype: bool
|
||||
"""
|
||||
# Prioritize lowercase environment variables over uppercase
|
||||
# to keep a consistent behaviour with other http projects (curl, wget).
|
||||
get_proxy = lambda k: os.environ.get(k) or os.environ.get(k.upper())
|
||||
|
||||
# First check whether no_proxy is defined. If it is, check that the URL
|
||||
@@ -721,43 +653,41 @@ def should_bypass_proxies(url, no_proxy):
|
||||
no_proxy_arg = no_proxy
|
||||
if no_proxy is None:
|
||||
no_proxy = get_proxy('no_proxy')
|
||||
parsed = urlparse(url)
|
||||
|
||||
if parsed.hostname is None:
|
||||
# URLs don't always have hostnames, e.g. file:/// urls.
|
||||
return True
|
||||
netloc = urlparse(url).netloc
|
||||
|
||||
if no_proxy:
|
||||
# We need to check whether we match here. We need to see if we match
|
||||
# the end of the hostname, both with and without the port.
|
||||
# the end of the netloc, both with and without the port.
|
||||
no_proxy = (
|
||||
host for host in no_proxy.replace(' ', '').split(',') if host
|
||||
)
|
||||
|
||||
if is_ipv4_address(parsed.hostname):
|
||||
ip = netloc.split(':')[0]
|
||||
if is_ipv4_address(ip):
|
||||
for proxy_ip in no_proxy:
|
||||
if is_valid_cidr(proxy_ip):
|
||||
if address_in_network(parsed.hostname, proxy_ip):
|
||||
if address_in_network(ip, proxy_ip):
|
||||
return True
|
||||
elif parsed.hostname == proxy_ip:
|
||||
elif ip == proxy_ip:
|
||||
# If no_proxy ip was defined in plain IP notation instead of cidr notation &
|
||||
# matches the IP of the index
|
||||
return True
|
||||
else:
|
||||
host_with_port = parsed.hostname
|
||||
if parsed.port:
|
||||
host_with_port += ':{}'.format(parsed.port)
|
||||
|
||||
for host in no_proxy:
|
||||
if parsed.hostname.endswith(host) or host_with_port.endswith(host):
|
||||
if netloc.endswith(host) or netloc.split(':')[0].endswith(host):
|
||||
# The URL does match something in no_proxy, so we don't want
|
||||
# to apply the proxies on this URL.
|
||||
return True
|
||||
|
||||
# If the system proxy settings indicate that this URL should be bypassed,
|
||||
# don't proxy.
|
||||
# The proxy_bypass function is incredibly buggy on OS X in early versions
|
||||
# of Python 2.6, so allow this call to fail. Only catch the specific
|
||||
# exceptions we've seen, though: this call failing in other ways can reveal
|
||||
# legitimate problems.
|
||||
with set_environ('no_proxy', no_proxy_arg):
|
||||
# parsed.hostname can be `None` in cases such as a file URI.
|
||||
try:
|
||||
bypass = proxy_bypass(parsed.hostname)
|
||||
bypass = proxy_bypass(netloc)
|
||||
except (TypeError, socket.gaierror):
|
||||
bypass = False
|
||||
|
||||
@@ -827,7 +757,7 @@ def default_headers():
|
||||
|
||||
|
||||
def parse_header_links(value):
|
||||
"""Return a list of parsed link headers proxies.
|
||||
"""Return a dict of parsed link headers proxies.
|
||||
|
||||
i.e. Link: <http:/.../front.jpeg>; rel=front; type="image/jpeg",<http://.../back.jpeg>; rel=back;type="image/jpeg"
|
||||
|
||||
@@ -838,10 +768,6 @@ def parse_header_links(value):
|
||||
|
||||
replace_chars = ' \'"'
|
||||
|
||||
value = value.strip(replace_chars)
|
||||
if not value:
|
||||
return links
|
||||
|
||||
for val in re.split(', *<', value):
|
||||
try:
|
||||
url, params = val.split(';', 1)
|
||||
@@ -863,6 +789,19 @@ def parse_header_links(value):
|
||||
return links
|
||||
|
||||
|
||||
def is_valid_location(response):
|
||||
"""Verify that multiple Location headers weren't
|
||||
returned from the last response.
|
||||
"""
|
||||
headers = getattr(response.raw, 'headers', None)
|
||||
if headers is not None:
|
||||
getlist = getattr(headers, 'getlist', None)
|
||||
if getlist is not None:
|
||||
return len(getlist('location')) <= 1
|
||||
# If response.raw isn't urllib3-like we can't reliably check this
|
||||
return True
|
||||
|
||||
|
||||
# Null bytes; no need to recreate these on each call to guess_json_utf
|
||||
_null = '\x00'.encode('ascii') # encoding to ASCII for Python 3
|
||||
_null2 = _null * 2
|
||||
@@ -947,8 +886,6 @@ def check_header_validity(header):
|
||||
:param header: tuple, in the format (name, value).
|
||||
"""
|
||||
name, value = header
|
||||
if value is None:
|
||||
return
|
||||
|
||||
if isinstance(value, bytes):
|
||||
pat = _CLEAN_HEADER_REGEX_BYTE
|
||||
@@ -958,8 +895,8 @@ def check_header_validity(header):
|
||||
if not pat.match(value):
|
||||
raise InvalidHeader("Invalid return character or leading space in header: %s" % name)
|
||||
except TypeError:
|
||||
raise InvalidHeader("Value for header {%s: %s} must be of type str or "
|
||||
"bytes, not %s" % (name, value, type(value)))
|
||||
raise InvalidHeader("Header value %s must be of type str or bytes, "
|
||||
"not %s" % (value, type(value)))
|
||||
|
||||
|
||||
def urldefragauth(url):
|
||||
@@ -992,3 +929,10 @@ def rewind_body(prepared_request):
|
||||
"body for redirect.")
|
||||
else:
|
||||
raise UnrewindableBodyError("Unable to rewind request body for redirect.")
|
||||
|
||||
|
||||
def is_stream(data):
|
||||
"""Given data, determines if it should be sent as a stream."""
|
||||
is_iterable = getattr(data, '__iter__', False)
|
||||
is_io_type = not isinstance(data, (basestring, list, tuple, collections.Mapping))
|
||||
return is_iterable and is_io_type
|
||||
|
||||
@@ -1,6 +0,0 @@
|
||||
pytest>=2.8.0,<=3.10.1
|
||||
pytest-cov
|
||||
pytest-httpbin<1.0
|
||||
pytest-mock==2.0.0
|
||||
httpbin==0.7.0
|
||||
wheel
|
||||
16
requirements.txt
Normal file
@@ -0,0 +1,16 @@
|
||||
-e .[socks]
|
||||
pytest>=2.8.0
|
||||
codecov
|
||||
pytest-httpbin==0.0.7
|
||||
pytest-mock
|
||||
pytest-cov
|
||||
pytest-xdist
|
||||
alabaster
|
||||
readme_renderer
|
||||
Sphinx<=1.5.5
|
||||
PySocks
|
||||
setuptools>=18.5
|
||||
docutils
|
||||
flake8
|
||||
tox
|
||||
detox
|
||||
47
setup.py
@@ -1,5 +1,5 @@
|
||||
#!/usr/bin/env python
|
||||
# Learn more: https://github.com/kennethreitz/setup.py
|
||||
|
||||
import os
|
||||
import re
|
||||
import sys
|
||||
@@ -42,71 +42,60 @@ if sys.argv[-1] == 'publish':
|
||||
packages = ['requests']
|
||||
|
||||
requires = [
|
||||
'chardet>=3.0.2,<4',
|
||||
'idna>=2.5,<3',
|
||||
'urllib3>=1.21.1,<1.27',
|
||||
'chardet>=3.0.2,<3.1.0',
|
||||
'idna>=2.5,<2.6',
|
||||
'urllib3>=1.21.1,<1.22',
|
||||
'certifi>=2017.4.17'
|
||||
|
||||
]
|
||||
test_requirements = [
|
||||
'pytest-httpbin==0.0.7',
|
||||
'pytest-cov',
|
||||
'pytest-mock',
|
||||
'pytest-xdist',
|
||||
'PySocks>=1.5.6, !=1.5.7',
|
||||
'pytest>=3'
|
||||
]
|
||||
test_requirements = ['pytest-httpbin==0.0.7', 'pytest-cov', 'pytest-mock', 'pytest-xdist', 'PySocks>=1.5.6, !=1.5.7', 'pytest>=2.8.0']
|
||||
|
||||
about = {}
|
||||
with open(os.path.join(here, 'requests', '__version__.py'), 'r', 'utf-8') as f:
|
||||
exec(f.read(), about)
|
||||
|
||||
with open('README.md', 'r', 'utf-8') as f:
|
||||
with open('README.rst', 'r', 'utf-8') as f:
|
||||
readme = f.read()
|
||||
with open('HISTORY.rst', 'r', 'utf-8') as f:
|
||||
history = f.read()
|
||||
|
||||
setup(
|
||||
name=about['__title__'],
|
||||
version=about['__version__'],
|
||||
description=about['__description__'],
|
||||
long_description=readme,
|
||||
long_description_content_type='text/markdown',
|
||||
long_description=readme + '\n\n' + history,
|
||||
author=about['__author__'],
|
||||
author_email=about['__author_email__'],
|
||||
url=about['__url__'],
|
||||
packages=packages,
|
||||
package_data={'': ['LICENSE', 'NOTICE']},
|
||||
package_data={'': ['LICENSE', 'NOTICE'], 'requests': ['*.pem']},
|
||||
package_dir={'requests': 'requests'},
|
||||
include_package_data=True,
|
||||
python_requires=">=2.7, !=3.0.*, !=3.1.*, !=3.2.*, !=3.3.*, !=3.4.*",
|
||||
install_requires=requires,
|
||||
license=about['__license__'],
|
||||
zip_safe=False,
|
||||
classifiers=[
|
||||
classifiers=(
|
||||
'Development Status :: 5 - Production/Stable',
|
||||
'Intended Audience :: Developers',
|
||||
'Natural Language :: English',
|
||||
'License :: OSI Approved :: Apache Software License',
|
||||
'Programming Language :: Python',
|
||||
'Programming Language :: Python :: 2',
|
||||
'Programming Language :: Python :: 2.6',
|
||||
'Programming Language :: Python :: 2.7',
|
||||
'Programming Language :: Python :: 3',
|
||||
'Programming Language :: Python :: 3.3',
|
||||
'Programming Language :: Python :: 3.4',
|
||||
'Programming Language :: Python :: 3.5',
|
||||
'Programming Language :: Python :: 3.6',
|
||||
'Programming Language :: Python :: 3.7',
|
||||
'Programming Language :: Python :: 3.8',
|
||||
'Programming Language :: Python :: 3.9',
|
||||
'Programming Language :: Python :: Implementation :: CPython',
|
||||
'Programming Language :: Python :: Implementation :: PyPy'
|
||||
],
|
||||
),
|
||||
cmdclass={'test': PyTest},
|
||||
tests_require=test_requirements,
|
||||
extras_require={
|
||||
'security': ['pyOpenSSL >= 0.14', 'cryptography>=1.3.4'],
|
||||
'security': ['pyOpenSSL>=0.14', 'cryptography>=1.3.4', 'idna>=2.0.0'],
|
||||
'socks': ['PySocks>=1.5.6, !=1.5.7'],
|
||||
'socks:sys_platform == "win32" and python_version == "2.7"': ['win_inet_pton'],
|
||||
},
|
||||
project_urls={
|
||||
'Documentation': 'https://requests.readthedocs.io',
|
||||
'Source': 'https://github.com/psf/requests',
|
||||
'socks:sys_platform == "win32" and (python_version == "2.7" or python_version == "2.6")': ['win_inet_pton'],
|
||||
},
|
||||
)
|
||||
|
||||
|
||||
@@ -1,31 +0,0 @@
|
||||
# -*- encoding: utf-8
|
||||
|
||||
import sys
|
||||
|
||||
import pytest
|
||||
|
||||
from requests.help import info
|
||||
|
||||
|
||||
def test_system_ssl():
|
||||
"""Verify we're actually setting system_ssl when it should be available."""
|
||||
assert info()['system_ssl']['version'] != ''
|
||||
|
||||
|
||||
class VersionedPackage(object):
|
||||
def __init__(self, version):
|
||||
self.__version__ = version
|
||||
|
||||
|
||||
def test_idna_without_version_attribute(mocker):
|
||||
"""Older versions of IDNA don't provide a __version__ attribute, verify
|
||||
that if we have such a package, we don't blow up.
|
||||
"""
|
||||
mocker.patch('requests.help.idna', new=None)
|
||||
assert info()['idna'] == {'version': ''}
|
||||
|
||||
|
||||
def test_idna_with_version_attribute(mocker):
|
||||
"""Verify we're actually setting idna version when it should be available."""
|
||||
mocker.patch('requests.help.idna', new=VersionedPackage('2.6'))
|
||||
assert info()['idna'] == {'version': '2.6'}
|
||||
113
tests/test_lowlevel.py
Normal file → Executable file
@@ -16,19 +16,36 @@ def test_chunked_upload():
|
||||
data = iter([b'a', b'b', b'c'])
|
||||
|
||||
with server as (host, port):
|
||||
url = 'http://{}:{}/'.format(host, port)
|
||||
url = 'http://{0}:{1}/'.format(host, port)
|
||||
r = requests.post(url, data=data, stream=True)
|
||||
close_server.set() # release server block
|
||||
|
||||
assert r.status_code == 200
|
||||
assert r.request.headers['Transfer-Encoding'] == 'chunked'
|
||||
|
||||
def test_incorrect_content_length():
|
||||
"""Test ConnectionError raised for incomplete responses"""
|
||||
close_server = threading.Event()
|
||||
server = Server.text_response_server(
|
||||
"HTTP/1.1 200 OK\r\n" +
|
||||
"Content-Length: 50\r\n\r\n" +
|
||||
"Hello World."
|
||||
)
|
||||
with server as (host, port):
|
||||
url = 'http://{0}:{1}/'.format(host, port)
|
||||
r = requests.Request('GET', url).prepare()
|
||||
s = requests.Session()
|
||||
with pytest.raises(requests.exceptions.ConnectionError) as e:
|
||||
resp = s.send(r)
|
||||
assert "12 bytes read, 38 more expected" in str(e)
|
||||
close_server.set() # release server block
|
||||
|
||||
|
||||
def test_digestauth_401_count_reset_on_redirect():
|
||||
"""Ensure we correctly reset num_401_calls after a successful digest auth,
|
||||
followed by a 302 redirect to another digest auth prompt.
|
||||
|
||||
See https://github.com/psf/requests/issues/1979.
|
||||
See https://github.com/requests/requests/issues/1979.
|
||||
"""
|
||||
text_401 = (b'HTTP/1.1 401 UNAUTHORIZED\r\n'
|
||||
b'Content-Length: 0\r\n'
|
||||
@@ -77,7 +94,7 @@ def test_digestauth_401_count_reset_on_redirect():
|
||||
server = Server(digest_response_handler, wait_to_close_event=close_server)
|
||||
|
||||
with server as (host, port):
|
||||
url = 'http://{}:{}/'.format(host, port)
|
||||
url = 'http://{0}:{1}/'.format(host, port)
|
||||
r = requests.get(url, auth=auth)
|
||||
# Verify server succeeded in authenticating.
|
||||
assert r.status_code == 200
|
||||
@@ -127,7 +144,7 @@ def test_digestauth_401_only_sent_once():
|
||||
server = Server(digest_failed_response_handler, wait_to_close_event=close_server)
|
||||
|
||||
with server as (host, port):
|
||||
url = 'http://{}:{}/'.format(host, port)
|
||||
url = 'http://{0}:{1}/'.format(host, port)
|
||||
r = requests.get(url, auth=auth)
|
||||
# Verify server didn't authenticate us.
|
||||
assert r.status_code == 401
|
||||
@@ -138,7 +155,7 @@ def test_digestauth_401_only_sent_once():
|
||||
def test_digestauth_only_on_4xx():
|
||||
"""Ensure we only send digestauth on 4xx challenges.
|
||||
|
||||
See https://github.com/psf/requests/issues/3772.
|
||||
See https://github.com/requests/requests/issues/3772.
|
||||
"""
|
||||
text_200_chal = (b'HTTP/1.1 200 OK\r\n'
|
||||
b'Content-Length: 0\r\n'
|
||||
@@ -164,7 +181,7 @@ def test_digestauth_only_on_4xx():
|
||||
server = Server(digest_response_handler, wait_to_close_event=close_server)
|
||||
|
||||
with server as (host, port):
|
||||
url = 'http://{}:{}/'.format(host, port)
|
||||
url = 'http://{0}:{1}/'.format(host, port)
|
||||
r = requests.get(url, auth=auth)
|
||||
# Verify server didn't receive auth from us.
|
||||
assert r.status_code == 200
|
||||
@@ -181,17 +198,17 @@ _schemes_by_var_prefix = [
|
||||
_proxy_combos = []
|
||||
for prefix, schemes in _schemes_by_var_prefix:
|
||||
for scheme in schemes:
|
||||
_proxy_combos.append(("{}_proxy".format(prefix), scheme))
|
||||
_proxy_combos.append(("{0}_proxy".format(prefix), scheme))
|
||||
|
||||
_proxy_combos += [(var.upper(), scheme) for var, scheme in _proxy_combos]
|
||||
|
||||
|
||||
@pytest.mark.parametrize("var,scheme", _proxy_combos)
|
||||
def test_use_proxy_from_environment(httpbin, var, scheme):
|
||||
url = "{}://httpbin.org".format(scheme)
|
||||
url = "{0}://httpbin.org".format(scheme)
|
||||
fake_proxy = Server() # do nothing with the requests; just close the socket
|
||||
with fake_proxy as (host, port):
|
||||
proxy_url = "socks5://{}:{}".format(host, port)
|
||||
proxy_url = "socks5://{0}:{1}".format(host, port)
|
||||
kwargs = {var: proxy_url}
|
||||
with override_environ(**kwargs):
|
||||
# fake proxy's lack of response will cause a ConnectionError
|
||||
@@ -212,7 +229,7 @@ def test_redirect_rfc1808_to_non_ascii_location():
|
||||
|
||||
def redirect_resp_handler(sock):
|
||||
consume_socket_content(sock, timeout=0.5)
|
||||
location = u'//{}:{}/{}'.format(host, port, path)
|
||||
location = u'//{0}:{1}/{2}'.format(host, port, path)
|
||||
sock.send(
|
||||
b'HTTP/1.1 301 Moved Permanently\r\n'
|
||||
b'Content-Length: 0\r\n'
|
||||
@@ -226,84 +243,12 @@ def test_redirect_rfc1808_to_non_ascii_location():
|
||||
server = Server(redirect_resp_handler, wait_to_close_event=close_server)
|
||||
|
||||
with server as (host, port):
|
||||
url = u'http://{}:{}'.format(host, port)
|
||||
url = u'http://{0}:{1}'.format(host, port)
|
||||
r = requests.get(url=url, allow_redirects=True)
|
||||
assert r.status_code == 200
|
||||
assert len(r.history) == 1
|
||||
assert r.history[0].status_code == 301
|
||||
assert redirect_request[0].startswith(b'GET /' + expected_path + b' HTTP/1.1')
|
||||
assert r.url == u'{}/{}'.format(url, expected_path.decode('ascii'))
|
||||
|
||||
close_server.set()
|
||||
|
||||
def test_fragment_not_sent_with_request():
|
||||
"""Verify that the fragment portion of a URI isn't sent to the server."""
|
||||
def response_handler(sock):
|
||||
req = consume_socket_content(sock, timeout=0.5)
|
||||
sock.send(
|
||||
b'HTTP/1.1 200 OK\r\n'
|
||||
b'Content-Length: '+bytes(len(req))+b'\r\n'
|
||||
b'\r\n'+req
|
||||
)
|
||||
|
||||
close_server = threading.Event()
|
||||
server = Server(response_handler, wait_to_close_event=close_server)
|
||||
|
||||
with server as (host, port):
|
||||
url = 'http://{}:{}/path/to/thing/#view=edit&token=hunter2'.format(host, port)
|
||||
r = requests.get(url)
|
||||
raw_request = r.content
|
||||
|
||||
assert r.status_code == 200
|
||||
headers, body = raw_request.split(b'\r\n\r\n', 1)
|
||||
status_line, headers = headers.split(b'\r\n', 1)
|
||||
|
||||
assert status_line == b'GET /path/to/thing/ HTTP/1.1'
|
||||
for frag in (b'view', b'edit', b'token', b'hunter2'):
|
||||
assert frag not in headers
|
||||
assert frag not in body
|
||||
|
||||
close_server.set()
|
||||
|
||||
def test_fragment_update_on_redirect():
|
||||
"""Verify we only append previous fragment if one doesn't exist on new
|
||||
location. If a new fragment is encountered in a Location header, it should
|
||||
be added to all subsequent requests.
|
||||
"""
|
||||
|
||||
def response_handler(sock):
|
||||
consume_socket_content(sock, timeout=0.5)
|
||||
sock.send(
|
||||
b'HTTP/1.1 302 FOUND\r\n'
|
||||
b'Content-Length: 0\r\n'
|
||||
b'Location: /get#relevant-section\r\n\r\n'
|
||||
)
|
||||
consume_socket_content(sock, timeout=0.5)
|
||||
sock.send(
|
||||
b'HTTP/1.1 302 FOUND\r\n'
|
||||
b'Content-Length: 0\r\n'
|
||||
b'Location: /final-url/\r\n\r\n'
|
||||
)
|
||||
consume_socket_content(sock, timeout=0.5)
|
||||
sock.send(
|
||||
b'HTTP/1.1 200 OK\r\n\r\n'
|
||||
)
|
||||
|
||||
close_server = threading.Event()
|
||||
server = Server(response_handler, wait_to_close_event=close_server)
|
||||
|
||||
with server as (host, port):
|
||||
url = 'http://{}:{}/path/to/thing/#view=edit&token=hunter2'.format(host, port)
|
||||
r = requests.get(url)
|
||||
raw_request = r.content
|
||||
|
||||
assert r.status_code == 200
|
||||
assert len(r.history) == 2
|
||||
assert r.history[0].request.url == url
|
||||
|
||||
# Verify we haven't overwritten the location with our previous fragment.
|
||||
assert r.history[1].request.url == 'http://{}:{}/get#relevant-section'.format(host, port)
|
||||
# Verify previous fragment is used and not the original.
|
||||
assert r.url == 'http://{}:{}/final-url/#relevant-section'.format(host, port)
|
||||
assert r.url == u'{0}/{1}'.format(url, expected_path.decode('ascii'))
|
||||
|
||||
close_server.set()
|
||||
|
||||
826
tests/test_requests.py
Normal file → Executable file
@@ -50,7 +50,7 @@ class TestTestServer:
|
||||
)
|
||||
|
||||
with server as (host, port):
|
||||
r = requests.get('http://{}:{}'.format(host, port))
|
||||
r = requests.get('http://{0}:{1}'.format(host, port))
|
||||
|
||||
assert r.status_code == 200
|
||||
assert r.text == u'roflol'
|
||||
@@ -59,7 +59,7 @@ class TestTestServer:
|
||||
def test_basic_response(self):
|
||||
"""the basic response server returns an empty http response"""
|
||||
with Server.basic_response_server() as (host, port):
|
||||
r = requests.get('http://{}:{}'.format(host, port))
|
||||
r = requests.get('http://{0}:{1}'.format(host, port))
|
||||
assert r.status_code == 200
|
||||
assert r.text == u''
|
||||
assert r.headers['Content-Length'] == '0'
|
||||
@@ -83,7 +83,7 @@ class TestTestServer:
|
||||
server = Server.basic_response_server(requests_to_handle=requests_to_handle)
|
||||
|
||||
with server as (host, port):
|
||||
server_url = 'http://{}:{}'.format(host, port)
|
||||
server_url = 'http://{0}:{1}'.format(host, port)
|
||||
for _ in range(requests_to_handle):
|
||||
r = requests.get(server_url)
|
||||
assert r.status_code == 200
|
||||
|
||||
@@ -1,19 +1,15 @@
|
||||
# -*- coding: utf-8 -*-
|
||||
|
||||
import os
|
||||
import copy
|
||||
import filecmp
|
||||
from io import BytesIO
|
||||
import zipfile
|
||||
from collections import deque
|
||||
|
||||
import pytest
|
||||
from requests import compat
|
||||
from requests.cookies import RequestsCookieJar
|
||||
from requests.structures import CaseInsensitiveDict
|
||||
from requests.utils import (
|
||||
address_in_network, dotted_netmask, extract_zipped_paths,
|
||||
get_auth_from_url, _parse_content_type_header, get_encoding_from_headers,
|
||||
address_in_network, dotted_netmask,
|
||||
get_auth_from_url, get_encoding_from_headers,
|
||||
get_encodings_from_content, get_environ_proxies,
|
||||
guess_filename, guess_json_utf, is_ipv4_address,
|
||||
is_valid_cidr, iter_slices, parse_dict_header,
|
||||
@@ -21,7 +17,7 @@ from requests.utils import (
|
||||
requote_uri, select_proxy, should_bypass_proxies, super_len,
|
||||
to_key_val_list, to_native_string,
|
||||
unquote_header_value, unquote_unreserved,
|
||||
urldefragauth, add_dict_to_cookiejar, set_environ)
|
||||
urldefragauth, add_dict_to_cookiejar)
|
||||
from requests._internal_utils import unicode_is_ascii
|
||||
|
||||
from .compat import StringIO, cStringIO
|
||||
@@ -33,8 +29,7 @@ class TestSuperLen:
|
||||
'stream, value', (
|
||||
(StringIO.StringIO, 'Test'),
|
||||
(BytesIO, b'Test'),
|
||||
pytest.param(cStringIO, 'Test',
|
||||
marks=pytest.mark.skipif('cStringIO is None')),
|
||||
pytest.mark.skipif('cStringIO is None')((cStringIO, 'Test')),
|
||||
))
|
||||
def test_io_streams(self, stream, value):
|
||||
"""Ensures that we properly deal with different kinds of IO streams."""
|
||||
@@ -260,32 +255,6 @@ class TestGuessFilename:
|
||||
assert isinstance(result, expected_type)
|
||||
|
||||
|
||||
class TestExtractZippedPaths:
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
'path', (
|
||||
'/',
|
||||
__file__,
|
||||
pytest.__file__,
|
||||
'/etc/invalid/location',
|
||||
))
|
||||
def test_unzipped_paths_unchanged(self, path):
|
||||
assert path == extract_zipped_paths(path)
|
||||
|
||||
def test_zipped_paths_extracted(self, tmpdir):
|
||||
zipped_py = tmpdir.join('test.zip')
|
||||
with zipfile.ZipFile(zipped_py.strpath, 'w') as f:
|
||||
f.write(__file__)
|
||||
|
||||
_, name = os.path.splitdrive(__file__)
|
||||
zipped_path = os.path.join(zipped_py.strpath, name.lstrip(r'\/'))
|
||||
extracted_path = extract_zipped_paths(zipped_path)
|
||||
|
||||
assert extracted_path != zipped_path
|
||||
assert os.path.exists(extracted_path)
|
||||
assert filecmp.cmp(extracted_path, __file__)
|
||||
|
||||
|
||||
class TestContentEncodingDetection:
|
||||
|
||||
def test_none(self):
|
||||
@@ -398,7 +367,7 @@ def test_get_auth_from_url(url, auth):
|
||||
),
|
||||
))
|
||||
def test_requote_uri_with_unquoted_percents(uri, expected):
|
||||
"""See: https://github.com/psf/requests/issues/2356"""
|
||||
"""See: https://github.com/requests/requests/issues/2356"""
|
||||
assert requote_uri(uri) == expected
|
||||
|
||||
|
||||
@@ -471,49 +440,6 @@ def test_parse_dict_header(value, expected):
|
||||
assert parse_dict_header(value) == expected
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
'value, expected', (
|
||||
(
|
||||
'application/xml',
|
||||
('application/xml', {})
|
||||
),
|
||||
(
|
||||
'application/json ; charset=utf-8',
|
||||
('application/json', {'charset': 'utf-8'})
|
||||
),
|
||||
(
|
||||
'application/json ; Charset=utf-8',
|
||||
('application/json', {'charset': 'utf-8'})
|
||||
),
|
||||
(
|
||||
'text/plain',
|
||||
('text/plain', {})
|
||||
),
|
||||
(
|
||||
'multipart/form-data; boundary = something ; boundary2=\'something_else\' ; no_equals ',
|
||||
('multipart/form-data', {'boundary': 'something', 'boundary2': 'something_else', 'no_equals': True})
|
||||
),
|
||||
(
|
||||
'multipart/form-data; boundary = something ; boundary2="something_else" ; no_equals ',
|
||||
('multipart/form-data', {'boundary': 'something', 'boundary2': 'something_else', 'no_equals': True})
|
||||
),
|
||||
(
|
||||
'multipart/form-data; boundary = something ; \'boundary2=something_else\' ; no_equals ',
|
||||
('multipart/form-data', {'boundary': 'something', 'boundary2': 'something_else', 'no_equals': True})
|
||||
),
|
||||
(
|
||||
'multipart/form-data; boundary = something ; "boundary2=something_else" ; no_equals ',
|
||||
('multipart/form-data', {'boundary': 'something', 'boundary2': 'something_else', 'no_equals': True})
|
||||
),
|
||||
(
|
||||
'application/json ; ; ',
|
||||
('application/json', {})
|
||||
)
|
||||
))
|
||||
def test__parse_content_type_header(value, expected):
|
||||
assert _parse_content_type_header(value) == expected
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
'value, expected', (
|
||||
(
|
||||
@@ -571,10 +497,6 @@ def test_iter_slices(value, length):
|
||||
{'url': 'http://.../back.jpeg'}
|
||||
]
|
||||
),
|
||||
(
|
||||
'',
|
||||
[]
|
||||
),
|
||||
))
|
||||
def test_parse_header_links(value, expected):
|
||||
assert parse_header_links(value) == expected
|
||||
@@ -619,41 +541,19 @@ def test_urldefragauth(url, expected):
|
||||
('http://172.16.1.1/', True),
|
||||
('http://172.16.1.1:5000/', True),
|
||||
('http://localhost.localdomain:5000/v1.0/', True),
|
||||
('http://google.com:6000/', True),
|
||||
('http://172.16.1.12/', False),
|
||||
('http://172.16.1.12:5000/', False),
|
||||
('http://google.com:5000/v1.0/', False),
|
||||
('file:///some/path/on/disk', True),
|
||||
))
|
||||
def test_should_bypass_proxies(url, expected, monkeypatch):
|
||||
"""Tests for function should_bypass_proxies to check if proxy
|
||||
can be bypassed or not
|
||||
"""
|
||||
monkeypatch.setenv('no_proxy', '192.168.0.0/24,127.0.0.1,localhost.localdomain,172.16.1.1, google.com:6000')
|
||||
monkeypatch.setenv('NO_PROXY', '192.168.0.0/24,127.0.0.1,localhost.localdomain,172.16.1.1, google.com:6000')
|
||||
monkeypatch.setenv('no_proxy', '192.168.0.0/24,127.0.0.1,localhost.localdomain,172.16.1.1')
|
||||
monkeypatch.setenv('NO_PROXY', '192.168.0.0/24,127.0.0.1,localhost.localdomain,172.16.1.1')
|
||||
assert should_bypass_proxies(url, no_proxy=None) == expected
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
'url, expected', (
|
||||
('http://172.16.1.1/', '172.16.1.1'),
|
||||
('http://172.16.1.1:5000/', '172.16.1.1'),
|
||||
('http://user:pass@172.16.1.1', '172.16.1.1'),
|
||||
('http://user:pass@172.16.1.1:5000', '172.16.1.1'),
|
||||
('http://hostname/', 'hostname'),
|
||||
('http://hostname:5000/', 'hostname'),
|
||||
('http://user:pass@hostname', 'hostname'),
|
||||
('http://user:pass@hostname:5000', 'hostname'),
|
||||
))
|
||||
def test_should_bypass_proxies_pass_only_hostname(url, expected, mocker):
|
||||
"""The proxy_bypass function should be called with a hostname or IP without
|
||||
a port number or auth credentials.
|
||||
"""
|
||||
proxy_bypass = mocker.patch('requests.utils.proxy_bypass')
|
||||
should_bypass_proxies(url, no_proxy=None)
|
||||
proxy_bypass.assert_called_once_with(expected)
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
'cookiejar', (
|
||||
compat.cookielib.CookieJar(),
|
||||
@@ -666,7 +566,7 @@ def test_add_dict_to_cookiejar(cookiejar):
|
||||
cookiedict = {'test': 'cookies',
|
||||
'good': 'cookies'}
|
||||
cj = add_dict_to_cookiejar(cookiejar, cookiedict)
|
||||
cookies = {cookie.name: cookie.value for cookie in cj}
|
||||
cookies = dict((cookie.name, cookie.value) for cookie in cj)
|
||||
assert cookiedict == cookies
|
||||
|
||||
|
||||
@@ -733,7 +633,6 @@ def test_should_bypass_proxies_win_registry(url, expected, override,
|
||||
pass
|
||||
|
||||
ie_settings = RegHandle()
|
||||
proxyEnableValues = deque([1, "1"])
|
||||
|
||||
def OpenKey(key, subkey):
|
||||
return ie_settings
|
||||
@@ -741,9 +640,7 @@ def test_should_bypass_proxies_win_registry(url, expected, override,
|
||||
def QueryValueEx(key, value_name):
|
||||
if key is ie_settings:
|
||||
if value_name == 'ProxyEnable':
|
||||
# this could be a string (REG_SZ) or a 32-bit number (REG_DWORD)
|
||||
proxyEnableValues.rotate()
|
||||
return [proxyEnableValues[0]]
|
||||
return [1]
|
||||
elif value_name == 'ProxyOverride':
|
||||
return [override]
|
||||
|
||||
@@ -754,30 +651,4 @@ def test_should_bypass_proxies_win_registry(url, expected, override,
|
||||
monkeypatch.setenv('NO_PROXY', '')
|
||||
monkeypatch.setattr(winreg, 'OpenKey', OpenKey)
|
||||
monkeypatch.setattr(winreg, 'QueryValueEx', QueryValueEx)
|
||||
assert should_bypass_proxies(url, None) == expected
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
'env_name, value', (
|
||||
('no_proxy', '192.168.0.0/24,127.0.0.1,localhost.localdomain'),
|
||||
('no_proxy', None),
|
||||
('a_new_key', '192.168.0.0/24,127.0.0.1,localhost.localdomain'),
|
||||
('a_new_key', None),
|
||||
))
|
||||
def test_set_environ(env_name, value):
|
||||
"""Tests set_environ will set environ values and will restore the environ."""
|
||||
environ_copy = copy.deepcopy(os.environ)
|
||||
with set_environ(env_name, value):
|
||||
assert os.environ.get(env_name) == value
|
||||
|
||||
assert os.environ == environ_copy
|
||||
|
||||
|
||||
def test_set_environ_raises_exception():
|
||||
"""Tests set_environ will raise exceptions in context when the
|
||||
value parameter is None."""
|
||||
with pytest.raises(Exception) as exception:
|
||||
with set_environ('test1', None):
|
||||
raise Exception('Expected exception')
|
||||
|
||||
assert 'Expected exception' in str(exception.value)
|
||||
assert should_bypass_proxies(url, no_proxy=None) == expected
|
||||
|
||||
@@ -96,7 +96,6 @@ class Server(threading.Thread):
|
||||
handler_result = self.handler(sock)
|
||||
|
||||
self.handler_results.append(handler_result)
|
||||
sock.close()
|
||||
|
||||
def _accept_connection(self):
|
||||
try:
|
||||
|
||||