Compare commits
2 Commits
| Author | SHA1 | Date | |
|---|---|---|---|

|
850c0bed7f | ||
|
|
48684d3705 |
@@ -1,2 +1,2 @@
|
||||
[run]
|
||||
omit = requests/packages/*
|
||||
omit = requests/packages/*
|
||||
@@ -1,5 +0,0 @@
|
||||
# You can configure git to automatically use this file with the following config:
|
||||
# git config --global blame.ignoreRevsFile .git-blame-ignore-revs
|
||||
|
||||
# Add automatic code formatting to Requests
|
||||
2a6f290bc09324406708a4d404a88a45d848ddf9
|
||||
6
.github/CODE_OF_CONDUCT.md
vendored
@@ -1,6 +0,0 @@
|
||||
# Treat each other well
|
||||
|
||||
Everyone participating in the _requests_ project, and in particular in the issue tracker,
|
||||
pull requests, and social media activity, is expected to treat other people with respect
|
||||
and more generally to follow the guidelines articulated in the
|
||||
[Python Community Code of Conduct](https://www.python.org/psf/codeofconduct/).
|
||||
1
.github/FUNDING.yml
vendored
@@ -1 +0,0 @@
|
||||
custom: ['https://www.python.org/psf/sponsorship/']
|
||||
2
.github/ISSUE_TEMPLATE.md
vendored
@@ -25,4 +25,4 @@ import requests
|
||||
|
||||
This command is only available on Requests v2.16.4 and greater. Otherwise,
|
||||
please provide some basic information about your system (Python version,
|
||||
operating system, &c).
|
||||
operating system, &c).
|
||||
36
.github/ISSUE_TEMPLATE/Bug_report.md
vendored
@@ -1,36 +0,0 @@
|
||||
---
|
||||
name: Bug report
|
||||
about: Create a report to help us improve
|
||||
|
||||
---
|
||||
|
||||
<!-- Summary. -->
|
||||
|
||||
## Expected Result
|
||||
|
||||
<!-- What you expected. -->
|
||||
|
||||
## Actual Result
|
||||
|
||||
<!-- What happened instead. -->
|
||||
|
||||
## Reproduction Steps
|
||||
|
||||
```python
|
||||
import requests
|
||||
|
||||
```
|
||||
|
||||
## System Information
|
||||
|
||||
$ python -m requests.help
|
||||
|
||||
```json
|
||||
{
|
||||
"paste": "here"
|
||||
}
|
||||
```
|
||||
|
||||
<!-- This command is only available on Requests v2.16.4 and greater. Otherwise,
|
||||
please provide some basic information about your system (Python version,
|
||||
operating system, &c). -->
|
||||
10
.github/ISSUE_TEMPLATE/Custom.md
vendored
@@ -1,10 +0,0 @@
|
||||
---
|
||||
name: Request for Help
|
||||
about: Guidance on using Requests.
|
||||
labels:
|
||||
- "Question/Not a bug"
|
||||
- "actions/autoclose-qa"
|
||||
|
||||
---
|
||||
|
||||
Please refer to our [Stack Overflow tag](https://stackoverflow.com/questions/tagged/python-requests) for guidance.
|
||||
10
.github/ISSUE_TEMPLATE/Feature_request.md
vendored
@@ -1,10 +0,0 @@
|
||||
---
|
||||
name: Feature request
|
||||
about: Suggest an idea for this project
|
||||
labels:
|
||||
- "Feature Request"
|
||||
- "actions/autoclose-feat"
|
||||
|
||||
---
|
||||
|
||||
Requests is not accepting feature requests at this time.
|
||||
93
.github/SECURITY.md
vendored
@@ -1,93 +0,0 @@
|
||||
# Vulnerability Disclosure
|
||||
|
||||
If you think you have found a potential security vulnerability in
|
||||
requests, please email [Nate](mailto:nate.prewitt@gmail.com)
|
||||
and [Seth](mailto:sethmichaellarson@gmail.com) directly.
|
||||
**Do not file a public issue.**
|
||||
|
||||
Our PGP Key fingerprints are:
|
||||
|
||||
- 8722 7E29 AD9C FF5C FAC3 EA6A 44D3 FF97 B80D C864 ([@nateprewitt](https://keybase.io/nateprewitt))
|
||||
|
||||
- EDD5 6765 A9D8 4653 CBC8 A134 51B0 6736 1740 F5FC ([@sethmlarson](https://keybase.io/sethmlarson))
|
||||
|
||||
You can also contact us on [Keybase](https://keybase.io) with the
|
||||
profiles above if desired.
|
||||
|
||||
If English is not your first language, please try to describe the
|
||||
problem and its impact to the best of your ability. For greater detail,
|
||||
please use your native language and we will try our best to translate it
|
||||
using online services.
|
||||
|
||||
Please also include the code you used to find the problem and the
|
||||
shortest amount of code necessary to reproduce it.
|
||||
|
||||
Please do not disclose this to anyone else. We will retrieve a CVE
|
||||
identifier if necessary and give you full credit under whatever name or
|
||||
alias you provide. We will only request an identifier when we have a fix
|
||||
and can publish it in a release.
|
||||
|
||||
We will respect your privacy and will only publicize your involvement if
|
||||
you grant us permission.
|
||||
|
||||
## Process
|
||||
|
||||
This following information discusses the process the requests project
|
||||
follows in response to vulnerability disclosures. If you are disclosing
|
||||
a vulnerability, this section of the documentation lets you know how we
|
||||
will respond to your disclosure.
|
||||
|
||||
### Timeline
|
||||
|
||||
When you report an issue, one of the project members will respond to you
|
||||
within two days *at the outside*. In most cases responses will be
|
||||
faster, usually within 12 hours. This initial response will at the very
|
||||
least confirm receipt of the report.
|
||||
|
||||
If we were able to rapidly reproduce the issue, the initial response
|
||||
will also contain confirmation of the issue. If we are not, we will
|
||||
often ask for more information about the reproduction scenario.
|
||||
|
||||
Our goal is to have a fix for any vulnerability released within two
|
||||
weeks of the initial disclosure. This may potentially involve shipping
|
||||
an interim release that simply disables function while a more mature fix
|
||||
can be prepared, but will in the vast majority of cases mean shipping a
|
||||
complete release as soon as possible.
|
||||
|
||||
Throughout the fix process we will keep you up to speed with how the fix
|
||||
is progressing. Once the fix is prepared, we will notify you that we
|
||||
believe we have a fix. Often we will ask you to confirm the fix resolves
|
||||
the problem in your environment, especially if we are not confident of
|
||||
our reproduction scenario.
|
||||
|
||||
At this point, we will prepare for the release. We will obtain a CVE
|
||||
number if one is required, providing you with full credit for the
|
||||
discovery. We will also decide on a planned release date, and let you
|
||||
know when it is. This release date will *always* be on a weekday.
|
||||
|
||||
At this point we will reach out to our major downstream packagers to
|
||||
notify them of an impending security-related patch so they can make
|
||||
arrangements. In addition, these packagers will be provided with the
|
||||
intended patch ahead of time, to ensure that they are able to promptly
|
||||
release their downstream packages. Currently the list of people we
|
||||
actively contact *ahead of a public release* is:
|
||||
|
||||
- Jeremy Cline, Red Hat (@jeremycline)
|
||||
- Daniele Tricoli, Debian (@eriol)
|
||||
|
||||
We will notify these individuals at least a week ahead of our planned
|
||||
release date to ensure that they have sufficient time to prepare. If you
|
||||
believe you should be on this list, please let one of the maintainers
|
||||
know at one of the email addresses at the top of this article.
|
||||
|
||||
On release day, we will push the patch to our public repository, along
|
||||
with an updated changelog that describes the issue and credits you. We
|
||||
will then issue a PyPI release containing the patch.
|
||||
|
||||
At this point, we will publicise the release. This will involve mails to
|
||||
mailing lists, Tweets, and all other communication mechanisms available
|
||||
to the core team.
|
||||
|
||||
We will also explicitly mention which commits contain the fix to make it
|
||||
easier for other distributors and users to easily patch their own
|
||||
versions of requests if upgrading is not an option.
|
||||
11
.github/dependabot.yml
vendored
@@ -1,11 +0,0 @@
|
||||
version: 2
|
||||
updates:
|
||||
- package-ecosystem: github-actions
|
||||
directory: /
|
||||
schedule:
|
||||
interval: weekly
|
||||
ignore:
|
||||
# Ignore all patch releases as we can manually
|
||||
# upgrade if we run into a bug and need a fix.
|
||||
- dependency-name: "*"
|
||||
update-types: ["version-update:semver-patch"]
|
||||
35
.github/workflows/close-issues.yml
vendored
@@ -1,35 +0,0 @@
|
||||
name: 'Autoclose Issues'
|
||||
|
||||
on:
|
||||
issues:
|
||||
types:
|
||||
- labeled
|
||||
|
||||
permissions:
|
||||
issues: write
|
||||
|
||||
jobs:
|
||||
close_qa:
|
||||
if: github.event.label.name == 'actions/autoclose-qa'
|
||||
runs-on: ubuntu-latest
|
||||
steps:
|
||||
- env:
|
||||
ISSUE_URL: ${{ github.event.issue.html_url }}
|
||||
GH_TOKEN: ${{ github.token }}
|
||||
run: |
|
||||
gh issue close $ISSUE_URL \
|
||||
--comment "As described in the template, we won't be able to answer questions on this issue tracker. Please use [Stack Overflow](https://stackoverflow.com/)" \
|
||||
--reason completed
|
||||
gh issue lock $ISSUE_URL --reason off_topic
|
||||
close_feature_request:
|
||||
if: github.event.label.name == 'actions/autoclose-feat'
|
||||
runs-on: ubuntu-latest
|
||||
steps:
|
||||
- env:
|
||||
ISSUE_URL: ${{ github.event.issue.html_url }}
|
||||
GH_TOKEN: ${{ github.token }}
|
||||
run: |
|
||||
gh issue close $ISSUE_URL \
|
||||
--comment "As described in the template, Requests is not accepting feature requests" \
|
||||
--reason "not planned"
|
||||
gh issue lock $ISSUE_URL --reason off_topic
|
||||
73
.github/workflows/codeql-analysis.yml
vendored
@@ -1,73 +0,0 @@
|
||||
# For most projects, this workflow file will not need changing; you simply need
|
||||
# to commit it to your repository.
|
||||
#
|
||||
# You may wish to alter this file to override the set of languages analyzed,
|
||||
# or to provide custom queries or build logic.
|
||||
name: "CodeQL"
|
||||
|
||||
on:
|
||||
push:
|
||||
branches: [main]
|
||||
pull_request:
|
||||
# The branches below must be a subset of the branches above
|
||||
branches: [main]
|
||||
schedule:
|
||||
- cron: '0 23 * * 0'
|
||||
|
||||
permissions:
|
||||
contents: read
|
||||
|
||||
jobs:
|
||||
analyze:
|
||||
permissions:
|
||||
actions: read # for github/codeql-action/init to get workflow details
|
||||
contents: read # for actions/checkout to fetch code
|
||||
security-events: write # for github/codeql-action/autobuild to send a status report
|
||||
name: Analyze
|
||||
runs-on: ubuntu-latest
|
||||
|
||||
strategy:
|
||||
fail-fast: false
|
||||
|
||||
|
||||
steps:
|
||||
- name: Checkout repository
|
||||
uses: actions/checkout@8ade135a41bc03ea155e62e844d188df1ea18608 # v4.1.0
|
||||
with:
|
||||
# We must fetch at least the immediate parents so that if this is
|
||||
# a pull request then we can checkout the head.
|
||||
fetch-depth: 2
|
||||
|
||||
# If this run was triggered by a pull request event, then checkout
|
||||
# the head of the pull request instead of the merge commit.
|
||||
- run: git checkout HEAD^2
|
||||
if: ${{ github.event_name == 'pull_request' }}
|
||||
|
||||
# Initializes the CodeQL tools for scanning.
|
||||
- name: Initialize CodeQL
|
||||
uses: github/codeql-action/init@df5a14dc28094dc936e103b37d749c6628682b60 # v3.25.0
|
||||
with:
|
||||
languages: "python"
|
||||
# If you wish to specify custom queries, you can do so here or in a config file.
|
||||
# By default, queries listed here will override any specified in a config file.
|
||||
# Prefix the list here with "+" to use these queries and those in the config file.
|
||||
# queries: ./path/to/local/query, your-org/your-repo/queries@main
|
||||
|
||||
# Autobuild attempts to build any compiled languages (C/C++, C#, or Java).
|
||||
# If this step fails, then you should remove it and run the build manually (see below)
|
||||
- name: Autobuild
|
||||
uses: github/codeql-action/autobuild@df5a14dc28094dc936e103b37d749c6628682b60 # v3.25.0
|
||||
|
||||
# ℹ️ Command-line programs to run using the OS shell.
|
||||
# 📚 https://git.io/JvXDl
|
||||
|
||||
# ✏️ If the Autobuild fails above, remove it and uncomment the following three lines
|
||||
# and modify them (or add more) to build your code if your project
|
||||
# uses a compiled language
|
||||
|
||||
#- run: |
|
||||
# make bootstrap
|
||||
# make release
|
||||
|
||||
- name: Perform CodeQL Analysis
|
||||
uses: github/codeql-action/analyze@df5a14dc28094dc936e103b37d749c6628682b60 # v3.25.0
|
||||
20
.github/workflows/lint.yml
vendored
@@ -1,20 +0,0 @@
|
||||
name: Lint code
|
||||
|
||||
on: [push, pull_request]
|
||||
|
||||
permissions:
|
||||
contents: read
|
||||
|
||||
jobs:
|
||||
lint:
|
||||
runs-on: ubuntu-20.04
|
||||
timeout-minutes: 10
|
||||
|
||||
steps:
|
||||
- uses: actions/checkout@8ade135a41bc03ea155e62e844d188df1ea18608 # v4.1.0
|
||||
- name: Set up Python
|
||||
uses: actions/setup-python@82c7e631bb3cdc910f68e0081d67478d79c6982d # v5.1.0
|
||||
with:
|
||||
python-version: "3.x"
|
||||
- name: Run pre-commit
|
||||
uses: pre-commit/action@646c83fcd040023954eafda54b4db0192ce70507 # v3.0.0
|
||||
19
.github/workflows/lock-issues.yml
vendored
@@ -1,19 +0,0 @@
|
||||
name: 'Lock Threads'
|
||||
|
||||
on:
|
||||
schedule:
|
||||
- cron: '0 0 * * *'
|
||||
|
||||
permissions:
|
||||
issues: write
|
||||
pull-requests: write
|
||||
|
||||
jobs:
|
||||
action:
|
||||
if: github.repository_owner == 'psf'
|
||||
runs-on: ubuntu-latest
|
||||
steps:
|
||||
- uses: dessant/lock-threads@d42e5f49803f3c4e14ffee0378e31481265dda22 # v5.0.0
|
||||
with:
|
||||
issue-lock-inactive-days: 90
|
||||
pr-lock-inactive-days: 90
|
||||
59
.github/workflows/run-tests.yml
vendored
@@ -1,59 +0,0 @@
|
||||
name: Tests
|
||||
|
||||
on: [push, pull_request]
|
||||
|
||||
permissions:
|
||||
contents: read
|
||||
|
||||
jobs:
|
||||
build:
|
||||
runs-on: ${{ matrix.os }}
|
||||
timeout-minutes: 10
|
||||
strategy:
|
||||
fail-fast: false
|
||||
matrix:
|
||||
python-version: ["3.8", "3.9", "3.10", "3.11", "3.12", "pypy-3.9", "pypy-3.10"]
|
||||
os: [ubuntu-22.04, macOS-latest, windows-latest]
|
||||
# Python 3.8 and 3.9 do not run on macOS-latest which
|
||||
# is now using arm64 hardware.
|
||||
# https://github.com/actions/setup-python/issues/696#issuecomment-1637587760
|
||||
exclude:
|
||||
- { python-version: "3.8", os: "macos-latest" }
|
||||
- { python-version: "3.9", os: "macos-latest" }
|
||||
include:
|
||||
- { python-version: "3.8", os: "macos-13" }
|
||||
- { python-version: "3.9", os: "macos-13" }
|
||||
|
||||
steps:
|
||||
- uses: actions/checkout@8ade135a41bc03ea155e62e844d188df1ea18608 # v4.1.0
|
||||
- name: Set up Python ${{ matrix.python-version }}
|
||||
uses: actions/setup-python@82c7e631bb3cdc910f68e0081d67478d79c6982d # v5.1.0
|
||||
with:
|
||||
python-version: ${{ matrix.python-version }}
|
||||
cache: 'pip'
|
||||
- name: Install dependencies
|
||||
run: |
|
||||
make
|
||||
- name: Run tests
|
||||
run: |
|
||||
make ci
|
||||
|
||||
no_chardet:
|
||||
name: "No Character Detection"
|
||||
runs-on: ubuntu-latest
|
||||
strategy:
|
||||
fail-fast: true
|
||||
|
||||
steps:
|
||||
- uses: actions/checkout@8ade135a41bc03ea155e62e844d188df1ea18608
|
||||
- name: 'Set up Python 3.8'
|
||||
uses: actions/setup-python@82c7e631bb3cdc910f68e0081d67478d79c6982d
|
||||
with:
|
||||
python-version: '3.8'
|
||||
- name: Install dependencies
|
||||
run: |
|
||||
make
|
||||
python -m pip uninstall -y "charset_normalizer" "chardet"
|
||||
- name: Run tests
|
||||
run: |
|
||||
make ci
|
||||
15
.gitignore
vendored
@@ -5,7 +5,6 @@ nosetests.xml
|
||||
junit-report.xml
|
||||
pylint.txt
|
||||
toy.py
|
||||
.cache/
|
||||
cover/
|
||||
build/
|
||||
docs/_build
|
||||
@@ -14,24 +13,10 @@ requests.egg-info/
|
||||
*.swp
|
||||
*.egg
|
||||
env/
|
||||
.venv/
|
||||
.eggs/
|
||||
.tox/
|
||||
.pytest_cache/
|
||||
.vscode/
|
||||
.eggs/
|
||||
|
||||
.workon
|
||||
|
||||
# in case you work with IntelliJ/PyCharm
|
||||
.idea
|
||||
*.iml
|
||||
.python-version
|
||||
|
||||
|
||||
t.py
|
||||
|
||||
t2.py
|
||||
dist
|
||||
|
||||
/.mypy_cache/
|
||||
|
||||
@@ -1,28 +0,0 @@
|
||||
exclude: 'docs/|ext/'
|
||||
|
||||
repos:
|
||||
- repo: https://github.com/pre-commit/pre-commit-hooks
|
||||
rev: v4.4.0
|
||||
hooks:
|
||||
- id: check-yaml
|
||||
- id: debug-statements
|
||||
- id: end-of-file-fixer
|
||||
- id: trailing-whitespace
|
||||
- repo: https://github.com/PyCQA/isort
|
||||
rev: 5.12.0
|
||||
hooks:
|
||||
- id: isort
|
||||
- repo: https://github.com/psf/black
|
||||
rev: 23.7.0
|
||||
hooks:
|
||||
- id: black
|
||||
exclude: tests/test_lowlevel.py
|
||||
- repo: https://github.com/asottile/pyupgrade
|
||||
rev: v3.10.1
|
||||
hooks:
|
||||
- id: pyupgrade
|
||||
args: [--py37-plus]
|
||||
- repo: https://github.com/PyCQA/flake8
|
||||
rev: 6.1.0
|
||||
hooks:
|
||||
- id: flake8
|
||||
@@ -1,29 +0,0 @@
|
||||
# Read the Docs configuration file for Sphinx projects
|
||||
# See https://docs.readthedocs.io/en/stable/config-file/v2.html for details
|
||||
|
||||
# Required
|
||||
version: 2
|
||||
|
||||
# Set the OS, Python version and other tools you might need
|
||||
build:
|
||||
os: ubuntu-22.04
|
||||
tools:
|
||||
python: "3.12"
|
||||
|
||||
# Build documentation in the "docs/" directory with Sphinx
|
||||
sphinx:
|
||||
configuration: docs/conf.py
|
||||
builder: "dirhtml"
|
||||
|
||||
# Optionally build your docs in additional formats such as PDF and ePub
|
||||
formats:
|
||||
- pdf
|
||||
- epub
|
||||
|
||||
# Optional but recommended, declare the Python requirements required
|
||||
# to build your documentation
|
||||
# See https://docs.readthedocs.io/en/stable/guides/reproducible-builds.html
|
||||
python:
|
||||
install:
|
||||
- path: .
|
||||
- requirements: docs/requirements.txt
|
||||
32
.travis.yml
Normal file
@@ -0,0 +1,32 @@
|
||||
sudo: false
|
||||
language: python
|
||||
python:
|
||||
- "2.6"
|
||||
- "2.7"
|
||||
- "3.3"
|
||||
- "3.4"
|
||||
- "3.5"
|
||||
- "3.6"
|
||||
# - "3.7-dev"
|
||||
# - "pypy" -- appears to hang
|
||||
# - "pypy3"
|
||||
# command to install dependencies
|
||||
install: "make"
|
||||
# command to run tests
|
||||
script:
|
||||
- |
|
||||
if [[ "$TRAVIS_PYTHON_VERSION" != "2.6" ]] ; then make test-readme; fi
|
||||
- make ci
|
||||
cache: pip
|
||||
jobs:
|
||||
include:
|
||||
- stage: test
|
||||
script:
|
||||
- |
|
||||
if [[ "$TRAVIS_PYTHON_VERSION" != "2.6" ]] ; then make test-readme; fi
|
||||
- make ci
|
||||
- stage: coverage
|
||||
python: 3.6
|
||||
script: codecov
|
||||
|
||||
|
||||
41
AUTHORS.rst
Normal file → Executable file
@@ -1,16 +1,20 @@
|
||||
Requests was lovingly created by Kenneth Reitz.
|
||||
Requests is written and maintained by Kenneth Reitz and
|
||||
various contributors:
|
||||
|
||||
Keepers of the Crystals
|
||||
```````````````````````
|
||||
|
||||
- Nate Prewitt `@nateprewitt <https://github.com/nateprewitt>`_.
|
||||
- Seth M. Larson `@sethmlarson <https://github.com/sethmlarson>`_.
|
||||
|
||||
Previous Keepers of Crystals
|
||||
Keepers of the Four Crystals
|
||||
````````````````````````````
|
||||
- Kenneth Reitz <me@kennethreitz.org> `@kennethreitz <https://github.com/kennethreitz>`_, reluctant Keeper of the Master Crystal.
|
||||
|
||||
- Kenneth Reitz <me@kennethreitz.org> `@kennethreitz <https://github.com/kennethreitz>`_, Keeper of the Master Crystal.
|
||||
- Cory Benfield <cory@lukasa.co.uk> `@lukasa <https://github.com/lukasa>`_
|
||||
- Ian Cordasco <graffatcolmingov@gmail.com> `@sigmavirus24 <https://github.com/sigmavirus24>`_.
|
||||
- Ian Cordasco <graffatcolmingov@gmail.com> `@sigmavirus24 <https://github.com/sigmavirus24>`_
|
||||
- Nate Prewitt <nate.prewitt@gmail.com> `@nateprewitt <https://github.com/nateprewitt>`_
|
||||
|
||||
|
||||
|
||||
Urllib3
|
||||
```````
|
||||
|
||||
- Andrey Petrov <andrey.petrov@shazow.net>
|
||||
|
||||
|
||||
Patches and Suggestions
|
||||
@@ -124,7 +128,7 @@ Patches and Suggestions
|
||||
- Bryce Boe <bbzbryce@gmail.com> (`@bboe <https://github.com/bboe>`_)
|
||||
- Colin Dunklau <colin.dunklau@gmail.com> (`@cdunklau <https://github.com/cdunklau>`_)
|
||||
- Bob Carroll <bob.carroll@alum.rit.edu> (`@rcarz <https://github.com/rcarz>`_)
|
||||
- Hugo Osvaldo Barrera <hugo@barrera.io> (`@hobarrera <https://github.com/hobarrera>`_)
|
||||
- Hugo Osvaldo Barrera <hugo@osvaldobarrera.com.ar> (`@hobarrera <https://github.com/hobarrera>`_)
|
||||
- Łukasz Langa <lukasz@langa.pl>
|
||||
- Dave Shawley <daveshawley@gmail.com>
|
||||
- James Clarke (`@jam <https://github.com/jam>`_)
|
||||
@@ -178,18 +182,3 @@ Patches and Suggestions
|
||||
- David Fontenot (`@davidfontenot <https://github.com/davidfontenot>`_)
|
||||
- Shmuel Amar (`@shmuelamar <https://github.com/shmuelamar>`_)
|
||||
- Gary Wu (`@garywu <https://github.com/garywu>`_)
|
||||
- Ryan Pineo (`@ryanpineo <https://github.com/ryanpineo>`_)
|
||||
- Ed Morley (`@edmorley <https://github.com/edmorley>`_)
|
||||
- Matt Liu <liumatt@gmail.com> (`@mlcrazy <https://github.com/mlcrazy>`_)
|
||||
- Taylor Hoff <primdevs@protonmail.com> (`@PrimordialHelios <https://github.com/PrimordialHelios>`_)
|
||||
- Arthur Vigil (`@ahvigil <https://github.com/ahvigil>`_)
|
||||
- Nehal J Wani (`@nehaljwani <https://github.com/nehaljwani>`_)
|
||||
- Demetrios Bairaktaris (`@DemetriosBairaktaris <https://github.com/demetriosbairaktaris>`_)
|
||||
- Darren Dormer (`@ddormer <https://github.com/ddormer>`_)
|
||||
- Rajiv Mayani (`@mayani <https://github.com/mayani>`_)
|
||||
- Antti Kaihola (`@akaihola <https://github.com/akaihola>`_)
|
||||
- "Dull Bananas" <dull.bananas0@gmail.com> (`@dullbananas <https://github.com/dullbananas>`_)
|
||||
- Alessio Izzo (`@aless10 <https://github.com/aless10>`_)
|
||||
- Sylvain Marié (`@smarie <https://github.com/smarie>`_)
|
||||
- Hod Bin Noon (`@hodbn <https://github.com/hodbn>`_)
|
||||
- Mike Fiedler (`@miketheman <https://github.com/miketheman>`_)
|
||||
|
||||
3
CODE_OF_CONDUCT.md
Normal file
@@ -0,0 +1,3 @@
|
||||
Be cordial or be on your way.
|
||||
|
||||
https://www.kennethreitz.org/essays/be-cordial-or-be-on-your-way
|
||||
@@ -1,7 +1,10 @@
|
||||
# Contribution Guidelines
|
||||
|
||||
Before opening any issues or proposing any pull requests, please read
|
||||
our [Contributor's Guide](https://requests.readthedocs.io/en/latest/dev/contributing/).
|
||||
Before opening any issues or proposing any pull requests, please do the
|
||||
following:
|
||||
|
||||
1. Read our [Contributor's Guide](http://docs.python-requests.org/en/latest/dev/contributing/).
|
||||
2. Understand our [development philosophy](http://docs.python-requests.org/en/latest/dev/philosophy/).
|
||||
|
||||
To get the greatest chance of helpful responses, please also observe the
|
||||
following additional notes.
|
||||
1982
HISTORY.md
1462
HISTORY.rst
Normal file
182
LICENSE
@@ -1,175 +1,13 @@
|
||||
Copyright 2017 Kenneth Reitz
|
||||
|
||||
Apache License
|
||||
Version 2.0, January 2004
|
||||
http://www.apache.org/licenses/
|
||||
Licensed under the Apache License, Version 2.0 (the "License");
|
||||
you may not use this file except in compliance with the License.
|
||||
You may obtain a copy of the License at
|
||||
|
||||
TERMS AND CONDITIONS FOR USE, REPRODUCTION, AND DISTRIBUTION
|
||||
http://www.apache.org/licenses/LICENSE-2.0
|
||||
|
||||
1. Definitions.
|
||||
|
||||
"License" shall mean the terms and conditions for use, reproduction,
|
||||
and distribution as defined by Sections 1 through 9 of this document.
|
||||
|
||||
"Licensor" shall mean the copyright owner or entity authorized by
|
||||
the copyright owner that is granting the License.
|
||||
|
||||
"Legal Entity" shall mean the union of the acting entity and all
|
||||
other entities that control, are controlled by, or are under common
|
||||
control with that entity. For the purposes of this definition,
|
||||
"control" means (i) the power, direct or indirect, to cause the
|
||||
direction or management of such entity, whether by contract or
|
||||
otherwise, or (ii) ownership of fifty percent (50%) or more of the
|
||||
outstanding shares, or (iii) beneficial ownership of such entity.
|
||||
|
||||
"You" (or "Your") shall mean an individual or Legal Entity
|
||||
exercising permissions granted by this License.
|
||||
|
||||
"Source" form shall mean the preferred form for making modifications,
|
||||
including but not limited to software source code, documentation
|
||||
source, and configuration files.
|
||||
|
||||
"Object" form shall mean any form resulting from mechanical
|
||||
transformation or translation of a Source form, including but
|
||||
not limited to compiled object code, generated documentation,
|
||||
and conversions to other media types.
|
||||
|
||||
"Work" shall mean the work of authorship, whether in Source or
|
||||
Object form, made available under the License, as indicated by a
|
||||
copyright notice that is included in or attached to the work
|
||||
(an example is provided in the Appendix below).
|
||||
|
||||
"Derivative Works" shall mean any work, whether in Source or Object
|
||||
form, that is based on (or derived from) the Work and for which the
|
||||
editorial revisions, annotations, elaborations, or other modifications
|
||||
represent, as a whole, an original work of authorship. For the purposes
|
||||
of this License, Derivative Works shall not include works that remain
|
||||
separable from, or merely link (or bind by name) to the interfaces of,
|
||||
the Work and Derivative Works thereof.
|
||||
|
||||
"Contribution" shall mean any work of authorship, including
|
||||
the original version of the Work and any modifications or additions
|
||||
to that Work or Derivative Works thereof, that is intentionally
|
||||
submitted to Licensor for inclusion in the Work by the copyright owner
|
||||
or by an individual or Legal Entity authorized to submit on behalf of
|
||||
the copyright owner. For the purposes of this definition, "submitted"
|
||||
means any form of electronic, verbal, or written communication sent
|
||||
to the Licensor or its representatives, including but not limited to
|
||||
communication on electronic mailing lists, source code control systems,
|
||||
and issue tracking systems that are managed by, or on behalf of, the
|
||||
Licensor for the purpose of discussing and improving the Work, but
|
||||
excluding communication that is conspicuously marked or otherwise
|
||||
designated in writing by the copyright owner as "Not a Contribution."
|
||||
|
||||
"Contributor" shall mean Licensor and any individual or Legal Entity
|
||||
on behalf of whom a Contribution has been received by Licensor and
|
||||
subsequently incorporated within the Work.
|
||||
|
||||
2. Grant of Copyright License. Subject to the terms and conditions of
|
||||
this License, each Contributor hereby grants to You a perpetual,
|
||||
worldwide, non-exclusive, no-charge, royalty-free, irrevocable
|
||||
copyright license to reproduce, prepare Derivative Works of,
|
||||
publicly display, publicly perform, sublicense, and distribute the
|
||||
Work and such Derivative Works in Source or Object form.
|
||||
|
||||
3. Grant of Patent License. Subject to the terms and conditions of
|
||||
this License, each Contributor hereby grants to You a perpetual,
|
||||
worldwide, non-exclusive, no-charge, royalty-free, irrevocable
|
||||
(except as stated in this section) patent license to make, have made,
|
||||
use, offer to sell, sell, import, and otherwise transfer the Work,
|
||||
where such license applies only to those patent claims licensable
|
||||
by such Contributor that are necessarily infringed by their
|
||||
Contribution(s) alone or by combination of their Contribution(s)
|
||||
with the Work to which such Contribution(s) was submitted. If You
|
||||
institute patent litigation against any entity (including a
|
||||
cross-claim or counterclaim in a lawsuit) alleging that the Work
|
||||
or a Contribution incorporated within the Work constitutes direct
|
||||
or contributory patent infringement, then any patent licenses
|
||||
granted to You under this License for that Work shall terminate
|
||||
as of the date such litigation is filed.
|
||||
|
||||
4. Redistribution. You may reproduce and distribute copies of the
|
||||
Work or Derivative Works thereof in any medium, with or without
|
||||
modifications, and in Source or Object form, provided that You
|
||||
meet the following conditions:
|
||||
|
||||
(a) You must give any other recipients of the Work or
|
||||
Derivative Works a copy of this License; and
|
||||
|
||||
(b) You must cause any modified files to carry prominent notices
|
||||
stating that You changed the files; and
|
||||
|
||||
(c) You must retain, in the Source form of any Derivative Works
|
||||
that You distribute, all copyright, patent, trademark, and
|
||||
attribution notices from the Source form of the Work,
|
||||
excluding those notices that do not pertain to any part of
|
||||
the Derivative Works; and
|
||||
|
||||
(d) If the Work includes a "NOTICE" text file as part of its
|
||||
distribution, then any Derivative Works that You distribute must
|
||||
include a readable copy of the attribution notices contained
|
||||
within such NOTICE file, excluding those notices that do not
|
||||
pertain to any part of the Derivative Works, in at least one
|
||||
of the following places: within a NOTICE text file distributed
|
||||
as part of the Derivative Works; within the Source form or
|
||||
documentation, if provided along with the Derivative Works; or,
|
||||
within a display generated by the Derivative Works, if and
|
||||
wherever such third-party notices normally appear. The contents
|
||||
of the NOTICE file are for informational purposes only and
|
||||
do not modify the License. You may add Your own attribution
|
||||
notices within Derivative Works that You distribute, alongside
|
||||
or as an addendum to the NOTICE text from the Work, provided
|
||||
that such additional attribution notices cannot be construed
|
||||
as modifying the License.
|
||||
|
||||
You may add Your own copyright statement to Your modifications and
|
||||
may provide additional or different license terms and conditions
|
||||
for use, reproduction, or distribution of Your modifications, or
|
||||
for any such Derivative Works as a whole, provided Your use,
|
||||
reproduction, and distribution of the Work otherwise complies with
|
||||
the conditions stated in this License.
|
||||
|
||||
5. Submission of Contributions. Unless You explicitly state otherwise,
|
||||
any Contribution intentionally submitted for inclusion in the Work
|
||||
by You to the Licensor shall be under the terms and conditions of
|
||||
this License, without any additional terms or conditions.
|
||||
Notwithstanding the above, nothing herein shall supersede or modify
|
||||
the terms of any separate license agreement you may have executed
|
||||
with Licensor regarding such Contributions.
|
||||
|
||||
6. Trademarks. This License does not grant permission to use the trade
|
||||
names, trademarks, service marks, or product names of the Licensor,
|
||||
except as required for reasonable and customary use in describing the
|
||||
origin of the Work and reproducing the content of the NOTICE file.
|
||||
|
||||
7. Disclaimer of Warranty. Unless required by applicable law or
|
||||
agreed to in writing, Licensor provides the Work (and each
|
||||
Contributor provides its Contributions) on an "AS IS" BASIS,
|
||||
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or
|
||||
implied, including, without limitation, any warranties or conditions
|
||||
of TITLE, NON-INFRINGEMENT, MERCHANTABILITY, or FITNESS FOR A
|
||||
PARTICULAR PURPOSE. You are solely responsible for determining the
|
||||
appropriateness of using or redistributing the Work and assume any
|
||||
risks associated with Your exercise of permissions under this License.
|
||||
|
||||
8. Limitation of Liability. In no event and under no legal theory,
|
||||
whether in tort (including negligence), contract, or otherwise,
|
||||
unless required by applicable law (such as deliberate and grossly
|
||||
negligent acts) or agreed to in writing, shall any Contributor be
|
||||
liable to You for damages, including any direct, indirect, special,
|
||||
incidental, or consequential damages of any character arising as a
|
||||
result of this License or out of the use or inability to use the
|
||||
Work (including but not limited to damages for loss of goodwill,
|
||||
work stoppage, computer failure or malfunction, or any and all
|
||||
other commercial damages or losses), even if such Contributor
|
||||
has been advised of the possibility of such damages.
|
||||
|
||||
9. Accepting Warranty or Additional Liability. While redistributing
|
||||
the Work or Derivative Works thereof, You may choose to offer,
|
||||
and charge a fee for, acceptance of support, warranty, indemnity,
|
||||
or other liability obligations and/or rights consistent with this
|
||||
License. However, in accepting such obligations, You may act only
|
||||
on Your own behalf and on Your sole responsibility, not on behalf
|
||||
of any other Contributor, and only if You agree to indemnify,
|
||||
defend, and hold each Contributor harmless for any liability
|
||||
incurred by, or claims asserted against, such Contributor by reason
|
||||
of your accepting any such warranty or additional liability.
|
||||
Unless required by applicable law or agreed to in writing, software
|
||||
distributed under the License is distributed on an "AS IS" BASIS,
|
||||
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
See the License for the specific language governing permissions and
|
||||
limitations under the License.
|
||||
|
||||
@@ -1,3 +1,2 @@
|
||||
include README.md LICENSE NOTICE HISTORY.md requirements-dev.txt
|
||||
include README.rst LICENSE NOTICE HISTORY.rst pytest.ini
|
||||
recursive-include tests *.py
|
||||
recursive-include tests/certs *
|
||||
|
||||
18
Makefile
@@ -1,27 +1,27 @@
|
||||
.PHONY: docs
|
||||
init:
|
||||
python -m pip install -r requirements-dev.txt
|
||||
pip install -r requirements.txt
|
||||
test:
|
||||
# This runs all of the tests on all supported Python versions.
|
||||
tox -p
|
||||
# This runs all of the tests, on both Python 2 and Python 3.
|
||||
detox
|
||||
ci:
|
||||
python -m pytest tests --junitxml=report.xml
|
||||
py.test -n 8 --boxed --junitxml=report.xml
|
||||
|
||||
test-readme:
|
||||
python setup.py check --restructuredtext --strict && ([ $$? -eq 0 ] && echo "README.rst and HISTORY.rst ok") || echo "Invalid markup in README.rst or HISTORY.rst!"
|
||||
python setup.py check -r -s
|
||||
|
||||
flake8:
|
||||
python -m flake8 src/requests
|
||||
flake8 --ignore=E501 requests
|
||||
|
||||
coverage:
|
||||
python -m pytest --cov-config .coveragerc --verbose --cov-report term --cov-report xml --cov=src/requests tests
|
||||
py.test --cov-config .coveragerc --verbose --cov-report term --cov-report xml --cov=requests tests
|
||||
|
||||
publish:
|
||||
python -m pip install 'twine>=1.5.0'
|
||||
pip install 'twine>=1.5.0'
|
||||
python setup.py sdist bdist_wheel
|
||||
twine upload dist/*
|
||||
rm -fr build dist .egg requests.egg-info
|
||||
|
||||
docs:
|
||||
cd docs && make html
|
||||
@echo "\033[95m\n\nBuild successful! View the docs homepage at docs/_build/html/index.html.\n\033[0m"
|
||||
@echo "\033[95m\n\nBuild successful! View the docs homepage at docs/_build/html/index.html.\n\033[0m"
|
||||
78
README.md
@@ -1,78 +0,0 @@
|
||||
# Requests
|
||||
|
||||
**Requests** is a simple, yet elegant, HTTP library.
|
||||
|
||||
```python
|
||||
>>> import requests
|
||||
>>> r = requests.get('https://httpbin.org/basic-auth/user/pass', auth=('user', 'pass'))
|
||||
>>> r.status_code
|
||||
200
|
||||
>>> r.headers['content-type']
|
||||
'application/json; charset=utf8'
|
||||
>>> r.encoding
|
||||
'utf-8'
|
||||
>>> r.text
|
||||
'{"authenticated": true, ...'
|
||||
>>> r.json()
|
||||
{'authenticated': True, ...}
|
||||
```
|
||||
|
||||
Requests allows you to send HTTP/1.1 requests extremely easily. There’s no need to manually add query strings to your URLs, or to form-encode your `PUT` & `POST` data — but nowadays, just use the `json` method!
|
||||
|
||||
Requests is one of the most downloaded Python packages today, pulling in around `30M downloads / week`— according to GitHub, Requests is currently [depended upon](https://github.com/psf/requests/network/dependents?package_id=UGFja2FnZS01NzA4OTExNg%3D%3D) by `1,000,000+` repositories. You may certainly put your trust in this code.
|
||||
|
||||
[](https://pepy.tech/project/requests)
|
||||
[](https://pypi.org/project/requests)
|
||||
[](https://github.com/psf/requests/graphs/contributors)
|
||||
|
||||
## Installing Requests and Supported Versions
|
||||
|
||||
Requests is available on PyPI:
|
||||
|
||||
```console
|
||||
$ python -m pip install requests
|
||||
```
|
||||
|
||||
Requests officially supports Python 3.8+.
|
||||
|
||||
## Supported Features & Best–Practices
|
||||
|
||||
Requests is ready for the demands of building robust and reliable HTTP–speaking applications, for the needs of today.
|
||||
|
||||
- Keep-Alive & Connection Pooling
|
||||
- International Domains and URLs
|
||||
- Sessions with Cookie Persistence
|
||||
- Browser-style TLS/SSL Verification
|
||||
- Basic & Digest Authentication
|
||||
- Familiar `dict`–like Cookies
|
||||
- Automatic Content Decompression and Decoding
|
||||
- Multi-part File Uploads
|
||||
- SOCKS Proxy Support
|
||||
- Connection Timeouts
|
||||
- Streaming Downloads
|
||||
- Automatic honoring of `.netrc`
|
||||
- Chunked HTTP Requests
|
||||
|
||||
## API Reference and User Guide available on [Read the Docs](https://requests.readthedocs.io)
|
||||
|
||||
[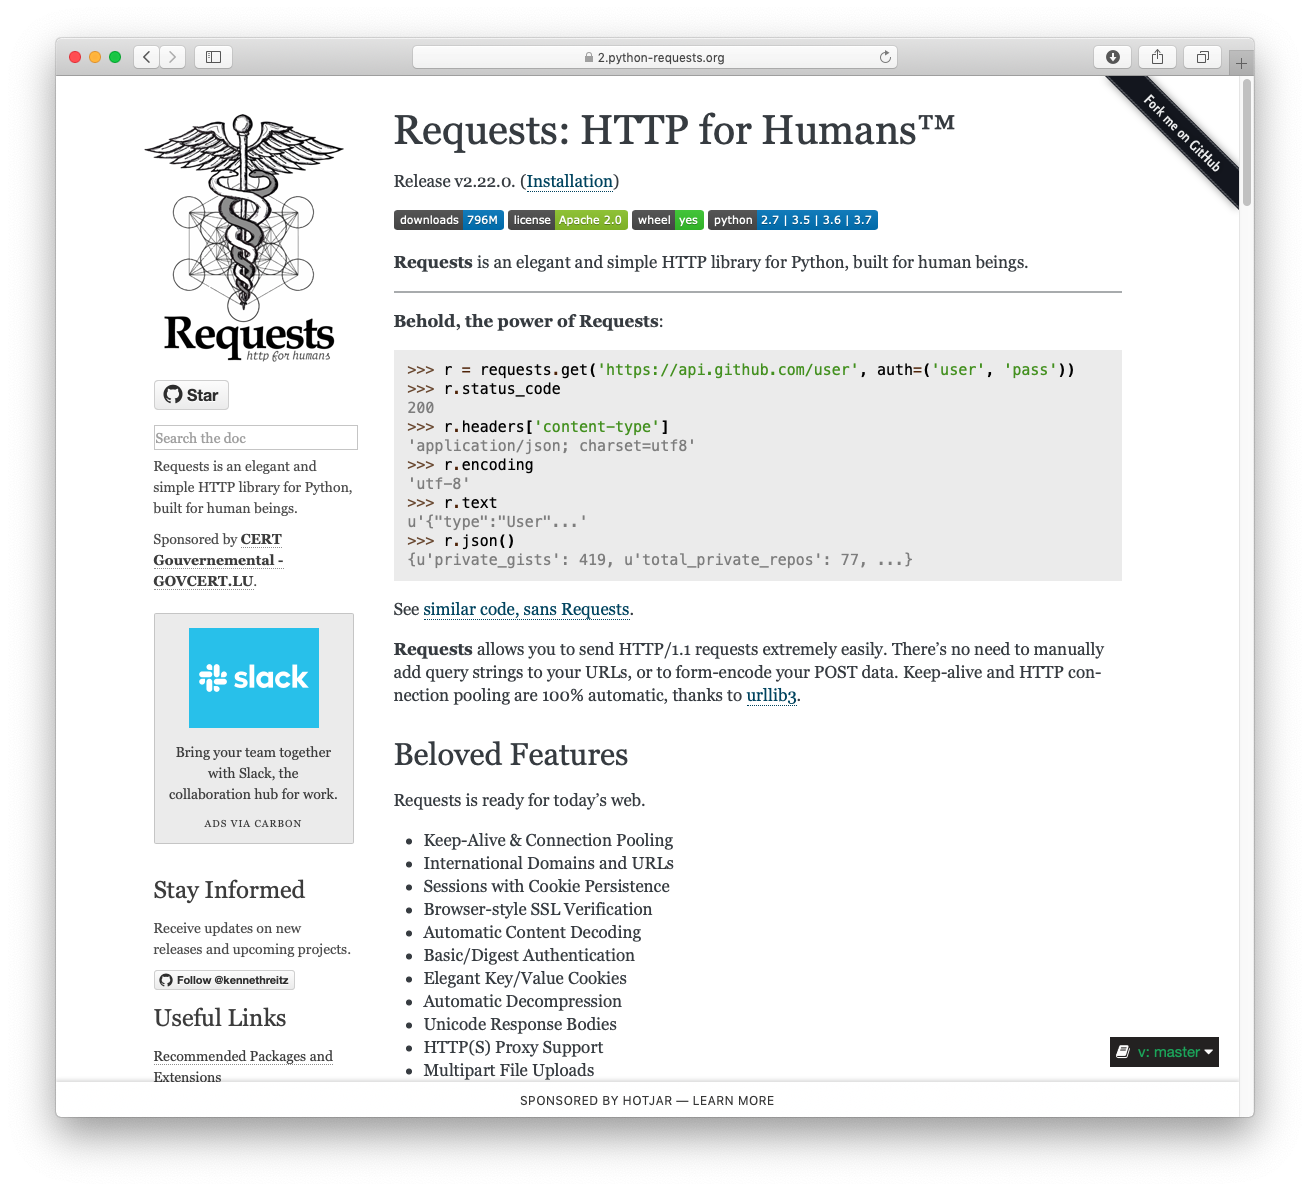](https://requests.readthedocs.io)
|
||||
|
||||
## Cloning the repository
|
||||
|
||||
When cloning the Requests repository, you may need to add the `-c
|
||||
fetch.fsck.badTimezone=ignore` flag to avoid an error about a bad commit (see
|
||||
[this issue](https://github.com/psf/requests/issues/2690) for more background):
|
||||
|
||||
```shell
|
||||
git clone -c fetch.fsck.badTimezone=ignore https://github.com/psf/requests.git
|
||||
```
|
||||
|
||||
You can also apply this setting to your global Git config:
|
||||
|
||||
```shell
|
||||
git config --global fetch.fsck.badTimezone ignore
|
||||
```
|
||||
|
||||
---
|
||||
|
||||
[](https://kennethreitz.org) [](https://www.python.org/psf)
|
||||
114
README.rst
Normal file
@@ -0,0 +1,114 @@
|
||||
Requests: HTTP for Humans
|
||||
=========================
|
||||
|
||||
.. image:: https://img.shields.io/pypi/v/requests.svg
|
||||
:target: https://pypi.python.org/pypi/requests
|
||||
|
||||
.. image:: https://img.shields.io/pypi/l/requests.svg
|
||||
:target: https://pypi.python.org/pypi/requests
|
||||
|
||||
.. image:: https://img.shields.io/pypi/pyversions/requests.svg
|
||||
:target: https://pypi.python.org/pypi/requests
|
||||
|
||||
.. image:: https://codecov.io/github/requests/requests/coverage.svg?branch=master
|
||||
:target: https://codecov.io/github/requests/requests
|
||||
:alt: codecov.io
|
||||
|
||||
.. image:: https://img.shields.io/github/contributors/requests/requests.svg
|
||||
:target: https://github.com/requests/requests/graphs/contributors
|
||||
|
||||
.. image:: https://img.shields.io/badge/Say%20Thanks-!-1EAEDB.svg
|
||||
:target: https://saythanks.io/to/kennethreitz
|
||||
|
||||
|
||||
|
||||
Requests is the only *Non-GMO* HTTP library for Python, safe for human
|
||||
consumption.
|
||||
|
||||
**Warning:** Recreational use of the Python standard library for HTTP may result in dangerous side-effects,
|
||||
including: security vulnerabilities, verbose code, reinventing the wheel,
|
||||
constantly reading documentation, depression, headaches, or even death.
|
||||
|
||||
Behold, the power of Requests:
|
||||
|
||||
.. code-block:: python
|
||||
|
||||
>>> r = requests.get('https://api.github.com/user', auth=('user', 'pass'))
|
||||
>>> r.status_code
|
||||
200
|
||||
>>> r.headers['content-type']
|
||||
'application/json; charset=utf8'
|
||||
>>> r.encoding
|
||||
'utf-8'
|
||||
>>> r.text
|
||||
u'{"type":"User"...'
|
||||
>>> r.json()
|
||||
{u'disk_usage': 368627, u'private_gists': 484, ...}
|
||||
|
||||
See `the similar code, sans Requests <https://gist.github.com/973705>`_.
|
||||
|
||||
.. image:: https://raw.githubusercontent.com/requests/requests/master/docs/_static/requests-logo-small.png
|
||||
:target: http://docs.python-requests.org/
|
||||
|
||||
|
||||
Requests allows you to send *organic, grass-fed* HTTP/1.1 requests, without the
|
||||
need for manual labor. There's no need to manually add query strings to your
|
||||
URLs, or to form-encode your POST data. Keep-alive and HTTP connection pooling
|
||||
are 100% automatic, thanks to `urllib3 <https://github.com/shazow/urllib3>`_.
|
||||
|
||||
Besides, all the cool kids are doing it. Requests is one of the most
|
||||
downloaded Python packages of all time, pulling in over 11,000,000 downloads
|
||||
every month. You don't want to be left out!
|
||||
|
||||
Feature Support
|
||||
---------------
|
||||
|
||||
Requests is ready for today's web.
|
||||
|
||||
- International Domains and URLs
|
||||
- Keep-Alive & Connection Pooling
|
||||
- Sessions with Cookie Persistence
|
||||
- Browser-style SSL Verification
|
||||
- Basic/Digest Authentication
|
||||
- Elegant Key/Value Cookies
|
||||
- Automatic Decompression
|
||||
- Automatic Content Decoding
|
||||
- Unicode Response Bodies
|
||||
- Multipart File Uploads
|
||||
- HTTP(S) Proxy Support
|
||||
- Connection Timeouts
|
||||
- Streaming Downloads
|
||||
- ``.netrc`` Support
|
||||
- Chunked Requests
|
||||
|
||||
Requests officially supports Python 2.6–2.7 & 3.3–3.7, and runs great on PyPy.
|
||||
|
||||
Installation
|
||||
------------
|
||||
|
||||
To install Requests, simply:
|
||||
|
||||
.. code-block:: bash
|
||||
|
||||
$ pip install requests
|
||||
✨🍰✨
|
||||
|
||||
Satisfaction, guaranteed.
|
||||
|
||||
Documentation
|
||||
-------------
|
||||
|
||||
Fantastic documentation is available at http://docs.python-requests.org/, for a limited time only.
|
||||
|
||||
|
||||
How to Contribute
|
||||
-----------------
|
||||
|
||||
#. Check for open issues or open a fresh issue to start a discussion around a feature idea or a bug. There is a `Contributor Friendly`_ tag for issues that should be ideal for people who are not very familiar with the codebase yet.
|
||||
#. Fork `the repository`_ on GitHub to start making your changes to the **master** branch (or branch off of it).
|
||||
#. Write a test which shows that the bug was fixed or that the feature works as expected.
|
||||
#. Send a pull request and bug the maintainer until it gets merged and published. :) Make sure to add yourself to AUTHORS_.
|
||||
|
||||
.. _`the repository`: http://github.com/requests/requests
|
||||
.. _AUTHORS: https://github.com/requests/requests/blob/master/AUTHORS.rst
|
||||
.. _Contributor Friendly: https://github.com/requests/requests/issues?direction=desc&labels=Contributor+Friendly&page=1&sort=updated&state=open
|
||||
229
_appveyor/install.ps1
Normal file
@@ -0,0 +1,229 @@
|
||||
# Sample script to install Python and pip under Windows
|
||||
# Authors: Olivier Grisel, Jonathan Helmus, Kyle Kastner, and Alex Willmer
|
||||
# License: CC0 1.0 Universal: http://creativecommons.org/publicdomain/zero/1.0/
|
||||
|
||||
$MINICONDA_URL = "http://repo.continuum.io/miniconda/"
|
||||
$BASE_URL = "https://www.python.org/ftp/python/"
|
||||
$GET_PIP_URL = "https://bootstrap.pypa.io/get-pip.py"
|
||||
$GET_PIP_PATH = "C:\get-pip.py"
|
||||
|
||||
$PYTHON_PRERELEASE_REGEX = @"
|
||||
(?x)
|
||||
(?<major>\d+)
|
||||
\.
|
||||
(?<minor>\d+)
|
||||
\.
|
||||
(?<micro>\d+)
|
||||
(?<prerelease>[a-z]{1,2}\d+)
|
||||
"@
|
||||
|
||||
|
||||
function Download ($filename, $url) {
|
||||
$webclient = New-Object System.Net.WebClient
|
||||
|
||||
$basedir = $pwd.Path + "\"
|
||||
$filepath = $basedir + $filename
|
||||
if (Test-Path $filename) {
|
||||
Write-Host "Reusing" $filepath
|
||||
return $filepath
|
||||
}
|
||||
|
||||
# Download and retry up to 3 times in case of network transient errors.
|
||||
Write-Host "Downloading" $filename "from" $url
|
||||
$retry_attempts = 2
|
||||
for ($i = 0; $i -lt $retry_attempts; $i++) {
|
||||
try {
|
||||
$webclient.DownloadFile($url, $filepath)
|
||||
break
|
||||
}
|
||||
Catch [Exception]{
|
||||
Start-Sleep 1
|
||||
}
|
||||
}
|
||||
if (Test-Path $filepath) {
|
||||
Write-Host "File saved at" $filepath
|
||||
} else {
|
||||
# Retry once to get the error message if any at the last try
|
||||
$webclient.DownloadFile($url, $filepath)
|
||||
}
|
||||
return $filepath
|
||||
}
|
||||
|
||||
|
||||
function ParsePythonVersion ($python_version) {
|
||||
if ($python_version -match $PYTHON_PRERELEASE_REGEX) {
|
||||
return ([int]$matches.major, [int]$matches.minor, [int]$matches.micro,
|
||||
$matches.prerelease)
|
||||
}
|
||||
$version_obj = [version]$python_version
|
||||
return ($version_obj.major, $version_obj.minor, $version_obj.build, "")
|
||||
}
|
||||
|
||||
|
||||
function DownloadPython ($python_version, $platform_suffix) {
|
||||
$major, $minor, $micro, $prerelease = ParsePythonVersion $python_version
|
||||
|
||||
if (($major -le 2 -and $micro -eq 0) `
|
||||
-or ($major -eq 3 -and $minor -le 2 -and $micro -eq 0) `
|
||||
) {
|
||||
$dir = "$major.$minor"
|
||||
$python_version = "$major.$minor$prerelease"
|
||||
} else {
|
||||
$dir = "$major.$minor.$micro"
|
||||
}
|
||||
|
||||
if ($prerelease) {
|
||||
if (($major -le 2) `
|
||||
-or ($major -eq 3 -and $minor -eq 1) `
|
||||
-or ($major -eq 3 -and $minor -eq 2) `
|
||||
-or ($major -eq 3 -and $minor -eq 3) `
|
||||
) {
|
||||
$dir = "$dir/prev"
|
||||
}
|
||||
}
|
||||
|
||||
if (($major -le 2) -or ($major -le 3 -and $minor -le 4)) {
|
||||
$ext = "msi"
|
||||
if ($platform_suffix) {
|
||||
$platform_suffix = ".$platform_suffix"
|
||||
}
|
||||
} else {
|
||||
$ext = "exe"
|
||||
if ($platform_suffix) {
|
||||
$platform_suffix = "-$platform_suffix"
|
||||
}
|
||||
}
|
||||
|
||||
$filename = "python-$python_version$platform_suffix.$ext"
|
||||
$url = "$BASE_URL$dir/$filename"
|
||||
$filepath = Download $filename $url
|
||||
return $filepath
|
||||
}
|
||||
|
||||
|
||||
function InstallPython ($python_version, $architecture, $python_home) {
|
||||
Write-Host "Installing Python" $python_version "for" $architecture "bit architecture to" $python_home
|
||||
if (Test-Path $python_home) {
|
||||
Write-Host $python_home "already exists, skipping."
|
||||
return $false
|
||||
}
|
||||
if ($architecture -eq "32") {
|
||||
$platform_suffix = ""
|
||||
} else {
|
||||
$platform_suffix = "amd64"
|
||||
}
|
||||
$installer_path = DownloadPython $python_version $platform_suffix
|
||||
$installer_ext = [System.IO.Path]::GetExtension($installer_path)
|
||||
Write-Host "Installing $installer_path to $python_home"
|
||||
$install_log = $python_home + ".log"
|
||||
if ($installer_ext -eq '.msi') {
|
||||
InstallPythonMSI $installer_path $python_home $install_log
|
||||
} else {
|
||||
InstallPythonEXE $installer_path $python_home $install_log
|
||||
}
|
||||
if (Test-Path $python_home) {
|
||||
Write-Host "Python $python_version ($architecture) installation complete"
|
||||
} else {
|
||||
Write-Host "Failed to install Python in $python_home"
|
||||
Get-Content -Path $install_log
|
||||
Exit 1
|
||||
}
|
||||
}
|
||||
|
||||
|
||||
function InstallPythonEXE ($exepath, $python_home, $install_log) {
|
||||
$install_args = "/quiet InstallAllUsers=1 TargetDir=$python_home"
|
||||
RunCommand $exepath $install_args
|
||||
}
|
||||
|
||||
|
||||
function InstallPythonMSI ($msipath, $python_home, $install_log) {
|
||||
$install_args = "/qn /log $install_log /i $msipath TARGETDIR=$python_home"
|
||||
$uninstall_args = "/qn /x $msipath"
|
||||
RunCommand "msiexec.exe" $install_args
|
||||
if (-not(Test-Path $python_home)) {
|
||||
Write-Host "Python seems to be installed else-where, reinstalling."
|
||||
RunCommand "msiexec.exe" $uninstall_args
|
||||
RunCommand "msiexec.exe" $install_args
|
||||
}
|
||||
}
|
||||
|
||||
function RunCommand ($command, $command_args) {
|
||||
Write-Host $command $command_args
|
||||
Start-Process -FilePath $command -ArgumentList $command_args -Wait -Passthru
|
||||
}
|
||||
|
||||
|
||||
function InstallPip ($python_home) {
|
||||
$pip_path = $python_home + "\Scripts\pip.exe"
|
||||
$python_path = $python_home + "\python.exe"
|
||||
if (-not(Test-Path $pip_path)) {
|
||||
Write-Host "Installing pip..."
|
||||
$webclient = New-Object System.Net.WebClient
|
||||
$webclient.DownloadFile($GET_PIP_URL, $GET_PIP_PATH)
|
||||
Write-Host "Executing:" $python_path $GET_PIP_PATH
|
||||
& $python_path $GET_PIP_PATH
|
||||
} else {
|
||||
Write-Host "pip already installed."
|
||||
}
|
||||
}
|
||||
|
||||
|
||||
function DownloadMiniconda ($python_version, $platform_suffix) {
|
||||
if ($python_version -eq "3.4") {
|
||||
$filename = "Miniconda3-3.5.5-Windows-" + $platform_suffix + ".exe"
|
||||
} else {
|
||||
$filename = "Miniconda-3.5.5-Windows-" + $platform_suffix + ".exe"
|
||||
}
|
||||
$url = $MINICONDA_URL + $filename
|
||||
$filepath = Download $filename $url
|
||||
return $filepath
|
||||
}
|
||||
|
||||
|
||||
function InstallMiniconda ($python_version, $architecture, $python_home) {
|
||||
Write-Host "Installing Python" $python_version "for" $architecture "bit architecture to" $python_home
|
||||
if (Test-Path $python_home) {
|
||||
Write-Host $python_home "already exists, skipping."
|
||||
return $false
|
||||
}
|
||||
if ($architecture -eq "32") {
|
||||
$platform_suffix = "x86"
|
||||
} else {
|
||||
$platform_suffix = "x86_64"
|
||||
}
|
||||
$filepath = DownloadMiniconda $python_version $platform_suffix
|
||||
Write-Host "Installing" $filepath "to" $python_home
|
||||
$install_log = $python_home + ".log"
|
||||
$args = "/S /D=$python_home"
|
||||
Write-Host $filepath $args
|
||||
Start-Process -FilePath $filepath -ArgumentList $args -Wait -Passthru
|
||||
if (Test-Path $python_home) {
|
||||
Write-Host "Python $python_version ($architecture) installation complete"
|
||||
} else {
|
||||
Write-Host "Failed to install Python in $python_home"
|
||||
Get-Content -Path $install_log
|
||||
Exit 1
|
||||
}
|
||||
}
|
||||
|
||||
|
||||
function InstallMinicondaPip ($python_home) {
|
||||
$pip_path = $python_home + "\Scripts\pip.exe"
|
||||
$conda_path = $python_home + "\Scripts\conda.exe"
|
||||
if (-not(Test-Path $pip_path)) {
|
||||
Write-Host "Installing pip..."
|
||||
$args = "install --yes pip"
|
||||
Write-Host $conda_path $args
|
||||
Start-Process -FilePath "$conda_path" -ArgumentList $args -Wait -Passthru
|
||||
} else {
|
||||
Write-Host "pip already installed."
|
||||
}
|
||||
}
|
||||
|
||||
function main () {
|
||||
InstallPython $env:PYTHON_VERSION $env:PYTHON_ARCH $env:PYTHON
|
||||
InstallPip $env:PYTHON
|
||||
}
|
||||
|
||||
main
|
||||
56
appveyor.yml
Normal file
@@ -0,0 +1,56 @@
|
||||
# AppVeyor.yml from https://github.com/ogrisel/python-appveyor-demo
|
||||
# License: CC0 1.0 Universal: http://creativecommons.org/publicdomain/zero/1.0/
|
||||
|
||||
build: off
|
||||
|
||||
environment:
|
||||
matrix:
|
||||
- PYTHON: "C:\\Python27-x64"
|
||||
PYTHON_VERSION: "2.7.x"
|
||||
PYTHON_ARCH: "64"
|
||||
TOXENV: "py27"
|
||||
|
||||
- PYTHON: "C:\\Python33-x64"
|
||||
PYTHON_VERSION: "3.3.x"
|
||||
PYTHON_ARCH: "64"
|
||||
TOXENV: "py33"
|
||||
|
||||
- PYTHON: "C:\\Python34-x64"
|
||||
PYTHON_VERSION: "3.4.x"
|
||||
PYTHON_ARCH: "64"
|
||||
TOXENV: "py34"
|
||||
|
||||
- PYTHON: "C:\\Python35-x64"
|
||||
PYTHON_VERSION: "3.5.x"
|
||||
PYTHON_ARCH: "64"
|
||||
TOXENV: "py35"
|
||||
|
||||
- PYTHON: "C:\\Python36-x64"
|
||||
PYTHON_VERSION: "3.6.x"
|
||||
PYTHON_ARCH: "64"
|
||||
TOXENV: "py36"
|
||||
|
||||
install:
|
||||
# Install Python (from the official .msi of http://python.org) and pip when
|
||||
# not already installed.
|
||||
- ps: if (-not(Test-Path($env:PYTHON))) { & _appveyor\install.ps1 }
|
||||
|
||||
# Prepend newly installed Python to the PATH of this build (this cannot be
|
||||
# done from inside the powershell script as it would require to restart
|
||||
# the parent CMD process).
|
||||
- "SET PATH=%PYTHON%;%PYTHON%\\Scripts;%PATH%"
|
||||
|
||||
# Check that we have the expected version and architecture for Python
|
||||
- "python --version"
|
||||
- "python -c \"import struct; print(struct.calcsize('P') * 8)\""
|
||||
|
||||
# Upgrade to the latest version of pip to avoid it displaying warnings
|
||||
# about it being out of date.
|
||||
- "pip install --disable-pip-version-check --user --upgrade pip"
|
||||
- "C:\\MinGW\\bin\\mingw32-make"
|
||||
|
||||
test_script:
|
||||
- "C:\\MinGW\\bin\\mingw32-make coverage"
|
||||
|
||||
on_success:
|
||||
- "codecov -f coverage.xml"
|
||||
@@ -1 +0,0 @@
|
||||
|
||||
177
docs/_static/custom.css
vendored
@@ -1,177 +0,0 @@
|
||||
body > div.document > div.sphinxsidebar > div > form > table > tbody > tr:nth-child(2) > td > select {
|
||||
width: 100%!important;
|
||||
}
|
||||
|
||||
#python27 > a {
|
||||
color: white;
|
||||
}
|
||||
|
||||
/* Carbon by BuySellAds */
|
||||
#carbonads {
|
||||
display: block;
|
||||
overflow: hidden;
|
||||
margin: 1.5em 0 2em;
|
||||
padding: 1em;
|
||||
border: solid 1px #cccccc;
|
||||
border-radius: 2px;
|
||||
background-color: #eeeeee;
|
||||
text-align: center;
|
||||
line-height: 1.5;
|
||||
}
|
||||
|
||||
#carbonads a {
|
||||
border-bottom: 0;
|
||||
}
|
||||
|
||||
#carbonads span {
|
||||
display: block;
|
||||
overflow: hidden;
|
||||
}
|
||||
|
||||
.carbon-img {
|
||||
display: block;
|
||||
margin: 0 auto 1em;
|
||||
text-align: center;
|
||||
}
|
||||
|
||||
.carbon-text {
|
||||
display: block;
|
||||
margin-bottom: 1em;
|
||||
}
|
||||
|
||||
.carbon-poweredby {
|
||||
display: block;
|
||||
text-transform: uppercase;
|
||||
letter-spacing: 1px;
|
||||
font-size: 10px;
|
||||
line-height: 1;
|
||||
}
|
||||
|
||||
|
||||
/* Native CPC by BuySellAds */
|
||||
|
||||
#native-ribbon #_custom_ {
|
||||
position: fixed;
|
||||
right: 0;
|
||||
bottom: 0;
|
||||
left: 0;
|
||||
box-shadow: 0 -1px 4px 1px hsla(0, 0%, 0%, .15);
|
||||
font-family: -apple-system, BlinkMacSystemFont, "Segoe UI", Roboto, Oxygen-Sans, Ubuntu,
|
||||
Cantarell, "Helvetica Neue", Helvetica, Arial, sans-serif;
|
||||
transition: all .25s ease-in-out;
|
||||
transform: translateY(calc(100% - 35px));
|
||||
|
||||
flex-flow: column nowrap;
|
||||
}
|
||||
|
||||
#native-ribbon #_custom_:hover {
|
||||
transform: translateY(0);
|
||||
}
|
||||
|
||||
.native-img {
|
||||
margin-right: 20px;
|
||||
max-height: 50px;
|
||||
border-radius: 3px;
|
||||
}
|
||||
|
||||
.native-sponsor {
|
||||
margin: 10px 20px;
|
||||
text-align: center;
|
||||
text-transform: uppercase;
|
||||
letter-spacing: .5px;
|
||||
font-size: 12px;
|
||||
transition: all .3s ease-in-out;
|
||||
transform-origin: left;
|
||||
}
|
||||
|
||||
#native-ribbon #_custom_:hover .native-sponsor {
|
||||
margin: 0 20px;
|
||||
opacity: 0;
|
||||
transform: scaleY(0);
|
||||
}
|
||||
|
||||
.native-flex {
|
||||
display: flex;
|
||||
padding: 10px 20px 25px;
|
||||
text-decoration: none;
|
||||
|
||||
flex-flow: row nowrap;
|
||||
justify-content: center;
|
||||
align-items: center;
|
||||
}
|
||||
|
||||
.native-main {
|
||||
display: flex;
|
||||
|
||||
flex-flow: row nowrap;
|
||||
align-items: center;
|
||||
}
|
||||
|
||||
.native-details {
|
||||
display: flex;
|
||||
margin-right: 30px;
|
||||
|
||||
flex-flow: column nowrap;
|
||||
}
|
||||
|
||||
.native-company {
|
||||
margin-bottom: 4px;
|
||||
text-transform: uppercase;
|
||||
letter-spacing: 2px;
|
||||
font-size: 10px;
|
||||
}
|
||||
|
||||
.native-desc {
|
||||
letter-spacing: 1px;
|
||||
font-weight: 300;
|
||||
font-size: 14px;
|
||||
line-height: 1.4;
|
||||
}
|
||||
|
||||
.native-cta {
|
||||
padding: 10px 14px;
|
||||
border-radius: 3px;
|
||||
box-shadow: 0 6px 13px 0 hsla(0, 0%, 0%, .15);
|
||||
text-transform: uppercase;
|
||||
white-space: nowrap;
|
||||
letter-spacing: 1px;
|
||||
font-weight: 400;
|
||||
font-size: 12px;
|
||||
transition: all .3s ease-in-out;
|
||||
transform: translateY(-1px);
|
||||
}
|
||||
|
||||
.native-cta:hover {
|
||||
box-shadow: none;
|
||||
transform: translateY(1px);
|
||||
}
|
||||
|
||||
@media only screen and (min-width: 320px) and (max-width: 759px) {
|
||||
.native-flex {
|
||||
padding: 5px 5px 15px;
|
||||
flex-direction: column;
|
||||
|
||||
flex-wrap: wrap;
|
||||
}
|
||||
|
||||
.native-img {
|
||||
margin: 0;
|
||||
display: none;
|
||||
}
|
||||
|
||||
.native-details {
|
||||
margin: 0;
|
||||
}
|
||||
|
||||
.native-main {
|
||||
flex-direction: column;
|
||||
text-align: left;
|
||||
|
||||
flex-wrap: wrap;
|
||||
align-content: center;
|
||||
}
|
||||
|
||||
.native-cta {
|
||||
display: none;
|
||||
}
|
||||
}
|
||||
116
docs/_static/konami.js
vendored
Normal file
@@ -0,0 +1,116 @@
|
||||
/*
|
||||
* Konami-JS ~
|
||||
* :: Now with support for touch events and multiple instances for
|
||||
* :: those situations that call for multiple easter eggs!
|
||||
* Code: http://konami-js.googlecode.com/
|
||||
* Examples: http://www.snaptortoise.com/konami-js
|
||||
* Copyright (c) 2009 George Mandis (georgemandis.com, snaptortoise.com)
|
||||
* Version: 1.4.2 (9/2/2013)
|
||||
* Licensed under the MIT License (http://opensource.org/licenses/MIT)
|
||||
* Tested in: Safari 4+, Google Chrome 4+, Firefox 3+, IE7+, Mobile Safari 2.2.1 and Dolphin Browser
|
||||
*/
|
||||
|
||||
var Konami = function (callback) {
|
||||
var konami = {
|
||||
addEvent: function (obj, type, fn, ref_obj) {
|
||||
if (obj.addEventListener)
|
||||
obj.addEventListener(type, fn, false);
|
||||
else if (obj.attachEvent) {
|
||||
// IE
|
||||
obj["e" + type + fn] = fn;
|
||||
obj[type + fn] = function () {
|
||||
obj["e" + type + fn](window.event, ref_obj);
|
||||
};
|
||||
obj.attachEvent("on" + type, obj[type + fn]);
|
||||
}
|
||||
},
|
||||
input: "",
|
||||
pattern: "38384040373937396665",
|
||||
load: function (link) {
|
||||
this.addEvent(document, "keydown", function (e, ref_obj) {
|
||||
if (ref_obj) konami = ref_obj; // IE
|
||||
konami.input += e ? e.keyCode : event.keyCode;
|
||||
if (konami.input.length > konami.pattern.length)
|
||||
konami.input = konami.input.substr((konami.input.length - konami.pattern.length));
|
||||
if (konami.input == konami.pattern) {
|
||||
konami.code(link);
|
||||
konami.input = "";
|
||||
e.preventDefault();
|
||||
return false;
|
||||
}
|
||||
}, this);
|
||||
this.iphone.load(link);
|
||||
},
|
||||
code: function (link) {
|
||||
window.location = link
|
||||
},
|
||||
iphone: {
|
||||
start_x: 0,
|
||||
start_y: 0,
|
||||
stop_x: 0,
|
||||
stop_y: 0,
|
||||
tapTolerance: 8,
|
||||
capture: false,
|
||||
orig_keys: "",
|
||||
keys: ["UP", "UP", "DOWN", "DOWN", "LEFT", "RIGHT", "LEFT", "RIGHT", "TAP", "TAP"],
|
||||
code: function (link) {
|
||||
konami.code(link);
|
||||
},
|
||||
touchCapture: function(evt) {
|
||||
konami.iphone.start_x = evt.changedTouches[0].pageX;
|
||||
konami.iphone.start_y = evt.changedTouches[0].pageY;
|
||||
konami.iphone.capture = true;
|
||||
},
|
||||
load: function (link) {
|
||||
this.orig_keys = this.keys;
|
||||
konami.addEvent(document, "touchmove", function (e) {
|
||||
if (e.touches.length == 1 && konami.iphone.capture == true) {
|
||||
var touch = e.touches[0];
|
||||
konami.iphone.stop_x = touch.pageX;
|
||||
konami.iphone.stop_y = touch.pageY;
|
||||
konami.iphone.check_direction();
|
||||
}
|
||||
});
|
||||
konami.addEvent(document, "touchend", function (evt) {
|
||||
konami.touchCapture(evt);
|
||||
konami.iphone.check_direction(link);
|
||||
}, false);
|
||||
konami.addEvent(document, "touchstart", function (evt) {
|
||||
konami.touchCapture(evt);
|
||||
});
|
||||
},
|
||||
check_direction: function (link) {
|
||||
var x_magnitude = Math.abs(this.start_x - this.stop_x);
|
||||
var y_magnitude = Math.abs(this.start_y - this.stop_y);
|
||||
var hasMoved = (x_magnitude > this.tapTolerance || y_magnitude > this.tapTolerance);
|
||||
var result;
|
||||
if (this.capture === true && hasMoved) {
|
||||
this.capture = false;
|
||||
var x = ((this.start_x - this.stop_x) < 0) ? "RIGHT" : "LEFT";
|
||||
var y = ((this.start_y - this.stop_y) < 0) ? "DOWN" : "UP";
|
||||
var result = (x_magnitude > y_magnitude) ? x : y;
|
||||
}
|
||||
else if (this.capture === false && !hasMoved) {
|
||||
result = (this.tap == true) ? "TAP" : result;
|
||||
result = "TAP";
|
||||
}
|
||||
if (result) {
|
||||
if (result == this.keys[0]) this.keys = this.keys.slice(1, this.keys.length);
|
||||
else this.keys = this.orig_keys;
|
||||
}
|
||||
if (this.keys.length == 0) {
|
||||
this.keys = this.orig_keys;
|
||||
this.code(link);
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
typeof callback === "string" && konami.load(callback);
|
||||
if (typeof callback === "function") {
|
||||
konami.code = callback;
|
||||
konami.load();
|
||||
}
|
||||
|
||||
return konami;
|
||||
};
|
||||
BIN
docs/_static/requests-logo-small.png
vendored
Normal file

|
After Width: | Height: | Size: 155 KiB |
78
docs/_templates/hacks.html
vendored
@@ -23,58 +23,32 @@
|
||||
/* Have code blocks escape the document right-margin. */
|
||||
div.highlight pre {margin-right: -30px;}
|
||||
}
|
||||
|
||||
</style>
|
||||
|
||||
<!-- Native CPC by BuySellAds -->
|
||||
|
||||
<script type="text/javascript" src="//m.servedby-buysellads.com/monetization.js"></script>
|
||||
|
||||
<div id="native-ribbon">
|
||||
</div>
|
||||
|
||||
<script>
|
||||
_bsa.init('custom', 'CK7D62JU', 'placement:pythonrequestsorg',
|
||||
{
|
||||
target: '#native-ribbon',
|
||||
template: `
|
||||
<div class="native-sponsor">Sponsored by ##company## — Learn More</div>
|
||||
<a href="##link##" class="native-flex">
|
||||
<style>
|
||||
#native-ribbon #_custom_ {
|
||||
background: linear-gradient(-30deg, ##backgroundColor##E5, ##backgroundColor##E5 45%, ##backgroundColor## 45%) #fff;
|
||||
}
|
||||
|
||||
.native-details,
|
||||
.native-sponsor,
|
||||
.native-bsa {
|
||||
color: ##textColor## !important;
|
||||
}
|
||||
|
||||
.native-details:hover {
|
||||
color: ##textColorHover## !important;
|
||||
}
|
||||
|
||||
.native-cta {
|
||||
color: ##ctaTextColor##;
|
||||
background-color: ##ctaBackgroundColor##;
|
||||
}
|
||||
|
||||
.native-cta:hover {
|
||||
color: ##ctaTextColorHover##;
|
||||
background-color: ##ctaBackgroundColorHover##;
|
||||
}
|
||||
</style>
|
||||
<div class="native-main">
|
||||
<img class="native-img" src="##logo##">
|
||||
<div class="native-details">
|
||||
<span class="native-company">##title##</span>
|
||||
<span class="native-desc">##description##</span>
|
||||
</div>
|
||||
</div>
|
||||
<span class="native-cta">##callToAction##</span>
|
||||
</a>
|
||||
</div>
|
||||
`
|
||||
}
|
||||
);
|
||||
<!-- Analytics tracking for Kenneth. -->
|
||||
<script type="text/javascript">
|
||||
var _gauges = _gauges || [];
|
||||
(function() {
|
||||
var t = document.createElement('script');
|
||||
t.type = 'text/javascript';
|
||||
t.async = true;
|
||||
t.id = 'gauges-tracker';
|
||||
t.setAttribute('data-site-id', '56ca7a57c88d9011080024dd');
|
||||
t.setAttribute('data-track-path', 'https://track.gaug.es/track.gif');
|
||||
t.src = 'https://d36ee2fcip1434.cloudfront.net/track.js';
|
||||
var s = document.getElementsByTagName('script')[0];
|
||||
s.parentNode.insertBefore(t, s);
|
||||
})();
|
||||
</script>
|
||||
|
||||
<!-- There are no more hacks. -->
|
||||
<!-- இڿڰۣ-ڰۣ— -->
|
||||
<!-- Love, Kenneth Reitz -->
|
||||
|
||||
<script src="{{ pathto('_static/', 1) }}/konami.js"></script>
|
||||
<script>
|
||||
var easter_egg = new Konami('http://fortunes.herokuapp.com/random/raw');
|
||||
</script>
|
||||
|
||||
<!-- That was not a hack. That was art. -->
|
||||
83
docs/_templates/sidebarintro.html
vendored
@@ -1,11 +1,11 @@
|
||||
<p class="logo">
|
||||
<a href="{{ pathto(master_doc) }}">
|
||||
<img class="logo" src="{{ pathto('_static/requests-sidebar.png', 1) }}" alt="Requests logo" />
|
||||
<img class="logo" src="{{ pathto('_static/requests-sidebar.png', 1) }}" title="https://kennethreitz.org/tattoos"/>
|
||||
</a>
|
||||
</p>
|
||||
|
||||
<p>
|
||||
<iframe src="https://ghbtns.com/github-btn.html?user=psf&repo=requests&type=watch&count=true&size=large"
|
||||
<iframe src="http://ghbtns.com/github-btn.html?user=kennethreitz&repo=requests&type=watch&count=true&size=large"
|
||||
allowtransparency="true" frameborder="0" scrolling="0" width="200px" height="35px"></iframe>
|
||||
</p>
|
||||
|
||||
@@ -14,24 +14,67 @@
|
||||
human beings.
|
||||
</p>
|
||||
|
||||
<h3>Useful Links</h3>
|
||||
|
||||
<h3>The Hitchhiker's Guide to Python</h3>
|
||||
|
||||
<p>This guide is now available in tangible book form!</p>
|
||||
|
||||
<a href="https://www.amazon.com/Hitchhikers-Guide-Python-Practices-Development/dp/1491933178/ref=as_li_ss_il?ie=UTF8&linkCode=li2&tag=bookforkind-20&linkId=804806ebdacaf3b56567347f3afbdbca" target="_blank"><img border="0" src="https://ws-na.amazon-adsystem.com/widgets/q?_encoding=UTF8&ASIN=1491933178&Format=_SL160_&ID=AsinImage&MarketPlace=US&ServiceVersion=20070822&WS=1&tag=bookforkind-20" ></a><img src="//ir-na.amazon-adsystem.com/e/ir?t=bookforkind-20&l=li2&o=1&a=1491933178" width="1" height="1" border="0" alt="" style="border:none !important; margin:0px !important;" />
|
||||
|
||||
<p>All proceeds are being directly donated to the <a href="https://djangogirls.org">DjangoGirls</a> organization.</p>
|
||||
|
||||
|
||||
|
||||
<h3>Stay Informed</h3>
|
||||
<p>Receive updates on new releases and upcoming projects.</p>
|
||||
|
||||
<p><iframe src="http://ghbtns.com/github-btn.html?user=kennethreitz&type=follow&count=false"
|
||||
allowtransparency="true" frameborder="0" scrolling="0" width="200" height="20"></iframe></p>
|
||||
|
||||
<p><a href="https://twitter.com/kennethreitz" class="twitter-follow-button" data-show-count="false">Follow @kennethreitz</a> <script>!function(d,s,id){var js,fjs=d.getElementsByTagName(s)[0],p=/^http:/.test(d.location)?'http':'https';if(!d.getElementById(id)){js=d.createElement(s);js.id=id;js.src=p+'://platform.twitter.com/widgets.js';fjs.parentNode.insertBefore(js,fjs);}}(document, 'script', 'twitter-wjs');</script></p>
|
||||
<p><a href="https://saythanks.io/to/kennethreitz">Say Thanks!</a></p>
|
||||
<p><a href="http://tinyletter.com/kennethreitz">Join Mailing List</a>.</p>
|
||||
|
||||
|
||||
<h3>Other Projects</h3>
|
||||
|
||||
<p>More <a href="http://kennethreitz.org/">Kenneth Reitz</a> projects:</p>
|
||||
<ul>
|
||||
<li><a href="{{ pathto('user/quickstart') }}">Quickstart</a></li>
|
||||
<li><a href="{{ pathto('user/advanced') }}">Advanced Usage</a></li>
|
||||
<li><a href="{{ pathto('api') }}">API Reference</a></li>
|
||||
<li><a href="{{ pathto('community/updates') + '#release-history' }}">Release History</a></li>
|
||||
<li><a href="{{ pathto('dev/contributing') }}">Contributors Guide</a></li>
|
||||
|
||||
<p></p>
|
||||
|
||||
<li><a href="{{ pathto('community/recommended') }}">Recommended Packages and Extensions</a></li>
|
||||
|
||||
<p></p>
|
||||
|
||||
<li><a href="https://github.com/psf/requests">Requests @ GitHub</a></li>
|
||||
<li><a href="https://pypi.org/project/requests/">Requests @ PyPI</a></li>
|
||||
<li><a href="https://github.com/psf/requests/issues">Issue Tracker</a></li>
|
||||
<li><a href="http://edmsynths.com/">edmsynths.com</a></li>
|
||||
<li><a href="http://pipenv.org/">pipenv</a></li>
|
||||
<li><a href="http://pep8.org/">pep8.org</a></li>
|
||||
<li><a href="http://httpbin.org/">httpbin.org</a></li>
|
||||
<li><a href="http://python-guide.org">The Python Guide</a></li>
|
||||
<li><a href="https://github.com/kennethreitz/maya">Maya: Datetimes for Humans</a></li>
|
||||
<li><a href="https://github.com/kennethreitz/records">Records: SQL for Humans</a></li>
|
||||
<li><a href="http://www.git-legit.org">Legit: Git for Humans</a></li>
|
||||
<li><a href="http://docs.python-tablib.org/en/latest/">Tablib: Tabular Datasets</a></li>
|
||||
</ul>
|
||||
|
||||
|
||||
<h3>Useful Links</h3>
|
||||
<ul>
|
||||
<li><a href="http://docs.python-requests.org/en/latest/community/recommended/">Recommended Packages and Extensions</a></li>
|
||||
|
||||
<p></p>
|
||||
|
||||
<li><a href="http://github.com/requests/requests">Requests @ GitHub</a></li>
|
||||
<li><a href="http://pypi.python.org/pypi/requests">Requests @ PyPI</a></li>
|
||||
<li><a href="http://github.com/requests/requests/issues">Issue Tracker</a></li>
|
||||
<li><a href="http://docs.python-requests.org/en/latest/community/updates/#software-updates">Release History</a></li>
|
||||
</ul>
|
||||
|
||||
|
||||
<h3>Translations</h3>
|
||||
|
||||
<ul>
|
||||
<li><a href="http://docs.python-requests.org/">English</a></li>
|
||||
<li><a href="http://fr.python-requests.org/">French</a></li>
|
||||
<li><a href="http://de.python-requests.org/">German</a></li>
|
||||
<li><a href="http://jp.python-requests.org/">Japanese</a></li>
|
||||
<li><a href="http://cn.python-requests.org/">Chinese</a></li>
|
||||
<li><a href="http://pt.python-requests.org/">Portuguese</a></li>
|
||||
<li><a href="http://it.python-requests.org/">Italian</a></li>
|
||||
<li><a href="http://es.python-requests.org/">Spanish</a></li>
|
||||
</ul>
|
||||
|
||||
<div id="native-ribbon">
|
||||
</div>
|
||||
|
||||
75
docs/_templates/sidebarlogo.html
vendored
@@ -1,6 +1,11 @@
|
||||
<p class="logo">
|
||||
<a href="{{ pathto(master_doc) }}">
|
||||
<img class="logo" src="{{ pathto('_static/requests-sidebar.png', 1) }}" title="https://kennethreitz.org/tattoos"/>
|
||||
</a>
|
||||
</p>
|
||||
<p>
|
||||
<iframe src="https://ghbtns.com/github-btn.html?user=psf&repo=requests&type=watch&count=true&size=large"
|
||||
allowtransparency="true" frameborder="0" scrolling="0" width="200px" height="35px"></iframe>
|
||||
<iframe src="http://ghbtns.com/github-btn.html?user=kennethreitz&repo=requests&type=watch&count=true&size=large"
|
||||
allowtransparency="true" frameborder="0" scrolling="0" width="200px" height="35px"></iframe>
|
||||
</p>
|
||||
|
||||
<p>
|
||||
@@ -9,22 +14,56 @@
|
||||
development release.
|
||||
</p>
|
||||
|
||||
<h3>Useful Links</h3>
|
||||
<h3>Stay Informed</h3>
|
||||
<p>Receive updates on new releases and upcoming projects.</p>
|
||||
|
||||
<p><a href="http://tinyletter.com/kennethreitz">Join Mailing List</a>.</p>
|
||||
|
||||
<hr/>
|
||||
|
||||
<h3>The Hitchhiker's Guide to Python</h3>
|
||||
|
||||
<p>This guide is now available in tangible book form!</p>
|
||||
|
||||
<a href="https://www.amazon.com/Hitchhikers-Guide-Python-Practices-Development/dp/1491933178/ref=as_li_ss_il?ie=UTF8&linkCode=li2&tag=bookforkind-20&linkId=804806ebdacaf3b56567347f3afbdbca" target="_blank"><img border="0" src="https://ws-na.amazon-adsystem.com/widgets/q?_encoding=UTF8&ASIN=1491933178&Format=_SL160_&ID=AsinImage&MarketPlace=US&ServiceVersion=20070822&WS=1&tag=bookforkind-20" ></a><img src="//ir-na.amazon-adsystem.com/e/ir?t=bookforkind-20&l=li2&o=1&a=1491933178" width="1" height="1" border="0" alt="" style="border:none !important; margin:0px !important;" />
|
||||
|
||||
<p>All proceeds are being directly donated to the <a href="https://djangogirls.org">DjangoGirls</a> organization.</p>
|
||||
|
||||
|
||||
<p>If you enjoy using this project, <a href="https://saythanks.io/to/kennethreitz">Say Thanks!</a></p>
|
||||
|
||||
<p><iframe src="http://ghbtns.com/github-btn.html?user=kennethreitz&type=follow&count=false"
|
||||
allowtransparency="true" frameborder="0" scrolling="0" width="200" height="20"></iframe></p>
|
||||
|
||||
<p><a href="https://twitter.com/kennethreitz" class="twitter-follow-button" data-show-count="false">Follow @kennethreitz</a> <script>!function(d,s,id){var js,fjs=d.getElementsByTagName(s)[0],p=/^http:/.test(d.location)?'http':'https';if(!d.getElementById(id)){js=d.createElement(s);js.id=id;js.src=p+'://platform.twitter.com/widgets.js';fjs.parentNode.insertBefore(js,fjs);}}(document, 'script', 'twitter-wjs');</script></p>
|
||||
|
||||
|
||||
<h3>Other Projects</h3>
|
||||
|
||||
<p>More <a href="http://kennethreitz.org/">Kenneth Reitz</a> projects:</p>
|
||||
<ul>
|
||||
<li><a href="{{ pathto('user/quickstart') }}">Quickstart</a></li>
|
||||
<li><a href="{{ pathto('user/advanced') }}">Advanced Usage</a></li>
|
||||
<li><a href="{{ pathto('api') }}">API Reference</a></li>
|
||||
<li><a href="{{ pathto('community/updates') + '#release-history' }}">Release History</a></li>
|
||||
<li><a href="{{ pathto('dev/contributing') }}">Contributors Guide</a></li>
|
||||
|
||||
<p></p>
|
||||
|
||||
<li><a href="{{ pathto('community/recommended') }}">Recommended Packages and Extensions</a></li>
|
||||
|
||||
<p></p>
|
||||
|
||||
<li><a href="https://github.com/psf/requests">Requests @ GitHub</a></li>
|
||||
<li><a href="https://pypi.org/project/requests/">Requests @ PyPI</a></li>
|
||||
<li><a href="https://github.com/psf/requests/issues">Issue Tracker</a></li>
|
||||
<li><a href="http://edmsynths.com/">edmsynths.com</a></li>
|
||||
<li><a href="http://pipenv.org/">pipenv</a></li>
|
||||
<li><a href="http://pep8.org/">pep8.org</a></li>
|
||||
<li><a href="http://httpbin.org/">httpbin.org</a></li>
|
||||
<li><a href="http://python-guide.org">The Python Guide</a></li>
|
||||
<li><a href="https://github.com/kennethreitz/maya">Maya: Datetimes for Humans</a></li>
|
||||
<li><a href="https://github.com/kennethreitz/records">Records: SQL for Humans</a></li>
|
||||
<li><a href="http://www.git-legit.org">Legit: Git for Humans</a></li>
|
||||
<li><a href="http://docs.python-tablib.org/en/latest/">Tablib: Tabular Datasets</a></li>
|
||||
</ul>
|
||||
|
||||
|
||||
<h3>Translations</h3>
|
||||
|
||||
<ul>
|
||||
<li><a href="http://docs.python-requests.org/">English</a></li>
|
||||
<li><a href="http://fr.python-requests.org/">French</a></li>
|
||||
<li><a href="http://de.python-requests.org/">German</a></li>
|
||||
<li><a href="http://jp.python-requests.org/">Japanese</a></li>
|
||||
<li><a href="http://cn.python-requests.org/">Chinese</a></li>
|
||||
<li><a href="http://pt.python-requests.org/">Portuguese</a></li>
|
||||
<li><a href="http://it.python-requests.org/">Italian</a></li>
|
||||
<li><a href="http://es.python-requests.org/">Spanish</a></li>
|
||||
</ul>
|
||||
|
||||
|
||||
29
docs/api.rst
@@ -36,7 +36,6 @@ Exceptions
|
||||
.. autoexception:: requests.ConnectTimeout
|
||||
.. autoexception:: requests.ReadTimeout
|
||||
.. autoexception:: requests.Timeout
|
||||
.. autoexception:: requests.JSONDecodeError
|
||||
|
||||
|
||||
Request Sessions
|
||||
@@ -110,7 +109,17 @@ Status Code Lookup
|
||||
|
||||
.. autoclass:: requests.codes
|
||||
|
||||
.. automodule:: requests.status_codes
|
||||
::
|
||||
|
||||
>>> requests.codes['temporary_redirect']
|
||||
307
|
||||
|
||||
>>> requests.codes.teapot
|
||||
418
|
||||
|
||||
>>> requests.codes['\o/']
|
||||
200
|
||||
|
||||
|
||||
|
||||
Migrating to 1.x
|
||||
@@ -128,7 +137,7 @@ API Changes
|
||||
::
|
||||
|
||||
import requests
|
||||
r = requests.get('https://api.github.com/events')
|
||||
r = requests.get('https://github.com/timeline.json')
|
||||
r.json() # This *call* raises an exception if JSON decoding fails
|
||||
|
||||
* The ``Session`` API has changed. Sessions objects no longer take parameters.
|
||||
@@ -140,7 +149,7 @@ API Changes
|
||||
s = requests.Session() # formerly, session took parameters
|
||||
s.auth = auth
|
||||
s.headers.update(headers)
|
||||
r = s.get('https://httpbin.org/headers')
|
||||
r = s.get('http://httpbin.org/headers')
|
||||
|
||||
* All request hooks have been removed except 'response'.
|
||||
|
||||
@@ -157,7 +166,7 @@ API Changes
|
||||
::
|
||||
|
||||
# in 0.x, passing prefetch=False would accomplish the same thing
|
||||
r = requests.get('https://api.github.com/events', stream=True)
|
||||
r = requests.get('https://github.com/timeline.json', stream=True)
|
||||
for chunk in r.iter_content(8192):
|
||||
...
|
||||
|
||||
@@ -182,11 +191,11 @@ API Changes
|
||||
|
||||
logging.basicConfig() # you need to initialize logging, otherwise you will not see anything from requests
|
||||
logging.getLogger().setLevel(logging.DEBUG)
|
||||
requests_log = logging.getLogger("urllib3")
|
||||
requests_log = logging.getLogger("requests.packages.urllib3")
|
||||
requests_log.setLevel(logging.DEBUG)
|
||||
requests_log.propagate = True
|
||||
|
||||
requests.get('https://httpbin.org/headers')
|
||||
requests.get('http://httpbin.org/headers')
|
||||
|
||||
|
||||
|
||||
@@ -198,8 +207,8 @@ license from the ISC_ license to the `Apache 2.0`_ license. The Apache 2.0
|
||||
license ensures that contributions to Requests are also covered by the Apache
|
||||
2.0 license.
|
||||
|
||||
.. _ISC: https://opensource.org/licenses/ISC
|
||||
.. _Apache 2.0: https://opensource.org/licenses/Apache-2.0
|
||||
.. _ISC: http://opensource.org/licenses/ISC
|
||||
.. _Apache 2.0: http://opensource.org/licenses/Apache-2.0
|
||||
|
||||
|
||||
Migrating to 2.x
|
||||
@@ -214,7 +223,7 @@ For more details on the changes in this release including new APIs, links
|
||||
to the relevant GitHub issues and some of the bug fixes, read Cory's blog_
|
||||
on the subject.
|
||||
|
||||
.. _blog: https://lukasa.co.uk/2013/09/Requests_20/
|
||||
.. _blog: http://lukasa.co.uk/2013/09/Requests_20/
|
||||
|
||||
|
||||
API Changes
|
||||
|
||||
@@ -11,9 +11,6 @@ Encoded Data?
|
||||
Requests automatically decompresses gzip-encoded responses, and does
|
||||
its best to decode response content to unicode when possible.
|
||||
|
||||
When either the `brotli <https://pypi.org/project/Brotli/>`_ or `brotlicffi <https://pypi.org/project/brotlicffi/>`_
|
||||
package is installed, requests also decodes Brotli-encoded responses.
|
||||
|
||||
You can get direct access to the raw response (and even the socket),
|
||||
if needed as well.
|
||||
|
||||
@@ -22,8 +19,7 @@ Custom User-Agents?
|
||||
-------------------
|
||||
|
||||
Requests allows you to easily override User-Agent strings, along with
|
||||
any other HTTP Header. See :ref:`documentation about headers <custom-headers>`.
|
||||
|
||||
any other HTTP Header.
|
||||
|
||||
|
||||
Why not Httplib2?
|
||||
@@ -55,17 +51,16 @@ Chris Adams gave an excellent summary on
|
||||
Python 3 Support?
|
||||
-----------------
|
||||
|
||||
Yes! Requests officially supports Python 3.8+ and PyPy.
|
||||
Yes! Here's a list of Python platforms that are officially
|
||||
supported:
|
||||
|
||||
Python 2 Support?
|
||||
-----------------
|
||||
|
||||
No! As of Requests 2.28.0, Requests no longer supports Python 2.7. Users who
|
||||
have been unable to migrate should pin to `requests<2.28`. Full information
|
||||
can be found in `psf/requests#6023 <https://github.com/psf/requests/issues/6023>`_.
|
||||
|
||||
It is *highly* recommended users migrate to Python 3.8+ now since Python
|
||||
2.7 is no longer receiving bug fixes or security updates as of January 1, 2020.
|
||||
* Python 2.6
|
||||
* Python 2.7
|
||||
* Python 3.3
|
||||
* Python 3.4
|
||||
* Python 3.5
|
||||
* Python 3.6
|
||||
* PyPy
|
||||
|
||||
What are "hostname doesn't match" errors?
|
||||
-----------------------------------------
|
||||
@@ -74,7 +69,7 @@ These errors occur when :ref:`SSL certificate verification <verification>`
|
||||
fails to match the certificate the server responds with to the hostname
|
||||
Requests thinks it's contacting. If you're certain the server's SSL setup is
|
||||
correct (for example, because you can visit the site with your browser) and
|
||||
you're using Python 2.7, a possible explanation is that you need
|
||||
you're using Python 2.6 or 2.7, a possible explanation is that you need
|
||||
Server-Name-Indication.
|
||||
|
||||
`Server-Name-Indication`_, or SNI, is an official extension to SSL where the
|
||||
@@ -83,7 +78,10 @@ when servers are using `Virtual Hosting`_. When such servers are hosting
|
||||
more than one SSL site they need to be able to return the appropriate
|
||||
certificate based on the hostname the client is connecting to.
|
||||
|
||||
Python 3 already includes native support for SNI in their SSL modules.
|
||||
Python3 and Python 2.7.9+ include native support for SNI in their SSL modules.
|
||||
For information on using SNI with Requests on Python < 2.7.9 refer to this
|
||||
`Stack Overflow answer`_.
|
||||
|
||||
.. _`Server-Name-Indication`: https://en.wikipedia.org/wiki/Server_Name_Indication
|
||||
.. _`virtual hosting`: https://en.wikipedia.org/wiki/Virtual_hosting
|
||||
.. _`Stack Overflow answer`: https://stackoverflow.com/questions/18578439/using-requests-with-tls-doesnt-give-sni-support/18579484#18579484
|
||||
|
||||
@@ -1,10 +1,22 @@
|
||||
Integrations
|
||||
============
|
||||
|
||||
Python for iOS
|
||||
--------------
|
||||
|
||||
Requests is built into the wonderful `Python for iOS <https://itunes.apple.com/us/app/python-2.7-for-ios/id485729872?mt=Python8>`_ runtime!
|
||||
|
||||
To give it a try, simply::
|
||||
|
||||
import requests
|
||||
|
||||
|
||||
Articles & Talks
|
||||
================
|
||||
- `Daniel Greenfeld's Review of Requests <https://pydanny.blogspot.com/2011/05/python-http-requests-for-humans.html>`_
|
||||
- `Issac Kelly's 'Consuming Web APIs' talk <https://issackelly.github.io/Consuming-Web-APIs-with-Python-Talk/slides/slides.html>`_
|
||||
- `Blog post about Requests via Yum <https://arunsag.wordpress.com/2011/08/17/new-package-python-requests-http-for-humans/>`_
|
||||
- `Russian blog post introducing Requests <https://habr.com/post/126262/>`_
|
||||
- `Python for the Web <http://gun.io/blog/python-for-the-web/>`_ teaches how to use Python to interact with the web, using Requests.
|
||||
- `Daniel Greenfeld's Review of Requests <http://pydanny.blogspot.com/2011/05/python-http-requests-for-humans.html>`_
|
||||
- `My 'Python for Humans' talk <http://python-for-humans.heroku.com>`_ ( `audio <http://codeconf.s3.amazonaws.com/2011/pycodeconf/talks/PyCodeConf2011%20-%20Kenneth%20Reitz.m4a>`_ )
|
||||
- `Issac Kelly's 'Consuming Web APIs' talk <http://issackelly.github.com/Consuming-Web-APIs-with-Python-Talk/slides/slides.html>`_
|
||||
- `Blog post about Requests via Yum <http://arunsag.wordpress.com/2011/08/17/new-package-python-requests-http-for-humans/>`_
|
||||
- `Russian blog post introducing Requests <http://habrahabr.ru/blogs/python/126262/>`_
|
||||
- `Sending JSON in Requests <http://www.coglib.com/~icordasc/blog/2014/11/sending-json-in-requests.html>`_
|
||||
|
||||
@@ -13,7 +13,7 @@ Certifi CA Bundle
|
||||
validating the trustworthiness of SSL certificates while verifying the
|
||||
identity of TLS hosts. It has been extracted from the Requests project.
|
||||
|
||||
.. _Certifi: https://github.com/certifi/python-certifi
|
||||
.. _Certifi: http://certifi.io/en/latest/
|
||||
|
||||
CacheControl
|
||||
------------
|
||||
@@ -32,15 +32,7 @@ but do not belong in Requests proper. This library is actively maintained
|
||||
by members of the Requests core team, and reflects the functionality most
|
||||
requested by users within the community.
|
||||
|
||||
.. _Requests-Toolbelt: https://toolbelt.readthedocs.io/en/latest/index.html
|
||||
|
||||
|
||||
Requests-Threads
|
||||
----------------
|
||||
|
||||
`Requests-Threads`_ is a Requests session that returns the amazing Twisted's awaitable Deferreds instead of Response objects. This allows the use of ``async``/``await`` keyword usage on Python 3, or Twisted's style of programming, if desired.
|
||||
|
||||
.. _Requests-Threads: https://github.com/requests/requests-threads
|
||||
.. _Requests-Toolbelt: http://toolbelt.readthedocs.io/en/latest/index.html
|
||||
|
||||
Requests-OAuthlib
|
||||
-----------------
|
||||
@@ -59,4 +51,7 @@ Betamax
|
||||
`Betamax`_ records your HTTP interactions so the NSA does not have to.
|
||||
A VCR imitation designed only for Python-Requests.
|
||||
|
||||
.. _betamax: https://github.com/betamaxpy/betamax
|
||||
.. _betamax: https://github.com/sigmavirus24/betamax
|
||||
|
||||
|
||||
|
||||
|
||||
@@ -17,18 +17,19 @@ Breaking changes are changes that break backwards compatibility with prior
|
||||
versions. If the project were to change the ``text`` attribute on a
|
||||
``Response`` object to a method, that would only happen in a Major release.
|
||||
|
||||
Major releases may also include miscellaneous bug fixes. The core developers of
|
||||
Requests are committed to providing a good user experience. This means we're
|
||||
also committed to preserving backwards compatibility as much as possible. Major
|
||||
releases will be infrequent and will need strong justifications before they are
|
||||
considered.
|
||||
Major releases may also include miscellaneous bug fixes and upgrades to
|
||||
vendored packages. The core developers of Requests are committed to providing
|
||||
a good user experience. This means we're also committed to preserving
|
||||
backwards compatibility as much as possible. Major releases will be infrequent
|
||||
and will need strong justifications before they are considered.
|
||||
|
||||
Minor Releases
|
||||
--------------
|
||||
|
||||
A minor release will not include breaking changes but may include miscellaneous
|
||||
bug fixes. If the previous version of Requests released was ``v10.2.7`` a minor
|
||||
release would be versioned as ``v10.3.0``.
|
||||
A minor release will not include breaking changes but may include
|
||||
miscellaneous bug fixes and upgrades to vendored packages. If the previous
|
||||
version of Requests released was ``v10.2.7`` a minor release would be
|
||||
versioned as ``v10.3.0``.
|
||||
|
||||
Minor releases will be backwards compatible with releases that have the same
|
||||
major version number. In other words, all versions that would start with
|
||||
|
||||
@@ -5,27 +5,47 @@ Support
|
||||
|
||||
If you have questions or issues about Requests, there are several options:
|
||||
|
||||
Stack Overflow
|
||||
--------------
|
||||
StackOverflow
|
||||
-------------
|
||||
|
||||
If your question does not contain sensitive (possibly proprietary)
|
||||
information or can be properly anonymized, please ask a question on
|
||||
`Stack Overflow <https://stackoverflow.com/questions/tagged/python-requests>`_
|
||||
`StackOverflow <https://stackoverflow.com/questions/tagged/python-requests>`_
|
||||
and use the tag ``python-requests``.
|
||||
|
||||
Send a Tweet
|
||||
------------
|
||||
|
||||
If your question is less than 140 characters, feel free to send a tweet to
|
||||
`@kennethreitz <https://twitter.com/kennethreitz>`_,
|
||||
`@sigmavirus24 <https://twitter.com/sigmavirus24>`_, or
|
||||
`@lukasaoz <https://twitter.com/lukasaoz>`_.
|
||||
|
||||
File an Issue
|
||||
-------------
|
||||
|
||||
If you notice some unexpected behaviour in Requests, or want to see support
|
||||
for a new feature,
|
||||
`file an issue on GitHub <https://github.com/psf/requests/issues>`_.
|
||||
`file an issue on GitHub <https://github.com/requests/requests/issues>`_.
|
||||
|
||||
|
||||
Send a Tweet
|
||||
------------
|
||||
E-mail
|
||||
------
|
||||
|
||||
If your question is less than 280 characters, feel free to send a tweet to
|
||||
`@nateprewitt <https://twitter.com/nateprewitt>`_,
|
||||
`@sethmlarson <https://twitter.com/sethmlarson>`_, or
|
||||
`@sigmavirus24 <https://twitter.com/sigmavirus24>`_.
|
||||
I'm more than happy to answer any personal or in-depth questions about
|
||||
Requests. Feel free to email
|
||||
`requests@kennethreitz.com <mailto:requests@kennethreitz.com>`_.
|
||||
|
||||
|
||||
IRC
|
||||
---
|
||||
|
||||
The official Freenode channel for Requests is
|
||||
`#python-requests <irc://irc.freenode.net/python-requests>`_
|
||||
|
||||
The core developers of requests are on IRC throughout the day.
|
||||
You can find them in ``#python-requests`` as:
|
||||
|
||||
- kennethreitz
|
||||
- lukasa
|
||||
- sigmavirus24
|
||||
|
||||
@@ -12,7 +12,19 @@ GitHub
|
||||
------
|
||||
|
||||
The best way to track the development of Requests is through
|
||||
`the GitHub repo <https://github.com/psf/requests>`_.
|
||||
`the GitHub repo <https://github.com/requests/requests>`_.
|
||||
|
||||
Twitter
|
||||
-------
|
||||
|
||||
The author, Kenneth Reitz, often tweets about new features and releases of Requests.
|
||||
|
||||
Follow `@kennethreitz <https://twitter.com/kennethreitz>`_ for updates.
|
||||
|
||||
|
||||
.. include:: ../../HISTORY.md
|
||||
|
||||
Release and Version History
|
||||
===========================
|
||||
|
||||
.. include:: ../../HISTORY.rst
|
||||
|
||||
|
||||
@@ -2,16 +2,14 @@ Vulnerability Disclosure
|
||||
========================
|
||||
|
||||
If you think you have found a potential security vulnerability in requests,
|
||||
please email `Nate <mailto:nate.prewitt@gmail.com>`_ and `Seth <mailto:@sethmichaellarson@gmail.com>`_ directly. **Do not file a public issue.**
|
||||
please email `sigmavirus24 <mailto:graffatcolmingov@gmail.com>`_ and
|
||||
`Lukasa <mailto:cory@lukasa.co.uk>`_ directly. **Do not file a public issue.**
|
||||
|
||||
Our PGP Key fingerprints are:
|
||||
|
||||
- 8722 7E29 AD9C FF5C FAC3 EA6A 44D3 FF97 B80D C864 (`@nateprewitt <https://keybase.io/nateprewitt>`_)
|
||||
- 0161 BB7E B208 B5E0 4FDC 9F81 D9DA 0A04 9113 F853 (@sigmavirus24)
|
||||
|
||||
- EDD5 6765 A9D8 4653 CBC8 A134 51B0 6736 1740 F5FC (`@sethmlarson <https://keybase.io/sethmlarson>`_)
|
||||
|
||||
You can also contact us on `Keybase <https://keybase.io/>`_ with the
|
||||
profiles above if desired.
|
||||
- 90DC AE40 FEA7 4B14 9B70 662D F25F 2144 EEC1 373D (@lukasa)
|
||||
|
||||
If English is not your first language, please try to describe the problem and
|
||||
its impact to the best of your ability. For greater detail, please use your
|
||||
@@ -72,7 +70,7 @@ time, to ensure that they are able to promptly release their downstream
|
||||
packages. Currently the list of people we actively contact *ahead of a public
|
||||
release* is:
|
||||
|
||||
- Python Maintenance Team, Red Hat (python-maint@redhat.com)
|
||||
- Jeremy Cline, Red Hat (@jeremycline)
|
||||
- Daniele Tricoli, Debian (@eriol)
|
||||
|
||||
We will notify these individuals at least a week ahead of our planned release
|
||||
@@ -95,16 +93,13 @@ if upgrading is not an option.
|
||||
Previous CVEs
|
||||
-------------
|
||||
|
||||
- Fixed in 2.20.0
|
||||
- `CVE 2018-18074 <https://cve.mitre.org/cgi-bin/cvename.cgi?name=2018-18074>`_
|
||||
|
||||
- Fixed in 2.6.0
|
||||
|
||||
- `CVE 2015-2296 <https://cve.mitre.org/cgi-bin/cvename.cgi?name=2015-2296>`_,
|
||||
- `CVE 2015-2296 <http://www.cve.mitre.org/cgi-bin/cvename.cgi?name=2015-2296>`_,
|
||||
reported by Matthew Daley of `BugFuzz <https://bugfuzz.com/>`_.
|
||||
|
||||
- Fixed in 2.3.0
|
||||
|
||||
- `CVE 2014-1829 <https://cve.mitre.org/cgi-bin/cvename.cgi?name=2014-1829>`_
|
||||
- `CVE 2014-1829 <http://www.cve.mitre.org/cgi-bin/cvename.cgi?name=2014-1829>`_
|
||||
|
||||
- `CVE 2014-1830 <https://cve.mitre.org/cgi-bin/cvename.cgi?name=2014-1830>`_
|
||||
- `CVE 2014-1830 <http://www.cve.mitre.org/cgi-bin/cvename.cgi?name=2014-1830>`_
|
||||
|
||||
210
docs/conf.py
@@ -18,11 +18,11 @@ import os
|
||||
# If extensions (or modules to document with autodoc) are in another directory,
|
||||
# add these directories to sys.path here. If the directory is relative to the
|
||||
# documentation root, use os.path.abspath to make it absolute, like shown here.
|
||||
# sys.path.insert(0, os.path.abspath('.'))
|
||||
#sys.path.insert(0, os.path.abspath('.'))
|
||||
|
||||
# Insert Requests' path into the system.
|
||||
sys.path.insert(0, os.path.abspath(".."))
|
||||
sys.path.insert(0, os.path.abspath("_themes"))
|
||||
sys.path.insert(0, os.path.abspath('..'))
|
||||
sys.path.insert(0, os.path.abspath('_themes'))
|
||||
|
||||
import requests
|
||||
|
||||
@@ -30,36 +30,36 @@ import requests
|
||||
# -- General configuration ------------------------------------------------
|
||||
|
||||
# If your documentation needs a minimal Sphinx version, state it here.
|
||||
# needs_sphinx = '1.0'
|
||||
#needs_sphinx = '1.0'
|
||||
|
||||
# Add any Sphinx extension module names here, as strings. They can be
|
||||
# extensions coming with Sphinx (named 'sphinx.ext.*') or your custom
|
||||
# ones.
|
||||
extensions = [
|
||||
"sphinx.ext.autodoc",
|
||||
"sphinx.ext.intersphinx",
|
||||
"sphinx.ext.todo",
|
||||
"sphinx.ext.viewcode",
|
||||
'sphinx.ext.autodoc',
|
||||
'sphinx.ext.intersphinx',
|
||||
'sphinx.ext.todo',
|
||||
'sphinx.ext.viewcode',
|
||||
]
|
||||
|
||||
# Add any paths that contain templates here, relative to this directory.
|
||||
templates_path = ["_templates"]
|
||||
templates_path = ['_templates']
|
||||
|
||||
# The suffix(es) of source filenames.
|
||||
# You can specify multiple suffix as a list of string:
|
||||
# source_suffix = ['.rst', '.md']
|
||||
source_suffix = ".rst"
|
||||
source_suffix = '.rst'
|
||||
|
||||
# The encoding of source files.
|
||||
# source_encoding = 'utf-8-sig'
|
||||
#source_encoding = 'utf-8-sig'
|
||||
|
||||
# The master toctree document.
|
||||
master_doc = "index"
|
||||
master_doc = 'index'
|
||||
|
||||
# General information about the project.
|
||||
project = u"Requests"
|
||||
copyright = u'MMXVIX. A <a href="https://kenreitz.org/projects">Kenneth Reitz</a> Project'
|
||||
author = u"Kenneth Reitz"
|
||||
project = u'Requests'
|
||||
copyright = u'MMXVII. A <a href="http://kennethreitz.com/pages/open-projects.html">Kenneth Reitz</a> Project'
|
||||
author = u'Kenneth Reitz'
|
||||
|
||||
# The version info for the project you're documenting, acts as replacement for
|
||||
# |version| and |release|, also used in various other places throughout the
|
||||
@@ -79,17 +79,17 @@ language = None
|
||||
|
||||
# There are two options for replacing |today|: either, you set today to some
|
||||
# non-false value, then it is used:
|
||||
# today = ''
|
||||
#today = ''
|
||||
# Else, today_fmt is used as the format for a strftime call.
|
||||
# today_fmt = '%B %d, %Y'
|
||||
#today_fmt = '%B %d, %Y'
|
||||
|
||||
# List of patterns, relative to source directory, that match files and
|
||||
# directories to ignore when looking for source files.
|
||||
exclude_patterns = ["_build"]
|
||||
exclude_patterns = ['_build']
|
||||
|
||||
# The reST default role (used for this markup: `text`) to use for all
|
||||
# documents.
|
||||
# default_role = None
|
||||
#default_role = None
|
||||
|
||||
# If true, '()' will be appended to :func: etc. cross-reference text.
|
||||
add_function_parentheses = False
|
||||
@@ -100,16 +100,16 @@ add_module_names = True
|
||||
|
||||
# If true, sectionauthor and moduleauthor directives will be shown in the
|
||||
# output. They are ignored by default.
|
||||
# show_authors = False
|
||||
#show_authors = False
|
||||
|
||||
# The name of the Pygments (syntax highlighting) style to use.
|
||||
pygments_style = "flask_theme_support.FlaskyStyle"
|
||||
pygments_style = 'flask_theme_support.FlaskyStyle'
|
||||
|
||||
# A list of ignored prefixes for module index sorting.
|
||||
# modindex_common_prefix = []
|
||||
#modindex_common_prefix = []
|
||||
|
||||
# If true, keep warnings as "system message" paragraphs in the built documents.
|
||||
# keep_warnings = False
|
||||
#keep_warnings = False
|
||||
|
||||
# If true, `todo` and `todoList` produce output, else they produce nothing.
|
||||
todo_include_todos = True
|
||||
@@ -119,52 +119,51 @@ todo_include_todos = True
|
||||
|
||||
# The theme to use for HTML and HTML Help pages. See the documentation for
|
||||
# a list of builtin themes.
|
||||
html_theme = "alabaster"
|
||||
html_theme = 'alabaster'
|
||||
|
||||
# Theme options are theme-specific and customize the look and feel of a theme
|
||||
# further. For a list of options available for each theme, see the
|
||||
# documentation.
|
||||
html_theme_options = {
|
||||
"show_powered_by": False,
|
||||
"github_user": "requests",
|
||||
"github_repo": "requests",
|
||||
"github_banner": True,
|
||||
"show_related": False,
|
||||
"note_bg": "#FFF59C",
|
||||
'show_powered_by': False,
|
||||
'github_user': 'kennethreitz',
|
||||
'github_repo': 'requests',
|
||||
'github_banner': True,
|
||||
'show_related': False
|
||||
}
|
||||
|
||||
# Add any paths that contain custom themes here, relative to this directory.
|
||||
# html_theme_path = []
|
||||
#html_theme_path = []
|
||||
|
||||
# The name for this set of Sphinx documents. If None, it defaults to
|
||||
# "<project> v<release> documentation".
|
||||
# html_title = None
|
||||
#html_title = None
|
||||
|
||||
# A shorter title for the navigation bar. Default is the same as html_title.
|
||||
# html_short_title = None
|
||||
#html_short_title = None
|
||||
|
||||
# The name of an image file (relative to this directory) to place at the top
|
||||
# of the sidebar.
|
||||
# html_logo = None
|
||||
#html_logo = None
|
||||
|
||||
# The name of an image file (within the static path) to use as favicon of the
|
||||
# docs. This file should be a Windows icon file (.ico) being 16x16 or 32x32
|
||||
# pixels large.
|
||||
# html_favicon = None
|
||||
#html_favicon = None
|
||||
|
||||
# Add any paths that contain custom static files (such as style sheets) here,
|
||||
# relative to this directory. They are copied after the builtin static files,
|
||||
# so a file named "default.css" will overwrite the builtin "default.css".
|
||||
html_static_path = ["_static"]
|
||||
html_static_path = ['_static']
|
||||
|
||||
# Add any extra paths that contain custom files (such as robots.txt or
|
||||
# .htaccess) here, relative to this directory. These files are copied
|
||||
# directly to the root of the documentation.
|
||||
# html_extra_path = []
|
||||
#html_extra_path = []
|
||||
|
||||
# If not '', a 'Last updated on:' timestamp is inserted at every page bottom,
|
||||
# using the given strftime format.
|
||||
# html_last_updated_fmt = '%b %d, %Y'
|
||||
#html_last_updated_fmt = '%b %d, %Y'
|
||||
|
||||
# If true, SmartyPants will be used to convert quotes and dashes to
|
||||
# typographically correct entities.
|
||||
@@ -172,29 +171,24 @@ html_use_smartypants = False
|
||||
|
||||
# Custom sidebar templates, maps document names to template names.
|
||||
html_sidebars = {
|
||||
"index": ["sidebarintro.html", "sourcelink.html", "searchbox.html", "hacks.html"],
|
||||
"**": [
|
||||
"sidebarlogo.html",
|
||||
"localtoc.html",
|
||||
"relations.html",
|
||||
"sourcelink.html",
|
||||
"searchbox.html",
|
||||
"hacks.html",
|
||||
],
|
||||
'index': ['sidebarintro.html', 'sourcelink.html', 'searchbox.html',
|
||||
'hacks.html'],
|
||||
'**': ['sidebarlogo.html', 'localtoc.html', 'relations.html',
|
||||
'sourcelink.html', 'searchbox.html', 'hacks.html']
|
||||
}
|
||||
|
||||
# Additional templates that should be rendered to pages, maps page names to
|
||||
# template names.
|
||||
# html_additional_pages = {}
|
||||
#html_additional_pages = {}
|
||||
|
||||
# If false, no module index is generated.
|
||||
# html_domain_indices = True
|
||||
#html_domain_indices = True
|
||||
|
||||
# If false, no index is generated.
|
||||
# html_use_index = True
|
||||
#html_use_index = True
|
||||
|
||||
# If true, the index is split into individual pages for each letter.
|
||||
# html_split_index = False
|
||||
#html_split_index = False
|
||||
|
||||
# If true, links to the reST sources are added to the pages.
|
||||
html_show_sourcelink = False
|
||||
@@ -208,77 +202,84 @@ html_show_copyright = True
|
||||
# If true, an OpenSearch description file will be output, and all pages will
|
||||
# contain a <link> tag referring to it. The value of this option must be the
|
||||
# base URL from which the finished HTML is served.
|
||||
# html_use_opensearch = ''
|
||||
#html_use_opensearch = ''
|
||||
|
||||
# This is the file name suffix for HTML files (e.g. ".xhtml").
|
||||
# html_file_suffix = None
|
||||
#html_file_suffix = None
|
||||
|
||||
# Language to be used for generating the HTML full-text search index.
|
||||
# Sphinx supports the following languages:
|
||||
# 'da', 'de', 'en', 'es', 'fi', 'fr', 'hu', 'it', 'ja'
|
||||
# 'nl', 'no', 'pt', 'ro', 'ru', 'sv', 'tr'
|
||||
# html_search_language = 'en'
|
||||
#html_search_language = 'en'
|
||||
|
||||
# A dictionary with options for the search language support, empty by default.
|
||||
# Now only 'ja' uses this config value
|
||||
# html_search_options = {'type': 'default'}
|
||||
#html_search_options = {'type': 'default'}
|
||||
|
||||
# The name of a javascript file (relative to the configuration directory) that
|
||||
# implements a search results scorer. If empty, the default will be used.
|
||||
# html_search_scorer = 'scorer.js'
|
||||
#html_search_scorer = 'scorer.js'
|
||||
|
||||
# Output file base name for HTML help builder.
|
||||
htmlhelp_basename = "Requestsdoc"
|
||||
htmlhelp_basename = 'Requestsdoc'
|
||||
|
||||
# -- Options for LaTeX output ---------------------------------------------
|
||||
|
||||
latex_elements = {
|
||||
# The paper size ('letterpaper' or 'a4paper').
|
||||
#'papersize': 'letterpaper',
|
||||
# The font size ('10pt', '11pt' or '12pt').
|
||||
#'pointsize': '10pt',
|
||||
# Additional stuff for the LaTeX preamble.
|
||||
#'preamble': '',
|
||||
# Latex figure (float) alignment
|
||||
#'figure_align': 'htbp',
|
||||
# The paper size ('letterpaper' or 'a4paper').
|
||||
#'papersize': 'letterpaper',
|
||||
|
||||
# The font size ('10pt', '11pt' or '12pt').
|
||||
#'pointsize': '10pt',
|
||||
|
||||
# Additional stuff for the LaTeX preamble.
|
||||
#'preamble': '',
|
||||
|
||||
# Latex figure (float) alignment
|
||||
#'figure_align': 'htbp',
|
||||
}
|
||||
|
||||
# Grouping the document tree into LaTeX files. List of tuples
|
||||
# (source start file, target name, title,
|
||||
# author, documentclass [howto, manual, or own class]).
|
||||
latex_documents = [
|
||||
(master_doc, "Requests.tex", u"Requests Documentation", u"Kenneth Reitz", "manual")
|
||||
(master_doc, 'Requests.tex', u'Requests Documentation',
|
||||
u'Kenneth Reitz', 'manual'),
|
||||
]
|
||||
|
||||
# The name of an image file (relative to this directory) to place at the top of
|
||||
# the title page.
|
||||
# latex_logo = None
|
||||
#latex_logo = None
|
||||
|
||||
# For "manual" documents, if this is true, then toplevel headings are parts,
|
||||
# not chapters.
|
||||
# latex_use_parts = False
|
||||
#latex_use_parts = False
|
||||
|
||||
# If true, show page references after internal links.
|
||||
# latex_show_pagerefs = False
|
||||
#latex_show_pagerefs = False
|
||||
|
||||
# If true, show URL addresses after external links.
|
||||
# latex_show_urls = False
|
||||
#latex_show_urls = False
|
||||
|
||||
# Documents to append as an appendix to all manuals.
|
||||
# latex_appendices = []
|
||||
#latex_appendices = []
|
||||
|
||||
# If false, no module index is generated.
|
||||
# latex_domain_indices = True
|
||||
#latex_domain_indices = True
|
||||
|
||||
|
||||
# -- Options for manual page output ---------------------------------------
|
||||
|
||||
# One entry per manual page. List of tuples
|
||||
# (source start file, name, description, authors, manual section).
|
||||
man_pages = [(master_doc, "requests", u"Requests Documentation", [author], 1)]
|
||||
man_pages = [
|
||||
(master_doc, 'requests', u'Requests Documentation',
|
||||
[author], 1)
|
||||
]
|
||||
|
||||
# If true, show URL addresses after external links.
|
||||
# man_show_urls = False
|
||||
#man_show_urls = False
|
||||
|
||||
|
||||
# -- Options for Texinfo output -------------------------------------------
|
||||
@@ -287,28 +288,22 @@ man_pages = [(master_doc, "requests", u"Requests Documentation", [author], 1)]
|
||||
# (source start file, target name, title, author,
|
||||
# dir menu entry, description, category)
|
||||
texinfo_documents = [
|
||||
(
|
||||
master_doc,
|
||||
"Requests",
|
||||
u"Requests Documentation",
|
||||
author,
|
||||
"Requests",
|
||||
"One line description of project.",
|
||||
"Miscellaneous",
|
||||
)
|
||||
(master_doc, 'Requests', u'Requests Documentation',
|
||||
author, 'Requests', 'One line description of project.',
|
||||
'Miscellaneous'),
|
||||
]
|
||||
|
||||
# Documents to append as an appendix to all manuals.
|
||||
# texinfo_appendices = []
|
||||
#texinfo_appendices = []
|
||||
|
||||
# If false, no module index is generated.
|
||||
# texinfo_domain_indices = True
|
||||
#texinfo_domain_indices = True
|
||||
|
||||
# How to display URL addresses: 'footnote', 'no', or 'inline'.
|
||||
# texinfo_show_urls = 'footnote'
|
||||
#texinfo_show_urls = 'footnote'
|
||||
|
||||
# If true, do not generate a @detailmenu in the "Top" node's menu.
|
||||
# texinfo_no_detailmenu = False
|
||||
#texinfo_no_detailmenu = False
|
||||
|
||||
|
||||
# -- Options for Epub output ----------------------------------------------
|
||||
@@ -320,67 +315,64 @@ epub_publisher = author
|
||||
epub_copyright = copyright
|
||||
|
||||
# The basename for the epub file. It defaults to the project name.
|
||||
# epub_basename = project
|
||||
#epub_basename = project
|
||||
|
||||
# The HTML theme for the epub output. Since the default themes are not
|
||||
# optimized for small screen space, using the same theme for HTML and epub
|
||||
# output is usually not wise. This defaults to 'epub', a theme designed to save
|
||||
# visual space.
|
||||
# epub_theme = 'epub'
|
||||
#epub_theme = 'epub'
|
||||
|
||||
# The language of the text. It defaults to the language option
|
||||
# or 'en' if the language is not set.
|
||||
# epub_language = ''
|
||||
#epub_language = ''
|
||||
|
||||
# The scheme of the identifier. Typical schemes are ISBN or URL.
|
||||
# epub_scheme = ''
|
||||
#epub_scheme = ''
|
||||
|
||||
# The unique identifier of the text. This can be a ISBN number
|
||||
# or the project homepage.
|
||||
# epub_identifier = ''
|
||||
#epub_identifier = ''
|
||||
|
||||
# A unique identification for the text.
|
||||
# epub_uid = ''
|
||||
#epub_uid = ''
|
||||
|
||||
# A tuple containing the cover image and cover page html template filenames.
|
||||
# epub_cover = ()
|
||||
#epub_cover = ()
|
||||
|
||||
# A sequence of (type, uri, title) tuples for the guide element of content.opf.
|
||||
# epub_guide = ()
|
||||
#epub_guide = ()
|
||||
|
||||
# HTML files that should be inserted before the pages created by sphinx.
|
||||
# The format is a list of tuples containing the path and title.
|
||||
# epub_pre_files = []
|
||||
#epub_pre_files = []
|
||||
|
||||
# HTML files that should be inserted after the pages created by sphinx.
|
||||
# The format is a list of tuples containing the path and title.
|
||||
# epub_post_files = []
|
||||
#epub_post_files = []
|
||||
|
||||
# A list of files that should not be packed into the epub file.
|
||||
epub_exclude_files = ["search.html"]
|
||||
epub_exclude_files = ['search.html']
|
||||
|
||||
# The depth of the table of contents in toc.ncx.
|
||||
# epub_tocdepth = 3
|
||||
#epub_tocdepth = 3
|
||||
|
||||
# Allow duplicate toc entries.
|
||||
# epub_tocdup = True
|
||||
#epub_tocdup = True
|
||||
|
||||
# Choose between 'default' and 'includehidden'.
|
||||
# epub_tocscope = 'default'
|
||||
#epub_tocscope = 'default'
|
||||
|
||||
# Fix unsupported image types using the Pillow.
|
||||
# epub_fix_images = False
|
||||
#epub_fix_images = False
|
||||
|
||||
# Scale large images.
|
||||
# epub_max_image_width = 0
|
||||
#epub_max_image_width = 0
|
||||
|
||||
# How to display URL addresses: 'footnote', 'no', or 'inline'.
|
||||
# epub_show_urls = 'inline'
|
||||
#epub_show_urls = 'inline'
|
||||
|
||||
# If false, no index is generated.
|
||||
# epub_use_index = True
|
||||
#epub_use_index = True
|
||||
|
||||
intersphinx_mapping = {
|
||||
"python": ("https://docs.python.org/3/", None),
|
||||
"urllib3": ("https://urllib3.readthedocs.io/en/latest", None),
|
||||
}
|
||||
intersphinx_mapping = {'urllib3': ('http://urllib3.readthedocs.io/en/latest', None)}
|
||||
|
||||
@@ -1,4 +1,5 @@
|
||||
Authors
|
||||
=======
|
||||
|
||||
|
||||
.. include:: ../../AUTHORS.rst
|
||||
|
||||
@@ -11,17 +11,22 @@ contributing to the Requests project is *very* generous of you.
|
||||
This document lays out guidelines and advice for contributing to this project.
|
||||
If you're thinking of contributing, please start by reading this document and
|
||||
getting a feel for how contributing to this project works. If you have any
|
||||
questions, feel free to reach out to either `Nate Prewitt`_, `Ian Cordasco`_,
|
||||
or `Seth Michael Larson`_, the primary maintainers.
|
||||
questions, feel free to reach out to either `Ian Cordasco`_ or `Cory Benfield`_,
|
||||
the primary maintainers.
|
||||
|
||||
.. _Ian Cordasco: http://www.coglib.com/~icordasc/
|
||||
.. _Nate Prewitt: https://www.nateprewitt.com/
|
||||
.. _Seth Michael Larson: https://sethmlarson.dev/
|
||||
.. _Cory Benfield: https://lukasa.co.uk/about
|
||||
|
||||
If you have non-technical feedback, philosophical ponderings, crazy ideas, or
|
||||
other general thoughts about Requests or its position within the Python
|
||||
ecosystem, the BDFL, `Kenneth Reitz`_, would love to hear from you.
|
||||
|
||||
The guide is split into sections based on the type of contribution you're
|
||||
thinking of making, with a section that covers general guidelines for all
|
||||
contributors.
|
||||
|
||||
.. _Kenneth Reitz: mailto:me@kennethreitz.org
|
||||
|
||||
Be Cordial
|
||||
----------
|
||||
|
||||
@@ -34,7 +39,7 @@ including reporting bugs or requesting features. This golden rule is
|
||||
**All contributions are welcome**, as long as
|
||||
everyone involved is treated with respect.
|
||||
|
||||
.. _be cordial or be on your way: https://kenreitz.org/essays/2013/01/27/be-cordial-or-be-on-your-way
|
||||
.. _be cordial or be on your way: http://kennethreitz.org/be-cordial-or-be-on-your-way/
|
||||
|
||||
.. _early-feedback:
|
||||
|
||||
@@ -78,7 +83,7 @@ When contributing code, you'll want to follow this checklist:
|
||||
4. Make your change.
|
||||
5. Run the entire test suite again, confirming that all tests pass *including
|
||||
the ones you just added*.
|
||||
6. Send a GitHub Pull Request to the main repository's ``main`` branch.
|
||||
6. Send a GitHub Pull Request to the main repository's ``master`` branch.
|
||||
GitHub Pull Requests are the expected method of code collaboration on this
|
||||
project.
|
||||
|
||||
@@ -93,21 +98,6 @@ event that you object to the code review feedback, you should make your case
|
||||
clearly and calmly. If, after doing so, the feedback is judged to still apply,
|
||||
you must either apply the feedback or withdraw your contribution.
|
||||
|
||||
Code Style
|
||||
~~~~~~~~~~
|
||||
|
||||
Requests uses a collection of tools to ensure the code base has a consistent
|
||||
style as it grows. We have these orchestrated using a tool called
|
||||
`pre-commit`_. This can be installed locally and run over your changes prior
|
||||
to opening a PR, and will also be run as part of the CI approval process
|
||||
before a change is merged.
|
||||
|
||||
You can find the full list of formatting requirements specified in the
|
||||
`.pre-commit-config.yaml`_ at the top level directory of Requests.
|
||||
|
||||
.. _pre-commit: https://pre-commit.com/
|
||||
.. _.pre-commit-config.yaml: https://github.com/psf/requests/blob/main/.pre-commit-config.yaml
|
||||
|
||||
New Contributors
|
||||
~~~~~~~~~~~~~~~~
|
||||
|
||||
@@ -118,6 +108,55 @@ asking for help.
|
||||
|
||||
Please also check the :ref:`early-feedback` section.
|
||||
|
||||
Kenneth Reitz's Code Style™
|
||||
~~~~~~~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
The Requests codebase uses the `PEP 8`_ code style.
|
||||
|
||||
In addition to the standards outlined in PEP 8, we have a few guidelines:
|
||||
|
||||
- Line-length can exceed 79 characters, to 100, when convenient.
|
||||
- Line-length can exceed 100 characters, when doing otherwise would be *terribly* inconvenient.
|
||||
- Always use single-quoted strings (e.g. ``'#flatearth'``), unless a single-quote occurs within the string.
|
||||
|
||||
Additionally, one of the styles that PEP8 recommends for `line continuations`_
|
||||
completely lacks all sense of taste, and is not to be permitted within
|
||||
the Requests codebase::
|
||||
|
||||
# Aligned with opening delimiter.
|
||||
foo = long_function_name(var_one, var_two,
|
||||
var_three, var_four)
|
||||
|
||||
No. Just don't. Please.
|
||||
|
||||
Docstrings are to follow the following syntaxes::
|
||||
|
||||
def the_earth_is_flat():
|
||||
"""NASA divided up the seas into thirty-three degrees."""
|
||||
pass
|
||||
|
||||
::
|
||||
|
||||
def fibonacci_spiral_tool():
|
||||
"""With my feet upon the ground I lose myself / between the sounds
|
||||
and open wide to suck it in. / I feel it move across my skin. / I'm
|
||||
reaching up and reaching out. / I'm reaching for the random or
|
||||
whatever will bewilder me. / Whatever will bewilder me. / And
|
||||
following our will and wind we may just go where no one's been. /
|
||||
We'll ride the spiral to the end and may just go where no one's
|
||||
been.
|
||||
|
||||
Spiral out. Keep going...
|
||||
"""
|
||||
pass
|
||||
|
||||
All functions, methods, and classes are to contain docstrings. Object data
|
||||
model methods (e.g. ``__repr__``) are typically the exception to this rule.
|
||||
|
||||
Thanks for helping to make the world a better place!
|
||||
|
||||
.. _PEP 8: http://pep8.org
|
||||
.. _line continuations: https://www.python.org/dev/peps/pep-0008/#indentation
|
||||
|
||||
Documentation Contributions
|
||||
---------------------------
|
||||
@@ -148,7 +187,7 @@ through the `GitHub issues`_, **both open and closed**, to confirm that the bug
|
||||
hasn't been reported before. Duplicate bug reports are a huge drain on the time
|
||||
of other contributors, and should be avoided as much as possible.
|
||||
|
||||
.. _GitHub issues: https://github.com/psf/requests/issues
|
||||
.. _GitHub issues: https://github.com/requests/requests/issues
|
||||
|
||||
|
||||
Feature Requests
|
||||
@@ -164,4 +203,4 @@ while keeping an open ear and mind.
|
||||
|
||||
If you believe there is a feature missing, feel free to raise a feature
|
||||
request, but please do be aware that the overwhelming likelihood is that your
|
||||
feature request will not be accepted.
|
||||
feature request will not be accepted.
|
||||
41
docs/dev/philosophy.rst
Normal file
@@ -0,0 +1,41 @@
|
||||
Development Philosophy
|
||||
======================
|
||||
|
||||
Requests is an open but opinionated library, created by an open but opinionated developer.
|
||||
|
||||
|
||||
Management Style
|
||||
~~~~~~~~~~~~~~~~
|
||||
|
||||
`Kenneth Reitz <http://kennethreitz.org>`_ is the BDFL. He has final say in any decision related to the Requests project. Kenneth is responsible for the direction and form of the library. In addition to making decisions based on technical merit, he is responsible for making decisions based on the development philosophy of Requests. Only Kenneth may merge code into Requests.
|
||||
|
||||
`Ian Cordasco <http://www.coglib.com/~icordasc/>`_ and `Cory Benfield <https://lukasa.co.uk/about/>`_ are the core contributors. They are responsible for triaging bug reports, reviewing pull requests and ensuring that Kenneth is kept up to speed with developments around the library. The day-to-day managing of the project is done by the core contributors. They are responsible for making judgements about whether or not a feature request is likely to be accepted by Kenneth. They do not have the authority to change code or merge code changes, though they may change documentation. Their word is not final.
|
||||
|
||||
Values
|
||||
~~~~~~
|
||||
|
||||
- Simplicity is always better than functionality.
|
||||
- Listen to everyone, then disregard it.
|
||||
- The API is all that matters. Everything else is secondary.
|
||||
- Fit the 90% use-case. Ignore the nay-sayers.
|
||||
|
||||
Semantic Versioning
|
||||
~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
For many years, the open source community has been plagued with version number dystonia. Numbers vary so greatly from project to project, they are practically meaningless.
|
||||
|
||||
Requests uses `Semantic Versioning <http://semver.org>`_. This specification seeks to put an end to this madness with a small set of practical guidelines for you and your colleagues to use in your next project.
|
||||
|
||||
Standard Library?
|
||||
~~~~~~~~~~~~~~~~~
|
||||
|
||||
Requests has no *active* plans to be included in the standard library. This decision has been discussed at length with Guido as well as numerous core developers.
|
||||
|
||||
Essentially, the standard library is where a library goes to die. It is appropriate for a module to be included when active development is no longer necessary.
|
||||
|
||||
Linux Distro Packages
|
||||
~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
Distributions have been made for many Linux repositories, including: Ubuntu, Debian, RHEL, and Arch.
|
||||
|
||||
These distributions are sometimes divergent forks, or are otherwise not kept up-to-date with the latest code and bugfixes. PyPI (and its mirrors) and GitHub are the official distribution sources; alternatives are not supported by the Requests project.
|
||||
71
docs/dev/todo.rst
Normal file
@@ -0,0 +1,71 @@
|
||||
How to Help
|
||||
===========
|
||||
|
||||
Requests is under active development, and contributions are more than welcome!
|
||||
|
||||
#. Check for open issues or open a fresh issue to start a discussion around a bug.
|
||||
There is a Contributor Friendly tag for issues that should be ideal for people who are not very
|
||||
familiar with the codebase yet.
|
||||
#. Fork `the repository <https://github.com/requests/requests>`_ on GitHub and start making your
|
||||
changes to a new branch.
|
||||
#. Write a test which shows that the bug was fixed.
|
||||
#. Send a pull request and bug the maintainer until it gets merged and published. :)
|
||||
Make sure to add yourself to `AUTHORS <https://github.com/requests/requests/blob/master/AUTHORS.rst>`_.
|
||||
|
||||
Feature Freeze
|
||||
--------------
|
||||
|
||||
As of v1.0.0, Requests has now entered a feature freeze. Requests for new
|
||||
features and Pull Requests implementing those features will not be accepted.
|
||||
|
||||
Development Dependencies
|
||||
------------------------
|
||||
|
||||
You'll need to install py.test in order to run the Requests' test suite::
|
||||
|
||||
$ pip install pipenv
|
||||
$ pipenv lock
|
||||
$ pipenv install --dev
|
||||
$ pipenv run py.test tests
|
||||
============================= test session starts ==============================
|
||||
platform darwin -- Python 3.4.4, pytest-3.0.6, py-1.4.32, pluggy-0.4.0
|
||||
...
|
||||
collected 445 items
|
||||
|
||||
tests/test_hooks.py ...
|
||||
tests/test_lowlevel.py ............
|
||||
tests/test_requests.py ...........................................................
|
||||
tests/test_structures.py ....................
|
||||
tests/test_testserver.py ...........
|
||||
tests/test_utils.py ..s...........................................................
|
||||
|
||||
============== 442 passed, 1 skipped, 2 xpassed in 46.48 seconds ===============
|
||||
|
||||
Runtime Environments
|
||||
--------------------
|
||||
|
||||
Requests currently supports the following versions of Python:
|
||||
|
||||
- Python 2.6
|
||||
- Python 2.7
|
||||
- Python 3.3
|
||||
- Python 3.4
|
||||
- Python 3.5
|
||||
- Python 3.6
|
||||
- PyPy
|
||||
|
||||
Google AppEngine is not officially supported although support is available
|
||||
with the `Requests-Toolbelt`_.
|
||||
|
||||
.. _Requests-Toolbelt: http://toolbelt.readthedocs.io/
|
||||
|
||||
|
||||
Are you crazy?
|
||||
--------------
|
||||
|
||||
- SPDY support would be awesome. No C extensions.
|
||||
|
||||
Downstream Repackaging
|
||||
----------------------
|
||||
|
||||
If you are repackaging Requests, please note that you must also redistribute the ``cacerts.pem`` file in order to get correct SSL functionality.
|
||||
@@ -3,29 +3,34 @@
|
||||
You can adapt this file completely to your liking, but it should at least
|
||||
contain the root `toctree` directive.
|
||||
|
||||
Requests: HTTP for Humans™
|
||||
==========================
|
||||
Requests: HTTP for Humans
|
||||
=========================
|
||||
|
||||
Release v\ |version|. (:ref:`Installation <install>`)
|
||||
|
||||
|
||||
.. image:: https://static.pepy.tech/badge/requests/month
|
||||
:target: https://pepy.tech/project/requests
|
||||
:alt: Requests Downloads Per Month Badge
|
||||
|
||||
.. image:: https://img.shields.io/pypi/l/requests.svg
|
||||
:target: https://pypi.org/project/requests/
|
||||
:alt: License Badge
|
||||
:target: https://pypi.python.org/pypi/requests
|
||||
|
||||
.. image:: https://img.shields.io/pypi/wheel/requests.svg
|
||||
:target: https://pypi.org/project/requests/
|
||||
:alt: Wheel Support Badge
|
||||
:target: https://pypi.python.org/pypi/requests
|
||||
|
||||
.. image:: https://img.shields.io/pypi/pyversions/requests.svg
|
||||
:target: https://pypi.org/project/requests/
|
||||
:alt: Python Version Support Badge
|
||||
:target: https://pypi.python.org/pypi/requests
|
||||
|
||||
**Requests** is an elegant and simple HTTP library for Python, built for human beings.
|
||||
.. image:: https://codecov.io/github/requests/requests/coverage.svg?branch=master
|
||||
:target: https://codecov.io/github/requests/requests
|
||||
:alt: codecov.io
|
||||
|
||||
.. image:: https://img.shields.io/badge/Say%20Thanks!-🦉-1EAEDB.svg
|
||||
:target: https://saythanks.io/to/kennethreitz
|
||||
|
||||
|
||||
**Requests** is the only *Non-GMO* HTTP library for Python, safe for human
|
||||
consumption.
|
||||
|
||||
*Warning: Recreational use of the Python standard library for HTTP may result in dangerous side-effects,
|
||||
including: security vulnerabilities, verbose code, reinventing the wheel,
|
||||
constantly reading documentation, depression, headaches, or even death.*
|
||||
|
||||
-------------------
|
||||
|
||||
@@ -39,17 +44,44 @@ Release v\ |version|. (:ref:`Installation <install>`)
|
||||
>>> r.encoding
|
||||
'utf-8'
|
||||
>>> r.text
|
||||
'{"type":"User"...'
|
||||
u'{"type":"User"...'
|
||||
>>> r.json()
|
||||
{'private_gists': 419, 'total_private_repos': 77, ...}
|
||||
{u'private_gists': 419, u'total_private_repos': 77, ...}
|
||||
|
||||
See `similar code, sans Requests <https://gist.github.com/973705>`_.
|
||||
|
||||
|
||||
**Requests** allows you to send HTTP/1.1 requests extremely easily.
|
||||
There's no need to manually add query strings to your
|
||||
**Requests** allows you to send *organic, grass-fed* HTTP/1.1 requests, without the
|
||||
need for manual labor. There's no need to manually add query strings to your
|
||||
URLs, or to form-encode your POST data. Keep-alive and HTTP connection pooling
|
||||
are 100% automatic, thanks to `urllib3 <https://github.com/urllib3/urllib3>`_.
|
||||
are 100% automatic, thanks to `urllib3 <https://github.com/shazow/urllib3>`_.
|
||||
|
||||
User Testimonials
|
||||
-----------------
|
||||
|
||||
Twitter, Spotify, Microsoft, Amazon, Lyft, BuzzFeed, Reddit, The NSA, Her Majesty's Government, Google, Twilio, Runscope, Mozilla, Heroku,
|
||||
PayPal, NPR, Obama for America, Transifex, Native Instruments, The Washington
|
||||
Post, SoundCloud, Kippt, Sony, and Federal U.S.
|
||||
Institutions that prefer to be unnamed claim to use Requests internally.
|
||||
|
||||
**Armin Ronacher**—
|
||||
*Requests is the perfect example how beautiful an API can be with the
|
||||
right level of abstraction.*
|
||||
|
||||
**Matt DeBoard**—
|
||||
*I'm going to get Kenneth Reitz's Python requests module tattooed
|
||||
on my body, somehow. The whole thing.*
|
||||
|
||||
**Daniel Greenfeld**—
|
||||
*Nuked a 1200 LOC spaghetti code library with 10 lines of code thanks to
|
||||
Kenneth Reitz's request library. Today has been AWESOME.*
|
||||
|
||||
**Kenny Meyers**—
|
||||
*Python HTTP: When in doubt, or when not in doubt, use Requests. Beautiful,
|
||||
simple, Pythonic.*
|
||||
|
||||
Requests is one of the most downloaded Python packages of all time, pulling in
|
||||
over 11,000,000 downloads every month. All the cool kids are doing it!
|
||||
|
||||
Beloved Features
|
||||
----------------
|
||||
@@ -72,7 +104,7 @@ Requests is ready for today's web.
|
||||
- Chunked Requests
|
||||
- ``.netrc`` Support
|
||||
|
||||
Requests officially supports Python 3.8+, and runs great on PyPy.
|
||||
Requests officially supports Python 2.6–2.7 & 3.3–3.7, and runs great on PyPy.
|
||||
|
||||
|
||||
The User Guide
|
||||
@@ -85,6 +117,7 @@ instructions for getting the most out of Requests.
|
||||
.. toctree::
|
||||
:maxdepth: 2
|
||||
|
||||
user/intro
|
||||
user/install
|
||||
user/quickstart
|
||||
user/advanced
|
||||
@@ -98,19 +131,15 @@ This part of the documentation, which is mostly prose, details the
|
||||
Requests ecosystem and community.
|
||||
|
||||
.. toctree::
|
||||
:maxdepth: 2
|
||||
:maxdepth: 1
|
||||
|
||||
community/recommended
|
||||
community/faq
|
||||
community/recommended
|
||||
community/out-there
|
||||
community/support
|
||||
community/vulnerabilities
|
||||
community/release-process
|
||||
|
||||
.. toctree::
|
||||
:maxdepth: 1
|
||||
|
||||
community/updates
|
||||
community/release-process
|
||||
|
||||
The API Documentation / Guide
|
||||
-----------------------------
|
||||
@@ -134,6 +163,8 @@ you.
|
||||
:maxdepth: 3
|
||||
|
||||
dev/contributing
|
||||
dev/philosophy
|
||||
dev/todo
|
||||
dev/authors
|
||||
|
||||
There are no more guides. You are now guideless.
|
||||
|
||||
@@ -1,3 +0,0 @@
|
||||
# Pinning to avoid unexpected breakages.
|
||||
# Used by RTD to generate docs.
|
||||
Sphinx==7.2.6
|
||||
@@ -23,8 +23,8 @@ Let's persist some cookies across requests::
|
||||
|
||||
s = requests.Session()
|
||||
|
||||
s.get('https://httpbin.org/cookies/set/sessioncookie/123456789')
|
||||
r = s.get('https://httpbin.org/cookies')
|
||||
s.get('http://httpbin.org/cookies/set/sessioncookie/123456789')
|
||||
r = s.get('http://httpbin.org/cookies')
|
||||
|
||||
print(r.text)
|
||||
# '{"cookies": {"sessioncookie": "123456789"}}'
|
||||
@@ -38,7 +38,7 @@ is done by providing data to the properties on a Session object::
|
||||
s.headers.update({'x-test': 'true'})
|
||||
|
||||
# both 'x-test' and 'x-test2' are sent
|
||||
s.get('https://httpbin.org/headers', headers={'x-test2': 'true'})
|
||||
s.get('http://httpbin.org/headers', headers={'x-test2': 'true'})
|
||||
|
||||
|
||||
Any dictionaries that you pass to a request method will be merged with the
|
||||
@@ -51,11 +51,11 @@ with the first request, but not the second::
|
||||
|
||||
s = requests.Session()
|
||||
|
||||
r = s.get('https://httpbin.org/cookies', cookies={'from-my': 'browser'})
|
||||
r = s.get('http://httpbin.org/cookies', cookies={'from-my': 'browser'})
|
||||
print(r.text)
|
||||
# '{"cookies": {"from-my": "browser"}}'
|
||||
|
||||
r = s.get('https://httpbin.org/cookies')
|
||||
r = s.get('http://httpbin.org/cookies')
|
||||
print(r.text)
|
||||
# '{"cookies": {}}'
|
||||
|
||||
@@ -67,7 +67,7 @@ If you want to manually add cookies to your session, use the
|
||||
Sessions can also be used as context managers::
|
||||
|
||||
with requests.Session() as s:
|
||||
s.get('https://httpbin.org/cookies/set/sessioncookie/123456789')
|
||||
s.get('http://httpbin.org/cookies/set/sessioncookie/123456789')
|
||||
|
||||
This will make sure the session is closed as soon as the ``with`` block is
|
||||
exited, even if unhandled exceptions occurred.
|
||||
@@ -95,7 +95,7 @@ The ``Response`` object contains all of the information returned by the server a
|
||||
also contains the ``Request`` object you created originally. Here is a simple
|
||||
request to get some very important information from Wikipedia's servers::
|
||||
|
||||
>>> r = requests.get('https://en.wikipedia.org/wiki/Monty_Python')
|
||||
>>> r = requests.get('http://en.wikipedia.org/wiki/Monty_Python')
|
||||
|
||||
If we want to access the headers the server sent back to us, we do this::
|
||||
|
||||
@@ -187,25 +187,6 @@ applied, replace the call to :meth:`Request.prepare()
|
||||
|
||||
print(resp.status_code)
|
||||
|
||||
When you are using the prepared request flow, keep in mind that it does not take into account the environment.
|
||||
This can cause problems if you are using environment variables to change the behaviour of requests.
|
||||
For example: Self-signed SSL certificates specified in ``REQUESTS_CA_BUNDLE`` will not be taken into account.
|
||||
As a result an ``SSL: CERTIFICATE_VERIFY_FAILED`` is thrown.
|
||||
You can get around this behaviour by explicitly merging the environment settings into your session::
|
||||
|
||||
from requests import Request, Session
|
||||
|
||||
s = Session()
|
||||
req = Request('GET', url)
|
||||
|
||||
prepped = s.prepare_request(req)
|
||||
|
||||
# Merge environment settings into session
|
||||
settings = s.merge_environment_settings(prepped.url, {}, None, None, None)
|
||||
resp = s.send(prepped, **settings)
|
||||
|
||||
print(resp.status_code)
|
||||
|
||||
.. _verification:
|
||||
|
||||
SSL Cert Verification
|
||||
@@ -233,22 +214,15 @@ or persistent::
|
||||
s.verify = '/path/to/certfile'
|
||||
|
||||
.. note:: If ``verify`` is set to a path to a directory, the directory must have been processed using
|
||||
the ``c_rehash`` utility supplied with OpenSSL.
|
||||
the c_rehash utility supplied with OpenSSL.
|
||||
|
||||
This list of trusted CAs can also be specified through the ``REQUESTS_CA_BUNDLE`` environment variable.
|
||||
If ``REQUESTS_CA_BUNDLE`` is not set, ``CURL_CA_BUNDLE`` will be used as fallback.
|
||||
|
||||
Requests can also ignore verifying the SSL certificate if you set ``verify`` to False::
|
||||
|
||||
>>> requests.get('https://kennethreitz.org', verify=False)
|
||||
<Response [200]>
|
||||
|
||||
Note that when ``verify`` is set to ``False``, requests will accept any TLS
|
||||
certificate presented by the server, and will ignore hostname mismatches
|
||||
and/or expired certificates, which will make your application vulnerable to
|
||||
man-in-the-middle (MitM) attacks. Setting verify to ``False`` may be useful
|
||||
during local development or testing.
|
||||
|
||||
By default, ``verify`` is set to True. Option ``verify`` only applies to host certs.
|
||||
|
||||
Client Side Certificates
|
||||
@@ -279,20 +253,21 @@ If you specify a wrong path or an invalid cert, you'll get a SSLError::
|
||||
CA Certificates
|
||||
---------------
|
||||
|
||||
Requests uses certificates from the package `certifi`_. This allows for users
|
||||
to update their trusted certificates without changing the version of Requests.
|
||||
By default, Requests bundles a set of root CAs that it trusts, sourced from the
|
||||
`Mozilla trust store`_. However, these are only updated once for each Requests
|
||||
version. This means that if you pin a Requests version your certificates can
|
||||
become extremely out of date.
|
||||
|
||||
Before version 2.16, Requests bundled a set of root CAs that it trusted,
|
||||
sourced from the `Mozilla trust store`_. The certificates were only updated
|
||||
once for each Requests version. When ``certifi`` was not installed, this led to
|
||||
extremely out-of-date certificate bundles when using significantly older
|
||||
versions of Requests.
|
||||
From Requests version 2.4.0 onwards, Requests will attempt to use certificates
|
||||
from `certifi`_ if it is present on the system. This allows for users to update
|
||||
their trusted certificates without having to change the code that runs on their
|
||||
system.
|
||||
|
||||
For the sake of security we recommend upgrading certifi frequently!
|
||||
|
||||
.. _HTTP persistent connection: https://en.wikipedia.org/wiki/HTTP_persistent_connection
|
||||
.. _connection pooling: https://urllib3.readthedocs.io/en/latest/reference/urllib3.connectionpool.html
|
||||
.. _certifi: https://certifiio.readthedocs.io/
|
||||
.. _connection pooling: http://urllib3.readthedocs.io/en/latest/reference/index.html#module-urllib3.connectionpool
|
||||
.. _certifi: http://certifi.io/
|
||||
.. _Mozilla trust store: https://hg.mozilla.org/mozilla-central/raw-file/tip/security/nss/lib/ckfw/builtins/certdata.txt
|
||||
|
||||
.. _body-content-workflow:
|
||||
@@ -305,7 +280,7 @@ immediately. You can override this behaviour and defer downloading the response
|
||||
body until you access the :attr:`Response.content <requests.Response.content>`
|
||||
attribute with the ``stream`` parameter::
|
||||
|
||||
tarball_url = 'https://github.com/psf/requests/tarball/main'
|
||||
tarball_url = 'https://github.com/requests/requests/tarball/master'
|
||||
r = requests.get(tarball_url, stream=True)
|
||||
|
||||
At this point only the response headers have been downloaded and the connection
|
||||
@@ -326,11 +301,15 @@ release the connection back to the pool unless you consume all the data or call
|
||||
:meth:`Response.close <requests.Response.close>`. This can lead to
|
||||
inefficiency with connections. If you find yourself partially reading request
|
||||
bodies (or not reading them at all) while using ``stream=True``, you should
|
||||
make the request within a ``with`` statement to ensure it's always closed::
|
||||
consider using ``contextlib.closing`` (`documented here`_), like this::
|
||||
|
||||
with requests.get('https://httpbin.org/get', stream=True) as r:
|
||||
from contextlib import closing
|
||||
|
||||
with closing(requests.get('http://httpbin.org/get', stream=True)) as r:
|
||||
# Do things with the response here.
|
||||
|
||||
.. _`documented here`: http://docs.python.org/2/library/contextlib.html#contextlib.closing
|
||||
|
||||
.. _keep-alive:
|
||||
|
||||
Keep-Alive
|
||||
@@ -356,11 +335,13 @@ file-like object for your body::
|
||||
with open('massive-body', 'rb') as f:
|
||||
requests.post('http://some.url/streamed', data=f)
|
||||
|
||||
.. warning:: It is strongly recommended that you open files in :ref:`binary
|
||||
mode <tut-files>`. This is because Requests may attempt to provide
|
||||
the ``Content-Length`` header for you, and if it does this value
|
||||
will be set to the number of *bytes* in the file. Errors may occur
|
||||
if you open the file in *text mode*.
|
||||
.. warning:: It is strongly recommended that you open files in `binary mode`_.
|
||||
This is because Requests may attempt to provide the
|
||||
``Content-Length`` header for you, and if it does this value will
|
||||
be set to the number of *bytes* in the file. Errors may occur if
|
||||
you open the file in *text mode*.
|
||||
|
||||
.. _binary mode: https://docs.python.org/2/tutorial/inputoutput.html#reading-and-writing-files
|
||||
|
||||
|
||||
.. _chunk-encoding:
|
||||
@@ -398,10 +379,10 @@ upload image files to an HTML form with a multiple file field 'images'::
|
||||
|
||||
To do that, just set files to a list of tuples of ``(form_field_name, file_info)``::
|
||||
|
||||
>>> url = 'https://httpbin.org/post'
|
||||
>>> url = 'http://httpbin.org/post'
|
||||
>>> multiple_files = [
|
||||
... ('images', ('foo.png', open('foo.png', 'rb'), 'image/png')),
|
||||
... ('images', ('bar.png', open('bar.png', 'rb'), 'image/png'))]
|
||||
('images', ('foo.png', open('foo.png', 'rb'), 'image/png')),
|
||||
('images', ('bar.png', open('bar.png', 'rb'), 'image/png'))]
|
||||
>>> r = requests.post(url, files=multiple_files)
|
||||
>>> r.text
|
||||
{
|
||||
@@ -411,11 +392,13 @@ To do that, just set files to a list of tuples of ``(form_field_name, file_info)
|
||||
...
|
||||
}
|
||||
|
||||
.. warning:: It is strongly recommended that you open files in :ref:`binary
|
||||
mode <tut-files>`. This is because Requests may attempt to provide
|
||||
the ``Content-Length`` header for you, and if it does this value
|
||||
will be set to the number of *bytes* in the file. Errors may occur
|
||||
if you open the file in *text mode*.
|
||||
.. warning:: It is strongly recommended that you open files in `binary mode`_.
|
||||
This is because Requests may attempt to provide the
|
||||
``Content-Length`` header for you, and if it does this value will
|
||||
be set to the number of *bytes* in the file. Errors may occur if
|
||||
you open the file in *text mode*.
|
||||
|
||||
.. _binary mode: https://docs.python.org/2/tutorial/inputoutput.html#reading-and-writing-files
|
||||
|
||||
|
||||
.. _event-hooks:
|
||||
@@ -436,7 +419,7 @@ You can assign a hook function on a per-request basis by passing a
|
||||
``{hook_name: callback_function}`` dictionary to the ``hooks`` request
|
||||
parameter::
|
||||
|
||||
hooks={'response': print_url}
|
||||
hooks=dict(response=print_url)
|
||||
|
||||
That ``callback_function`` will receive a chunk of data as its first
|
||||
argument.
|
||||
@@ -446,48 +429,24 @@ argument.
|
||||
def print_url(r, *args, **kwargs):
|
||||
print(r.url)
|
||||
|
||||
Your callback function must handle its own exceptions. Any unhandled exception won't be passed silently and thus should be handled by the code calling Requests.
|
||||
If an error occurs while executing your callback, a warning is given.
|
||||
|
||||
If the callback function returns a value, it is assumed that it is to
|
||||
replace the data that was passed in. If the function doesn't return
|
||||
anything, nothing else is affected.
|
||||
|
||||
::
|
||||
|
||||
def record_hook(r, *args, **kwargs):
|
||||
r.hook_called = True
|
||||
return r
|
||||
anything, nothing else is effected.
|
||||
|
||||
Let's print some request method arguments at runtime::
|
||||
|
||||
>>> requests.get('https://httpbin.org/', hooks={'response': print_url})
|
||||
https://httpbin.org/
|
||||
>>> requests.get('http://httpbin.org', hooks=dict(response=print_url))
|
||||
http://httpbin.org
|
||||
<Response [200]>
|
||||
|
||||
You can add multiple hooks to a single request. Let's call two hooks at once::
|
||||
|
||||
>>> r = requests.get('https://httpbin.org/', hooks={'response': [print_url, record_hook]})
|
||||
>>> r.hook_called
|
||||
True
|
||||
|
||||
You can also add hooks to a ``Session`` instance. Any hooks you add will then
|
||||
be called on every request made to the session. For example::
|
||||
|
||||
>>> s = requests.Session()
|
||||
>>> s.hooks['response'].append(print_url)
|
||||
>>> s.get('https://httpbin.org/')
|
||||
https://httpbin.org/
|
||||
<Response [200]>
|
||||
|
||||
A ``Session`` can have multiple hooks, which will be called in the order
|
||||
they are added.
|
||||
|
||||
.. _custom-auth:
|
||||
|
||||
Custom Authentication
|
||||
---------------------
|
||||
|
||||
Requests allows you to specify your own authentication mechanism.
|
||||
Requests allows you to use specify your own authentication mechanism.
|
||||
|
||||
Any callable which is passed as the ``auth`` argument to a request method will
|
||||
have the opportunity to modify the request before it is dispatched.
|
||||
@@ -534,7 +493,7 @@ set ``stream`` to ``True`` and iterate over the response with
|
||||
import json
|
||||
import requests
|
||||
|
||||
r = requests.get('https://httpbin.org/stream/20', stream=True)
|
||||
r = requests.get('http://httpbin.org/stream/20', stream=True)
|
||||
|
||||
for line in r.iter_lines():
|
||||
|
||||
@@ -548,7 +507,7 @@ When using `decode_unicode=True` with
|
||||
:meth:`Response.iter_content() <requests.Response.iter_content>`, you'll want
|
||||
to provide a fallback encoding in the event the server doesn't provide one::
|
||||
|
||||
r = requests.get('https://httpbin.org/stream/20', stream=True)
|
||||
r = requests.get('http://httpbin.org/stream/20', stream=True)
|
||||
|
||||
if r.encoding is None:
|
||||
r.encoding = 'utf-8'
|
||||
@@ -589,55 +548,21 @@ If you need to use a proxy, you can configure individual requests with the
|
||||
|
||||
requests.get('http://example.org', proxies=proxies)
|
||||
|
||||
Alternatively you can configure it once for an entire
|
||||
:class:`Session <requests.Session>`::
|
||||
You can also configure proxies by setting the environment variables
|
||||
``HTTP_PROXY`` and ``HTTPS_PROXY``.
|
||||
|
||||
import requests
|
||||
|
||||
proxies = {
|
||||
'http': 'http://10.10.1.10:3128',
|
||||
'https': 'http://10.10.1.10:1080',
|
||||
}
|
||||
session = requests.Session()
|
||||
session.proxies.update(proxies)
|
||||
|
||||
session.get('http://example.org')
|
||||
|
||||
.. warning:: Setting ``session.proxies`` may behave differently than expected.
|
||||
Values provided will be overwritten by environmental proxies
|
||||
(those returned by `urllib.request.getproxies <https://docs.python.org/3/library/urllib.request.html#urllib.request.getproxies>`_).
|
||||
To ensure the use of proxies in the presence of environmental proxies,
|
||||
explicitly specify the ``proxies`` argument on all individual requests as
|
||||
initially explained above.
|
||||
|
||||
See `#2018 <https://github.com/psf/requests/issues/2018>`_ for details.
|
||||
|
||||
When the proxies configuration is not overridden per request as shown above,
|
||||
Requests relies on the proxy configuration defined by standard
|
||||
environment variables ``http_proxy``, ``https_proxy``, ``no_proxy``,
|
||||
and ``all_proxy``. Uppercase variants of these variables are also supported.
|
||||
You can therefore set them to configure Requests (only set the ones relevant
|
||||
to your needs)::
|
||||
::
|
||||
|
||||
$ export HTTP_PROXY="http://10.10.1.10:3128"
|
||||
$ export HTTPS_PROXY="http://10.10.1.10:1080"
|
||||
$ export ALL_PROXY="socks5://10.10.1.10:3434"
|
||||
|
||||
$ python
|
||||
>>> import requests
|
||||
>>> requests.get('http://example.org')
|
||||
|
||||
To use HTTP Basic Auth with your proxy, use the `http://user:password@host/`
|
||||
syntax in any of the above configuration entries::
|
||||
To use HTTP Basic Auth with your proxy, use the `http://user:password@host/` syntax::
|
||||
|
||||
$ export HTTPS_PROXY="http://user:pass@10.10.1.10:1080"
|
||||
|
||||
$ python
|
||||
>>> proxies = {'http': 'http://user:pass@10.10.1.10:3128/'}
|
||||
|
||||
.. warning:: Storing sensitive username and password information in an
|
||||
environment variable or a version-controlled file is a security risk and is
|
||||
highly discouraged.
|
||||
proxies = {'http': 'http://user:pass@10.10.1.10:3128/'}
|
||||
|
||||
To give a proxy for a specific scheme and host, use the
|
||||
`scheme://hostname` form for the key. This will match for
|
||||
@@ -649,25 +574,6 @@ any request to the given scheme and exact hostname.
|
||||
|
||||
Note that proxy URLs must include the scheme.
|
||||
|
||||
Finally, note that using a proxy for https connections typically requires your
|
||||
local machine to trust the proxy's root certificate. By default the list of
|
||||
certificates trusted by Requests can be found with::
|
||||
|
||||
from requests.utils import DEFAULT_CA_BUNDLE_PATH
|
||||
print(DEFAULT_CA_BUNDLE_PATH)
|
||||
|
||||
You override this default certificate bundle by setting the ``REQUESTS_CA_BUNDLE``
|
||||
(or ``CURL_CA_BUNDLE``) environment variable to another file path::
|
||||
|
||||
$ export REQUESTS_CA_BUNDLE="/usr/local/myproxy_info/cacert.pem"
|
||||
$ export https_proxy="http://10.10.1.10:1080"
|
||||
|
||||
$ python
|
||||
>>> import requests
|
||||
>>> requests.get('https://example.org')
|
||||
|
||||
.. _socks:
|
||||
|
||||
SOCKS
|
||||
^^^^^
|
||||
|
||||
@@ -681,7 +587,7 @@ You can get the dependencies for this feature from ``pip``:
|
||||
|
||||
.. code-block:: bash
|
||||
|
||||
$ python -m pip install requests[socks]
|
||||
$ pip install requests[socks]
|
||||
|
||||
Once you've installed those dependencies, using a SOCKS proxy is just as easy
|
||||
as using a HTTP one::
|
||||
@@ -691,8 +597,6 @@ as using a HTTP one::
|
||||
'https': 'socks5://user:pass@host:port'
|
||||
}
|
||||
|
||||
Using the scheme ``socks5`` causes the DNS resolution to happen on the client, rather than on the proxy server. This is in line with curl, which uses the scheme to decide whether to do the DNS resolution on the client or proxy. If you want to resolve the domains on the proxy server, use ``socks5h`` as the scheme.
|
||||
|
||||
.. _compliance:
|
||||
|
||||
Compliance
|
||||
@@ -709,24 +613,13 @@ Encodings
|
||||
When you receive a response, Requests makes a guess at the encoding to
|
||||
use for decoding the response when you access the :attr:`Response.text
|
||||
<requests.Response.text>` attribute. Requests will first check for an
|
||||
encoding in the HTTP header, and if none is present, will use
|
||||
`charset_normalizer <https://pypi.org/project/charset_normalizer/>`_
|
||||
or `chardet <https://github.com/chardet/chardet>`_ to attempt to
|
||||
guess the encoding.
|
||||
encoding in the HTTP header, and if none is present, will use `chardet
|
||||
<http://pypi.python.org/pypi/chardet>`_ to attempt to guess the encoding.
|
||||
|
||||
If ``chardet`` is installed, ``requests`` uses it, however for python3
|
||||
``chardet`` is no longer a mandatory dependency. The ``chardet``
|
||||
library is an LGPL-licenced dependency and some users of requests
|
||||
cannot depend on mandatory LGPL-licensed dependencies.
|
||||
|
||||
When you install ``requests`` without specifying ``[use_chardet_on_py3]`` extra,
|
||||
and ``chardet`` is not already installed, ``requests`` uses ``charset-normalizer``
|
||||
(MIT-licensed) to guess the encoding.
|
||||
|
||||
The only time Requests will not guess the encoding is if no explicit charset
|
||||
The only time Requests will not do this is if no explicit charset
|
||||
is present in the HTTP headers **and** the ``Content-Type``
|
||||
header contains ``text``. In this situation, `RFC 2616
|
||||
<https://www.w3.org/Protocols/rfc2616/rfc2616-sec3.html#sec3.7.1>`_ specifies
|
||||
<http://www.w3.org/Protocols/rfc2616/rfc2616-sec3.html#sec3.7.1>`_ specifies
|
||||
that the default charset must be ``ISO-8859-1``. Requests follows the
|
||||
specification in this case. If you require a different encoding, you can
|
||||
manually set the :attr:`Response.encoding <requests.Response.encoding>`
|
||||
@@ -749,7 +642,7 @@ from GitHub. Suppose we wanted commit ``a050faf`` on Requests. We would get it
|
||||
like so::
|
||||
|
||||
>>> import requests
|
||||
>>> r = requests.get('https://api.github.com/repos/psf/requests/git/commits/a050faf084662f3a352dd1a941f2c7c9f886d4ad')
|
||||
>>> r = requests.get('https://api.github.com/repos/requests/requests/git/commits/a050faf084662f3a352dd1a941f2c7c9f886d4ad')
|
||||
|
||||
We should confirm that GitHub responded correctly. If it has, we want to work
|
||||
out what type of content it is. Do this like so::
|
||||
@@ -767,12 +660,12 @@ So, GitHub returns JSON. That's great, we can use the :meth:`r.json
|
||||
>>> commit_data = r.json()
|
||||
|
||||
>>> print(commit_data.keys())
|
||||
['committer', 'author', 'url', 'tree', 'sha', 'parents', 'message']
|
||||
[u'committer', u'author', u'url', u'tree', u'sha', u'parents', u'message']
|
||||
|
||||
>>> print(commit_data['committer'])
|
||||
{'date': '2012-05-10T11:10:50-07:00', 'email': 'me@kennethreitz.com', 'name': 'Kenneth Reitz'}
|
||||
>>> print(commit_data[u'committer'])
|
||||
{u'date': u'2012-05-10T11:10:50-07:00', u'email': u'me@kennethreitz.com', u'name': u'Kenneth Reitz'}
|
||||
|
||||
>>> print(commit_data['message'])
|
||||
>>> print(commit_data[u'message'])
|
||||
makin' history
|
||||
|
||||
So far, so simple. Well, let's investigate the GitHub API a little bit. Now,
|
||||
@@ -804,37 +697,37 @@ we should probably avoid making ham-handed POSTS to it. Instead, let's play
|
||||
with the Issues feature of GitHub.
|
||||
|
||||
This documentation was added in response to
|
||||
`Issue #482 <https://github.com/psf/requests/issues/482>`_. Given that
|
||||
`Issue #482 <https://github.com/requests/requests/issues/482>`_. Given that
|
||||
this issue already exists, we will use it as an example. Let's start by getting it.
|
||||
|
||||
::
|
||||
|
||||
>>> r = requests.get('https://api.github.com/repos/psf/requests/issues/482')
|
||||
>>> r = requests.get('https://api.github.com/repos/requests/requests/issues/482')
|
||||
>>> r.status_code
|
||||
200
|
||||
|
||||
>>> issue = json.loads(r.text)
|
||||
|
||||
>>> print(issue['title'])
|
||||
>>> print(issue[u'title'])
|
||||
Feature any http verb in docs
|
||||
|
||||
>>> print(issue['comments'])
|
||||
>>> print(issue[u'comments'])
|
||||
3
|
||||
|
||||
Cool, we have three comments. Let's take a look at the last of them.
|
||||
|
||||
::
|
||||
|
||||
>>> r = requests.get(r.url + '/comments')
|
||||
>>> r = requests.get(r.url + u'/comments')
|
||||
>>> r.status_code
|
||||
200
|
||||
|
||||
>>> comments = r.json()
|
||||
|
||||
>>> print(comments[0].keys())
|
||||
['body', 'url', 'created_at', 'updated_at', 'user', 'id']
|
||||
[u'body', u'url', u'created_at', u'updated_at', u'user', u'id']
|
||||
|
||||
>>> print(comments[2]['body'])
|
||||
>>> print(comments[2][u'body'])
|
||||
Probably in the "advanced" section
|
||||
|
||||
Well, that seems like a silly place. Let's post a comment telling the poster
|
||||
@@ -842,7 +735,7 @@ that he's silly. Who is the poster, anyway?
|
||||
|
||||
::
|
||||
|
||||
>>> print(comments[2]['user']['login'])
|
||||
>>> print(comments[2][u'user'][u'login'])
|
||||
kennethreitz
|
||||
|
||||
OK, so let's tell this Kenneth guy that we think this example should go in the
|
||||
@@ -852,7 +745,7 @@ is to POST to the thread. Let's do it.
|
||||
::
|
||||
|
||||
>>> body = json.dumps({u"body": u"Sounds great! I'll get right on it!"})
|
||||
>>> url = u"https://api.github.com/repos/psf/requests/issues/482/comments"
|
||||
>>> url = u"https://api.github.com/repos/requests/requests/issues/482/comments"
|
||||
|
||||
>>> r = requests.post(url=url, data=body)
|
||||
>>> r.status_code
|
||||
@@ -872,7 +765,7 @@ the very common Basic Auth.
|
||||
201
|
||||
|
||||
>>> content = r.json()
|
||||
>>> print(content['body'])
|
||||
>>> print(content[u'body'])
|
||||
Sounds great! I'll get right on it.
|
||||
|
||||
Brilliant. Oh, wait, no! I meant to add that it would take me a while, because
|
||||
@@ -886,7 +779,7 @@ that.
|
||||
5804413
|
||||
|
||||
>>> body = json.dumps({u"body": u"Sounds great! I'll get right on it once I feed my cat."})
|
||||
>>> url = u"https://api.github.com/repos/psf/requests/issues/comments/5804413"
|
||||
>>> url = u"https://api.github.com/repos/requests/requests/issues/comments/5804413"
|
||||
|
||||
>>> r = requests.patch(url=url, data=body, auth=auth)
|
||||
>>> r.status_code
|
||||
@@ -948,7 +841,7 @@ Link Headers
|
||||
Many HTTP APIs feature Link headers. They make APIs more self describing and
|
||||
discoverable.
|
||||
|
||||
GitHub uses these for `pagination <https://docs.github.com/en/rest/guides/using-pagination-in-the-rest-api>`_
|
||||
GitHub uses these for `pagination <http://developer.github.com/v3/#pagination>`_
|
||||
in their API, for example::
|
||||
|
||||
>>> url = 'https://api.github.com/users/kennethreitz/repos?page=1&per_page=10'
|
||||
@@ -990,16 +883,12 @@ it should apply to.
|
||||
::
|
||||
|
||||
>>> s = requests.Session()
|
||||
>>> s.mount('https://github.com/', MyAdapter())
|
||||
>>> s.mount('http://www.github.com', MyAdapter())
|
||||
|
||||
The mount call registers a specific instance of a Transport Adapter to a
|
||||
prefix. Once mounted, any HTTP request made using that session whose URL starts
|
||||
with the given prefix will use the given Transport Adapter.
|
||||
|
||||
.. note:: The adapter will be chosen based on a longest prefix match. Be mindful
|
||||
prefixes such as ``http://localhost`` will also match ``http://localhost.other.com``
|
||||
or ``http://localhost@other.com``. It's recommended to terminate full hostnames with a ``/``.
|
||||
|
||||
Many of the details of implementing a Transport Adapter are beyond the scope of
|
||||
this documentation, but take a look at the next example for a simple SSL use-
|
||||
case. For more than that, you might look at subclassing the
|
||||
@@ -1019,9 +908,9 @@ passed-through to `urllib3`. We'll make a Transport Adapter that instructs the
|
||||
library to use SSLv3::
|
||||
|
||||
import ssl
|
||||
from urllib3.poolmanager import PoolManager
|
||||
|
||||
from requests.adapters import HTTPAdapter
|
||||
from requests.packages.urllib3.poolmanager import PoolManager
|
||||
|
||||
|
||||
class Ssl3HttpAdapter(HTTPAdapter):
|
||||
@@ -1032,30 +921,8 @@ library to use SSLv3::
|
||||
num_pools=connections, maxsize=maxsize,
|
||||
block=block, ssl_version=ssl.PROTOCOL_SSLv3)
|
||||
|
||||
Example: Automatic Retries
|
||||
^^^^^^^^^^^^^^^^^^^^^^^^^^
|
||||
|
||||
By default, Requests does not retry failed connections. However, it is possible
|
||||
to implement automatic retries with a powerful array of features, including
|
||||
backoff, within a Requests :class:`Session <requests.Session>` using the
|
||||
`urllib3.util.Retry`_ class::
|
||||
|
||||
from urllib3.util import Retry
|
||||
from requests import Session
|
||||
from requests.adapters import HTTPAdapter
|
||||
|
||||
s = Session()
|
||||
retries = Retry(
|
||||
total=3,
|
||||
backoff_factor=0.1,
|
||||
status_forcelist=[502, 503, 504],
|
||||
allowed_methods={'POST'},
|
||||
)
|
||||
s.mount('https://', HTTPAdapter(max_retries=retries))
|
||||
|
||||
.. _`described here`: https://kenreitz.org/essays/2012/06/14/the-future-of-python-http
|
||||
.. _`urllib3`: https://github.com/urllib3/urllib3
|
||||
.. _`urllib3.util.Retry`: https://urllib3.readthedocs.io/en/stable/reference/urllib3.util.html#urllib3.util.Retry
|
||||
.. _`described here`: http://www.kennethreitz.org/essays/the-future-of-python-http
|
||||
.. _`urllib3`: https://github.com/shazow/urllib3
|
||||
|
||||
.. _blocking-or-nonblocking:
|
||||
|
||||
@@ -1071,19 +938,17 @@ response at a time. However, these calls will still block.
|
||||
|
||||
If you are concerned about the use of blocking IO, there are lots of projects
|
||||
out there that combine Requests with one of Python's asynchronicity frameworks.
|
||||
Some excellent examples are `requests-threads`_, `grequests`_, `requests-futures`_, and `httpx`_.
|
||||
Two excellent examples are `grequests`_ and `requests-futures`_.
|
||||
|
||||
.. _`requests-threads`: https://github.com/requests/requests-threads
|
||||
.. _`grequests`: https://github.com/spyoungtech/grequests
|
||||
.. _`grequests`: https://github.com/kennethreitz/grequests
|
||||
.. _`requests-futures`: https://github.com/ross/requests-futures
|
||||
.. _`httpx`: https://github.com/encode/httpx
|
||||
|
||||
Header Ordering
|
||||
---------------
|
||||
|
||||
In unusual circumstances you may want to provide headers in an ordered manner. If you pass an ``OrderedDict`` to the ``headers`` keyword argument, that will provide the headers with an ordering. *However*, the ordering of the default headers used by Requests will be preferred, which means that if you override default headers in the ``headers`` keyword argument, they may appear out of order compared to other headers in that keyword argument.
|
||||
|
||||
If this is problematic, users should consider setting the default headers on a :class:`Session <requests.Session>` object, by setting :attr:`Session.headers <requests.Session.headers>` to a custom ``OrderedDict``. That ordering will always be preferred.
|
||||
If this is problematic, users should consider setting the default headers on a :class:`Session <requests.Session>` object, by setting :attr:`Session <requests.Session.headers>` to a custom ``OrderedDict``. That ordering will always be preferred.
|
||||
|
||||
.. _timeouts:
|
||||
|
||||
@@ -1099,7 +964,7 @@ The **connect** timeout is the number of seconds Requests will wait for your
|
||||
client to establish a connection to a remote machine (corresponding to the
|
||||
`connect()`_) call on the socket. It's a good practice to set connect timeouts
|
||||
to slightly larger than a multiple of 3, which is the default `TCP packet
|
||||
retransmission window <https://datatracker.ietf.org/doc/html/rfc2988>`_.
|
||||
retransmission window <http://www.hjp.at/doc/rfc/rfc2988.txt>`_.
|
||||
|
||||
Once your client has connected to the server and sent the HTTP request, the
|
||||
**read** timeout is the number of seconds the client will wait for the server
|
||||
@@ -1124,18 +989,4 @@ coffee.
|
||||
|
||||
r = requests.get('https://github.com', timeout=None)
|
||||
|
||||
.. note:: The connect timeout applies to each connection attempt to an IP address.
|
||||
If multiple addresses exist for a domain name, the underlying ``urllib3`` will
|
||||
try each address sequentially until one successfully connects.
|
||||
This may lead to an effective total connection timeout *multiple* times longer
|
||||
than the specified time, e.g. an unresponsive server having both IPv4 and IPv6
|
||||
addresses will have its perceived timeout *doubled*, so take that into account
|
||||
when setting the connection timeout.
|
||||
.. note:: Neither the connect nor read timeouts are `wall clock`_. This means
|
||||
that if you start a request, and look at the time, and then look at
|
||||
the time when the request finishes or times out, the real-world time
|
||||
may be greater than what you specified.
|
||||
|
||||
|
||||
.. _`wall clock`: https://wiki.php.net/rfc/max_execution_wall_time
|
||||
.. _`connect()`: https://linux.die.net/man/2/connect
|
||||
.. _`connect()`: http://linux.die.net/man/2/connect
|
||||
|
||||
@@ -19,14 +19,13 @@ the simplest kind, and Requests supports it straight out of the box.
|
||||
Making requests with HTTP Basic Auth is very simple::
|
||||
|
||||
>>> from requests.auth import HTTPBasicAuth
|
||||
>>> basic = HTTPBasicAuth('user', 'pass')
|
||||
>>> requests.get('https://httpbin.org/basic-auth/user/pass', auth=basic)
|
||||
>>> requests.get('https://api.github.com/user', auth=HTTPBasicAuth('user', 'pass'))
|
||||
<Response [200]>
|
||||
|
||||
In fact, HTTP Basic Auth is so common that Requests provides a handy shorthand
|
||||
for using it::
|
||||
|
||||
>>> requests.get('https://httpbin.org/basic-auth/user/pass', auth=('user', 'pass'))
|
||||
>>> requests.get('https://api.github.com/user', auth=('user', 'pass'))
|
||||
<Response [200]>
|
||||
|
||||
Providing the credentials in a tuple like this is exactly the same as the
|
||||
@@ -52,7 +51,7 @@ Another very popular form of HTTP Authentication is Digest Authentication,
|
||||
and Requests supports this out of the box as well::
|
||||
|
||||
>>> from requests.auth import HTTPDigestAuth
|
||||
>>> url = 'https://httpbin.org/digest-auth/auth/user/pass'
|
||||
>>> url = 'http://httpbin.org/digest-auth/auth/user/pass'
|
||||
>>> requests.get(url, auth=HTTPDigestAuth('user', 'pass'))
|
||||
<Response [200]>
|
||||
|
||||
@@ -121,7 +120,7 @@ To do so, subclass :class:`AuthBase <requests.auth.AuthBase>` and implement the
|
||||
... # Implement my authentication
|
||||
... return r
|
||||
...
|
||||
>>> url = 'https://httpbin.org/get'
|
||||
>>> url = 'http://httpbin.org/get'
|
||||
>>> requests.get(url, auth=MyAuth())
|
||||
<Response [200]>
|
||||
|
||||
@@ -133,13 +132,13 @@ authentication will additionally add hooks to provide further functionality.
|
||||
Further examples can be found under the `Requests organization`_ and in the
|
||||
``auth.py`` file.
|
||||
|
||||
.. _OAuth: https://oauth.net/
|
||||
.. _OAuth: http://oauth.net/
|
||||
.. _requests_oauthlib: https://github.com/requests/requests-oauthlib
|
||||
.. _requests-oauthlib OAuth2 documentation: https://requests-oauthlib.readthedocs.io/en/latest/oauth2_workflow.html
|
||||
.. _Web Application Flow: https://requests-oauthlib.readthedocs.io/en/latest/oauth2_workflow.html#web-application-flow
|
||||
.. _Mobile Application Flow: https://requests-oauthlib.readthedocs.io/en/latest/oauth2_workflow.html#mobile-application-flow
|
||||
.. _Legacy Application Flow: https://requests-oauthlib.readthedocs.io/en/latest/oauth2_workflow.html#legacy-application-flow
|
||||
.. _Backend Application Flow: https://requests-oauthlib.readthedocs.io/en/latest/oauth2_workflow.html#backend-application-flow
|
||||
.. _requests-oauthlib OAuth2 documentation: http://requests-oauthlib.readthedocs.io/en/latest/oauth2_workflow.html
|
||||
.. _Web Application Flow: http://requests-oauthlib.readthedocs.io/en/latest/oauth2_workflow.html#web-application-flow
|
||||
.. _Mobile Application Flow: http://requests-oauthlib.readthedocs.io/en/latest/oauth2_workflow.html#mobile-application-flow
|
||||
.. _Legacy Application Flow: http://requests-oauthlib.readthedocs.io/en/latest/oauth2_workflow.html#legacy-application-flow
|
||||
.. _Backend Application Flow: http://requests-oauthlib.readthedocs.io/en/latest/oauth2_workflow.html#backend-application-flow
|
||||
.. _Kerberos: https://github.com/requests/requests-kerberos
|
||||
.. _NTLM: https://github.com/requests/requests-ntlm
|
||||
.. _Requests organization: https://github.com/requests
|
||||
|
||||
@@ -1,36 +1,39 @@
|
||||
.. _install:
|
||||
|
||||
Installation of Requests
|
||||
========================
|
||||
Installation
|
||||
============
|
||||
|
||||
This part of the documentation covers the installation of Requests.
|
||||
The first step to using any software package is getting it properly installed.
|
||||
|
||||
|
||||
$ python -m pip install requests
|
||||
--------------------------------
|
||||
Pip Install Requests
|
||||
--------------------
|
||||
|
||||
To install Requests, simply run this simple command in your terminal of choice::
|
||||
|
||||
$ python -m pip install requests
|
||||
$ pip install requests
|
||||
|
||||
If you don't have `pip <https://pip.pypa.io>`_ installed (tisk tisk!),
|
||||
`this Python installation guide <http://docs.python-guide.org/en/latest/starting/installation/>`_
|
||||
can guide you through the process.
|
||||
|
||||
Get the Source Code
|
||||
-------------------
|
||||
|
||||
Requests is actively developed on GitHub, where the code is
|
||||
`always available <https://github.com/psf/requests>`_.
|
||||
`always available <https://github.com/requests/requests>`_.
|
||||
|
||||
You can either clone the public repository::
|
||||
|
||||
$ git clone https://github.com/psf/requests.git
|
||||
$ git clone git://github.com/requests/requests.git
|
||||
|
||||
Or, download the `tarball <https://github.com/psf/requests/tarball/main>`_::
|
||||
Or, download the `tarball <https://github.com/requests/requests/tarball/master>`_::
|
||||
|
||||
$ curl -OL https://github.com/psf/requests/tarball/main
|
||||
# optionally, zipball is also available (for Windows users).
|
||||
$ curl -OL https://github.com/requests/requests/tarball/master
|
||||
# optionally, zipball is also available (for Windows users).
|
||||
|
||||
Once you have a copy of the source, you can embed it in your own Python
|
||||
package, or install it into your site-packages easily::
|
||||
|
||||
$ cd requests
|
||||
$ python -m pip install .
|
||||
$ python setup.py install
|
||||
|
||||
45
docs/user/intro.rst
Normal file
@@ -0,0 +1,45 @@
|
||||
.. _introduction:
|
||||
|
||||
Introduction
|
||||
============
|
||||
|
||||
Philosophy
|
||||
----------
|
||||
|
||||
Requests was developed with a few :pep:`20` idioms in mind.
|
||||
|
||||
|
||||
#. Beautiful is better than ugly.
|
||||
#. Explicit is better than implicit.
|
||||
#. Simple is better than complex.
|
||||
#. Complex is better than complicated.
|
||||
#. Readability counts.
|
||||
|
||||
All contributions to Requests should keep these important rules in mind.
|
||||
|
||||
.. _`apache2`:
|
||||
|
||||
Apache2 License
|
||||
---------------
|
||||
|
||||
A large number of open source projects you find today are `GPL Licensed`_.
|
||||
While the GPL has its time and place, it should most certainly not be your
|
||||
go-to license for your next open source project.
|
||||
|
||||
A project that is released as GPL cannot be used in any commercial product
|
||||
without the product itself also being offered as open source.
|
||||
|
||||
The MIT, BSD, ISC, and Apache2 licenses are great alternatives to the GPL
|
||||
that allow your open-source software to be used freely in proprietary,
|
||||
closed-source software.
|
||||
|
||||
Requests is released under terms of `Apache2 License`_.
|
||||
|
||||
.. _`GPL Licensed`: http://www.opensource.org/licenses/gpl-license.php
|
||||
.. _`Apache2 License`: http://opensource.org/licenses/Apache-2.0
|
||||
|
||||
|
||||
Requests License
|
||||
----------------
|
||||
|
||||
.. include:: ../../LICENSE
|
||||
@@ -37,15 +37,15 @@ get all the information we need from this object.
|
||||
Requests' simple API means that all forms of HTTP request are as obvious. For
|
||||
example, this is how you make an HTTP POST request::
|
||||
|
||||
>>> r = requests.post('https://httpbin.org/post', data={'key': 'value'})
|
||||
>>> r = requests.post('http://httpbin.org/post', data = {'key':'value'})
|
||||
|
||||
Nice, right? What about the other HTTP request types: PUT, DELETE, HEAD and
|
||||
OPTIONS? These are all just as simple::
|
||||
|
||||
>>> r = requests.put('https://httpbin.org/put', data={'key': 'value'})
|
||||
>>> r = requests.delete('https://httpbin.org/delete')
|
||||
>>> r = requests.head('https://httpbin.org/get')
|
||||
>>> r = requests.options('https://httpbin.org/get')
|
||||
>>> r = requests.put('http://httpbin.org/put', data = {'key':'value'})
|
||||
>>> r = requests.delete('http://httpbin.org/delete')
|
||||
>>> r = requests.head('http://httpbin.org/get')
|
||||
>>> r = requests.options('http://httpbin.org/get')
|
||||
|
||||
That's all well and good, but it's also only the start of what Requests can
|
||||
do.
|
||||
@@ -63,12 +63,12 @@ using the ``params`` keyword argument. As an example, if you wanted to pass
|
||||
following code::
|
||||
|
||||
>>> payload = {'key1': 'value1', 'key2': 'value2'}
|
||||
>>> r = requests.get('https://httpbin.org/get', params=payload)
|
||||
>>> r = requests.get('http://httpbin.org/get', params=payload)
|
||||
|
||||
You can see that the URL has been correctly encoded by printing the URL::
|
||||
|
||||
>>> print(r.url)
|
||||
https://httpbin.org/get?key2=value2&key1=value1
|
||||
http://httpbin.org/get?key2=value2&key1=value1
|
||||
|
||||
Note that any dictionary key whose value is ``None`` will not be added to the
|
||||
URL's query string.
|
||||
@@ -77,9 +77,9 @@ You can also pass a list of items as a value::
|
||||
|
||||
>>> payload = {'key1': 'value1', 'key2': ['value2', 'value3']}
|
||||
|
||||
>>> r = requests.get('https://httpbin.org/get', params=payload)
|
||||
>>> r = requests.get('http://httpbin.org/get', params=payload)
|
||||
>>> print(r.url)
|
||||
https://httpbin.org/get?key1=value1&key2=value2&key2=value3
|
||||
http://httpbin.org/get?key1=value1&key2=value2&key2=value3
|
||||
|
||||
Response Content
|
||||
----------------
|
||||
@@ -91,7 +91,7 @@ again::
|
||||
|
||||
>>> r = requests.get('https://api.github.com/events')
|
||||
>>> r.text
|
||||
'[{"repository":{"open_issues":0,"url":"https://github.com/...
|
||||
u'[{"repository":{"open_issues":0,"url":"https://github.com/...
|
||||
|
||||
Requests will automatically decode content from the server. Most unicode
|
||||
charsets are seamlessly decoded.
|
||||
@@ -108,7 +108,7 @@ using, and change it, using the ``r.encoding`` property::
|
||||
If you change the encoding, Requests will use the new value of ``r.encoding``
|
||||
whenever you call ``r.text``. You might want to do this in any situation where
|
||||
you can apply special logic to work out what the encoding of the content will
|
||||
be. For example, HTML and XML have the ability to specify their encoding in
|
||||
be. For example, HTTP and XML have the ability to specify their encoding in
|
||||
their body. In situations like this, you should use ``r.content`` to find the
|
||||
encoding, and then set ``r.encoding``. This will let you use ``r.text`` with
|
||||
the correct encoding.
|
||||
@@ -128,9 +128,6 @@ You can also access the response body as bytes, for non-text requests::
|
||||
|
||||
The ``gzip`` and ``deflate`` transfer-encodings are automatically decoded for you.
|
||||
|
||||
The ``br`` transfer-encoding is automatically decoded for you if a Brotli library
|
||||
like `brotli <https://pypi.org/project/brotli>`_ or `brotlicffi <https://pypi.org/project/brotlicffi>`_ is installed.
|
||||
|
||||
For example, to create an image from binary data returned by a request, you can
|
||||
use the following code::
|
||||
|
||||
@@ -149,13 +146,11 @@ There's also a builtin JSON decoder, in case you're dealing with JSON data::
|
||||
|
||||
>>> r = requests.get('https://api.github.com/events')
|
||||
>>> r.json()
|
||||
[{'repository': {'open_issues': 0, 'url': 'https://github.com/...
|
||||
[{u'repository': {u'open_issues': 0, u'url': 'https://github.com/...
|
||||
|
||||
In case the JSON decoding fails, ``r.json()`` raises an exception. For example, if
|
||||
the response gets a 204 (No Content), or if the response contains invalid JSON,
|
||||
attempting ``r.json()`` raises ``requests.exceptions.JSONDecodeError``. This wrapper exception
|
||||
provides interoperability for multiple exceptions that may be thrown by different
|
||||
python versions and json serialization libraries.
|
||||
attempting ``r.json()`` raises ``ValueError: No JSON object could be decoded``.
|
||||
|
||||
It should be noted that the success of the call to ``r.json()`` does **not**
|
||||
indicate the success of the response. Some servers may return a JSON object in a
|
||||
@@ -174,10 +169,10 @@ server, you can access ``r.raw``. If you want to do this, make sure you set
|
||||
>>> r = requests.get('https://api.github.com/events', stream=True)
|
||||
|
||||
>>> r.raw
|
||||
<urllib3.response.HTTPResponse object at 0x101194810>
|
||||
<requests.packages.urllib3.response.HTTPResponse object at 0x101194810>
|
||||
|
||||
>>> r.raw.read(10)
|
||||
b'\x1f\x8b\x08\x00\x00\x00\x00\x00\x00\x03'
|
||||
'\x1f\x8b\x08\x00\x00\x00\x00\x00\x00\x03'
|
||||
|
||||
In general, however, you should use a pattern like this to save what is being
|
||||
streamed to a file::
|
||||
@@ -192,16 +187,6 @@ download, the above is the preferred and recommended way to retrieve the
|
||||
content. Note that ``chunk_size`` can be freely adjusted to a number that
|
||||
may better fit your use cases.
|
||||
|
||||
.. note::
|
||||
|
||||
An important note about using ``Response.iter_content`` versus ``Response.raw``.
|
||||
``Response.iter_content`` will automatically decode the ``gzip`` and ``deflate``
|
||||
transfer-encodings. ``Response.raw`` is a raw stream of bytes -- it does not
|
||||
transform the response content. If you really need access to the bytes as they
|
||||
were returned, use ``Response.raw``.
|
||||
|
||||
|
||||
.. _custom-headers:
|
||||
|
||||
Custom Headers
|
||||
--------------
|
||||
@@ -220,8 +205,7 @@ Note: Custom headers are given less precedence than more specific sources of inf
|
||||
|
||||
* Authorization headers set with `headers=` will be overridden if credentials
|
||||
are specified in ``.netrc``, which in turn will be overridden by the ``auth=``
|
||||
parameter. Requests will search for the netrc file at `~/.netrc`, `~/_netrc`,
|
||||
or at the path specified by the `NETRC` environment variable.
|
||||
parameter.
|
||||
* Authorization headers will be removed if you get redirected off-host.
|
||||
* Proxy-Authorization headers will be overridden by proxy credentials provided in the URL.
|
||||
* Content-Length headers will be overridden when we can determine the length of the content.
|
||||
@@ -239,7 +223,7 @@ dictionary of data will automatically be form-encoded when the request is made::
|
||||
|
||||
>>> payload = {'key1': 'value1', 'key2': 'value2'}
|
||||
|
||||
>>> r = requests.post('https://httpbin.org/post', data=payload)
|
||||
>>> r = requests.post("http://httpbin.org/post", data=payload)
|
||||
>>> print(r.text)
|
||||
{
|
||||
...
|
||||
@@ -250,16 +234,12 @@ dictionary of data will automatically be form-encoded when the request is made::
|
||||
...
|
||||
}
|
||||
|
||||
The ``data`` argument can also have multiple values for each key. This can be
|
||||
done by making ``data`` either a list of tuples or a dictionary with lists
|
||||
as values. This is particularly useful when the form has multiple elements that
|
||||
use the same key::
|
||||
You can also pass a list of tuples to the ``data`` argument. This is particularly
|
||||
useful when the form has multiple elements that use the same key::
|
||||
|
||||
>>> payload_tuples = [('key1', 'value1'), ('key1', 'value2')]
|
||||
>>> r1 = requests.post('https://httpbin.org/post', data=payload_tuples)
|
||||
>>> payload_dict = {'key1': ['value1', 'value2']}
|
||||
>>> r2 = requests.post('https://httpbin.org/post', data=payload_dict)
|
||||
>>> print(r1.text)
|
||||
>>> payload = (('key1', 'value1'), ('key1', 'value2'))
|
||||
>>> r = requests.post('http://httpbin.org/post', data=payload)
|
||||
>>> print(r.text)
|
||||
{
|
||||
...
|
||||
"form": {
|
||||
@@ -270,8 +250,6 @@ use the same key::
|
||||
},
|
||||
...
|
||||
}
|
||||
>>> r1.text == r2.text
|
||||
True
|
||||
|
||||
There are times that you may want to send data that is not form-encoded. If
|
||||
you pass in a ``string`` instead of a ``dict``, that data will be posted directly.
|
||||
@@ -285,26 +263,21 @@ For example, the GitHub API v3 accepts JSON-Encoded POST/PATCH data::
|
||||
|
||||
>>> r = requests.post(url, data=json.dumps(payload))
|
||||
|
||||
Please note that the above code will NOT add the ``Content-Type`` header
|
||||
(so in particular it will NOT set it to ``application/json``).
|
||||
|
||||
If you need that header set and you don't want to encode the ``dict`` yourself,
|
||||
you can also pass it directly using the ``json`` parameter (added in version 2.4.2)
|
||||
and it will be encoded automatically:
|
||||
Instead of encoding the ``dict`` yourself, you can also pass it directly using
|
||||
the ``json`` parameter (added in version 2.4.2) and it will be encoded automatically::
|
||||
|
||||
>>> url = 'https://api.github.com/some/endpoint'
|
||||
>>> payload = {'some': 'data'}
|
||||
|
||||
>>> r = requests.post(url, json=payload)
|
||||
|
||||
Note, the ``json`` parameter is ignored if either ``data`` or ``files`` is passed.
|
||||
|
||||
POST a Multipart-Encoded File
|
||||
-----------------------------
|
||||
|
||||
Requests makes it simple to upload Multipart-encoded files::
|
||||
|
||||
>>> url = 'https://httpbin.org/post'
|
||||
>>> url = 'http://httpbin.org/post'
|
||||
>>> files = {'file': open('report.xls', 'rb')}
|
||||
|
||||
>>> r = requests.post(url, files=files)
|
||||
@@ -319,7 +292,7 @@ Requests makes it simple to upload Multipart-encoded files::
|
||||
|
||||
You can set the filename, content_type and headers explicitly::
|
||||
|
||||
>>> url = 'https://httpbin.org/post'
|
||||
>>> url = 'http://httpbin.org/post'
|
||||
>>> files = {'file': ('report.xls', open('report.xls', 'rb'), 'application/vnd.ms-excel', {'Expires': '0'})}
|
||||
|
||||
>>> r = requests.post(url, files=files)
|
||||
@@ -334,7 +307,7 @@ You can set the filename, content_type and headers explicitly::
|
||||
|
||||
If you want, you can send strings to be received as files::
|
||||
|
||||
>>> url = 'https://httpbin.org/post'
|
||||
>>> url = 'http://httpbin.org/post'
|
||||
>>> files = {'file': ('report.csv', 'some,data,to,send\nanother,row,to,send\n')}
|
||||
|
||||
>>> r = requests.post(url, files=files)
|
||||
@@ -356,11 +329,13 @@ support this, but there is a separate package which does -
|
||||
For sending multiple files in one request refer to the :ref:`advanced <advanced>`
|
||||
section.
|
||||
|
||||
.. warning:: It is strongly recommended that you open files in :ref:`binary
|
||||
mode <tut-files>`. This is because Requests may attempt to provide
|
||||
the ``Content-Length`` header for you, and if it does this value
|
||||
will be set to the number of *bytes* in the file. Errors may occur
|
||||
if you open the file in *text mode*.
|
||||
.. warning:: It is strongly recommended that you open files in `binary mode`_.
|
||||
This is because Requests may attempt to provide the
|
||||
``Content-Length`` header for you, and if it does this value will
|
||||
be set to the number of *bytes* in the file. Errors may occur if
|
||||
you open the file in *text mode*.
|
||||
|
||||
.. _binary mode: https://docs.python.org/2/tutorial/inputoutput.html#reading-and-writing-files
|
||||
|
||||
|
||||
Response Status Codes
|
||||
@@ -368,7 +343,7 @@ Response Status Codes
|
||||
|
||||
We can check the response status code::
|
||||
|
||||
>>> r = requests.get('https://httpbin.org/get')
|
||||
>>> r = requests.get('http://httpbin.org/get')
|
||||
>>> r.status_code
|
||||
200
|
||||
|
||||
@@ -382,7 +357,7 @@ If we made a bad request (a 4XX client error or 5XX server error response), we
|
||||
can raise it with
|
||||
:meth:`Response.raise_for_status() <requests.Response.raise_for_status>`::
|
||||
|
||||
>>> bad_r = requests.get('https://httpbin.org/status/404')
|
||||
>>> bad_r = requests.get('http://httpbin.org/status/404')
|
||||
>>> bad_r.status_code
|
||||
404
|
||||
|
||||
@@ -418,7 +393,7 @@ We can view the server's response headers using a Python dictionary::
|
||||
}
|
||||
|
||||
The dictionary is special, though: it's made just for HTTP headers. According to
|
||||
`RFC 7230 <https://tools.ietf.org/html/rfc7230#section-3.2>`_, HTTP Header names
|
||||
`RFC 7230 <http://tools.ietf.org/html/rfc7230#section-3.2>`_, HTTP Header names
|
||||
are case-insensitive.
|
||||
|
||||
So, we can access the headers using any capitalization we want::
|
||||
@@ -432,7 +407,7 @@ So, we can access the headers using any capitalization we want::
|
||||
It is also special in that the server could have sent the same header multiple
|
||||
times with different values, but requests combines them so they can be
|
||||
represented in the dictionary within a single mapping, as per
|
||||
`RFC 7230 <https://tools.ietf.org/html/rfc7230#section-3.2>`_:
|
||||
`RFC 7230 <http://tools.ietf.org/html/rfc7230#section-3.2>`_:
|
||||
|
||||
A recipient MAY combine multiple header fields with the same field name
|
||||
into one "field-name: field-value" pair, without changing the semantics
|
||||
@@ -453,7 +428,7 @@ If a response contains some Cookies, you can quickly access them::
|
||||
To send your own cookies to the server, you can use the ``cookies``
|
||||
parameter::
|
||||
|
||||
>>> url = 'https://httpbin.org/cookies'
|
||||
>>> url = 'http://httpbin.org/cookies'
|
||||
>>> cookies = dict(cookies_are='working')
|
||||
|
||||
>>> r = requests.get(url, cookies=cookies)
|
||||
@@ -468,7 +443,7 @@ also be passed in to requests::
|
||||
>>> jar = requests.cookies.RequestsCookieJar()
|
||||
>>> jar.set('tasty_cookie', 'yum', domain='httpbin.org', path='/cookies')
|
||||
>>> jar.set('gross_cookie', 'blech', domain='httpbin.org', path='/elsewhere')
|
||||
>>> url = 'https://httpbin.org/cookies'
|
||||
>>> url = 'http://httpbin.org/cookies'
|
||||
>>> r = requests.get(url, cookies=jar)
|
||||
>>> r.text
|
||||
'{"cookies": {"tasty_cookie": "yum"}}'
|
||||
@@ -489,7 +464,7 @@ response.
|
||||
|
||||
For example, GitHub redirects all HTTP requests to HTTPS::
|
||||
|
||||
>>> r = requests.get('http://github.com/')
|
||||
>>> r = requests.get('http://github.com')
|
||||
|
||||
>>> r.url
|
||||
'https://github.com/'
|
||||
@@ -504,7 +479,7 @@ For example, GitHub redirects all HTTP requests to HTTPS::
|
||||
If you're using GET, OPTIONS, POST, PUT, PATCH or DELETE, you can disable
|
||||
redirection handling with the ``allow_redirects`` parameter::
|
||||
|
||||
>>> r = requests.get('http://github.com/', allow_redirects=False)
|
||||
>>> r = requests.get('http://github.com', allow_redirects=False)
|
||||
|
||||
>>> r.status_code
|
||||
301
|
||||
@@ -514,7 +489,7 @@ redirection handling with the ``allow_redirects`` parameter::
|
||||
|
||||
If you're using HEAD, you can enable redirection as well::
|
||||
|
||||
>>> r = requests.head('http://github.com/', allow_redirects=True)
|
||||
>>> r = requests.head('http://github.com', allow_redirects=True)
|
||||
|
||||
>>> r.url
|
||||
'https://github.com/'
|
||||
@@ -531,7 +506,7 @@ seconds with the ``timeout`` parameter. Nearly all production code should use
|
||||
this parameter in nearly all requests. Failure to do so can cause your program
|
||||
to hang indefinitely::
|
||||
|
||||
>>> requests.get('https://github.com/', timeout=0.001)
|
||||
>>> requests.get('http://github.com', timeout=0.001)
|
||||
Traceback (most recent call last):
|
||||
File "<stdin>", line 1, in <module>
|
||||
requests.exceptions.Timeout: HTTPConnectionPool(host='github.com', port=80): Request timed out. (timeout=0.001)
|
||||
|
||||
@@ -1 +0,0 @@
|
||||
Copyright 2019 Kenneth Reitz. All rights reserved.
|
||||

|
Before Width: | Height: | Size: 14 KiB |

|
Before Width: | Height: | Size: 5.8 KiB |
BIN
ext/kr.png

|
Before Width: | Height: | Size: 9.2 KiB |

|
Before Width: | Height: | Size: 12 KiB |
BIN
ext/psf.png

|
Before Width: | Height: | Size: 14 KiB |

|
Before Width: | Height: | Size: 188 KiB |

|
Before Width: | Height: | Size: 188 KiB |

|
Before Width: | Height: | Size: 363 KiB |
BIN
ext/ss.png

|
Before Width: | Height: | Size: 363 KiB |
@@ -1,10 +0,0 @@
|
||||
[tool.isort]
|
||||
profile = "black"
|
||||
src_paths = ["src/requests", "test"]
|
||||
honor_noqa = true
|
||||
|
||||
[tool.pytest.ini_options]
|
||||
addopts = "--doctest-modules"
|
||||
doctest_optionflags = "NORMALIZE_WHITESPACE ELLIPSIS"
|
||||
minversion = "6.2"
|
||||
testpaths = ["tests"]
|
||||
2
pytest.ini
Normal file
@@ -0,0 +1,2 @@
|
||||
[pytest]
|
||||
addopts = -p no:warnings
|
||||
113
requests/__init__.py
Normal file
@@ -0,0 +1,113 @@
|
||||
# -*- coding: utf-8 -*-
|
||||
|
||||
# __
|
||||
# /__) _ _ _ _ _/ _
|
||||
# / ( (- (/ (/ (- _) / _)
|
||||
# /
|
||||
|
||||
"""
|
||||
Requests HTTP Library
|
||||
~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
Requests is an HTTP library, written in Python, for human beings. Basic GET
|
||||
usage:
|
||||
|
||||
>>> import requests
|
||||
>>> r = requests.get('https://www.python.org')
|
||||
>>> r.status_code
|
||||
200
|
||||
>>> 'Python is a programming language' in r.content
|
||||
True
|
||||
|
||||
... or POST:
|
||||
|
||||
>>> payload = dict(key1='value1', key2='value2')
|
||||
>>> r = requests.post('http://httpbin.org/post', data=payload)
|
||||
>>> print(r.text)
|
||||
{
|
||||
...
|
||||
"form": {
|
||||
"key2": "value2",
|
||||
"key1": "value1"
|
||||
},
|
||||
...
|
||||
}
|
||||
|
||||
The other HTTP methods are supported - see `requests.api`. Full documentation
|
||||
is at <http://python-requests.org>.
|
||||
|
||||
:copyright: (c) 2017 by Kenneth Reitz.
|
||||
:license: Apache 2.0, see LICENSE for more details.
|
||||
"""
|
||||
|
||||
from .__version__ import __title__, __description__, __url__, __version__
|
||||
from .__version__ import __build__, __author__, __author_email__, __license__
|
||||
from .__version__ import __copyright__, __cake__
|
||||
|
||||
# Check urllib3 for compatibility.
|
||||
import urllib3
|
||||
urllib3_version = urllib3.__version__.split('.')
|
||||
# Sometimes, urllib3 only reports its version as 16.1.
|
||||
if len(urllib3_version) == 2:
|
||||
urllib3_version.append('0')
|
||||
major, minor, patch = urllib3_version
|
||||
major, minor, patch = int(major), int(minor), int(patch)
|
||||
# urllib3 >= 1.21.1, < 1.22
|
||||
try:
|
||||
assert major == 1
|
||||
assert minor >= 21
|
||||
assert minor <= 22
|
||||
except AssertionError:
|
||||
raise RuntimeError('Requests dependency \'urllib3\' must be version >= 1.21.1, < 1.22!')
|
||||
|
||||
|
||||
# Check chardet for compatibility.
|
||||
import chardet
|
||||
major, minor, patch = chardet.__version__.split('.')[:3]
|
||||
major, minor, patch = int(major), int(minor), int(patch)
|
||||
# chardet >= 3.0.2, < 3.1.0
|
||||
try:
|
||||
assert major == 3
|
||||
assert minor < 1
|
||||
assert patch >= 2
|
||||
except AssertionError:
|
||||
raise RuntimeError('Requests dependency \'chardet\' must be version >= 3.0.2, < 3.1.0!')
|
||||
|
||||
# Attempt to enable urllib3's SNI support, if possible
|
||||
try:
|
||||
from urllib3.contrib import pyopenssl
|
||||
pyopenssl.inject_into_urllib3()
|
||||
except ImportError:
|
||||
pass
|
||||
|
||||
import warnings
|
||||
|
||||
# urllib3's DependencyWarnings should be silenced.
|
||||
from urllib3.exceptions import DependencyWarning
|
||||
warnings.simplefilter('ignore', DependencyWarning)
|
||||
|
||||
from . import utils
|
||||
from . import packages
|
||||
from .models import Request, Response, PreparedRequest
|
||||
from .api import request, get, head, post, patch, put, delete, options
|
||||
from .sessions import session, Session
|
||||
from .status_codes import codes
|
||||
from .exceptions import (
|
||||
RequestException, Timeout, URLRequired,
|
||||
TooManyRedirects, HTTPError, ConnectionError,
|
||||
FileModeWarning, ConnectTimeout, ReadTimeout
|
||||
)
|
||||
|
||||
# Set default logging handler to avoid "No handler found" warnings.
|
||||
import logging
|
||||
try: # Python 2.7+
|
||||
from logging import NullHandler
|
||||
except ImportError:
|
||||
class NullHandler(logging.Handler):
|
||||
def emit(self, record):
|
||||
pass
|
||||
|
||||
logging.getLogger(__name__).addHandler(NullHandler())
|
||||
|
||||
# FileModeWarnings go off per the default.
|
||||
warnings.simplefilter('default', FileModeWarning, append=True)
|
||||
16
requests/__version__.py
Normal file
@@ -0,0 +1,16 @@
|
||||
# .-. .-. .-. . . .-. .-. .-. .-.
|
||||
# |( |- |.| | | |- `-. | `-.
|
||||
# ' ' `-' `-`.`-' `-' `-' ' `-'
|
||||
|
||||
__title__ = 'requests'
|
||||
__description__ = 'Python HTTP for Humans.'
|
||||
__url__ = 'http://python-requests.org'
|
||||
__version__ = '2.17.2'
|
||||
__build__ = 0x021702
|
||||
__author__ = 'Kenneth Reitz'
|
||||
__author_email__ = 'me@kennethreitz.org'
|
||||
__license__ = 'Apache 2.0'
|
||||
__copyright__ = 'Copyright 2017 Kenneth Reitz'
|
||||
__cake__ = u'\u2728 \U0001f370 \u2728'
|
||||
|
||||
|
||||
@@ -1,3 +1,5 @@
|
||||
# -*- coding: utf-8 -*-
|
||||
|
||||
"""
|
||||
requests._internal_utils
|
||||
~~~~~~~~~~~~~~
|
||||
@@ -5,24 +7,11 @@ requests._internal_utils
|
||||
Provides utility functions that are consumed internally by Requests
|
||||
which depend on extremely few external helpers (such as compat)
|
||||
"""
|
||||
import re
|
||||
|
||||
from .compat import builtin_str
|
||||
|
||||
_VALID_HEADER_NAME_RE_BYTE = re.compile(rb"^[^:\s][^:\r\n]*$")
|
||||
_VALID_HEADER_NAME_RE_STR = re.compile(r"^[^:\s][^:\r\n]*$")
|
||||
_VALID_HEADER_VALUE_RE_BYTE = re.compile(rb"^\S[^\r\n]*$|^$")
|
||||
_VALID_HEADER_VALUE_RE_STR = re.compile(r"^\S[^\r\n]*$|^$")
|
||||
|
||||
_HEADER_VALIDATORS_STR = (_VALID_HEADER_NAME_RE_STR, _VALID_HEADER_VALUE_RE_STR)
|
||||
_HEADER_VALIDATORS_BYTE = (_VALID_HEADER_NAME_RE_BYTE, _VALID_HEADER_VALUE_RE_BYTE)
|
||||
HEADER_VALIDATORS = {
|
||||
bytes: _HEADER_VALIDATORS_BYTE,
|
||||
str: _HEADER_VALIDATORS_STR,
|
||||
}
|
||||
from .compat import is_py2, builtin_str, str
|
||||
|
||||
|
||||
def to_native_string(string, encoding="ascii"):
|
||||
def to_native_string(string, encoding='ascii'):
|
||||
"""Given a string object, regardless of type, returns a representation of
|
||||
that string in the native string type, encoding and decoding where
|
||||
necessary. This assumes ASCII unless told otherwise.
|
||||
@@ -30,7 +19,10 @@ def to_native_string(string, encoding="ascii"):
|
||||
if isinstance(string, builtin_str):
|
||||
out = string
|
||||
else:
|
||||
out = string.decode(encoding)
|
||||
if is_py2:
|
||||
out = string.encode(encoding)
|
||||
else:
|
||||
out = string.decode(encoding)
|
||||
|
||||
return out
|
||||
|
||||
@@ -44,7 +36,7 @@ def unicode_is_ascii(u_string):
|
||||
"""
|
||||
assert isinstance(u_string, str)
|
||||
try:
|
||||
u_string.encode("ascii")
|
||||
u_string.encode('ascii')
|
||||
return True
|
||||
except UnicodeEncodeError:
|
||||
return False
|
||||
@@ -1,3 +1,5 @@
|
||||
# -*- coding: utf-8 -*-
|
||||
|
||||
"""
|
||||
requests.adapters
|
||||
~~~~~~~~~~~~~~~~~
|
||||
@@ -7,142 +9,54 @@ and maintain connections.
|
||||
"""
|
||||
|
||||
import os.path
|
||||
import socket # noqa: F401
|
||||
import typing
|
||||
import warnings
|
||||
import socket
|
||||
|
||||
from urllib3.exceptions import ClosedPoolError, ConnectTimeoutError
|
||||
from urllib3.exceptions import HTTPError as _HTTPError
|
||||
from urllib3.exceptions import InvalidHeader as _InvalidHeader
|
||||
from urllib3.exceptions import (
|
||||
LocationValueError,
|
||||
MaxRetryError,
|
||||
NewConnectionError,
|
||||
ProtocolError,
|
||||
)
|
||||
from urllib3.exceptions import ProxyError as _ProxyError
|
||||
from urllib3.exceptions import ReadTimeoutError, ResponseError
|
||||
from urllib3.exceptions import SSLError as _SSLError
|
||||
from urllib3.poolmanager import PoolManager, proxy_from_url
|
||||
from urllib3.response import HTTPResponse
|
||||
from urllib3.util import Timeout as TimeoutSauce
|
||||
from urllib3.util import parse_url
|
||||
from urllib3.util.retry import Retry
|
||||
from urllib3.util.ssl_ import create_urllib3_context
|
||||
from urllib3.exceptions import ClosedPoolError
|
||||
from urllib3.exceptions import ConnectTimeoutError
|
||||
from urllib3.exceptions import HTTPError as _HTTPError
|
||||
from urllib3.exceptions import MaxRetryError
|
||||
from urllib3.exceptions import NewConnectionError
|
||||
from urllib3.exceptions import ProxyError as _ProxyError
|
||||
from urllib3.exceptions import ProtocolError
|
||||
from urllib3.exceptions import ReadTimeoutError
|
||||
from urllib3.exceptions import SSLError as _SSLError
|
||||
from urllib3.exceptions import ResponseError
|
||||
|
||||
from .auth import _basic_auth_str
|
||||
from .compat import basestring, urlparse
|
||||
from .cookies import extract_cookies_to_jar
|
||||
from .exceptions import (
|
||||
ConnectionError,
|
||||
ConnectTimeout,
|
||||
InvalidHeader,
|
||||
InvalidProxyURL,
|
||||
InvalidSchema,
|
||||
InvalidURL,
|
||||
ProxyError,
|
||||
ReadTimeout,
|
||||
RetryError,
|
||||
SSLError,
|
||||
)
|
||||
from .models import Response
|
||||
from .compat import urlparse, basestring
|
||||
from .utils import (DEFAULT_CA_BUNDLE_PATH, get_encoding_from_headers,
|
||||
prepend_scheme_if_needed, get_auth_from_url, urldefragauth,
|
||||
select_proxy)
|
||||
from .structures import CaseInsensitiveDict
|
||||
from .utils import (
|
||||
DEFAULT_CA_BUNDLE_PATH,
|
||||
extract_zipped_paths,
|
||||
get_auth_from_url,
|
||||
get_encoding_from_headers,
|
||||
prepend_scheme_if_needed,
|
||||
select_proxy,
|
||||
urldefragauth,
|
||||
)
|
||||
from .cookies import extract_cookies_to_jar
|
||||
from .exceptions import (ConnectionError, ConnectTimeout, ReadTimeout, SSLError,
|
||||
ProxyError, RetryError, InvalidSchema)
|
||||
from .auth import _basic_auth_str
|
||||
|
||||
try:
|
||||
from urllib3.contrib.socks import SOCKSProxyManager
|
||||
except ImportError:
|
||||
|
||||
def SOCKSProxyManager(*args, **kwargs):
|
||||
raise InvalidSchema("Missing dependencies for SOCKS support.")
|
||||
|
||||
|
||||
if typing.TYPE_CHECKING:
|
||||
from .models import PreparedRequest
|
||||
|
||||
|
||||
DEFAULT_POOLBLOCK = False
|
||||
DEFAULT_POOLSIZE = 10
|
||||
DEFAULT_RETRIES = 0
|
||||
DEFAULT_POOL_TIMEOUT = None
|
||||
|
||||
|
||||
try:
|
||||
import ssl # noqa: F401
|
||||
|
||||
_preloaded_ssl_context = create_urllib3_context()
|
||||
_preloaded_ssl_context.load_verify_locations(
|
||||
extract_zipped_paths(DEFAULT_CA_BUNDLE_PATH)
|
||||
)
|
||||
except ImportError:
|
||||
# Bypass default SSLContext creation when Python
|
||||
# interpreter isn't built with the ssl module.
|
||||
_preloaded_ssl_context = None
|
||||
|
||||
|
||||
def _urllib3_request_context(
|
||||
request: "PreparedRequest",
|
||||
verify: "bool | str | None",
|
||||
client_cert: "typing.Tuple[str, str] | str | None",
|
||||
poolmanager: "PoolManager",
|
||||
) -> "(typing.Dict[str, typing.Any], typing.Dict[str, typing.Any])":
|
||||
host_params = {}
|
||||
pool_kwargs = {}
|
||||
parsed_request_url = urlparse(request.url)
|
||||
scheme = parsed_request_url.scheme.lower()
|
||||
port = parsed_request_url.port
|
||||
|
||||
# Determine if we have and should use our default SSLContext
|
||||
# to optimize performance on standard requests.
|
||||
poolmanager_kwargs = getattr(poolmanager, "connection_pool_kw", {})
|
||||
has_poolmanager_ssl_context = poolmanager_kwargs.get("ssl_context")
|
||||
should_use_default_ssl_context = (
|
||||
_preloaded_ssl_context is not None and not has_poolmanager_ssl_context
|
||||
)
|
||||
|
||||
cert_reqs = "CERT_REQUIRED"
|
||||
if verify is False:
|
||||
cert_reqs = "CERT_NONE"
|
||||
elif verify is True and should_use_default_ssl_context:
|
||||
pool_kwargs["ssl_context"] = _preloaded_ssl_context
|
||||
elif isinstance(verify, str):
|
||||
if not os.path.isdir(verify):
|
||||
pool_kwargs["ca_certs"] = verify
|
||||
else:
|
||||
pool_kwargs["ca_cert_dir"] = verify
|
||||
pool_kwargs["cert_reqs"] = cert_reqs
|
||||
if client_cert is not None:
|
||||
if isinstance(client_cert, tuple) and len(client_cert) == 2:
|
||||
pool_kwargs["cert_file"] = client_cert[0]
|
||||
pool_kwargs["key_file"] = client_cert[1]
|
||||
else:
|
||||
# According to our docs, we allow users to specify just the client
|
||||
# cert path
|
||||
pool_kwargs["cert_file"] = client_cert
|
||||
host_params = {
|
||||
"scheme": scheme,
|
||||
"host": parsed_request_url.hostname,
|
||||
"port": port,
|
||||
}
|
||||
return host_params, pool_kwargs
|
||||
|
||||
|
||||
class BaseAdapter:
|
||||
class BaseAdapter(object):
|
||||
"""The Base Transport Adapter"""
|
||||
|
||||
def __init__(self):
|
||||
super().__init__()
|
||||
super(BaseAdapter, self).__init__()
|
||||
|
||||
def send(
|
||||
self, request, stream=False, timeout=None, verify=True, cert=None, proxies=None
|
||||
):
|
||||
def send(self, request, stream=False, timeout=None, verify=True,
|
||||
cert=None, proxies=None):
|
||||
"""Sends PreparedRequest object. Returns Response object.
|
||||
|
||||
:param request: The :class:`PreparedRequest <PreparedRequest>` being sent.
|
||||
@@ -190,22 +104,12 @@ class HTTPAdapter(BaseAdapter):
|
||||
>>> a = requests.adapters.HTTPAdapter(max_retries=3)
|
||||
>>> s.mount('http://', a)
|
||||
"""
|
||||
__attrs__ = ['max_retries', 'config', '_pool_connections', '_pool_maxsize',
|
||||
'_pool_block']
|
||||
|
||||
__attrs__ = [
|
||||
"max_retries",
|
||||
"config",
|
||||
"_pool_connections",
|
||||
"_pool_maxsize",
|
||||
"_pool_block",
|
||||
]
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
pool_connections=DEFAULT_POOLSIZE,
|
||||
pool_maxsize=DEFAULT_POOLSIZE,
|
||||
max_retries=DEFAULT_RETRIES,
|
||||
pool_block=DEFAULT_POOLBLOCK,
|
||||
):
|
||||
def __init__(self, pool_connections=DEFAULT_POOLSIZE,
|
||||
pool_maxsize=DEFAULT_POOLSIZE, max_retries=DEFAULT_RETRIES,
|
||||
pool_block=DEFAULT_POOLBLOCK):
|
||||
if max_retries == DEFAULT_RETRIES:
|
||||
self.max_retries = Retry(0, read=False)
|
||||
else:
|
||||
@@ -213,7 +117,7 @@ class HTTPAdapter(BaseAdapter):
|
||||
self.config = {}
|
||||
self.proxy_manager = {}
|
||||
|
||||
super().__init__()
|
||||
super(HTTPAdapter, self).__init__()
|
||||
|
||||
self._pool_connections = pool_connections
|
||||
self._pool_maxsize = pool_maxsize
|
||||
@@ -222,7 +126,8 @@ class HTTPAdapter(BaseAdapter):
|
||||
self.init_poolmanager(pool_connections, pool_maxsize, block=pool_block)
|
||||
|
||||
def __getstate__(self):
|
||||
return {attr: getattr(self, attr, None) for attr in self.__attrs__}
|
||||
return dict((attr, getattr(self, attr, None)) for attr in
|
||||
self.__attrs__)
|
||||
|
||||
def __setstate__(self, state):
|
||||
# Can't handle by adding 'proxy_manager' to self.__attrs__ because
|
||||
@@ -233,13 +138,10 @@ class HTTPAdapter(BaseAdapter):
|
||||
for attr, value in state.items():
|
||||
setattr(self, attr, value)
|
||||
|
||||
self.init_poolmanager(
|
||||
self._pool_connections, self._pool_maxsize, block=self._pool_block
|
||||
)
|
||||
self.init_poolmanager(self._pool_connections, self._pool_maxsize,
|
||||
block=self._pool_block)
|
||||
|
||||
def init_poolmanager(
|
||||
self, connections, maxsize, block=DEFAULT_POOLBLOCK, **pool_kwargs
|
||||
):
|
||||
def init_poolmanager(self, connections, maxsize, block=DEFAULT_POOLBLOCK, **pool_kwargs):
|
||||
"""Initializes a urllib3 PoolManager.
|
||||
|
||||
This method should not be called from user code, and is only
|
||||
@@ -256,12 +158,8 @@ class HTTPAdapter(BaseAdapter):
|
||||
self._pool_maxsize = maxsize
|
||||
self._pool_block = block
|
||||
|
||||
self.poolmanager = PoolManager(
|
||||
num_pools=connections,
|
||||
maxsize=maxsize,
|
||||
block=block,
|
||||
**pool_kwargs,
|
||||
)
|
||||
self.poolmanager = PoolManager(num_pools=connections, maxsize=maxsize,
|
||||
block=block, strict=True, **pool_kwargs)
|
||||
|
||||
def proxy_manager_for(self, proxy, **proxy_kwargs):
|
||||
"""Return urllib3 ProxyManager for the given proxy.
|
||||
@@ -277,7 +175,7 @@ class HTTPAdapter(BaseAdapter):
|
||||
"""
|
||||
if proxy in self.proxy_manager:
|
||||
manager = self.proxy_manager[proxy]
|
||||
elif proxy.lower().startswith("socks"):
|
||||
elif proxy.lower().startswith('socks'):
|
||||
username, password = get_auth_from_url(proxy)
|
||||
manager = self.proxy_manager[proxy] = SOCKSProxyManager(
|
||||
proxy,
|
||||
@@ -286,7 +184,7 @@ class HTTPAdapter(BaseAdapter):
|
||||
num_pools=self._pool_connections,
|
||||
maxsize=self._pool_maxsize,
|
||||
block=self._pool_block,
|
||||
**proxy_kwargs,
|
||||
**proxy_kwargs
|
||||
)
|
||||
else:
|
||||
proxy_headers = self.proxy_headers(proxy)
|
||||
@@ -296,8 +194,7 @@ class HTTPAdapter(BaseAdapter):
|
||||
num_pools=self._pool_connections,
|
||||
maxsize=self._pool_maxsize,
|
||||
block=self._pool_block,
|
||||
**proxy_kwargs,
|
||||
)
|
||||
**proxy_kwargs)
|
||||
|
||||
return manager
|
||||
|
||||
@@ -313,29 +210,29 @@ class HTTPAdapter(BaseAdapter):
|
||||
to a CA bundle to use
|
||||
:param cert: The SSL certificate to verify.
|
||||
"""
|
||||
if url.lower().startswith("https") and verify:
|
||||
conn.cert_reqs = "CERT_REQUIRED"
|
||||
if url.lower().startswith('https') and verify:
|
||||
|
||||
# Only load the CA certificates if 'verify' is a string indicating the CA bundle to use.
|
||||
# Otherwise, if verify is a boolean, we don't load anything since
|
||||
# the connection will be using a context with the default certificates already loaded,
|
||||
# and this avoids a call to the slow load_verify_locations()
|
||||
cert_loc = None
|
||||
|
||||
# Allow self-specified cert location.
|
||||
if verify is not True:
|
||||
# `verify` must be a str with a path then
|
||||
cert_loc = verify
|
||||
|
||||
if not os.path.exists(cert_loc):
|
||||
raise OSError(
|
||||
f"Could not find a suitable TLS CA certificate bundle, "
|
||||
f"invalid path: {cert_loc}"
|
||||
)
|
||||
if not cert_loc:
|
||||
cert_loc = DEFAULT_CA_BUNDLE_PATH
|
||||
|
||||
if not os.path.isdir(cert_loc):
|
||||
conn.ca_certs = cert_loc
|
||||
else:
|
||||
conn.ca_cert_dir = cert_loc
|
||||
if not cert_loc or not os.path.exists(cert_loc):
|
||||
raise IOError("Could not find a suitable TLS CA certificate bundle, "
|
||||
"invalid path: {0}".format(cert_loc))
|
||||
|
||||
conn.cert_reqs = 'CERT_REQUIRED'
|
||||
|
||||
if not os.path.isdir(cert_loc):
|
||||
conn.ca_certs = cert_loc
|
||||
else:
|
||||
conn.ca_cert_dir = cert_loc
|
||||
else:
|
||||
conn.cert_reqs = "CERT_NONE"
|
||||
conn.cert_reqs = 'CERT_NONE'
|
||||
conn.ca_certs = None
|
||||
conn.ca_cert_dir = None
|
||||
|
||||
@@ -347,14 +244,11 @@ class HTTPAdapter(BaseAdapter):
|
||||
conn.cert_file = cert
|
||||
conn.key_file = None
|
||||
if conn.cert_file and not os.path.exists(conn.cert_file):
|
||||
raise OSError(
|
||||
f"Could not find the TLS certificate file, "
|
||||
f"invalid path: {conn.cert_file}"
|
||||
)
|
||||
raise IOError("Could not find the TLS certificate file, "
|
||||
"invalid path: {0}".format(conn.cert_file))
|
||||
if conn.key_file and not os.path.exists(conn.key_file):
|
||||
raise OSError(
|
||||
f"Could not find the TLS key file, invalid path: {conn.key_file}"
|
||||
)
|
||||
raise IOError("Could not find the TLS key file, "
|
||||
"invalid path: {0}".format(conn.key_file))
|
||||
|
||||
def build_response(self, req, resp):
|
||||
"""Builds a :class:`Response <requests.Response>` object from a urllib3
|
||||
@@ -369,10 +263,10 @@ class HTTPAdapter(BaseAdapter):
|
||||
response = Response()
|
||||
|
||||
# Fallback to None if there's no status_code, for whatever reason.
|
||||
response.status_code = getattr(resp, "status", None)
|
||||
response.status_code = getattr(resp, 'status', None)
|
||||
|
||||
# Make headers case-insensitive.
|
||||
response.headers = CaseInsensitiveDict(getattr(resp, "headers", {}))
|
||||
response.headers = CaseInsensitiveDict(getattr(resp, 'headers', {}))
|
||||
|
||||
# Set encoding.
|
||||
response.encoding = get_encoding_from_headers(response.headers)
|
||||
@@ -380,7 +274,7 @@ class HTTPAdapter(BaseAdapter):
|
||||
response.reason = response.raw.reason
|
||||
|
||||
if isinstance(req.url, bytes):
|
||||
response.url = req.url.decode("utf-8")
|
||||
response.url = req.url.decode('utf-8')
|
||||
else:
|
||||
response.url = req.url
|
||||
|
||||
@@ -393,110 +287,8 @@ class HTTPAdapter(BaseAdapter):
|
||||
|
||||
return response
|
||||
|
||||
def build_connection_pool_key_attributes(self, request, verify, cert=None):
|
||||
"""Build the PoolKey attributes used by urllib3 to return a connection.
|
||||
|
||||
This looks at the PreparedRequest, the user-specified verify value,
|
||||
and the value of the cert parameter to determine what PoolKey values
|
||||
to use to select a connection from a given urllib3 Connection Pool.
|
||||
|
||||
The SSL related pool key arguments are not consistently set. As of
|
||||
this writing, use the following to determine what keys may be in that
|
||||
dictionary:
|
||||
|
||||
* If ``verify`` is ``True``, ``"ssl_context"`` will be set and will be the
|
||||
default Requests SSL Context
|
||||
* If ``verify`` is ``False``, ``"ssl_context"`` will not be set but
|
||||
``"cert_reqs"`` will be set
|
||||
* If ``verify`` is a string, (i.e., it is a user-specified trust bundle)
|
||||
``"ca_certs"`` will be set if the string is not a directory recognized
|
||||
by :py:func:`os.path.isdir`, otherwise ``"ca_certs_dir"`` will be
|
||||
set.
|
||||
* If ``"cert"`` is specified, ``"cert_file"`` will always be set. If
|
||||
``"cert"`` is a tuple with a second item, ``"key_file"`` will also
|
||||
be present
|
||||
|
||||
To override these settings, one may subclass this class, call this
|
||||
method and use the above logic to change parameters as desired. For
|
||||
example, if one wishes to use a custom :py:class:`ssl.SSLContext` one
|
||||
must both set ``"ssl_context"`` and based on what else they require,
|
||||
alter the other keys to ensure the desired behaviour.
|
||||
|
||||
:param request:
|
||||
The PreparedReqest being sent over the connection.
|
||||
:type request:
|
||||
:class:`~requests.models.PreparedRequest`
|
||||
:param verify:
|
||||
Either a boolean, in which case it controls whether
|
||||
we verify the server's TLS certificate, or a string, in which case it
|
||||
must be a path to a CA bundle to use.
|
||||
:param cert:
|
||||
(optional) Any user-provided SSL certificate for client
|
||||
authentication (a.k.a., mTLS). This may be a string (i.e., just
|
||||
the path to a file which holds both certificate and key) or a
|
||||
tuple of length 2 with the certificate file path and key file
|
||||
path.
|
||||
:returns:
|
||||
A tuple of two dictionaries. The first is the "host parameters"
|
||||
portion of the Pool Key including scheme, hostname, and port. The
|
||||
second is a dictionary of SSLContext related parameters.
|
||||
"""
|
||||
return _urllib3_request_context(request, verify, cert, self.poolmanager)
|
||||
|
||||
def get_connection_with_tls_context(self, request, verify, proxies=None, cert=None):
|
||||
"""Returns a urllib3 connection for the given request and TLS settings.
|
||||
This should not be called from user code, and is only exposed for use
|
||||
when subclassing the :class:`HTTPAdapter <requests.adapters.HTTPAdapter>`.
|
||||
|
||||
:param request:
|
||||
The :class:`PreparedRequest <PreparedRequest>` object to be sent
|
||||
over the connection.
|
||||
:param verify:
|
||||
Either a boolean, in which case it controls whether we verify the
|
||||
server's TLS certificate, or a string, in which case it must be a
|
||||
path to a CA bundle to use.
|
||||
:param proxies:
|
||||
(optional) The proxies dictionary to apply to the request.
|
||||
:param cert:
|
||||
(optional) Any user-provided SSL certificate to be used for client
|
||||
authentication (a.k.a., mTLS).
|
||||
:rtype:
|
||||
urllib3.ConnectionPool
|
||||
"""
|
||||
proxy = select_proxy(request.url, proxies)
|
||||
try:
|
||||
host_params, pool_kwargs = self.build_connection_pool_key_attributes(
|
||||
request,
|
||||
verify,
|
||||
cert,
|
||||
)
|
||||
except ValueError as e:
|
||||
raise InvalidURL(e, request=request)
|
||||
if proxy:
|
||||
proxy = prepend_scheme_if_needed(proxy, "http")
|
||||
proxy_url = parse_url(proxy)
|
||||
if not proxy_url.host:
|
||||
raise InvalidProxyURL(
|
||||
"Please check proxy URL. It is malformed "
|
||||
"and could be missing the host."
|
||||
)
|
||||
proxy_manager = self.proxy_manager_for(proxy)
|
||||
conn = proxy_manager.connection_from_host(
|
||||
**host_params, pool_kwargs=pool_kwargs
|
||||
)
|
||||
else:
|
||||
# Only scheme should be lower case
|
||||
conn = self.poolmanager.connection_from_host(
|
||||
**host_params, pool_kwargs=pool_kwargs
|
||||
)
|
||||
|
||||
return conn
|
||||
|
||||
def get_connection(self, url, proxies=None):
|
||||
"""DEPRECATED: Users should move to `get_connection_with_tls_context`
|
||||
for all subclasses of HTTPAdapter using Requests>=2.32.2.
|
||||
|
||||
Returns a urllib3 connection for the given URL. This should not be
|
||||
"""Returns a urllib3 connection for the given URL. This should not be
|
||||
called from user code, and is only exposed for use when subclassing the
|
||||
:class:`HTTPAdapter <requests.adapters.HTTPAdapter>`.
|
||||
|
||||
@@ -504,25 +296,10 @@ class HTTPAdapter(BaseAdapter):
|
||||
:param proxies: (optional) A Requests-style dictionary of proxies used on this request.
|
||||
:rtype: urllib3.ConnectionPool
|
||||
"""
|
||||
warnings.warn(
|
||||
(
|
||||
"`get_connection` has been deprecated in favor of "
|
||||
"`get_connection_with_tls_context`. Custom HTTPAdapter subclasses "
|
||||
"will need to migrate for Requests>=2.32.2. Please see "
|
||||
"https://github.com/psf/requests/pull/6710 for more details."
|
||||
),
|
||||
DeprecationWarning,
|
||||
)
|
||||
proxy = select_proxy(url, proxies)
|
||||
|
||||
if proxy:
|
||||
proxy = prepend_scheme_if_needed(proxy, "http")
|
||||
proxy_url = parse_url(proxy)
|
||||
if not proxy_url.host:
|
||||
raise InvalidProxyURL(
|
||||
"Please check proxy URL. It is malformed "
|
||||
"and could be missing the host."
|
||||
)
|
||||
proxy = prepend_scheme_if_needed(proxy, 'http')
|
||||
proxy_manager = self.proxy_manager_for(proxy)
|
||||
conn = proxy_manager.connection_from_url(url)
|
||||
else:
|
||||
@@ -560,16 +337,13 @@ class HTTPAdapter(BaseAdapter):
|
||||
proxy = select_proxy(request.url, proxies)
|
||||
scheme = urlparse(request.url).scheme
|
||||
|
||||
is_proxied_http_request = proxy and scheme != "https"
|
||||
is_proxied_http_request = (proxy and scheme != 'https')
|
||||
using_socks_proxy = False
|
||||
if proxy:
|
||||
proxy_scheme = urlparse(proxy).scheme.lower()
|
||||
using_socks_proxy = proxy_scheme.startswith("socks")
|
||||
using_socks_proxy = proxy_scheme.startswith('socks')
|
||||
|
||||
url = request.path_url
|
||||
if url.startswith("//"): # Don't confuse urllib3
|
||||
url = f"/{url.lstrip('/')}"
|
||||
|
||||
if is_proxied_http_request and not using_socks_proxy:
|
||||
url = urldefragauth(request.url)
|
||||
|
||||
@@ -599,20 +373,19 @@ class HTTPAdapter(BaseAdapter):
|
||||
when subclassing the
|
||||
:class:`HTTPAdapter <requests.adapters.HTTPAdapter>`.
|
||||
|
||||
:param proxy: The url of the proxy being used for this request.
|
||||
:param proxies: The url of the proxy being used for this request.
|
||||
:rtype: dict
|
||||
"""
|
||||
headers = {}
|
||||
username, password = get_auth_from_url(proxy)
|
||||
|
||||
if username:
|
||||
headers["Proxy-Authorization"] = _basic_auth_str(username, password)
|
||||
headers['Proxy-Authorization'] = _basic_auth_str(username,
|
||||
password)
|
||||
|
||||
return headers
|
||||
|
||||
def send(
|
||||
self, request, stream=False, timeout=None, verify=True, cert=None, proxies=None
|
||||
):
|
||||
def send(self, request, stream=False, timeout=None, verify=True, cert=None, proxies=None):
|
||||
"""Sends PreparedRequest object. Returns Response object.
|
||||
|
||||
:param request: The :class:`PreparedRequest <PreparedRequest>` being sent.
|
||||
@@ -629,56 +402,91 @@ class HTTPAdapter(BaseAdapter):
|
||||
:rtype: requests.Response
|
||||
"""
|
||||
|
||||
try:
|
||||
conn = self.get_connection_with_tls_context(
|
||||
request, verify, proxies=proxies, cert=cert
|
||||
)
|
||||
except LocationValueError as e:
|
||||
raise InvalidURL(e, request=request)
|
||||
conn = self.get_connection(request.url, proxies)
|
||||
|
||||
self.cert_verify(conn, request.url, verify, cert)
|
||||
url = self.request_url(request, proxies)
|
||||
self.add_headers(
|
||||
request,
|
||||
stream=stream,
|
||||
timeout=timeout,
|
||||
verify=verify,
|
||||
cert=cert,
|
||||
proxies=proxies,
|
||||
)
|
||||
self.add_headers(request)
|
||||
|
||||
chunked = not (request.body is None or "Content-Length" in request.headers)
|
||||
chunked = not (request.body is None or 'Content-Length' in request.headers)
|
||||
|
||||
if isinstance(timeout, tuple):
|
||||
try:
|
||||
connect, read = timeout
|
||||
timeout = TimeoutSauce(connect=connect, read=read)
|
||||
except ValueError:
|
||||
raise ValueError(
|
||||
f"Invalid timeout {timeout}. Pass a (connect, read) timeout tuple, "
|
||||
f"or a single float to set both timeouts to the same value."
|
||||
)
|
||||
except ValueError as e:
|
||||
# this may raise a string formatting error.
|
||||
err = ("Invalid timeout {0}. Pass a (connect, read) "
|
||||
"timeout tuple, or a single float to set "
|
||||
"both timeouts to the same value".format(timeout))
|
||||
raise ValueError(err)
|
||||
elif isinstance(timeout, TimeoutSauce):
|
||||
pass
|
||||
else:
|
||||
timeout = TimeoutSauce(connect=timeout, read=timeout)
|
||||
|
||||
try:
|
||||
resp = conn.urlopen(
|
||||
method=request.method,
|
||||
url=url,
|
||||
body=request.body,
|
||||
headers=request.headers,
|
||||
redirect=False,
|
||||
assert_same_host=False,
|
||||
preload_content=False,
|
||||
decode_content=False,
|
||||
retries=self.max_retries,
|
||||
timeout=timeout,
|
||||
chunked=chunked,
|
||||
)
|
||||
if not chunked:
|
||||
resp = conn.urlopen(
|
||||
method=request.method,
|
||||
url=url,
|
||||
body=request.body,
|
||||
headers=request.headers,
|
||||
redirect=False,
|
||||
assert_same_host=False,
|
||||
preload_content=False,
|
||||
decode_content=False,
|
||||
retries=self.max_retries,
|
||||
timeout=timeout
|
||||
)
|
||||
|
||||
except (ProtocolError, OSError) as err:
|
||||
# Send the request.
|
||||
else:
|
||||
if hasattr(conn, 'proxy_pool'):
|
||||
conn = conn.proxy_pool
|
||||
|
||||
low_conn = conn._get_conn(timeout=DEFAULT_POOL_TIMEOUT)
|
||||
|
||||
try:
|
||||
low_conn.putrequest(request.method,
|
||||
url,
|
||||
skip_accept_encoding=True)
|
||||
|
||||
for header, value in request.headers.items():
|
||||
low_conn.putheader(header, value)
|
||||
|
||||
low_conn.endheaders()
|
||||
|
||||
for i in request.body:
|
||||
low_conn.send(hex(len(i))[2:].encode('utf-8'))
|
||||
low_conn.send(b'\r\n')
|
||||
low_conn.send(i)
|
||||
low_conn.send(b'\r\n')
|
||||
low_conn.send(b'0\r\n\r\n')
|
||||
|
||||
# Receive the response from the server
|
||||
try:
|
||||
# For Python 2.7+ versions, use buffering of HTTP
|
||||
# responses
|
||||
r = low_conn.getresponse(buffering=True)
|
||||
except TypeError:
|
||||
# For compatibility with Python 2.6 versions and back
|
||||
r = low_conn.getresponse()
|
||||
|
||||
resp = HTTPResponse.from_httplib(
|
||||
r,
|
||||
pool=conn,
|
||||
connection=low_conn,
|
||||
preload_content=False,
|
||||
decode_content=False
|
||||
)
|
||||
except:
|
||||
# If we hit any problems here, clean up the connection.
|
||||
# Then, reraise so that we can handle the actual exception.
|
||||
low_conn.close()
|
||||
raise
|
||||
|
||||
except (ProtocolError, socket.error) as err:
|
||||
raise ConnectionError(err, request=request)
|
||||
|
||||
except MaxRetryError as e:
|
||||
@@ -693,10 +501,6 @@ class HTTPAdapter(BaseAdapter):
|
||||
if isinstance(e.reason, _ProxyError):
|
||||
raise ProxyError(e, request=request)
|
||||
|
||||
if isinstance(e.reason, _SSLError):
|
||||
# This branch is for urllib3 v1.22 and later.
|
||||
raise SSLError(e, request=request)
|
||||
|
||||
raise ConnectionError(e, request=request)
|
||||
|
||||
except ClosedPoolError as e:
|
||||
@@ -707,12 +511,9 @@ class HTTPAdapter(BaseAdapter):
|
||||
|
||||
except (_SSLError, _HTTPError) as e:
|
||||
if isinstance(e, _SSLError):
|
||||
# This branch is for urllib3 versions earlier than v1.22
|
||||
raise SSLError(e, request=request)
|
||||
elif isinstance(e, ReadTimeoutError):
|
||||
raise ReadTimeout(e, request=request)
|
||||
elif isinstance(e, _InvalidHeader):
|
||||
raise InvalidHeader(e, request=request)
|
||||
else:
|
||||
raise
|
||||
|
||||
@@ -1,3 +1,5 @@
|
||||
# -*- coding: utf-8 -*-
|
||||
|
||||
"""
|
||||
requests.api
|
||||
~~~~~~~~~~~~
|
||||
@@ -14,18 +16,16 @@ from . import sessions
|
||||
def request(method, url, **kwargs):
|
||||
"""Constructs and sends a :class:`Request <Request>`.
|
||||
|
||||
:param method: method for the new :class:`Request` object: ``GET``, ``OPTIONS``, ``HEAD``, ``POST``, ``PUT``, ``PATCH``, or ``DELETE``.
|
||||
:param method: method for the new :class:`Request` object.
|
||||
:param url: URL for the new :class:`Request` object.
|
||||
:param params: (optional) Dictionary, list of tuples or bytes to send
|
||||
in the query string for the :class:`Request`.
|
||||
:param data: (optional) Dictionary, list of tuples, bytes, or file-like
|
||||
object to send in the body of the :class:`Request`.
|
||||
:param json: (optional) A JSON serializable Python object to send in the body of the :class:`Request`.
|
||||
:param params: (optional) Dictionary or bytes to be sent in the query string for the :class:`Request`.
|
||||
:param data: (optional) Dictionary or list of tuples ``[(key, value)]`` (will be form-encoded), bytes, or file-like object to send in the body of the :class:`Request`.
|
||||
:param json: (optional) json data to send in the body of the :class:`Request`.
|
||||
:param headers: (optional) Dictionary of HTTP Headers to send with the :class:`Request`.
|
||||
:param cookies: (optional) Dict or CookieJar object to send with the :class:`Request`.
|
||||
:param files: (optional) Dictionary of ``'name': file-like-objects`` (or ``{'name': file-tuple}``) for multipart encoding upload.
|
||||
``file-tuple`` can be a 2-tuple ``('filename', fileobj)``, 3-tuple ``('filename', fileobj, 'content_type')``
|
||||
or a 4-tuple ``('filename', fileobj, 'content_type', custom_headers)``, where ``'content_type'`` is a string
|
||||
or a 4-tuple ``('filename', fileobj, 'content_type', custom_headers)``, where ``'content-type'`` is a string
|
||||
defining the content type of the given file and ``custom_headers`` a dict-like object containing additional headers
|
||||
to add for the file.
|
||||
:param auth: (optional) Auth tuple to enable Basic/Digest/Custom HTTP Auth.
|
||||
@@ -47,8 +47,7 @@ def request(method, url, **kwargs):
|
||||
Usage::
|
||||
|
||||
>>> import requests
|
||||
>>> req = requests.request('GET', 'https://httpbin.org/get')
|
||||
>>> req
|
||||
>>> req = requests.request('GET', 'http://httpbin.org/get')
|
||||
<Response [200]>
|
||||
"""
|
||||
|
||||
@@ -63,18 +62,18 @@ def get(url, params=None, **kwargs):
|
||||
r"""Sends a GET request.
|
||||
|
||||
:param url: URL for the new :class:`Request` object.
|
||||
:param params: (optional) Dictionary, list of tuples or bytes to send
|
||||
in the query string for the :class:`Request`.
|
||||
:param params: (optional) Dictionary or bytes to be sent in the query string for the :class:`Request`.
|
||||
:param \*\*kwargs: Optional arguments that ``request`` takes.
|
||||
:return: :class:`Response <Response>` object
|
||||
:rtype: requests.Response
|
||||
"""
|
||||
|
||||
return request("get", url, params=params, **kwargs)
|
||||
kwargs.setdefault('allow_redirects', True)
|
||||
return request('get', url, params=params, **kwargs)
|
||||
|
||||
|
||||
def options(url, **kwargs):
|
||||
r"""Sends an OPTIONS request.
|
||||
r"""Sends a OPTIONS request.
|
||||
|
||||
:param url: URL for the new :class:`Request` object.
|
||||
:param \*\*kwargs: Optional arguments that ``request`` takes.
|
||||
@@ -82,67 +81,63 @@ def options(url, **kwargs):
|
||||
:rtype: requests.Response
|
||||
"""
|
||||
|
||||
return request("options", url, **kwargs)
|
||||
kwargs.setdefault('allow_redirects', True)
|
||||
return request('options', url, **kwargs)
|
||||
|
||||
|
||||
def head(url, **kwargs):
|
||||
r"""Sends a HEAD request.
|
||||
|
||||
:param url: URL for the new :class:`Request` object.
|
||||
:param \*\*kwargs: Optional arguments that ``request`` takes. If
|
||||
`allow_redirects` is not provided, it will be set to `False` (as
|
||||
opposed to the default :meth:`request` behavior).
|
||||
:param \*\*kwargs: Optional arguments that ``request`` takes.
|
||||
:return: :class:`Response <Response>` object
|
||||
:rtype: requests.Response
|
||||
"""
|
||||
|
||||
kwargs.setdefault("allow_redirects", False)
|
||||
return request("head", url, **kwargs)
|
||||
kwargs.setdefault('allow_redirects', False)
|
||||
return request('head', url, **kwargs)
|
||||
|
||||
|
||||
def post(url, data=None, json=None, **kwargs):
|
||||
r"""Sends a POST request.
|
||||
|
||||
:param url: URL for the new :class:`Request` object.
|
||||
:param data: (optional) Dictionary, list of tuples, bytes, or file-like
|
||||
object to send in the body of the :class:`Request`.
|
||||
:param json: (optional) A JSON serializable Python object to send in the body of the :class:`Request`.
|
||||
:param data: (optional) Dictionary (will be form-encoded), bytes, or file-like object to send in the body of the :class:`Request`.
|
||||
:param json: (optional) json data to send in the body of the :class:`Request`.
|
||||
:param \*\*kwargs: Optional arguments that ``request`` takes.
|
||||
:return: :class:`Response <Response>` object
|
||||
:rtype: requests.Response
|
||||
"""
|
||||
|
||||
return request("post", url, data=data, json=json, **kwargs)
|
||||
return request('post', url, data=data, json=json, **kwargs)
|
||||
|
||||
|
||||
def put(url, data=None, **kwargs):
|
||||
r"""Sends a PUT request.
|
||||
|
||||
:param url: URL for the new :class:`Request` object.
|
||||
:param data: (optional) Dictionary, list of tuples, bytes, or file-like
|
||||
object to send in the body of the :class:`Request`.
|
||||
:param json: (optional) A JSON serializable Python object to send in the body of the :class:`Request`.
|
||||
:param data: (optional) Dictionary (will be form-encoded), bytes, or file-like object to send in the body of the :class:`Request`.
|
||||
:param json: (optional) json data to send in the body of the :class:`Request`.
|
||||
:param \*\*kwargs: Optional arguments that ``request`` takes.
|
||||
:return: :class:`Response <Response>` object
|
||||
:rtype: requests.Response
|
||||
"""
|
||||
|
||||
return request("put", url, data=data, **kwargs)
|
||||
return request('put', url, data=data, **kwargs)
|
||||
|
||||
|
||||
def patch(url, data=None, **kwargs):
|
||||
r"""Sends a PATCH request.
|
||||
|
||||
:param url: URL for the new :class:`Request` object.
|
||||
:param data: (optional) Dictionary, list of tuples, bytes, or file-like
|
||||
object to send in the body of the :class:`Request`.
|
||||
:param json: (optional) A JSON serializable Python object to send in the body of the :class:`Request`.
|
||||
:param data: (optional) Dictionary (will be form-encoded), bytes, or file-like object to send in the body of the :class:`Request`.
|
||||
:param json: (optional) json data to send in the body of the :class:`Request`.
|
||||
:param \*\*kwargs: Optional arguments that ``request`` takes.
|
||||
:return: :class:`Response <Response>` object
|
||||
:rtype: requests.Response
|
||||
"""
|
||||
|
||||
return request("patch", url, data=data, **kwargs)
|
||||
return request('patch', url, data=data, **kwargs)
|
||||
|
||||
|
||||
def delete(url, **kwargs):
|
||||
@@ -154,4 +149,4 @@ def delete(url, **kwargs):
|
||||
:rtype: requests.Response
|
||||
"""
|
||||
|
||||
return request("delete", url, **kwargs)
|
||||
return request('delete', url, **kwargs)
|
||||
@@ -1,3 +1,5 @@
|
||||
# -*- coding: utf-8 -*-
|
||||
|
||||
"""
|
||||
requests.auth
|
||||
~~~~~~~~~~~~~
|
||||
@@ -5,21 +7,22 @@ requests.auth
|
||||
This module contains the authentication handlers for Requests.
|
||||
"""
|
||||
|
||||
import hashlib
|
||||
import os
|
||||
import re
|
||||
import threading
|
||||
import time
|
||||
import hashlib
|
||||
import threading
|
||||
import warnings
|
||||
|
||||
from base64 import b64encode
|
||||
|
||||
from ._internal_utils import to_native_string
|
||||
from .compat import basestring, str, urlparse
|
||||
from .compat import urlparse, str, basestring
|
||||
from .cookies import extract_cookies_to_jar
|
||||
from ._internal_utils import to_native_string
|
||||
from .utils import parse_dict_header
|
||||
|
||||
CONTENT_TYPE_FORM_URLENCODED = "application/x-www-form-urlencoded"
|
||||
CONTENT_TYPE_MULTI_PART = "multipart/form-data"
|
||||
CONTENT_TYPE_FORM_URLENCODED = 'application/x-www-form-urlencoded'
|
||||
CONTENT_TYPE_MULTI_PART = 'multipart/form-data'
|
||||
|
||||
|
||||
def _basic_auth_str(username, password):
|
||||
@@ -35,7 +38,7 @@ def _basic_auth_str(username, password):
|
||||
if not isinstance(username, basestring):
|
||||
warnings.warn(
|
||||
"Non-string usernames will no longer be supported in Requests "
|
||||
"3.0.0. Please convert the object you've passed in ({!r}) to "
|
||||
"3.0.0. Please convert the object you've passed in ({0!r}) to "
|
||||
"a string or bytes object in the near future to avoid "
|
||||
"problems.".format(username),
|
||||
category=DeprecationWarning,
|
||||
@@ -45,32 +48,32 @@ def _basic_auth_str(username, password):
|
||||
if not isinstance(password, basestring):
|
||||
warnings.warn(
|
||||
"Non-string passwords will no longer be supported in Requests "
|
||||
"3.0.0. Please convert the object you've passed in ({!r}) to "
|
||||
"3.0.0. Please convert the object you've passed in ({0!r}) to "
|
||||
"a string or bytes object in the near future to avoid "
|
||||
"problems.".format(type(password)),
|
||||
"problems.".format(password),
|
||||
category=DeprecationWarning,
|
||||
)
|
||||
password = str(password)
|
||||
# -- End Removal --
|
||||
|
||||
if isinstance(username, str):
|
||||
username = username.encode("latin1")
|
||||
username = username.encode('latin1')
|
||||
|
||||
if isinstance(password, str):
|
||||
password = password.encode("latin1")
|
||||
password = password.encode('latin1')
|
||||
|
||||
authstr = "Basic " + to_native_string(
|
||||
b64encode(b":".join((username, password))).strip()
|
||||
authstr = 'Basic ' + to_native_string(
|
||||
b64encode(b':'.join((username, password))).strip()
|
||||
)
|
||||
|
||||
return authstr
|
||||
|
||||
|
||||
class AuthBase:
|
||||
class AuthBase(object):
|
||||
"""Base class that all auth implementations derive from"""
|
||||
|
||||
def __call__(self, r):
|
||||
raise NotImplementedError("Auth hooks must be callable.")
|
||||
raise NotImplementedError('Auth hooks must be callable.')
|
||||
|
||||
|
||||
class HTTPBasicAuth(AuthBase):
|
||||
@@ -81,18 +84,16 @@ class HTTPBasicAuth(AuthBase):
|
||||
self.password = password
|
||||
|
||||
def __eq__(self, other):
|
||||
return all(
|
||||
[
|
||||
self.username == getattr(other, "username", None),
|
||||
self.password == getattr(other, "password", None),
|
||||
]
|
||||
)
|
||||
return all([
|
||||
self.username == getattr(other, 'username', None),
|
||||
self.password == getattr(other, 'password', None)
|
||||
])
|
||||
|
||||
def __ne__(self, other):
|
||||
return not self == other
|
||||
|
||||
def __call__(self, r):
|
||||
r.headers["Authorization"] = _basic_auth_str(self.username, self.password)
|
||||
r.headers['Authorization'] = _basic_auth_str(self.username, self.password)
|
||||
return r
|
||||
|
||||
|
||||
@@ -100,7 +101,7 @@ class HTTPProxyAuth(HTTPBasicAuth):
|
||||
"""Attaches HTTP Proxy Authentication to a given Request object."""
|
||||
|
||||
def __call__(self, r):
|
||||
r.headers["Proxy-Authorization"] = _basic_auth_str(self.username, self.password)
|
||||
r.headers['Proxy-Authorization'] = _basic_auth_str(self.username, self.password)
|
||||
return r
|
||||
|
||||
|
||||
@@ -115,9 +116,9 @@ class HTTPDigestAuth(AuthBase):
|
||||
|
||||
def init_per_thread_state(self):
|
||||
# Ensure state is initialized just once per-thread
|
||||
if not hasattr(self._thread_local, "init"):
|
||||
if not hasattr(self._thread_local, 'init'):
|
||||
self._thread_local.init = True
|
||||
self._thread_local.last_nonce = ""
|
||||
self._thread_local.last_nonce = ''
|
||||
self._thread_local.nonce_count = 0
|
||||
self._thread_local.chal = {}
|
||||
self._thread_local.pos = None
|
||||
@@ -128,52 +129,32 @@ class HTTPDigestAuth(AuthBase):
|
||||
:rtype: str
|
||||
"""
|
||||
|
||||
realm = self._thread_local.chal["realm"]
|
||||
nonce = self._thread_local.chal["nonce"]
|
||||
qop = self._thread_local.chal.get("qop")
|
||||
algorithm = self._thread_local.chal.get("algorithm")
|
||||
opaque = self._thread_local.chal.get("opaque")
|
||||
realm = self._thread_local.chal['realm']
|
||||
nonce = self._thread_local.chal['nonce']
|
||||
qop = self._thread_local.chal.get('qop')
|
||||
algorithm = self._thread_local.chal.get('algorithm')
|
||||
opaque = self._thread_local.chal.get('opaque')
|
||||
hash_utf8 = None
|
||||
|
||||
if algorithm is None:
|
||||
_algorithm = "MD5"
|
||||
_algorithm = 'MD5'
|
||||
else:
|
||||
_algorithm = algorithm.upper()
|
||||
# lambdas assume digest modules are imported at the top level
|
||||
if _algorithm == "MD5" or _algorithm == "MD5-SESS":
|
||||
|
||||
if _algorithm == 'MD5' or _algorithm == 'MD5-SESS':
|
||||
def md5_utf8(x):
|
||||
if isinstance(x, str):
|
||||
x = x.encode("utf-8")
|
||||
x = x.encode('utf-8')
|
||||
return hashlib.md5(x).hexdigest()
|
||||
|
||||
hash_utf8 = md5_utf8
|
||||
elif _algorithm == "SHA":
|
||||
|
||||
elif _algorithm == 'SHA':
|
||||
def sha_utf8(x):
|
||||
if isinstance(x, str):
|
||||
x = x.encode("utf-8")
|
||||
x = x.encode('utf-8')
|
||||
return hashlib.sha1(x).hexdigest()
|
||||
|
||||
hash_utf8 = sha_utf8
|
||||
elif _algorithm == "SHA-256":
|
||||
|
||||
def sha256_utf8(x):
|
||||
if isinstance(x, str):
|
||||
x = x.encode("utf-8")
|
||||
return hashlib.sha256(x).hexdigest()
|
||||
|
||||
hash_utf8 = sha256_utf8
|
||||
elif _algorithm == "SHA-512":
|
||||
|
||||
def sha512_utf8(x):
|
||||
if isinstance(x, str):
|
||||
x = x.encode("utf-8")
|
||||
return hashlib.sha512(x).hexdigest()
|
||||
|
||||
hash_utf8 = sha512_utf8
|
||||
|
||||
KD = lambda s, d: hash_utf8(f"{s}:{d}") # noqa:E731
|
||||
KD = lambda s, d: hash_utf8("%s:%s" % (s, d))
|
||||
|
||||
if hash_utf8 is None:
|
||||
return None
|
||||
@@ -184,10 +165,10 @@ class HTTPDigestAuth(AuthBase):
|
||||
#: path is request-uri defined in RFC 2616 which should not be empty
|
||||
path = p_parsed.path or "/"
|
||||
if p_parsed.query:
|
||||
path += f"?{p_parsed.query}"
|
||||
path += '?' + p_parsed.query
|
||||
|
||||
A1 = f"{self.username}:{realm}:{self.password}"
|
||||
A2 = f"{method}:{path}"
|
||||
A1 = '%s:%s:%s' % (self.username, realm, self.password)
|
||||
A2 = '%s:%s' % (method, path)
|
||||
|
||||
HA1 = hash_utf8(A1)
|
||||
HA2 = hash_utf8(A2)
|
||||
@@ -196,20 +177,22 @@ class HTTPDigestAuth(AuthBase):
|
||||
self._thread_local.nonce_count += 1
|
||||
else:
|
||||
self._thread_local.nonce_count = 1
|
||||
ncvalue = f"{self._thread_local.nonce_count:08x}"
|
||||
s = str(self._thread_local.nonce_count).encode("utf-8")
|
||||
s += nonce.encode("utf-8")
|
||||
s += time.ctime().encode("utf-8")
|
||||
ncvalue = '%08x' % self._thread_local.nonce_count
|
||||
s = str(self._thread_local.nonce_count).encode('utf-8')
|
||||
s += nonce.encode('utf-8')
|
||||
s += time.ctime().encode('utf-8')
|
||||
s += os.urandom(8)
|
||||
|
||||
cnonce = hashlib.sha1(s).hexdigest()[:16]
|
||||
if _algorithm == "MD5-SESS":
|
||||
HA1 = hash_utf8(f"{HA1}:{nonce}:{cnonce}")
|
||||
cnonce = (hashlib.sha1(s).hexdigest()[:16])
|
||||
if _algorithm == 'MD5-SESS':
|
||||
HA1 = hash_utf8('%s:%s:%s' % (HA1, nonce, cnonce))
|
||||
|
||||
if not qop:
|
||||
respdig = KD(HA1, f"{nonce}:{HA2}")
|
||||
elif qop == "auth" or "auth" in qop.split(","):
|
||||
noncebit = f"{nonce}:{ncvalue}:{cnonce}:auth:{HA2}"
|
||||
respdig = KD(HA1, "%s:%s" % (nonce, HA2))
|
||||
elif qop == 'auth' or 'auth' in qop.split(','):
|
||||
noncebit = "%s:%s:%s:%s:%s" % (
|
||||
nonce, ncvalue, cnonce, 'auth', HA2
|
||||
)
|
||||
respdig = KD(HA1, noncebit)
|
||||
else:
|
||||
# XXX handle auth-int.
|
||||
@@ -218,20 +201,18 @@ class HTTPDigestAuth(AuthBase):
|
||||
self._thread_local.last_nonce = nonce
|
||||
|
||||
# XXX should the partial digests be encoded too?
|
||||
base = (
|
||||
f'username="{self.username}", realm="{realm}", nonce="{nonce}", '
|
||||
f'uri="{path}", response="{respdig}"'
|
||||
)
|
||||
base = 'username="%s", realm="%s", nonce="%s", uri="%s", ' \
|
||||
'response="%s"' % (self.username, realm, nonce, path, respdig)
|
||||
if opaque:
|
||||
base += f', opaque="{opaque}"'
|
||||
base += ', opaque="%s"' % opaque
|
||||
if algorithm:
|
||||
base += f', algorithm="{algorithm}"'
|
||||
base += ', algorithm="%s"' % algorithm
|
||||
if entdig:
|
||||
base += f', digest="{entdig}"'
|
||||
base += ', digest="%s"' % entdig
|
||||
if qop:
|
||||
base += f', qop="auth", nc={ncvalue}, cnonce="{cnonce}"'
|
||||
base += ', qop="auth", nc=%s, cnonce="%s"' % (ncvalue, cnonce)
|
||||
|
||||
return f"Digest {base}"
|
||||
return 'Digest %s' % (base)
|
||||
|
||||
def handle_redirect(self, r, **kwargs):
|
||||
"""Reset num_401_calls counter on redirects."""
|
||||
@@ -246,7 +227,7 @@ class HTTPDigestAuth(AuthBase):
|
||||
"""
|
||||
|
||||
# If response is not 4xx, do not auth
|
||||
# See https://github.com/psf/requests/issues/3772
|
||||
# See https://github.com/requests/requests/issues/3772
|
||||
if not 400 <= r.status_code < 500:
|
||||
self._thread_local.num_401_calls = 1
|
||||
return r
|
||||
@@ -255,12 +236,13 @@ class HTTPDigestAuth(AuthBase):
|
||||
# Rewind the file position indicator of the body to where
|
||||
# it was to resend the request.
|
||||
r.request.body.seek(self._thread_local.pos)
|
||||
s_auth = r.headers.get("www-authenticate", "")
|
||||
s_auth = r.headers.get('www-authenticate', '')
|
||||
|
||||
if 'digest' in s_auth.lower() and self._thread_local.num_401_calls < 2:
|
||||
|
||||
if "digest" in s_auth.lower() and self._thread_local.num_401_calls < 2:
|
||||
self._thread_local.num_401_calls += 1
|
||||
pat = re.compile(r"digest ", flags=re.IGNORECASE)
|
||||
self._thread_local.chal = parse_dict_header(pat.sub("", s_auth, count=1))
|
||||
pat = re.compile(r'digest ', flags=re.IGNORECASE)
|
||||
self._thread_local.chal = parse_dict_header(pat.sub('', s_auth, count=1))
|
||||
|
||||
# Consume content and release the original connection
|
||||
# to allow our new request to reuse the same one.
|
||||
@@ -270,9 +252,8 @@ class HTTPDigestAuth(AuthBase):
|
||||
extract_cookies_to_jar(prep._cookies, r.request, r.raw)
|
||||
prep.prepare_cookies(prep._cookies)
|
||||
|
||||
prep.headers["Authorization"] = self.build_digest_header(
|
||||
prep.method, prep.url
|
||||
)
|
||||
prep.headers['Authorization'] = self.build_digest_header(
|
||||
prep.method, prep.url)
|
||||
_r = r.connection.send(prep, **kwargs)
|
||||
_r.history.append(r)
|
||||
_r.request = prep
|
||||
@@ -287,7 +268,7 @@ class HTTPDigestAuth(AuthBase):
|
||||
self.init_per_thread_state()
|
||||
# If we have a saved nonce, skip the 401
|
||||
if self._thread_local.last_nonce:
|
||||
r.headers["Authorization"] = self.build_digest_header(r.method, r.url)
|
||||
r.headers['Authorization'] = self.build_digest_header(r.method, r.url)
|
||||
try:
|
||||
self._thread_local.pos = r.body.tell()
|
||||
except AttributeError:
|
||||
@@ -296,19 +277,17 @@ class HTTPDigestAuth(AuthBase):
|
||||
# file position of the previous body. Ensure it's set to
|
||||
# None.
|
||||
self._thread_local.pos = None
|
||||
r.register_hook("response", self.handle_401)
|
||||
r.register_hook("response", self.handle_redirect)
|
||||
r.register_hook('response', self.handle_401)
|
||||
r.register_hook('response', self.handle_redirect)
|
||||
self._thread_local.num_401_calls = 1
|
||||
|
||||
return r
|
||||
|
||||
def __eq__(self, other):
|
||||
return all(
|
||||
[
|
||||
self.username == getattr(other, "username", None),
|
||||
self.password == getattr(other, "password", None),
|
||||
]
|
||||
)
|
||||
return all([
|
||||
self.username == getattr(other, 'username', None),
|
||||
self.password == getattr(other, 'password', None)
|
||||
])
|
||||
|
||||
def __ne__(self, other):
|
||||
return not self == other
|
||||
@@ -1,4 +1,5 @@
|
||||
#!/usr/bin/env python
|
||||
# -*- coding: utf-8 -*-
|
||||
|
||||
"""
|
||||
requests.certs
|
||||
@@ -13,5 +14,5 @@ packaged CA bundle.
|
||||
"""
|
||||
from certifi import where
|
||||
|
||||
if __name__ == "__main__":
|
||||
if __name__ == '__main__':
|
||||
print(where())
|
||||
71
requests/compat.py
Normal file
@@ -0,0 +1,71 @@
|
||||
# -*- coding: utf-8 -*-
|
||||
|
||||
"""
|
||||
requests.compat
|
||||
~~~~~~~~~~~~~~~
|
||||
|
||||
This module handles import compatibility issues between Python 2 and
|
||||
Python 3.
|
||||
"""
|
||||
|
||||
import chardet
|
||||
|
||||
import sys
|
||||
|
||||
# -------
|
||||
# Pythons
|
||||
# -------
|
||||
|
||||
# Syntax sugar.
|
||||
_ver = sys.version_info
|
||||
|
||||
#: Python 2.x?
|
||||
is_py2 = (_ver[0] == 2)
|
||||
|
||||
#: Python 3.x?
|
||||
is_py3 = (_ver[0] == 3)
|
||||
|
||||
try:
|
||||
import simplejson as json
|
||||
except (ImportError, SyntaxError):
|
||||
# simplejson does not support Python 3.2, it throws a SyntaxError
|
||||
# because of u'...' Unicode literals.
|
||||
import json
|
||||
|
||||
# ---------
|
||||
# Specifics
|
||||
# ---------
|
||||
|
||||
if is_py2:
|
||||
from urllib import (
|
||||
quote, unquote, quote_plus, unquote_plus, urlencode, getproxies,
|
||||
proxy_bypass, proxy_bypass_environment, getproxies_environment)
|
||||
from urlparse import urlparse, urlunparse, urljoin, urlsplit, urldefrag
|
||||
from urllib2 import parse_http_list
|
||||
import cookielib
|
||||
from Cookie import Morsel
|
||||
from StringIO import StringIO
|
||||
|
||||
from urllib3.packages.ordered_dict import OrderedDict
|
||||
|
||||
builtin_str = str
|
||||
bytes = str
|
||||
str = unicode
|
||||
basestring = basestring
|
||||
numeric_types = (int, long, float)
|
||||
integer_types = (int, long)
|
||||
|
||||
elif is_py3:
|
||||
from urllib.parse import urlparse, urlunparse, urljoin, urlsplit, urlencode, quote, unquote, quote_plus, unquote_plus, urldefrag
|
||||
from urllib.request import parse_http_list, getproxies, proxy_bypass, proxy_bypass_environment, getproxies_environment
|
||||
from http import cookiejar as cookielib
|
||||
from http.cookies import Morsel
|
||||
from io import StringIO
|
||||
from collections import OrderedDict
|
||||
|
||||
builtin_str = str
|
||||
str = str
|
||||
bytes = bytes
|
||||
basestring = (str, bytes)
|
||||
numeric_types = (int, float)
|
||||
integer_types = (int,)
|
||||
@@ -1,18 +1,21 @@
|
||||
# -*- coding: utf-8 -*-
|
||||
|
||||
"""
|
||||
requests.cookies
|
||||
~~~~~~~~~~~~~~~~
|
||||
|
||||
Compatibility code to be able to use `http.cookiejar.CookieJar` with requests.
|
||||
Compatibility code to be able to use `cookielib.CookieJar` with requests.
|
||||
|
||||
requests.utils imports from here, so be careful with imports.
|
||||
"""
|
||||
|
||||
import calendar
|
||||
import copy
|
||||
import time
|
||||
import calendar
|
||||
import collections
|
||||
|
||||
from ._internal_utils import to_native_string
|
||||
from .compat import Morsel, MutableMapping, cookielib, urlparse, urlunparse
|
||||
from .compat import cookielib, urlparse, urlunparse, Morsel
|
||||
|
||||
try:
|
||||
import threading
|
||||
@@ -20,10 +23,10 @@ except ImportError:
|
||||
import dummy_threading as threading
|
||||
|
||||
|
||||
class MockRequest:
|
||||
class MockRequest(object):
|
||||
"""Wraps a `requests.Request` to mimic a `urllib2.Request`.
|
||||
|
||||
The code in `http.cookiejar.CookieJar` expects this interface in order to correctly
|
||||
The code in `cookielib.CookieJar` expects this interface in order to correctly
|
||||
manage cookie policies, i.e., determine whether a cookie can be set, given the
|
||||
domains of the request and the cookie.
|
||||
|
||||
@@ -49,22 +52,16 @@ class MockRequest:
|
||||
def get_full_url(self):
|
||||
# Only return the response's URL if the user hadn't set the Host
|
||||
# header
|
||||
if not self._r.headers.get("Host"):
|
||||
if not self._r.headers.get('Host'):
|
||||
return self._r.url
|
||||
# If they did set it, retrieve it and reconstruct the expected domain
|
||||
host = to_native_string(self._r.headers["Host"], encoding="utf-8")
|
||||
host = to_native_string(self._r.headers['Host'], encoding='utf-8')
|
||||
parsed = urlparse(self._r.url)
|
||||
# Reconstruct the URL as we expect it
|
||||
return urlunparse(
|
||||
[
|
||||
parsed.scheme,
|
||||
host,
|
||||
parsed.path,
|
||||
parsed.params,
|
||||
parsed.query,
|
||||
parsed.fragment,
|
||||
]
|
||||
)
|
||||
return urlunparse([
|
||||
parsed.scheme, host, parsed.path, parsed.params, parsed.query,
|
||||
parsed.fragment
|
||||
])
|
||||
|
||||
def is_unverifiable(self):
|
||||
return True
|
||||
@@ -76,10 +73,8 @@ class MockRequest:
|
||||
return self._r.headers.get(name, self._new_headers.get(name, default))
|
||||
|
||||
def add_header(self, key, val):
|
||||
"""cookiejar has no legitimate use for this method; add it back if you find one."""
|
||||
raise NotImplementedError(
|
||||
"Cookie headers should be added with add_unredirected_header()"
|
||||
)
|
||||
"""cookielib has no legitimate use for this method; add it back if you find one."""
|
||||
raise NotImplementedError("Cookie headers should be added with add_unredirected_header()")
|
||||
|
||||
def add_unredirected_header(self, name, value):
|
||||
self._new_headers[name] = value
|
||||
@@ -100,15 +95,15 @@ class MockRequest:
|
||||
return self.get_host()
|
||||
|
||||
|
||||
class MockResponse:
|
||||
class MockResponse(object):
|
||||
"""Wraps a `httplib.HTTPMessage` to mimic a `urllib.addinfourl`.
|
||||
|
||||
...what? Basically, expose the parsed HTTP headers from the server response
|
||||
the way `http.cookiejar` expects to see them.
|
||||
the way `cookielib` expects to see them.
|
||||
"""
|
||||
|
||||
def __init__(self, headers):
|
||||
"""Make a MockResponse for `cookiejar` to read.
|
||||
"""Make a MockResponse for `cookielib` to read.
|
||||
|
||||
:param headers: a httplib.HTTPMessage or analogous carrying the headers
|
||||
"""
|
||||
@@ -124,11 +119,12 @@ class MockResponse:
|
||||
def extract_cookies_to_jar(jar, request, response):
|
||||
"""Extract the cookies from the response into a CookieJar.
|
||||
|
||||
:param jar: http.cookiejar.CookieJar (not necessarily a RequestsCookieJar)
|
||||
:param jar: cookielib.CookieJar (not necessarily a RequestsCookieJar)
|
||||
:param request: our own requests.Request object
|
||||
:param response: urllib3.HTTPResponse object
|
||||
"""
|
||||
if not (hasattr(response, "_original_response") and response._original_response):
|
||||
if not (hasattr(response, '_original_response') and
|
||||
response._original_response):
|
||||
return
|
||||
# the _original_response field is the wrapped httplib.HTTPResponse object,
|
||||
req = MockRequest(request)
|
||||
@@ -145,7 +141,7 @@ def get_cookie_header(jar, request):
|
||||
"""
|
||||
r = MockRequest(request)
|
||||
jar.add_cookie_header(r)
|
||||
return r.get_new_headers().get("Cookie")
|
||||
return r.get_new_headers().get('Cookie')
|
||||
|
||||
|
||||
def remove_cookie_by_name(cookiejar, name, domain=None, path=None):
|
||||
@@ -173,8 +169,8 @@ class CookieConflictError(RuntimeError):
|
||||
"""
|
||||
|
||||
|
||||
class RequestsCookieJar(cookielib.CookieJar, MutableMapping):
|
||||
"""Compatibility class; is a http.cookiejar.CookieJar, but exposes a dict
|
||||
class RequestsCookieJar(cookielib.CookieJar, collections.MutableMapping):
|
||||
"""Compatibility class; is a cookielib.CookieJar, but exposes a dict
|
||||
interface.
|
||||
|
||||
This is the CookieJar we create by default for requests and sessions that
|
||||
@@ -210,9 +206,7 @@ class RequestsCookieJar(cookielib.CookieJar, MutableMapping):
|
||||
"""
|
||||
# support client code that unsets cookies by assignment of a None value:
|
||||
if value is None:
|
||||
remove_cookie_by_name(
|
||||
self, name, domain=kwargs.get("domain"), path=kwargs.get("path")
|
||||
)
|
||||
remove_cookie_by_name(self, name, domain=kwargs.get('domain'), path=kwargs.get('path'))
|
||||
return
|
||||
|
||||
if isinstance(value, Morsel):
|
||||
@@ -312,15 +306,14 @@ class RequestsCookieJar(cookielib.CookieJar, MutableMapping):
|
||||
"""
|
||||
dictionary = {}
|
||||
for cookie in iter(self):
|
||||
if (domain is None or cookie.domain == domain) and (
|
||||
path is None or cookie.path == path
|
||||
):
|
||||
if (domain is None or cookie.domain == domain) and (path is None
|
||||
or cookie.path == path):
|
||||
dictionary[cookie.name] = cookie.value
|
||||
return dictionary
|
||||
|
||||
def __contains__(self, name):
|
||||
try:
|
||||
return super().__contains__(name)
|
||||
return super(RequestsCookieJar, self).__contains__(name)
|
||||
except CookieConflictError:
|
||||
return True
|
||||
|
||||
@@ -341,19 +334,15 @@ class RequestsCookieJar(cookielib.CookieJar, MutableMapping):
|
||||
self.set(name, value)
|
||||
|
||||
def __delitem__(self, name):
|
||||
"""Deletes a cookie given a name. Wraps ``http.cookiejar.CookieJar``'s
|
||||
"""Deletes a cookie given a name. Wraps ``cookielib.CookieJar``'s
|
||||
``remove_cookie_by_name()``.
|
||||
"""
|
||||
remove_cookie_by_name(self, name)
|
||||
|
||||
def set_cookie(self, cookie, *args, **kwargs):
|
||||
if (
|
||||
hasattr(cookie.value, "startswith")
|
||||
and cookie.value.startswith('"')
|
||||
and cookie.value.endswith('"')
|
||||
):
|
||||
cookie.value = cookie.value.replace('\\"', "")
|
||||
return super().set_cookie(cookie, *args, **kwargs)
|
||||
if hasattr(cookie.value, 'startswith') and cookie.value.startswith('"') and cookie.value.endswith('"'):
|
||||
cookie.value = cookie.value.replace('\\"', '')
|
||||
return super(RequestsCookieJar, self).set_cookie(cookie, *args, **kwargs)
|
||||
|
||||
def update(self, other):
|
||||
"""Updates this jar with cookies from another CookieJar or dict-like"""
|
||||
@@ -361,7 +350,7 @@ class RequestsCookieJar(cookielib.CookieJar, MutableMapping):
|
||||
for cookie in other:
|
||||
self.set_cookie(copy.copy(cookie))
|
||||
else:
|
||||
super().update(other)
|
||||
super(RequestsCookieJar, self).update(other)
|
||||
|
||||
def _find(self, name, domain=None, path=None):
|
||||
"""Requests uses this method internally to get cookie values.
|
||||
@@ -381,7 +370,7 @@ class RequestsCookieJar(cookielib.CookieJar, MutableMapping):
|
||||
if path is None or cookie.path == path:
|
||||
return cookie.value
|
||||
|
||||
raise KeyError(f"name={name!r}, domain={domain!r}, path={path!r}")
|
||||
raise KeyError('name=%r, domain=%r, path=%r' % (name, domain, path))
|
||||
|
||||
def _find_no_duplicates(self, name, domain=None, path=None):
|
||||
"""Both ``__get_item__`` and ``get`` call this function: it's never
|
||||
@@ -400,48 +389,39 @@ class RequestsCookieJar(cookielib.CookieJar, MutableMapping):
|
||||
if cookie.name == name:
|
||||
if domain is None or cookie.domain == domain:
|
||||
if path is None or cookie.path == path:
|
||||
if toReturn is not None:
|
||||
# if there are multiple cookies that meet passed in criteria
|
||||
raise CookieConflictError(
|
||||
f"There are multiple cookies with name, {name!r}"
|
||||
)
|
||||
# we will eventually return this as long as no cookie conflict
|
||||
toReturn = cookie.value
|
||||
if toReturn is not None: # if there are multiple cookies that meet passed in criteria
|
||||
raise CookieConflictError('There are multiple cookies with name, %r' % (name))
|
||||
toReturn = cookie.value # we will eventually return this as long as no cookie conflict
|
||||
|
||||
if toReturn:
|
||||
return toReturn
|
||||
raise KeyError(f"name={name!r}, domain={domain!r}, path={path!r}")
|
||||
raise KeyError('name=%r, domain=%r, path=%r' % (name, domain, path))
|
||||
|
||||
def __getstate__(self):
|
||||
"""Unlike a normal CookieJar, this class is pickleable."""
|
||||
state = self.__dict__.copy()
|
||||
# remove the unpickleable RLock object
|
||||
state.pop("_cookies_lock")
|
||||
state.pop('_cookies_lock')
|
||||
return state
|
||||
|
||||
def __setstate__(self, state):
|
||||
"""Unlike a normal CookieJar, this class is pickleable."""
|
||||
self.__dict__.update(state)
|
||||
if "_cookies_lock" not in self.__dict__:
|
||||
if '_cookies_lock' not in self.__dict__:
|
||||
self._cookies_lock = threading.RLock()
|
||||
|
||||
def copy(self):
|
||||
"""Return a copy of this RequestsCookieJar."""
|
||||
new_cj = RequestsCookieJar()
|
||||
new_cj.set_policy(self.get_policy())
|
||||
new_cj.update(self)
|
||||
return new_cj
|
||||
|
||||
def get_policy(self):
|
||||
"""Return the CookiePolicy instance used."""
|
||||
return self._policy
|
||||
|
||||
|
||||
def _copy_cookie_jar(jar):
|
||||
if jar is None:
|
||||
return None
|
||||
|
||||
if hasattr(jar, "copy"):
|
||||
if hasattr(jar, 'copy'):
|
||||
# We're dealing with an instance of RequestsCookieJar
|
||||
return jar.copy()
|
||||
# We're dealing with a generic CookieJar instance
|
||||
@@ -458,33 +438,31 @@ def create_cookie(name, value, **kwargs):
|
||||
By default, the pair of `name` and `value` will be set for the domain ''
|
||||
and sent on every request (this is sometimes called a "supercookie").
|
||||
"""
|
||||
result = {
|
||||
"version": 0,
|
||||
"name": name,
|
||||
"value": value,
|
||||
"port": None,
|
||||
"domain": "",
|
||||
"path": "/",
|
||||
"secure": False,
|
||||
"expires": None,
|
||||
"discard": True,
|
||||
"comment": None,
|
||||
"comment_url": None,
|
||||
"rest": {"HttpOnly": None},
|
||||
"rfc2109": False,
|
||||
}
|
||||
result = dict(
|
||||
version=0,
|
||||
name=name,
|
||||
value=value,
|
||||
port=None,
|
||||
domain='',
|
||||
path='/',
|
||||
secure=False,
|
||||
expires=None,
|
||||
discard=True,
|
||||
comment=None,
|
||||
comment_url=None,
|
||||
rest={'HttpOnly': None},
|
||||
rfc2109=False,)
|
||||
|
||||
badargs = set(kwargs) - set(result)
|
||||
if badargs:
|
||||
raise TypeError(
|
||||
f"create_cookie() got unexpected keyword arguments: {list(badargs)}"
|
||||
)
|
||||
err = 'create_cookie() got unexpected keyword arguments: %s'
|
||||
raise TypeError(err % list(badargs))
|
||||
|
||||
result.update(kwargs)
|
||||
result["port_specified"] = bool(result["port"])
|
||||
result["domain_specified"] = bool(result["domain"])
|
||||
result["domain_initial_dot"] = result["domain"].startswith(".")
|
||||
result["path_specified"] = bool(result["path"])
|
||||
result['port_specified'] = bool(result['port'])
|
||||
result['domain_specified'] = bool(result['domain'])
|
||||
result['domain_initial_dot'] = result['domain'].startswith('.')
|
||||
result['path_specified'] = bool(result['path'])
|
||||
|
||||
return cookielib.Cookie(**result)
|
||||
|
||||
@@ -493,28 +471,30 @@ def morsel_to_cookie(morsel):
|
||||
"""Convert a Morsel object into a Cookie containing the one k/v pair."""
|
||||
|
||||
expires = None
|
||||
if morsel["max-age"]:
|
||||
if morsel['max-age']:
|
||||
try:
|
||||
expires = int(time.time() + int(morsel["max-age"]))
|
||||
expires = int(time.time() + int(morsel['max-age']))
|
||||
except ValueError:
|
||||
raise TypeError(f"max-age: {morsel['max-age']} must be integer")
|
||||
elif morsel["expires"]:
|
||||
time_template = "%a, %d-%b-%Y %H:%M:%S GMT"
|
||||
expires = calendar.timegm(time.strptime(morsel["expires"], time_template))
|
||||
raise TypeError('max-age: %s must be integer' % morsel['max-age'])
|
||||
elif morsel['expires']:
|
||||
time_template = '%a, %d-%b-%Y %H:%M:%S GMT'
|
||||
expires = calendar.timegm(
|
||||
time.strptime(morsel['expires'], time_template)
|
||||
)
|
||||
return create_cookie(
|
||||
comment=morsel["comment"],
|
||||
comment_url=bool(morsel["comment"]),
|
||||
comment=morsel['comment'],
|
||||
comment_url=bool(morsel['comment']),
|
||||
discard=False,
|
||||
domain=morsel["domain"],
|
||||
domain=morsel['domain'],
|
||||
expires=expires,
|
||||
name=morsel.key,
|
||||
path=morsel["path"],
|
||||
path=morsel['path'],
|
||||
port=None,
|
||||
rest={"HttpOnly": morsel["httponly"]},
|
||||
rest={'HttpOnly': morsel['httponly']},
|
||||
rfc2109=False,
|
||||
secure=bool(morsel["secure"]),
|
||||
secure=bool(morsel['secure']),
|
||||
value=morsel.value,
|
||||
version=morsel["version"] or 0,
|
||||
version=morsel['version'] or 0,
|
||||
)
|
||||
|
||||
|
||||
@@ -525,7 +505,6 @@ def cookiejar_from_dict(cookie_dict, cookiejar=None, overwrite=True):
|
||||
:param cookiejar: (optional) A cookiejar to add the cookies to.
|
||||
:param overwrite: (optional) If False, will not replace cookies
|
||||
already in the jar with new ones.
|
||||
:rtype: CookieJar
|
||||
"""
|
||||
if cookiejar is None:
|
||||
cookiejar = RequestsCookieJar()
|
||||
@@ -544,13 +523,13 @@ def merge_cookies(cookiejar, cookies):
|
||||
|
||||
:param cookiejar: CookieJar object to add the cookies to.
|
||||
:param cookies: Dictionary or CookieJar object to be added.
|
||||
:rtype: CookieJar
|
||||
"""
|
||||
if not isinstance(cookiejar, cookielib.CookieJar):
|
||||
raise ValueError("You can only merge into CookieJar")
|
||||
raise ValueError('You can only merge into CookieJar')
|
||||
|
||||
if isinstance(cookies, dict):
|
||||
cookiejar = cookiejar_from_dict(cookies, cookiejar=cookiejar, overwrite=False)
|
||||
cookiejar = cookiejar_from_dict(
|
||||
cookies, cookiejar=cookiejar, overwrite=False)
|
||||
elif isinstance(cookies, cookielib.CookieJar):
|
||||
try:
|
||||
cookiejar.update(cookies)
|
||||
@@ -1,3 +1,5 @@
|
||||
# -*- coding: utf-8 -*-
|
||||
|
||||
"""
|
||||
requests.exceptions
|
||||
~~~~~~~~~~~~~~~~~~~
|
||||
@@ -6,8 +8,6 @@ This module contains the set of Requests' exceptions.
|
||||
"""
|
||||
from urllib3.exceptions import HTTPError as BaseHTTPError
|
||||
|
||||
from .compat import JSONDecodeError as CompatJSONDecodeError
|
||||
|
||||
|
||||
class RequestException(IOError):
|
||||
"""There was an ambiguous exception that occurred while handling your
|
||||
@@ -16,40 +16,13 @@ class RequestException(IOError):
|
||||
|
||||
def __init__(self, *args, **kwargs):
|
||||
"""Initialize RequestException with `request` and `response` objects."""
|
||||
response = kwargs.pop("response", None)
|
||||
response = kwargs.pop('response', None)
|
||||
self.response = response
|
||||
self.request = kwargs.pop("request", None)
|
||||
if response is not None and not self.request and hasattr(response, "request"):
|
||||
self.request = kwargs.pop('request', None)
|
||||
if (response is not None and not self.request and
|
||||
hasattr(response, 'request')):
|
||||
self.request = self.response.request
|
||||
super().__init__(*args, **kwargs)
|
||||
|
||||
|
||||
class InvalidJSONError(RequestException):
|
||||
"""A JSON error occurred."""
|
||||
|
||||
|
||||
class JSONDecodeError(InvalidJSONError, CompatJSONDecodeError):
|
||||
"""Couldn't decode the text into json"""
|
||||
|
||||
def __init__(self, *args, **kwargs):
|
||||
"""
|
||||
Construct the JSONDecodeError instance first with all
|
||||
args. Then use it's args to construct the IOError so that
|
||||
the json specific args aren't used as IOError specific args
|
||||
and the error message from JSONDecodeError is preserved.
|
||||
"""
|
||||
CompatJSONDecodeError.__init__(self, *args)
|
||||
InvalidJSONError.__init__(self, *self.args, **kwargs)
|
||||
|
||||
def __reduce__(self):
|
||||
"""
|
||||
The __reduce__ method called when pickling the object must
|
||||
be the one from the JSONDecodeError (be it json/simplejson)
|
||||
as it expects all the arguments for instantiation, not just
|
||||
one like the IOError, and the MRO would by default call the
|
||||
__reduce__ method from the IOError due to the inheritance order.
|
||||
"""
|
||||
return CompatJSONDecodeError.__reduce__(self)
|
||||
super(RequestException, self).__init__(*args, **kwargs)
|
||||
|
||||
|
||||
class HTTPError(RequestException):
|
||||
@@ -97,11 +70,11 @@ class TooManyRedirects(RequestException):
|
||||
|
||||
|
||||
class MissingSchema(RequestException, ValueError):
|
||||
"""The URL scheme (e.g. http or https) is missing."""
|
||||
"""The URL schema (e.g. http or https) is missing."""
|
||||
|
||||
|
||||
class InvalidSchema(RequestException, ValueError):
|
||||
"""The URL scheme provided is either invalid or unsupported."""
|
||||
"""See defaults.py for valid schemas."""
|
||||
|
||||
|
||||
class InvalidURL(RequestException, ValueError):
|
||||
@@ -112,40 +85,32 @@ class InvalidHeader(RequestException, ValueError):
|
||||
"""The header value provided was somehow invalid."""
|
||||
|
||||
|
||||
class InvalidProxyURL(InvalidURL):
|
||||
"""The proxy URL provided is invalid."""
|
||||
|
||||
|
||||
class ChunkedEncodingError(RequestException):
|
||||
"""The server declared chunked encoding but sent an invalid chunk."""
|
||||
|
||||
|
||||
class ContentDecodingError(RequestException, BaseHTTPError):
|
||||
"""Failed to decode response content."""
|
||||
"""Failed to decode response content"""
|
||||
|
||||
|
||||
class StreamConsumedError(RequestException, TypeError):
|
||||
"""The content for this response was already consumed."""
|
||||
"""The content for this response was already consumed"""
|
||||
|
||||
|
||||
class RetryError(RequestException):
|
||||
"""Custom retries logic failed"""
|
||||
|
||||
|
||||
class UnrewindableBodyError(RequestException):
|
||||
"""Requests encountered an error when trying to rewind a body."""
|
||||
|
||||
"""Requests encountered an error when trying to rewind a body"""
|
||||
|
||||
# Warnings
|
||||
|
||||
|
||||
class RequestsWarning(Warning):
|
||||
"""Base warning for Requests."""
|
||||
pass
|
||||
|
||||
|
||||
class FileModeWarning(RequestsWarning, DeprecationWarning):
|
||||
"""A file was opened in text mode, but Requests determined its binary length."""
|
||||
|
||||
|
||||
class RequestsDependencyWarning(RequestsWarning):
|
||||
"""An imported dependency doesn't match the expected version range."""
|
||||
pass
|
||||
110
requests/help.py
Normal file
@@ -0,0 +1,110 @@
|
||||
"""Module containing bug report helper(s)."""
|
||||
from __future__ import print_function
|
||||
|
||||
import json
|
||||
import platform
|
||||
import sys
|
||||
import ssl
|
||||
|
||||
import urllib3
|
||||
import chardet
|
||||
|
||||
from . import __version__ as requests_version
|
||||
|
||||
try:
|
||||
from .packages.urllib3.contrib import pyopenssl
|
||||
except ImportError:
|
||||
pyopenssl = None
|
||||
OpenSSL = None
|
||||
cryptography = None
|
||||
else:
|
||||
import OpenSSL
|
||||
import cryptography
|
||||
|
||||
|
||||
def _implementation():
|
||||
"""Return a dict with the Python implementation and verison.
|
||||
|
||||
Provide both the name and the version of the Python implementation
|
||||
currently running. For example, on CPython 2.7.5 it will return
|
||||
{'name': 'CPython', 'version': '2.7.5'}.
|
||||
|
||||
This function works best on CPython and PyPy: in particular, it probably
|
||||
doesn't work for Jython or IronPython. Future investigation should be done
|
||||
to work out the correct shape of the code for those platforms.
|
||||
"""
|
||||
implementation = platform.python_implementation()
|
||||
|
||||
if implementation == 'CPython':
|
||||
implementation_version = platform.python_version()
|
||||
elif implementation == 'PyPy':
|
||||
implementation_version = '%s.%s.%s' % (sys.pypy_version_info.major,
|
||||
sys.pypy_version_info.minor,
|
||||
sys.pypy_version_info.micro)
|
||||
if sys.pypy_version_info.releaselevel != 'final':
|
||||
implementation_version = ''.join([
|
||||
implementation_version, sys.pypy_version_info.releaselevel
|
||||
])
|
||||
elif implementation == 'Jython':
|
||||
implementation_version = platform.python_version() # Complete Guess
|
||||
elif implementation == 'IronPython':
|
||||
implementation_version = platform.python_version() # Complete Guess
|
||||
else:
|
||||
implementation_version = 'Unknown'
|
||||
|
||||
return {'name': implementation, 'version': implementation_version}
|
||||
|
||||
|
||||
def info():
|
||||
"""Generate information for a bug report."""
|
||||
try:
|
||||
platform_info = {
|
||||
'system': platform.system(),
|
||||
'release': platform.release(),
|
||||
}
|
||||
except IOError:
|
||||
platform_info = {
|
||||
'system': 'Unknown',
|
||||
'release': 'Unknown',
|
||||
}
|
||||
|
||||
implementation_info = _implementation()
|
||||
urllib3_info = {'version': urllib3.__version__}
|
||||
chardet_info = {'version': chardet.__version__}
|
||||
|
||||
pyopenssl_info = {
|
||||
'version': None,
|
||||
'openssl_version': '',
|
||||
}
|
||||
if OpenSSL:
|
||||
pyopenssl_info = {
|
||||
'version': OpenSSL.__version__,
|
||||
'openssl_version': '%x' % OpenSSL.SSL.OPENSSL_VERSION_NUMBER,
|
||||
}
|
||||
cryptography_info = {
|
||||
'version': getattr(cryptography, '__version__', ''),
|
||||
}
|
||||
|
||||
return {
|
||||
'platform': platform_info,
|
||||
'implementation': implementation_info,
|
||||
'system_ssl': {
|
||||
'version': '%x' % ssl.OPENSSL_VERSION_NUMBER,
|
||||
},
|
||||
'using_pyopenssl': pyopenssl is not None,
|
||||
'pyOpenSSL': pyopenssl_info,
|
||||
'urllib3': urllib3_info,
|
||||
'chardet': chardet_info,
|
||||
'cryptography': cryptography_info,
|
||||
'requests': {
|
||||
'version': requests_version,
|
||||
},
|
||||
}
|
||||
|
||||
def main():
|
||||
"""Pretty-print the bug information as JSON."""
|
||||
print(json.dumps(info(), sort_keys=True, indent=2))
|
||||
|
||||
if __name__ == '__main__':
|
||||
main()
|
||||
|
||||
@@ -1,3 +1,5 @@
|
||||
# -*- coding: utf-8 -*-
|
||||
|
||||
"""
|
||||
requests.hooks
|
||||
~~~~~~~~~~~~~~
|
||||
@@ -9,22 +11,21 @@ Available hooks:
|
||||
``response``:
|
||||
The response generated from a Request.
|
||||
"""
|
||||
HOOKS = ["response"]
|
||||
HOOKS = ['response']
|
||||
|
||||
|
||||
def default_hooks():
|
||||
return {event: [] for event in HOOKS}
|
||||
|
||||
return dict((event, []) for event in HOOKS)
|
||||
|
||||
# TODO: response is the only one
|
||||
|
||||
|
||||
def dispatch_hook(key, hooks, hook_data, **kwargs):
|
||||
"""Dispatches a hook dictionary on a given piece of data."""
|
||||
hooks = hooks or {}
|
||||
hooks = hooks or dict()
|
||||
hooks = hooks.get(key)
|
||||
if hooks:
|
||||
if hasattr(hooks, "__call__"):
|
||||
if hasattr(hooks, '__call__'):
|
||||
hooks = [hooks]
|
||||
for hook in hooks:
|
||||
_hook_data = hook(hook_data, **kwargs)
|
||||
@@ -1,3 +1,5 @@
|
||||
# -*- coding: utf-8 -*-
|
||||
|
||||
"""
|
||||
requests.models
|
||||
~~~~~~~~~~~~~~~
|
||||
@@ -5,73 +7,47 @@ requests.models
|
||||
This module contains the primary objects that power Requests.
|
||||
"""
|
||||
|
||||
import collections
|
||||
import datetime
|
||||
import sys
|
||||
|
||||
# Import encoding now, to avoid implicit import later.
|
||||
# Implicit import within threads may cause LookupError when standard library is in a ZIP,
|
||||
# such as in Embedded Python. See https://github.com/psf/requests/issues/3578.
|
||||
import encodings.idna # noqa: F401
|
||||
from io import UnsupportedOperation
|
||||
# such as in Embedded Python. See https://github.com/requests/requests/issues/3578.
|
||||
import encodings.idna
|
||||
|
||||
from urllib3.exceptions import (
|
||||
DecodeError,
|
||||
LocationParseError,
|
||||
ProtocolError,
|
||||
ReadTimeoutError,
|
||||
SSLError,
|
||||
)
|
||||
from urllib3.fields import RequestField
|
||||
from urllib3.filepost import encode_multipart_formdata
|
||||
from urllib3.util import parse_url
|
||||
from urllib3.exceptions import (
|
||||
DecodeError, ReadTimeoutError, ProtocolError, LocationParseError)
|
||||
|
||||
from ._internal_utils import to_native_string, unicode_is_ascii
|
||||
from .auth import HTTPBasicAuth
|
||||
from .compat import (
|
||||
Callable,
|
||||
JSONDecodeError,
|
||||
Mapping,
|
||||
basestring,
|
||||
builtin_str,
|
||||
chardet,
|
||||
cookielib,
|
||||
)
|
||||
from .compat import json as complexjson
|
||||
from .compat import urlencode, urlsplit, urlunparse
|
||||
from .cookies import _copy_cookie_jar, cookiejar_from_dict, get_cookie_header
|
||||
from .exceptions import (
|
||||
ChunkedEncodingError,
|
||||
ConnectionError,
|
||||
ContentDecodingError,
|
||||
HTTPError,
|
||||
InvalidJSONError,
|
||||
InvalidURL,
|
||||
)
|
||||
from .exceptions import JSONDecodeError as RequestsJSONDecodeError
|
||||
from .exceptions import MissingSchema
|
||||
from .exceptions import SSLError as RequestsSSLError
|
||||
from .exceptions import StreamConsumedError
|
||||
from io import UnsupportedOperation
|
||||
from .hooks import default_hooks
|
||||
from .status_codes import codes
|
||||
from .structures import CaseInsensitiveDict
|
||||
|
||||
from .auth import HTTPBasicAuth
|
||||
from .cookies import cookiejar_from_dict, get_cookie_header, _copy_cookie_jar
|
||||
from .exceptions import (
|
||||
HTTPError, MissingSchema, InvalidURL, ChunkedEncodingError,
|
||||
ContentDecodingError, ConnectionError, StreamConsumedError)
|
||||
from ._internal_utils import to_native_string, unicode_is_ascii
|
||||
from .utils import (
|
||||
check_header_validity,
|
||||
get_auth_from_url,
|
||||
guess_filename,
|
||||
guess_json_utf,
|
||||
iter_slices,
|
||||
parse_header_links,
|
||||
requote_uri,
|
||||
stream_decode_response_unicode,
|
||||
super_len,
|
||||
to_key_val_list,
|
||||
)
|
||||
guess_filename, get_auth_from_url, requote_uri,
|
||||
stream_decode_response_unicode, to_key_val_list, parse_header_links,
|
||||
iter_slices, guess_json_utf, super_len, check_header_validity)
|
||||
from .compat import (
|
||||
cookielib, urlunparse, urlsplit, urlencode, str, bytes,
|
||||
is_py2, chardet, builtin_str, basestring)
|
||||
from .compat import json as complexjson
|
||||
from .status_codes import codes
|
||||
|
||||
#: The set of HTTP status codes that indicate an automatically
|
||||
#: processable redirect.
|
||||
REDIRECT_STATI = (
|
||||
codes.moved, # 301
|
||||
codes.found, # 302
|
||||
codes.other, # 303
|
||||
codes.moved, # 301
|
||||
codes.found, # 302
|
||||
codes.other, # 303
|
||||
codes.temporary_redirect, # 307
|
||||
codes.permanent_redirect, # 308
|
||||
)
|
||||
@@ -81,7 +57,7 @@ CONTENT_CHUNK_SIZE = 10 * 1024
|
||||
ITER_CHUNK_SIZE = 512
|
||||
|
||||
|
||||
class RequestEncodingMixin:
|
||||
class RequestEncodingMixin(object):
|
||||
@property
|
||||
def path_url(self):
|
||||
"""Build the path URL to use."""
|
||||
@@ -92,16 +68,16 @@ class RequestEncodingMixin:
|
||||
|
||||
path = p.path
|
||||
if not path:
|
||||
path = "/"
|
||||
path = '/'
|
||||
|
||||
url.append(path)
|
||||
|
||||
query = p.query
|
||||
if query:
|
||||
url.append("?")
|
||||
url.append('?')
|
||||
url.append(query)
|
||||
|
||||
return "".join(url)
|
||||
return ''.join(url)
|
||||
|
||||
@staticmethod
|
||||
def _encode_params(data):
|
||||
@@ -114,21 +90,18 @@ class RequestEncodingMixin:
|
||||
|
||||
if isinstance(data, (str, bytes)):
|
||||
return data
|
||||
elif hasattr(data, "read"):
|
||||
elif hasattr(data, 'read'):
|
||||
return data
|
||||
elif hasattr(data, "__iter__"):
|
||||
elif hasattr(data, '__iter__'):
|
||||
result = []
|
||||
for k, vs in to_key_val_list(data):
|
||||
if isinstance(vs, basestring) or not hasattr(vs, "__iter__"):
|
||||
if isinstance(vs, basestring) or not hasattr(vs, '__iter__'):
|
||||
vs = [vs]
|
||||
for v in vs:
|
||||
if v is not None:
|
||||
result.append(
|
||||
(
|
||||
k.encode("utf-8") if isinstance(k, str) else k,
|
||||
v.encode("utf-8") if isinstance(v, str) else v,
|
||||
)
|
||||
)
|
||||
(k.encode('utf-8') if isinstance(k, str) else k,
|
||||
v.encode('utf-8') if isinstance(v, str) else v))
|
||||
return urlencode(result, doseq=True)
|
||||
else:
|
||||
return data
|
||||
@@ -143,7 +116,7 @@ class RequestEncodingMixin:
|
||||
The tuples may be 2-tuples (filename, fileobj), 3-tuples (filename, fileobj, contentype)
|
||||
or 4-tuples (filename, fileobj, contentype, custom_headers).
|
||||
"""
|
||||
if not files:
|
||||
if (not files):
|
||||
raise ValueError("Files must be provided.")
|
||||
elif isinstance(data, basestring):
|
||||
raise ValueError("Data must not be a string.")
|
||||
@@ -153,7 +126,7 @@ class RequestEncodingMixin:
|
||||
files = to_key_val_list(files or {})
|
||||
|
||||
for field, val in fields:
|
||||
if isinstance(val, basestring) or not hasattr(val, "__iter__"):
|
||||
if isinstance(val, basestring) or not hasattr(val, '__iter__'):
|
||||
val = [val]
|
||||
for v in val:
|
||||
if v is not None:
|
||||
@@ -162,15 +135,10 @@ class RequestEncodingMixin:
|
||||
v = str(v)
|
||||
|
||||
new_fields.append(
|
||||
(
|
||||
field.decode("utf-8")
|
||||
if isinstance(field, bytes)
|
||||
else field,
|
||||
v.encode("utf-8") if isinstance(v, str) else v,
|
||||
)
|
||||
)
|
||||
(field.decode('utf-8') if isinstance(field, bytes) else field,
|
||||
v.encode('utf-8') if isinstance(v, str) else v))
|
||||
|
||||
for k, v in files:
|
||||
for (k, v) in files:
|
||||
# support for explicit filename
|
||||
ft = None
|
||||
fh = None
|
||||
@@ -187,12 +155,8 @@ class RequestEncodingMixin:
|
||||
|
||||
if isinstance(fp, (str, bytes, bytearray)):
|
||||
fdata = fp
|
||||
elif hasattr(fp, "read"):
|
||||
fdata = fp.read()
|
||||
elif fp is None:
|
||||
continue
|
||||
else:
|
||||
fdata = fp
|
||||
fdata = fp.read()
|
||||
|
||||
rf = RequestField(name=k, data=fdata, filename=fn, headers=fh)
|
||||
rf.make_multipart(content_type=ft)
|
||||
@@ -203,17 +167,17 @@ class RequestEncodingMixin:
|
||||
return body, content_type
|
||||
|
||||
|
||||
class RequestHooksMixin:
|
||||
class RequestHooksMixin(object):
|
||||
def register_hook(self, event, hook):
|
||||
"""Properly register a hook."""
|
||||
|
||||
if event not in self.hooks:
|
||||
raise ValueError(f'Unsupported event specified, with event name "{event}"')
|
||||
raise ValueError('Unsupported event specified, with event name "%s"' % (event))
|
||||
|
||||
if isinstance(hook, Callable):
|
||||
if isinstance(hook, collections.Callable):
|
||||
self.hooks[event].append(hook)
|
||||
elif hasattr(hook, "__iter__"):
|
||||
self.hooks[event].extend(h for h in hook if isinstance(h, Callable))
|
||||
elif hasattr(hook, '__iter__'):
|
||||
self.hooks[event].extend(h for h in hook if isinstance(h, collections.Callable))
|
||||
|
||||
def deregister_hook(self, event, hook):
|
||||
"""Deregister a previously registered hook.
|
||||
@@ -236,13 +200,9 @@ class Request(RequestHooksMixin):
|
||||
:param url: URL to send.
|
||||
:param headers: dictionary of headers to send.
|
||||
:param files: dictionary of {filename: fileobject} files to multipart upload.
|
||||
:param data: the body to attach to the request. If a dictionary or
|
||||
list of tuples ``[(key, value)]`` is provided, form-encoding will
|
||||
take place.
|
||||
:param data: the body to attach to the request. If a dictionary is provided, form-encoding will take place.
|
||||
:param json: json for the body to attach to the request (if files or data is not specified).
|
||||
:param params: URL parameters to append to the URL. If a dictionary or
|
||||
list of tuples ``[(key, value)]`` is provided, form-encoding will
|
||||
take place.
|
||||
:param params: dictionary of URL parameters to append to the URL.
|
||||
:param auth: Auth handler or (user, pass) tuple.
|
||||
:param cookies: dictionary or CookieJar of cookies to attach to this request.
|
||||
:param hooks: dictionary of callback hooks, for internal usage.
|
||||
@@ -250,24 +210,14 @@ class Request(RequestHooksMixin):
|
||||
Usage::
|
||||
|
||||
>>> import requests
|
||||
>>> req = requests.Request('GET', 'https://httpbin.org/get')
|
||||
>>> req = requests.Request('GET', 'http://httpbin.org/get')
|
||||
>>> req.prepare()
|
||||
<PreparedRequest [GET]>
|
||||
"""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
method=None,
|
||||
url=None,
|
||||
headers=None,
|
||||
files=None,
|
||||
data=None,
|
||||
params=None,
|
||||
auth=None,
|
||||
cookies=None,
|
||||
hooks=None,
|
||||
json=None,
|
||||
):
|
||||
def __init__(self, method=None, url=None, headers=None, files=None,
|
||||
data=None, params=None, auth=None, cookies=None, hooks=None, json=None):
|
||||
|
||||
# Default empty dicts for dict params.
|
||||
data = [] if data is None else data
|
||||
files = [] if files is None else files
|
||||
@@ -276,7 +226,7 @@ class Request(RequestHooksMixin):
|
||||
hooks = {} if hooks is None else hooks
|
||||
|
||||
self.hooks = default_hooks()
|
||||
for k, v in list(hooks.items()):
|
||||
for (k, v) in list(hooks.items()):
|
||||
self.register_hook(event=k, hook=v)
|
||||
|
||||
self.method = method
|
||||
@@ -290,7 +240,7 @@ class Request(RequestHooksMixin):
|
||||
self.cookies = cookies
|
||||
|
||||
def __repr__(self):
|
||||
return f"<Request [{self.method}]>"
|
||||
return '<Request [%s]>' % (self.method)
|
||||
|
||||
def prepare(self):
|
||||
"""Constructs a :class:`PreparedRequest <PreparedRequest>` for transmission and returns it."""
|
||||
@@ -314,16 +264,13 @@ class PreparedRequest(RequestEncodingMixin, RequestHooksMixin):
|
||||
"""The fully mutable :class:`PreparedRequest <PreparedRequest>` object,
|
||||
containing the exact bytes that will be sent to the server.
|
||||
|
||||
Instances are generated from a :class:`Request <Request>` object, and
|
||||
should not be instantiated manually; doing so may produce undesirable
|
||||
effects.
|
||||
Generated from either a :class:`Request <Request>` object or manually.
|
||||
|
||||
Usage::
|
||||
|
||||
>>> import requests
|
||||
>>> req = requests.Request('GET', 'https://httpbin.org/get')
|
||||
>>> req = requests.Request('GET', 'http://httpbin.org/get')
|
||||
>>> r = req.prepare()
|
||||
>>> r
|
||||
<PreparedRequest [GET]>
|
||||
|
||||
>>> s = requests.Session()
|
||||
@@ -348,19 +295,8 @@ class PreparedRequest(RequestEncodingMixin, RequestHooksMixin):
|
||||
#: integer denoting starting position of a readable file-like body.
|
||||
self._body_position = None
|
||||
|
||||
def prepare(
|
||||
self,
|
||||
method=None,
|
||||
url=None,
|
||||
headers=None,
|
||||
files=None,
|
||||
data=None,
|
||||
params=None,
|
||||
auth=None,
|
||||
cookies=None,
|
||||
hooks=None,
|
||||
json=None,
|
||||
):
|
||||
def prepare(self, method=None, url=None, headers=None, files=None,
|
||||
data=None, params=None, auth=None, cookies=None, hooks=None, json=None):
|
||||
"""Prepares the entire request with the given parameters."""
|
||||
|
||||
self.prepare_method(method)
|
||||
@@ -377,7 +313,7 @@ class PreparedRequest(RequestEncodingMixin, RequestHooksMixin):
|
||||
self.prepare_hooks(hooks)
|
||||
|
||||
def __repr__(self):
|
||||
return f"<PreparedRequest [{self.method}]>"
|
||||
return '<PreparedRequest [%s]>' % (self.method)
|
||||
|
||||
def copy(self):
|
||||
p = PreparedRequest()
|
||||
@@ -401,7 +337,7 @@ class PreparedRequest(RequestEncodingMixin, RequestHooksMixin):
|
||||
import idna
|
||||
|
||||
try:
|
||||
host = idna.encode(host, uts46=True).decode("utf-8")
|
||||
host = idna.encode(host, uts46=True).decode('utf-8')
|
||||
except idna.IDNAError:
|
||||
raise UnicodeError
|
||||
return host
|
||||
@@ -412,11 +348,11 @@ class PreparedRequest(RequestEncodingMixin, RequestHooksMixin):
|
||||
#: We're unable to blindly call unicode/str functions
|
||||
#: as this will include the bytestring indicator (b'')
|
||||
#: on python 3.x.
|
||||
#: https://github.com/psf/requests/pull/2238
|
||||
#: https://github.com/requests/requests/pull/2238
|
||||
if isinstance(url, bytes):
|
||||
url = url.decode("utf8")
|
||||
url = url.decode('utf8')
|
||||
else:
|
||||
url = str(url)
|
||||
url = unicode(url) if is_py2 else str(url)
|
||||
|
||||
# Remove leading whitespaces from url
|
||||
url = url.lstrip()
|
||||
@@ -424,7 +360,7 @@ class PreparedRequest(RequestEncodingMixin, RequestHooksMixin):
|
||||
# Don't do any URL preparation for non-HTTP schemes like `mailto`,
|
||||
# `data` etc to work around exceptions from `url_parse`, which
|
||||
# handles RFC 3986 only.
|
||||
if ":" in url and not url.lower().startswith("http"):
|
||||
if ':' in url and not url.lower().startswith('http'):
|
||||
self.url = url
|
||||
return
|
||||
|
||||
@@ -435,13 +371,13 @@ class PreparedRequest(RequestEncodingMixin, RequestHooksMixin):
|
||||
raise InvalidURL(*e.args)
|
||||
|
||||
if not scheme:
|
||||
raise MissingSchema(
|
||||
f"Invalid URL {url!r}: No scheme supplied. "
|
||||
f"Perhaps you meant https://{url}?"
|
||||
)
|
||||
error = ("Invalid URL {0!r}: No schema supplied. Perhaps you meant http://{0}?")
|
||||
error = error.format(to_native_string(url, 'utf8'))
|
||||
|
||||
raise MissingSchema(error)
|
||||
|
||||
if not host:
|
||||
raise InvalidURL(f"Invalid URL {url!r}: No host supplied")
|
||||
raise InvalidURL("Invalid URL %r: No host supplied" % url)
|
||||
|
||||
# In general, we want to try IDNA encoding the hostname if the string contains
|
||||
# non-ASCII characters. This allows users to automatically get the correct IDNA
|
||||
@@ -451,21 +387,33 @@ class PreparedRequest(RequestEncodingMixin, RequestHooksMixin):
|
||||
try:
|
||||
host = self._get_idna_encoded_host(host)
|
||||
except UnicodeError:
|
||||
raise InvalidURL("URL has an invalid label.")
|
||||
elif host.startswith(("*", ".")):
|
||||
raise InvalidURL("URL has an invalid label.")
|
||||
raise InvalidURL('URL has an invalid label.')
|
||||
elif host.startswith(u'*'):
|
||||
raise InvalidURL('URL has an invalid label.')
|
||||
|
||||
# Carefully reconstruct the network location
|
||||
netloc = auth or ""
|
||||
netloc = auth or ''
|
||||
if netloc:
|
||||
netloc += "@"
|
||||
netloc += '@'
|
||||
netloc += host
|
||||
if port:
|
||||
netloc += f":{port}"
|
||||
netloc += ':' + str(port)
|
||||
|
||||
# Bare domains aren't valid URLs.
|
||||
if not path:
|
||||
path = "/"
|
||||
path = '/'
|
||||
|
||||
if is_py2:
|
||||
if isinstance(scheme, str):
|
||||
scheme = scheme.encode('utf-8')
|
||||
if isinstance(netloc, str):
|
||||
netloc = netloc.encode('utf-8')
|
||||
if isinstance(path, str):
|
||||
path = path.encode('utf-8')
|
||||
if isinstance(query, str):
|
||||
query = query.encode('utf-8')
|
||||
if isinstance(fragment, str):
|
||||
fragment = fragment.encode('utf-8')
|
||||
|
||||
if isinstance(params, (str, bytes)):
|
||||
params = to_native_string(params)
|
||||
@@ -473,7 +421,7 @@ class PreparedRequest(RequestEncodingMixin, RequestHooksMixin):
|
||||
enc_params = self._encode_params(params)
|
||||
if enc_params:
|
||||
if query:
|
||||
query = f"{query}&{enc_params}"
|
||||
query = '%s&%s' % (query, enc_params)
|
||||
else:
|
||||
query = enc_params
|
||||
|
||||
@@ -504,51 +452,42 @@ class PreparedRequest(RequestEncodingMixin, RequestHooksMixin):
|
||||
if not data and json is not None:
|
||||
# urllib3 requires a bytes-like body. Python 2's json.dumps
|
||||
# provides this natively, but Python 3 gives a Unicode string.
|
||||
content_type = "application/json"
|
||||
|
||||
try:
|
||||
body = complexjson.dumps(json, allow_nan=False)
|
||||
except ValueError as ve:
|
||||
raise InvalidJSONError(ve, request=self)
|
||||
|
||||
content_type = 'application/json'
|
||||
body = complexjson.dumps(json)
|
||||
if not isinstance(body, bytes):
|
||||
body = body.encode("utf-8")
|
||||
body = body.encode('utf-8')
|
||||
|
||||
is_stream = all(
|
||||
[
|
||||
hasattr(data, "__iter__"),
|
||||
not isinstance(data, (basestring, list, tuple, Mapping)),
|
||||
]
|
||||
)
|
||||
is_stream = all([
|
||||
hasattr(data, '__iter__'),
|
||||
not isinstance(data, (basestring, list, tuple, collections.Mapping))
|
||||
])
|
||||
|
||||
try:
|
||||
length = super_len(data)
|
||||
except (TypeError, AttributeError, UnsupportedOperation):
|
||||
length = None
|
||||
|
||||
if is_stream:
|
||||
try:
|
||||
length = super_len(data)
|
||||
except (TypeError, AttributeError, UnsupportedOperation):
|
||||
length = None
|
||||
|
||||
body = data
|
||||
|
||||
if getattr(body, "tell", None) is not None:
|
||||
if getattr(body, 'tell', None) is not None:
|
||||
# Record the current file position before reading.
|
||||
# This will allow us to rewind a file in the event
|
||||
# of a redirect.
|
||||
try:
|
||||
self._body_position = body.tell()
|
||||
except OSError:
|
||||
except (IOError, OSError):
|
||||
# This differentiates from None, allowing us to catch
|
||||
# a failed `tell()` later when trying to rewind the body
|
||||
self._body_position = object()
|
||||
|
||||
if files:
|
||||
raise NotImplementedError(
|
||||
"Streamed bodies and files are mutually exclusive."
|
||||
)
|
||||
raise NotImplementedError('Streamed bodies and files are mutually exclusive.')
|
||||
|
||||
if length:
|
||||
self.headers["Content-Length"] = builtin_str(length)
|
||||
self.headers['Content-Length'] = builtin_str(length)
|
||||
else:
|
||||
self.headers["Transfer-Encoding"] = "chunked"
|
||||
self.headers['Transfer-Encoding'] = 'chunked'
|
||||
else:
|
||||
# Multi-part file uploads.
|
||||
if files:
|
||||
@@ -556,16 +495,16 @@ class PreparedRequest(RequestEncodingMixin, RequestHooksMixin):
|
||||
else:
|
||||
if data:
|
||||
body = self._encode_params(data)
|
||||
if isinstance(data, basestring) or hasattr(data, "read"):
|
||||
if isinstance(data, basestring) or hasattr(data, 'read'):
|
||||
content_type = None
|
||||
else:
|
||||
content_type = "application/x-www-form-urlencoded"
|
||||
content_type = 'application/x-www-form-urlencoded'
|
||||
|
||||
self.prepare_content_length(body)
|
||||
|
||||
# Add content-type if it wasn't explicitly provided.
|
||||
if content_type and ("content-type" not in self.headers):
|
||||
self.headers["Content-Type"] = content_type
|
||||
if content_type and ('content-type' not in self.headers):
|
||||
self.headers['Content-Type'] = content_type
|
||||
|
||||
self.body = body
|
||||
|
||||
@@ -576,16 +515,13 @@ class PreparedRequest(RequestEncodingMixin, RequestHooksMixin):
|
||||
if length:
|
||||
# If length exists, set it. Otherwise, we fallback
|
||||
# to Transfer-Encoding: chunked.
|
||||
self.headers["Content-Length"] = builtin_str(length)
|
||||
elif (
|
||||
self.method not in ("GET", "HEAD")
|
||||
and self.headers.get("Content-Length") is None
|
||||
):
|
||||
self.headers['Content-Length'] = builtin_str(length)
|
||||
elif self.method not in ('GET', 'HEAD') and self.headers.get('Content-Length') is None:
|
||||
# Set Content-Length to 0 for methods that can have a body
|
||||
# but don't provide one. (i.e. not GET or HEAD)
|
||||
self.headers["Content-Length"] = "0"
|
||||
self.headers['Content-Length'] = '0'
|
||||
|
||||
def prepare_auth(self, auth, url=""):
|
||||
def prepare_auth(self, auth, url=''):
|
||||
"""Prepares the given HTTP auth data."""
|
||||
|
||||
# If no Auth is explicitly provided, extract it from the URL first.
|
||||
@@ -625,7 +561,7 @@ class PreparedRequest(RequestEncodingMixin, RequestHooksMixin):
|
||||
|
||||
cookie_header = get_cookie_header(self._cookies, self)
|
||||
if cookie_header is not None:
|
||||
self.headers["Cookie"] = cookie_header
|
||||
self.headers['Cookie'] = cookie_header
|
||||
|
||||
def prepare_hooks(self, hooks):
|
||||
"""Prepares the given hooks."""
|
||||
@@ -637,25 +573,19 @@ class PreparedRequest(RequestEncodingMixin, RequestHooksMixin):
|
||||
self.register_hook(event, hooks[event])
|
||||
|
||||
|
||||
class Response:
|
||||
class Response(object):
|
||||
"""The :class:`Response <Response>` object, which contains a
|
||||
server's response to an HTTP request.
|
||||
"""
|
||||
|
||||
__attrs__ = [
|
||||
"_content",
|
||||
"status_code",
|
||||
"headers",
|
||||
"url",
|
||||
"history",
|
||||
"encoding",
|
||||
"reason",
|
||||
"cookies",
|
||||
"elapsed",
|
||||
"request",
|
||||
'_content', 'status_code', 'headers', 'url', 'history',
|
||||
'encoding', 'reason', 'cookies', 'elapsed', 'request'
|
||||
]
|
||||
|
||||
def __init__(self):
|
||||
super(Response, self).__init__()
|
||||
|
||||
self._content = False
|
||||
self._content_consumed = False
|
||||
self._next = None
|
||||
@@ -670,7 +600,7 @@ class Response:
|
||||
|
||||
#: File-like object representation of response (for advanced usage).
|
||||
#: Use of ``raw`` requires that ``stream=True`` be set on the request.
|
||||
#: This requirement does not apply for use internally to Requests.
|
||||
# This requirement does not apply for use internally to Requests.
|
||||
self.raw = None
|
||||
|
||||
#: Final URL location of Response.
|
||||
@@ -702,30 +632,27 @@ class Response:
|
||||
#: is a response.
|
||||
self.request = None
|
||||
|
||||
def __enter__(self):
|
||||
return self
|
||||
|
||||
def __exit__(self, *args):
|
||||
self.close()
|
||||
|
||||
def __getstate__(self):
|
||||
# Consume everything; accessing the content attribute makes
|
||||
# sure the content has been fully read.
|
||||
if not self._content_consumed:
|
||||
self.content
|
||||
|
||||
return {attr: getattr(self, attr, None) for attr in self.__attrs__}
|
||||
return dict(
|
||||
(attr, getattr(self, attr, None))
|
||||
for attr in self.__attrs__
|
||||
)
|
||||
|
||||
def __setstate__(self, state):
|
||||
for name, value in state.items():
|
||||
setattr(self, name, value)
|
||||
|
||||
# pickled objects do not have .raw
|
||||
setattr(self, "_content_consumed", True)
|
||||
setattr(self, "raw", None)
|
||||
setattr(self, '_content_consumed', True)
|
||||
setattr(self, 'raw', None)
|
||||
|
||||
def __repr__(self):
|
||||
return f"<Response [{self.status_code}]>"
|
||||
return '<Response [%s]>' % (self.status_code)
|
||||
|
||||
def __bool__(self):
|
||||
"""Returns True if :attr:`status_code` is less than 400.
|
||||
@@ -753,11 +680,11 @@ class Response:
|
||||
|
||||
@property
|
||||
def ok(self):
|
||||
"""Returns True if :attr:`status_code` is less than 400, False if not.
|
||||
"""Returns True if :attr:`status_code` is less than 400.
|
||||
|
||||
This attribute checks if the status code of the response is between
|
||||
400 and 600 to see if there was a client error or a server error. If
|
||||
the status code is between 200 and 400, this will return True. This
|
||||
the status code, is between 200 and 400, this will return True. This
|
||||
is **not** a check to see if the response code is ``200 OK``.
|
||||
"""
|
||||
try:
|
||||
@@ -771,15 +698,12 @@ class Response:
|
||||
"""True if this Response is a well-formed HTTP redirect that could have
|
||||
been processed automatically (by :meth:`Session.resolve_redirects`).
|
||||
"""
|
||||
return "location" in self.headers and self.status_code in REDIRECT_STATI
|
||||
return ('location' in self.headers and self.status_code in REDIRECT_STATI)
|
||||
|
||||
@property
|
||||
def is_permanent_redirect(self):
|
||||
"""True if this Response one of the permanent versions of redirect."""
|
||||
return "location" in self.headers and self.status_code in (
|
||||
codes.moved_permanently,
|
||||
codes.permanent_redirect,
|
||||
)
|
||||
return ('location' in self.headers and self.status_code in (codes.moved_permanently, codes.permanent_redirect))
|
||||
|
||||
@property
|
||||
def next(self):
|
||||
@@ -788,13 +712,8 @@ class Response:
|
||||
|
||||
@property
|
||||
def apparent_encoding(self):
|
||||
"""The apparent encoding, provided by the charset_normalizer or chardet libraries."""
|
||||
if chardet is not None:
|
||||
return chardet.detect(self.content)["encoding"]
|
||||
else:
|
||||
# If no character detection library is available, we'll fall back
|
||||
# to a standard Python utf-8 str.
|
||||
return "utf-8"
|
||||
"""The apparent encoding, provided by the chardet library."""
|
||||
return chardet.detect(self.content)['encoding']
|
||||
|
||||
def iter_content(self, chunk_size=1, decode_unicode=False):
|
||||
"""Iterates over the response data. When stream=True is set on the
|
||||
@@ -815,17 +734,16 @@ class Response:
|
||||
|
||||
def generate():
|
||||
# Special case for urllib3.
|
||||
if hasattr(self.raw, "stream"):
|
||||
if hasattr(self.raw, 'stream'):
|
||||
try:
|
||||
yield from self.raw.stream(chunk_size, decode_content=True)
|
||||
for chunk in self.raw.stream(chunk_size, decode_content=True):
|
||||
yield chunk
|
||||
except ProtocolError as e:
|
||||
raise ChunkedEncodingError(e)
|
||||
except DecodeError as e:
|
||||
raise ContentDecodingError(e)
|
||||
except ReadTimeoutError as e:
|
||||
raise ConnectionError(e)
|
||||
except SSLError as e:
|
||||
raise RequestsSSLError(e)
|
||||
else:
|
||||
# Standard file-like object.
|
||||
while True:
|
||||
@@ -839,9 +757,7 @@ class Response:
|
||||
if self._content_consumed and isinstance(self._content, bool):
|
||||
raise StreamConsumedError()
|
||||
elif chunk_size is not None and not isinstance(chunk_size, int):
|
||||
raise TypeError(
|
||||
f"chunk_size must be an int, it is instead a {type(chunk_size)}."
|
||||
)
|
||||
raise TypeError("chunk_size must be an int, it is instead a %s." % type(chunk_size))
|
||||
# simulate reading small chunks of the content
|
||||
reused_chunks = iter_slices(self._content, chunk_size)
|
||||
|
||||
@@ -854,9 +770,7 @@ class Response:
|
||||
|
||||
return chunks
|
||||
|
||||
def iter_lines(
|
||||
self, chunk_size=ITER_CHUNK_SIZE, decode_unicode=False, delimiter=None
|
||||
):
|
||||
def iter_lines(self, chunk_size=ITER_CHUNK_SIZE, decode_unicode=None, delimiter=None):
|
||||
"""Iterates over the response data, one line at a time. When
|
||||
stream=True is set on the request, this avoids reading the
|
||||
content at once into memory for large responses.
|
||||
@@ -866,9 +780,8 @@ class Response:
|
||||
|
||||
pending = None
|
||||
|
||||
for chunk in self.iter_content(
|
||||
chunk_size=chunk_size, decode_unicode=decode_unicode
|
||||
):
|
||||
for chunk in self.iter_content(chunk_size=chunk_size, decode_unicode=decode_unicode):
|
||||
|
||||
if pending is not None:
|
||||
chunk = pending + chunk
|
||||
|
||||
@@ -882,7 +795,8 @@ class Response:
|
||||
else:
|
||||
pending = None
|
||||
|
||||
yield from lines
|
||||
for line in lines:
|
||||
yield line
|
||||
|
||||
if pending is not None:
|
||||
yield pending
|
||||
@@ -894,12 +808,13 @@ class Response:
|
||||
if self._content is False:
|
||||
# Read the contents.
|
||||
if self._content_consumed:
|
||||
raise RuntimeError("The content for this response was already consumed")
|
||||
raise RuntimeError(
|
||||
'The content for this response was already consumed')
|
||||
|
||||
if self.status_code == 0 or self.raw is None:
|
||||
self._content = None
|
||||
else:
|
||||
self._content = b"".join(self.iter_content(CONTENT_CHUNK_SIZE)) or b""
|
||||
self._content = bytes().join(self.iter_content(CONTENT_CHUNK_SIZE)) or bytes()
|
||||
|
||||
self._content_consumed = True
|
||||
# don't need to release the connection; that's been handled by urllib3
|
||||
@@ -911,7 +826,7 @@ class Response:
|
||||
"""Content of the response, in unicode.
|
||||
|
||||
If Response.encoding is None, encoding will be guessed using
|
||||
``charset_normalizer`` or ``chardet``.
|
||||
``chardet``.
|
||||
|
||||
The encoding of the response content is determined based solely on HTTP
|
||||
headers, following RFC 2616 to the letter. If you can take advantage of
|
||||
@@ -924,7 +839,7 @@ class Response:
|
||||
encoding = self.encoding
|
||||
|
||||
if not self.content:
|
||||
return ""
|
||||
return str('')
|
||||
|
||||
# Fallback to auto-detected encoding.
|
||||
if self.encoding is None:
|
||||
@@ -932,7 +847,7 @@ class Response:
|
||||
|
||||
# Decode unicode from given encoding.
|
||||
try:
|
||||
content = str(self.content, encoding, errors="replace")
|
||||
content = str(self.content, encoding, errors='replace')
|
||||
except (LookupError, TypeError):
|
||||
# A LookupError is raised if the encoding was not found which could
|
||||
# indicate a misspelling or similar mistake.
|
||||
@@ -940,7 +855,7 @@ class Response:
|
||||
# A TypeError can be raised if encoding is None
|
||||
#
|
||||
# So we try blindly encoding.
|
||||
content = str(self.content, errors="replace")
|
||||
content = str(self.content, errors='replace')
|
||||
|
||||
return content
|
||||
|
||||
@@ -948,77 +863,67 @@ class Response:
|
||||
r"""Returns the json-encoded content of a response, if any.
|
||||
|
||||
:param \*\*kwargs: Optional arguments that ``json.loads`` takes.
|
||||
:raises requests.exceptions.JSONDecodeError: If the response body does not
|
||||
contain valid json.
|
||||
:raises ValueError: If the response body does not contain valid json.
|
||||
"""
|
||||
|
||||
if not self.encoding and self.content and len(self.content) > 3:
|
||||
# No encoding set. JSON RFC 4627 section 3 states we should expect
|
||||
# UTF-8, -16 or -32. Detect which one to use; If the detection or
|
||||
# decoding fails, fall back to `self.text` (using charset_normalizer to make
|
||||
# decoding fails, fall back to `self.text` (using chardet to make
|
||||
# a best guess).
|
||||
encoding = guess_json_utf(self.content)
|
||||
if encoding is not None:
|
||||
try:
|
||||
return complexjson.loads(self.content.decode(encoding), **kwargs)
|
||||
return complexjson.loads(
|
||||
self.content.decode(encoding), **kwargs
|
||||
)
|
||||
except UnicodeDecodeError:
|
||||
# Wrong UTF codec detected; usually because it's not UTF-8
|
||||
# but some other 8-bit codec. This is an RFC violation,
|
||||
# and the server didn't bother to tell us what codec *was*
|
||||
# used.
|
||||
pass
|
||||
except JSONDecodeError as e:
|
||||
raise RequestsJSONDecodeError(e.msg, e.doc, e.pos)
|
||||
|
||||
try:
|
||||
return complexjson.loads(self.text, **kwargs)
|
||||
except JSONDecodeError as e:
|
||||
# Catch JSON-related errors and raise as requests.JSONDecodeError
|
||||
# This aliases json.JSONDecodeError and simplejson.JSONDecodeError
|
||||
raise RequestsJSONDecodeError(e.msg, e.doc, e.pos)
|
||||
return complexjson.loads(self.text, **kwargs)
|
||||
|
||||
@property
|
||||
def links(self):
|
||||
"""Returns the parsed header links of the response, if any."""
|
||||
|
||||
header = self.headers.get("link")
|
||||
header = self.headers.get('link')
|
||||
|
||||
resolved_links = {}
|
||||
# l = MultiDict()
|
||||
l = {}
|
||||
|
||||
if header:
|
||||
links = parse_header_links(header)
|
||||
|
||||
for link in links:
|
||||
key = link.get("rel") or link.get("url")
|
||||
resolved_links[key] = link
|
||||
key = link.get('rel') or link.get('url')
|
||||
l[key] = link
|
||||
|
||||
return resolved_links
|
||||
return l
|
||||
|
||||
def raise_for_status(self):
|
||||
"""Raises :class:`HTTPError`, if one occurred."""
|
||||
"""Raises stored :class:`HTTPError`, if one occurred."""
|
||||
|
||||
http_error_msg = ""
|
||||
http_error_msg = ''
|
||||
if isinstance(self.reason, bytes):
|
||||
# We attempt to decode utf-8 first because some servers
|
||||
# choose to localize their reason strings. If the string
|
||||
# isn't utf-8, we fall back to iso-8859-1 for all other
|
||||
# encodings. (See PR #3538)
|
||||
try:
|
||||
reason = self.reason.decode("utf-8")
|
||||
reason = self.reason.decode('utf-8')
|
||||
except UnicodeDecodeError:
|
||||
reason = self.reason.decode("iso-8859-1")
|
||||
reason = self.reason.decode('iso-8859-1')
|
||||
else:
|
||||
reason = self.reason
|
||||
|
||||
if 400 <= self.status_code < 500:
|
||||
http_error_msg = (
|
||||
f"{self.status_code} Client Error: {reason} for url: {self.url}"
|
||||
)
|
||||
http_error_msg = u'%s Client Error: %s for url: %s' % (self.status_code, reason, self.url)
|
||||
|
||||
elif 500 <= self.status_code < 600:
|
||||
http_error_msg = (
|
||||
f"{self.status_code} Server Error: {reason} for url: {self.url}"
|
||||
)
|
||||
http_error_msg = u'%s Server Error: %s for url: %s' % (self.status_code, reason, self.url)
|
||||
|
||||
if http_error_msg:
|
||||
raise HTTPError(http_error_msg, response=self)
|
||||
@@ -1032,6 +937,6 @@ class Response:
|
||||
if not self._content_consumed:
|
||||
self.raw.close()
|
||||
|
||||
release_conn = getattr(self.raw, "release_conn", None)
|
||||
release_conn = getattr(self.raw, 'release_conn', None)
|
||||
if release_conn is not None:
|
||||
release_conn()
|
||||
14
requests/packages.py
Normal file
@@ -0,0 +1,14 @@
|
||||
import sys
|
||||
|
||||
# This code exists for backwards compatibility reasons.
|
||||
# I don't like it either. Just look the other way. :)
|
||||
|
||||
for package in ('urllib3', 'idna', 'chardet'):
|
||||
__import__(package)
|
||||
# This traversal is apparently necessary such that the identities are
|
||||
# preserved (requests.packages.urllib3.* is urllib3.*)
|
||||
for mod in list(sys.modules):
|
||||
if mod == package or mod.startswith(package + '.'):
|
||||
sys.modules['requests.packages.' + mod] = sys.modules[mod]
|
||||
|
||||
# Kinda cool, though, right?
|
||||
411
src/requests/sessions.py → requests/sessions.py
Normal file → Executable file
@@ -1,59 +1,48 @@
|
||||
# -*- coding: utf-8 -*-
|
||||
|
||||
"""
|
||||
requests.sessions
|
||||
~~~~~~~~~~~~~~~~~
|
||||
requests.session
|
||||
~~~~~~~~~~~~~~~~
|
||||
|
||||
This module provides a Session object to manage and persist settings across
|
||||
requests (cookies, auth, proxies).
|
||||
"""
|
||||
import os
|
||||
import sys
|
||||
import platform
|
||||
import time
|
||||
from collections import OrderedDict
|
||||
from collections import Mapping
|
||||
from datetime import timedelta
|
||||
|
||||
from ._internal_utils import to_native_string
|
||||
from .adapters import HTTPAdapter
|
||||
from .auth import _basic_auth_str
|
||||
from .compat import Mapping, cookielib, urljoin, urlparse
|
||||
from .compat import cookielib, is_py3, OrderedDict, urljoin, urlparse
|
||||
from .cookies import (
|
||||
RequestsCookieJar,
|
||||
cookiejar_from_dict,
|
||||
extract_cookies_to_jar,
|
||||
merge_cookies,
|
||||
)
|
||||
from .exceptions import (
|
||||
ChunkedEncodingError,
|
||||
ContentDecodingError,
|
||||
InvalidSchema,
|
||||
TooManyRedirects,
|
||||
)
|
||||
cookiejar_from_dict, extract_cookies_to_jar, RequestsCookieJar, merge_cookies)
|
||||
from .models import Request, PreparedRequest, DEFAULT_REDIRECT_LIMIT
|
||||
from .hooks import default_hooks, dispatch_hook
|
||||
from ._internal_utils import to_native_string
|
||||
from .utils import to_key_val_list, default_headers
|
||||
from .exceptions import (
|
||||
TooManyRedirects, InvalidSchema, ChunkedEncodingError, ContentDecodingError)
|
||||
|
||||
from .structures import CaseInsensitiveDict
|
||||
from .adapters import HTTPAdapter
|
||||
|
||||
from .utils import (
|
||||
requote_uri, get_environ_proxies, get_netrc_auth, should_bypass_proxies,
|
||||
get_auth_from_url, rewind_body
|
||||
)
|
||||
|
||||
from .status_codes import codes
|
||||
|
||||
# formerly defined here, reexposed here for backward compatibility
|
||||
from .models import ( # noqa: F401
|
||||
DEFAULT_REDIRECT_LIMIT,
|
||||
REDIRECT_STATI,
|
||||
PreparedRequest,
|
||||
Request,
|
||||
)
|
||||
from .status_codes import codes
|
||||
from .structures import CaseInsensitiveDict
|
||||
from .utils import ( # noqa: F401
|
||||
DEFAULT_PORTS,
|
||||
default_headers,
|
||||
get_auth_from_url,
|
||||
get_environ_proxies,
|
||||
get_netrc_auth,
|
||||
requote_uri,
|
||||
resolve_proxies,
|
||||
rewind_body,
|
||||
should_bypass_proxies,
|
||||
to_key_val_list,
|
||||
)
|
||||
from .models import REDIRECT_STATI
|
||||
|
||||
# Preferred clock, based on which one is more accurate on a given system.
|
||||
if sys.platform == "win32":
|
||||
preferred_clock = time.perf_counter
|
||||
if platform.system() == 'Windows':
|
||||
try: # Python 3.3+
|
||||
preferred_clock = time.perf_counter
|
||||
except AttributeError: # Earlier than Python 3.
|
||||
preferred_clock = time.clock
|
||||
else:
|
||||
preferred_clock = time.time
|
||||
|
||||
@@ -72,7 +61,8 @@ def merge_setting(request_setting, session_setting, dict_class=OrderedDict):
|
||||
|
||||
# Bypass if not a dictionary (e.g. verify)
|
||||
if not (
|
||||
isinstance(session_setting, Mapping) and isinstance(request_setting, Mapping)
|
||||
isinstance(session_setting, Mapping) and
|
||||
isinstance(request_setting, Mapping)
|
||||
):
|
||||
return request_setting
|
||||
|
||||
@@ -94,86 +84,39 @@ def merge_hooks(request_hooks, session_hooks, dict_class=OrderedDict):
|
||||
This is necessary because when request_hooks == {'response': []}, the
|
||||
merge breaks Session hooks entirely.
|
||||
"""
|
||||
if session_hooks is None or session_hooks.get("response") == []:
|
||||
if session_hooks is None or session_hooks.get('response') == []:
|
||||
return request_hooks
|
||||
|
||||
if request_hooks is None or request_hooks.get("response") == []:
|
||||
if request_hooks is None or request_hooks.get('response') == []:
|
||||
return session_hooks
|
||||
|
||||
return merge_setting(request_hooks, session_hooks, dict_class)
|
||||
|
||||
|
||||
class SessionRedirectMixin:
|
||||
class SessionRedirectMixin(object):
|
||||
|
||||
def get_redirect_target(self, resp):
|
||||
"""Receives a Response. Returns a redirect URI or ``None``"""
|
||||
# Due to the nature of how requests processes redirects this method will
|
||||
# be called at least once upon the original response and at least twice
|
||||
# on each subsequent redirect response (if any).
|
||||
# If a custom mixin is used to handle this logic, it may be advantageous
|
||||
# to cache the redirect location onto the response object as a private
|
||||
# attribute.
|
||||
if resp.is_redirect:
|
||||
location = resp.headers["location"]
|
||||
location = resp.headers['location']
|
||||
# Currently the underlying http module on py3 decode headers
|
||||
# in latin1, but empirical evidence suggests that latin1 is very
|
||||
# rarely used with non-ASCII characters in HTTP headers.
|
||||
# It is more likely to get UTF8 header rather than latin1.
|
||||
# This causes incorrect handling of UTF8 encoded location headers.
|
||||
# To solve this, we re-encode the location in latin1.
|
||||
location = location.encode("latin1")
|
||||
return to_native_string(location, "utf8")
|
||||
if is_py3:
|
||||
location = location.encode('latin1')
|
||||
return to_native_string(location, 'utf8')
|
||||
return None
|
||||
|
||||
def should_strip_auth(self, old_url, new_url):
|
||||
"""Decide whether Authorization header should be removed when redirecting"""
|
||||
old_parsed = urlparse(old_url)
|
||||
new_parsed = urlparse(new_url)
|
||||
if old_parsed.hostname != new_parsed.hostname:
|
||||
return True
|
||||
# Special case: allow http -> https redirect when using the standard
|
||||
# ports. This isn't specified by RFC 7235, but is kept to avoid
|
||||
# breaking backwards compatibility with older versions of requests
|
||||
# that allowed any redirects on the same host.
|
||||
if (
|
||||
old_parsed.scheme == "http"
|
||||
and old_parsed.port in (80, None)
|
||||
and new_parsed.scheme == "https"
|
||||
and new_parsed.port in (443, None)
|
||||
):
|
||||
return False
|
||||
|
||||
# Handle default port usage corresponding to scheme.
|
||||
changed_port = old_parsed.port != new_parsed.port
|
||||
changed_scheme = old_parsed.scheme != new_parsed.scheme
|
||||
default_port = (DEFAULT_PORTS.get(old_parsed.scheme, None), None)
|
||||
if (
|
||||
not changed_scheme
|
||||
and old_parsed.port in default_port
|
||||
and new_parsed.port in default_port
|
||||
):
|
||||
return False
|
||||
|
||||
# Standard case: root URI must match
|
||||
return changed_port or changed_scheme
|
||||
|
||||
def resolve_redirects(
|
||||
self,
|
||||
resp,
|
||||
req,
|
||||
stream=False,
|
||||
timeout=None,
|
||||
verify=True,
|
||||
cert=None,
|
||||
proxies=None,
|
||||
yield_requests=False,
|
||||
**adapter_kwargs,
|
||||
):
|
||||
def resolve_redirects(self, resp, req, stream=False, timeout=None,
|
||||
verify=True, cert=None, proxies=None, yield_requests=False, **adapter_kwargs):
|
||||
"""Receives a Response. Returns a generator of Responses or Requests."""
|
||||
|
||||
hist = [] # keep track of history
|
||||
hist = [] # keep track of history
|
||||
|
||||
url = self.get_redirect_target(resp)
|
||||
previous_fragment = urlparse(req.url).fragment
|
||||
while url:
|
||||
prepared_request = req.copy()
|
||||
|
||||
@@ -188,24 +131,18 @@ class SessionRedirectMixin:
|
||||
resp.raw.read(decode_content=False)
|
||||
|
||||
if len(resp.history) >= self.max_redirects:
|
||||
raise TooManyRedirects(
|
||||
f"Exceeded {self.max_redirects} redirects.", response=resp
|
||||
)
|
||||
raise TooManyRedirects('Exceeded %s redirects.' % self.max_redirects, response=resp)
|
||||
|
||||
# Release the connection back into the pool.
|
||||
resp.close()
|
||||
|
||||
# Handle redirection without scheme (see: RFC 1808 Section 4)
|
||||
if url.startswith("//"):
|
||||
if url.startswith('//'):
|
||||
parsed_rurl = urlparse(resp.url)
|
||||
url = ":".join([to_native_string(parsed_rurl.scheme), url])
|
||||
url = '%s:%s' % (to_native_string(parsed_rurl.scheme), url)
|
||||
|
||||
# Normalize url case and attach previous fragment if needed (RFC 7231 7.1.2)
|
||||
# The scheme should be lower case...
|
||||
parsed = urlparse(url)
|
||||
if parsed.fragment == "" and previous_fragment:
|
||||
parsed = parsed._replace(fragment=previous_fragment)
|
||||
elif parsed.fragment:
|
||||
previous_fragment = parsed.fragment
|
||||
url = parsed.geturl()
|
||||
|
||||
# Facilitate relative 'location' headers, as allowed by RFC 7231.
|
||||
@@ -220,19 +157,19 @@ class SessionRedirectMixin:
|
||||
|
||||
self.rebuild_method(prepared_request, resp)
|
||||
|
||||
# https://github.com/psf/requests/issues/1084
|
||||
if resp.status_code not in (
|
||||
codes.temporary_redirect,
|
||||
codes.permanent_redirect,
|
||||
):
|
||||
# https://github.com/psf/requests/issues/3490
|
||||
purged_headers = ("Content-Length", "Content-Type", "Transfer-Encoding")
|
||||
# https://github.com/requests/requests/issues/1084
|
||||
if resp.status_code not in (codes.temporary_redirect, codes.permanent_redirect):
|
||||
# https://github.com/requests/requests/issues/3490
|
||||
purged_headers = ('Content-Length', 'Content-Type', 'Transfer-Encoding')
|
||||
for header in purged_headers:
|
||||
prepared_request.headers.pop(header, None)
|
||||
prepared_request.body = None
|
||||
|
||||
headers = prepared_request.headers
|
||||
headers.pop("Cookie", None)
|
||||
try:
|
||||
del headers['Cookie']
|
||||
except KeyError:
|
||||
pass
|
||||
|
||||
# Extract any cookies sent on the response to the cookiejar
|
||||
# in the new request. Because we've mutated our copied prepared
|
||||
@@ -248,8 +185,9 @@ class SessionRedirectMixin:
|
||||
# A failed tell() sets `_body_position` to `object()`. This non-None
|
||||
# value ensures `rewindable` will be True, allowing us to raise an
|
||||
# UnrewindableBodyError, instead of hanging the connection.
|
||||
rewindable = prepared_request._body_position is not None and (
|
||||
"Content-Length" in headers or "Transfer-Encoding" in headers
|
||||
rewindable = (
|
||||
prepared_request._body_position is not None and
|
||||
('Content-Length' in headers or 'Transfer-Encoding' in headers)
|
||||
)
|
||||
|
||||
# Attempt to rewind consumed file-like object.
|
||||
@@ -262,6 +200,7 @@ class SessionRedirectMixin:
|
||||
if yield_requests:
|
||||
yield req
|
||||
else:
|
||||
|
||||
resp = self.send(
|
||||
req,
|
||||
stream=stream,
|
||||
@@ -270,7 +209,7 @@ class SessionRedirectMixin:
|
||||
cert=cert,
|
||||
proxies=proxies,
|
||||
allow_redirects=False,
|
||||
**adapter_kwargs,
|
||||
**adapter_kwargs
|
||||
)
|
||||
|
||||
extract_cookies_to_jar(self.cookies, prepared_request, resp.raw)
|
||||
@@ -287,18 +226,22 @@ class SessionRedirectMixin:
|
||||
headers = prepared_request.headers
|
||||
url = prepared_request.url
|
||||
|
||||
if "Authorization" in headers and self.should_strip_auth(
|
||||
response.request.url, url
|
||||
):
|
||||
if 'Authorization' in headers:
|
||||
# If we get redirected to a new host, we should strip out any
|
||||
# authentication headers.
|
||||
del headers["Authorization"]
|
||||
original_parsed = urlparse(response.request.url)
|
||||
redirect_parsed = urlparse(url)
|
||||
|
||||
if (original_parsed.hostname != redirect_parsed.hostname):
|
||||
del headers['Authorization']
|
||||
|
||||
# .netrc might have more auth for us on our new host.
|
||||
new_auth = get_netrc_auth(url) if self.trust_env else None
|
||||
if new_auth is not None:
|
||||
prepared_request.prepare_auth(new_auth)
|
||||
|
||||
return
|
||||
|
||||
def rebuild_proxies(self, prepared_request, proxies):
|
||||
"""This method re-evaluates the proxy configuration by considering the
|
||||
environment variables. If we are redirected to a URL covered by
|
||||
@@ -311,22 +254,32 @@ class SessionRedirectMixin:
|
||||
|
||||
:rtype: dict
|
||||
"""
|
||||
proxies = proxies if proxies is not None else {}
|
||||
headers = prepared_request.headers
|
||||
scheme = urlparse(prepared_request.url).scheme
|
||||
new_proxies = resolve_proxies(prepared_request, proxies, self.trust_env)
|
||||
url = prepared_request.url
|
||||
scheme = urlparse(url).scheme
|
||||
new_proxies = proxies.copy()
|
||||
no_proxy = proxies.get('no_proxy')
|
||||
|
||||
if "Proxy-Authorization" in headers:
|
||||
del headers["Proxy-Authorization"]
|
||||
bypass_proxy = should_bypass_proxies(url, no_proxy=no_proxy)
|
||||
if self.trust_env and not bypass_proxy:
|
||||
environ_proxies = get_environ_proxies(url, no_proxy=no_proxy)
|
||||
|
||||
proxy = environ_proxies.get(scheme, environ_proxies.get('all'))
|
||||
|
||||
if proxy:
|
||||
new_proxies.setdefault(scheme, proxy)
|
||||
|
||||
if 'Proxy-Authorization' in headers:
|
||||
del headers['Proxy-Authorization']
|
||||
|
||||
try:
|
||||
username, password = get_auth_from_url(new_proxies[scheme])
|
||||
except KeyError:
|
||||
username, password = None, None
|
||||
|
||||
# urllib3 handles proxy authorization for us in the standard adapter.
|
||||
# Avoid appending this to TLS tunneled requests where it may be leaked.
|
||||
if not scheme.startswith("https") and username and password:
|
||||
headers["Proxy-Authorization"] = _basic_auth_str(username, password)
|
||||
if username and password:
|
||||
headers['Proxy-Authorization'] = _basic_auth_str(username, password)
|
||||
|
||||
return new_proxies
|
||||
|
||||
@@ -336,19 +289,19 @@ class SessionRedirectMixin:
|
||||
"""
|
||||
method = prepared_request.method
|
||||
|
||||
# https://tools.ietf.org/html/rfc7231#section-6.4.4
|
||||
if response.status_code == codes.see_other and method != "HEAD":
|
||||
method = "GET"
|
||||
# http://tools.ietf.org/html/rfc7231#section-6.4.4
|
||||
if response.status_code == codes.see_other and method != 'HEAD':
|
||||
method = 'GET'
|
||||
|
||||
# Do what the browsers do, despite standards...
|
||||
# First, turn 302s into GETs.
|
||||
if response.status_code == codes.found and method != "HEAD":
|
||||
method = "GET"
|
||||
if response.status_code == codes.found and method != 'HEAD':
|
||||
method = 'GET'
|
||||
|
||||
# Second, if a POST is responded to with a 301, turn it into a GET.
|
||||
# This bizarre behaviour is explained in Issue 1704.
|
||||
if response.status_code == codes.moved and method == "POST":
|
||||
method = "GET"
|
||||
if response.status_code == codes.moved and method == 'POST':
|
||||
method = 'GET'
|
||||
|
||||
prepared_request.method = method
|
||||
|
||||
@@ -362,32 +315,24 @@ class Session(SessionRedirectMixin):
|
||||
|
||||
>>> import requests
|
||||
>>> s = requests.Session()
|
||||
>>> s.get('https://httpbin.org/get')
|
||||
>>> s.get('http://httpbin.org/get')
|
||||
<Response [200]>
|
||||
|
||||
Or as a context manager::
|
||||
|
||||
>>> with requests.Session() as s:
|
||||
... s.get('https://httpbin.org/get')
|
||||
>>> s.get('http://httpbin.org/get')
|
||||
<Response [200]>
|
||||
"""
|
||||
|
||||
__attrs__ = [
|
||||
"headers",
|
||||
"cookies",
|
||||
"auth",
|
||||
"proxies",
|
||||
"hooks",
|
||||
"params",
|
||||
"verify",
|
||||
"cert",
|
||||
"adapters",
|
||||
"stream",
|
||||
"trust_env",
|
||||
"max_redirects",
|
||||
'headers', 'cookies', 'auth', 'proxies', 'hooks', 'params', 'verify',
|
||||
'cert', 'prefetch', 'adapters', 'stream', 'trust_env',
|
||||
'max_redirects',
|
||||
]
|
||||
|
||||
def __init__(self):
|
||||
|
||||
#: A case-insensitive dictionary of headers to be sent on each
|
||||
#: :class:`Request <Request>` sent from this
|
||||
#: :class:`Session <Session>`.
|
||||
@@ -414,13 +359,6 @@ class Session(SessionRedirectMixin):
|
||||
self.stream = False
|
||||
|
||||
#: SSL Verification default.
|
||||
#: Defaults to `True`, requiring requests to verify the TLS certificate at the
|
||||
#: remote end.
|
||||
#: If verify is set to `False`, requests will accept any TLS certificate
|
||||
#: presented by the server, and will ignore hostname mismatches and/or
|
||||
#: expired certificates, which will make your application vulnerable to
|
||||
#: man-in-the-middle (MitM) attacks.
|
||||
#: Only set this to `False` for testing.
|
||||
self.verify = True
|
||||
|
||||
#: SSL client certificate default, if String, path to ssl client
|
||||
@@ -445,8 +383,8 @@ class Session(SessionRedirectMixin):
|
||||
|
||||
# Default connection adapters.
|
||||
self.adapters = OrderedDict()
|
||||
self.mount("https://", HTTPAdapter())
|
||||
self.mount("http://", HTTPAdapter())
|
||||
self.mount('https://', HTTPAdapter())
|
||||
self.mount('http://', HTTPAdapter())
|
||||
|
||||
def __enter__(self):
|
||||
return self
|
||||
@@ -472,8 +410,7 @@ class Session(SessionRedirectMixin):
|
||||
|
||||
# Merge with session cookies
|
||||
merged_cookies = merge_cookies(
|
||||
merge_cookies(RequestsCookieJar(), self.cookies), cookies
|
||||
)
|
||||
merge_cookies(RequestsCookieJar(), self.cookies), cookies)
|
||||
|
||||
# Set environment's basic authentication if not explicitly set.
|
||||
auth = request.auth
|
||||
@@ -487,9 +424,7 @@ class Session(SessionRedirectMixin):
|
||||
files=request.files,
|
||||
data=request.data,
|
||||
json=request.json,
|
||||
headers=merge_setting(
|
||||
request.headers, self.headers, dict_class=CaseInsensitiveDict
|
||||
),
|
||||
headers=merge_setting(request.headers, self.headers, dict_class=CaseInsensitiveDict),
|
||||
params=merge_setting(request.params, self.params),
|
||||
auth=merge_setting(auth, self.auth),
|
||||
cookies=merged_cookies,
|
||||
@@ -497,10 +432,7 @@ class Session(SessionRedirectMixin):
|
||||
)
|
||||
return p
|
||||
|
||||
def request(
|
||||
self,
|
||||
method,
|
||||
url,
|
||||
def request(self, method, url,
|
||||
params=None,
|
||||
data=None,
|
||||
headers=None,
|
||||
@@ -514,8 +446,7 @@ class Session(SessionRedirectMixin):
|
||||
stream=None,
|
||||
verify=None,
|
||||
cert=None,
|
||||
json=None,
|
||||
):
|
||||
json=None):
|
||||
"""Constructs a :class:`Request <Request>`, prepares it and sends it.
|
||||
Returns :class:`Response <Response>` object.
|
||||
|
||||
@@ -523,8 +454,8 @@ class Session(SessionRedirectMixin):
|
||||
:param url: URL for the new :class:`Request` object.
|
||||
:param params: (optional) Dictionary or bytes to be sent in the query
|
||||
string for the :class:`Request`.
|
||||
:param data: (optional) Dictionary, list of tuples, bytes, or file-like
|
||||
object to send in the body of the :class:`Request`.
|
||||
:param data: (optional) Dictionary, bytes, or file-like object to send
|
||||
in the body of the :class:`Request`.
|
||||
:param json: (optional) json to send in the body of the
|
||||
:class:`Request`.
|
||||
:param headers: (optional) Dictionary of HTTP Headers to send with the
|
||||
@@ -543,34 +474,27 @@ class Session(SessionRedirectMixin):
|
||||
:type allow_redirects: bool
|
||||
:param proxies: (optional) Dictionary mapping protocol or protocol and
|
||||
hostname to the URL of the proxy.
|
||||
:param hooks: (optional) Dictionary mapping hook name to one event or
|
||||
list of events, event must be callable.
|
||||
:param stream: (optional) whether to immediately download the response
|
||||
content. Defaults to ``False``.
|
||||
:param verify: (optional) Either a boolean, in which case it controls whether we verify
|
||||
the server's TLS certificate, or a string, in which case it must be a path
|
||||
to a CA bundle to use. Defaults to ``True``. When set to
|
||||
``False``, requests will accept any TLS certificate presented by
|
||||
the server, and will ignore hostname mismatches and/or expired
|
||||
certificates, which will make your application vulnerable to
|
||||
man-in-the-middle (MitM) attacks. Setting verify to ``False``
|
||||
may be useful during local development or testing.
|
||||
to a CA bundle to use. Defaults to ``True``.
|
||||
:param cert: (optional) if String, path to ssl client cert file (.pem).
|
||||
If Tuple, ('cert', 'key') pair.
|
||||
:rtype: requests.Response
|
||||
"""
|
||||
# Create the Request.
|
||||
req = Request(
|
||||
method=method.upper(),
|
||||
url=url,
|
||||
headers=headers,
|
||||
files=files,
|
||||
data=data or {},
|
||||
json=json,
|
||||
params=params or {},
|
||||
auth=auth,
|
||||
cookies=cookies,
|
||||
hooks=hooks,
|
||||
method = method.upper(),
|
||||
url = url,
|
||||
headers = headers,
|
||||
files = files,
|
||||
data = data or {},
|
||||
json = json,
|
||||
params = params or {},
|
||||
auth = auth,
|
||||
cookies = cookies,
|
||||
hooks = hooks,
|
||||
)
|
||||
prep = self.prepare_request(req)
|
||||
|
||||
@@ -582,8 +506,8 @@ class Session(SessionRedirectMixin):
|
||||
|
||||
# Send the request.
|
||||
send_kwargs = {
|
||||
"timeout": timeout,
|
||||
"allow_redirects": allow_redirects,
|
||||
'timeout': timeout,
|
||||
'allow_redirects': allow_redirects,
|
||||
}
|
||||
send_kwargs.update(settings)
|
||||
resp = self.send(prep, **send_kwargs)
|
||||
@@ -598,8 +522,8 @@ class Session(SessionRedirectMixin):
|
||||
:rtype: requests.Response
|
||||
"""
|
||||
|
||||
kwargs.setdefault("allow_redirects", True)
|
||||
return self.request("GET", url, **kwargs)
|
||||
kwargs.setdefault('allow_redirects', True)
|
||||
return self.request('GET', url, **kwargs)
|
||||
|
||||
def options(self, url, **kwargs):
|
||||
r"""Sends a OPTIONS request. Returns :class:`Response` object.
|
||||
@@ -609,8 +533,8 @@ class Session(SessionRedirectMixin):
|
||||
:rtype: requests.Response
|
||||
"""
|
||||
|
||||
kwargs.setdefault("allow_redirects", True)
|
||||
return self.request("OPTIONS", url, **kwargs)
|
||||
kwargs.setdefault('allow_redirects', True)
|
||||
return self.request('OPTIONS', url, **kwargs)
|
||||
|
||||
def head(self, url, **kwargs):
|
||||
r"""Sends a HEAD request. Returns :class:`Response` object.
|
||||
@@ -620,45 +544,42 @@ class Session(SessionRedirectMixin):
|
||||
:rtype: requests.Response
|
||||
"""
|
||||
|
||||
kwargs.setdefault("allow_redirects", False)
|
||||
return self.request("HEAD", url, **kwargs)
|
||||
kwargs.setdefault('allow_redirects', False)
|
||||
return self.request('HEAD', url, **kwargs)
|
||||
|
||||
def post(self, url, data=None, json=None, **kwargs):
|
||||
r"""Sends a POST request. Returns :class:`Response` object.
|
||||
|
||||
:param url: URL for the new :class:`Request` object.
|
||||
:param data: (optional) Dictionary, list of tuples, bytes, or file-like
|
||||
object to send in the body of the :class:`Request`.
|
||||
:param data: (optional) Dictionary, bytes, or file-like object to send in the body of the :class:`Request`.
|
||||
:param json: (optional) json to send in the body of the :class:`Request`.
|
||||
:param \*\*kwargs: Optional arguments that ``request`` takes.
|
||||
:rtype: requests.Response
|
||||
"""
|
||||
|
||||
return self.request("POST", url, data=data, json=json, **kwargs)
|
||||
return self.request('POST', url, data=data, json=json, **kwargs)
|
||||
|
||||
def put(self, url, data=None, **kwargs):
|
||||
r"""Sends a PUT request. Returns :class:`Response` object.
|
||||
|
||||
:param url: URL for the new :class:`Request` object.
|
||||
:param data: (optional) Dictionary, list of tuples, bytes, or file-like
|
||||
object to send in the body of the :class:`Request`.
|
||||
:param data: (optional) Dictionary, bytes, or file-like object to send in the body of the :class:`Request`.
|
||||
:param \*\*kwargs: Optional arguments that ``request`` takes.
|
||||
:rtype: requests.Response
|
||||
"""
|
||||
|
||||
return self.request("PUT", url, data=data, **kwargs)
|
||||
return self.request('PUT', url, data=data, **kwargs)
|
||||
|
||||
def patch(self, url, data=None, **kwargs):
|
||||
r"""Sends a PATCH request. Returns :class:`Response` object.
|
||||
|
||||
:param url: URL for the new :class:`Request` object.
|
||||
:param data: (optional) Dictionary, list of tuples, bytes, or file-like
|
||||
object to send in the body of the :class:`Request`.
|
||||
:param data: (optional) Dictionary, bytes, or file-like object to send in the body of the :class:`Request`.
|
||||
:param \*\*kwargs: Optional arguments that ``request`` takes.
|
||||
:rtype: requests.Response
|
||||
"""
|
||||
|
||||
return self.request("PATCH", url, data=data, **kwargs)
|
||||
return self.request('PATCH', url, data=data, **kwargs)
|
||||
|
||||
def delete(self, url, **kwargs):
|
||||
r"""Sends a DELETE request. Returns :class:`Response` object.
|
||||
@@ -668,7 +589,7 @@ class Session(SessionRedirectMixin):
|
||||
:rtype: requests.Response
|
||||
"""
|
||||
|
||||
return self.request("DELETE", url, **kwargs)
|
||||
return self.request('DELETE', url, **kwargs)
|
||||
|
||||
def send(self, request, **kwargs):
|
||||
"""Send a given PreparedRequest.
|
||||
@@ -677,20 +598,19 @@ class Session(SessionRedirectMixin):
|
||||
"""
|
||||
# Set defaults that the hooks can utilize to ensure they always have
|
||||
# the correct parameters to reproduce the previous request.
|
||||
kwargs.setdefault("stream", self.stream)
|
||||
kwargs.setdefault("verify", self.verify)
|
||||
kwargs.setdefault("cert", self.cert)
|
||||
if "proxies" not in kwargs:
|
||||
kwargs["proxies"] = resolve_proxies(request, self.proxies, self.trust_env)
|
||||
kwargs.setdefault('stream', self.stream)
|
||||
kwargs.setdefault('verify', self.verify)
|
||||
kwargs.setdefault('cert', self.cert)
|
||||
kwargs.setdefault('proxies', self.proxies)
|
||||
|
||||
# It's possible that users might accidentally send a Request object.
|
||||
# Guard against that specific failure case.
|
||||
if isinstance(request, Request):
|
||||
raise ValueError("You can only send PreparedRequests.")
|
||||
raise ValueError('You can only send PreparedRequests.')
|
||||
|
||||
# Set up variables needed for resolve_redirects and dispatching of hooks
|
||||
allow_redirects = kwargs.pop("allow_redirects", True)
|
||||
stream = kwargs.get("stream")
|
||||
allow_redirects = kwargs.pop('allow_redirects', True)
|
||||
stream = kwargs.get('stream')
|
||||
hooks = request.hooks
|
||||
|
||||
# Get the appropriate adapter to use
|
||||
@@ -707,23 +627,22 @@ class Session(SessionRedirectMixin):
|
||||
r.elapsed = timedelta(seconds=elapsed)
|
||||
|
||||
# Response manipulation hooks
|
||||
r = dispatch_hook("response", hooks, r, **kwargs)
|
||||
r = dispatch_hook('response', hooks, r, **kwargs)
|
||||
|
||||
# Persist cookies
|
||||
if r.history:
|
||||
|
||||
# If the hooks create history then we want those cookies too
|
||||
for resp in r.history:
|
||||
extract_cookies_to_jar(self.cookies, resp.request, resp.raw)
|
||||
|
||||
extract_cookies_to_jar(self.cookies, request, r.raw)
|
||||
|
||||
# Redirect resolving generator.
|
||||
gen = self.resolve_redirects(r, request, **kwargs)
|
||||
|
||||
# Resolve redirects if allowed.
|
||||
if allow_redirects:
|
||||
# Redirect resolving generator.
|
||||
gen = self.resolve_redirects(r, request, **kwargs)
|
||||
history = [resp for resp in gen]
|
||||
else:
|
||||
history = []
|
||||
history = [resp for resp in gen] if allow_redirects else []
|
||||
|
||||
# Shuffle things around if there's history.
|
||||
if history:
|
||||
@@ -736,9 +655,7 @@ class Session(SessionRedirectMixin):
|
||||
# If redirects aren't being followed, store the response on the Request for Response.next().
|
||||
if not allow_redirects:
|
||||
try:
|
||||
r._next = next(
|
||||
self.resolve_redirects(r, request, yield_requests=True, **kwargs)
|
||||
)
|
||||
r._next = next(self.resolve_redirects(r, request, yield_requests=True, **kwargs))
|
||||
except StopIteration:
|
||||
pass
|
||||
|
||||
@@ -756,19 +673,16 @@ class Session(SessionRedirectMixin):
|
||||
# Gather clues from the surrounding environment.
|
||||
if self.trust_env:
|
||||
# Set environment's proxies.
|
||||
no_proxy = proxies.get("no_proxy") if proxies is not None else None
|
||||
no_proxy = proxies.get('no_proxy') if proxies is not None else None
|
||||
env_proxies = get_environ_proxies(url, no_proxy=no_proxy)
|
||||
for k, v in env_proxies.items():
|
||||
for (k, v) in env_proxies.items():
|
||||
proxies.setdefault(k, v)
|
||||
|
||||
# Look for requests environment configuration
|
||||
# and be compatible with cURL.
|
||||
# Look for requests environment configuration and be compatible
|
||||
# with cURL.
|
||||
if verify is True or verify is None:
|
||||
verify = (
|
||||
os.environ.get("REQUESTS_CA_BUNDLE")
|
||||
or os.environ.get("CURL_CA_BUNDLE")
|
||||
or verify
|
||||
)
|
||||
verify = (os.environ.get('REQUESTS_CA_BUNDLE') or
|
||||
os.environ.get('CURL_CA_BUNDLE'))
|
||||
|
||||
# Merge all the kwargs.
|
||||
proxies = merge_setting(proxies, self.proxies)
|
||||
@@ -776,7 +690,8 @@ class Session(SessionRedirectMixin):
|
||||
verify = merge_setting(verify, self.verify)
|
||||
cert = merge_setting(cert, self.cert)
|
||||
|
||||
return {"proxies": proxies, "stream": stream, "verify": verify, "cert": cert}
|
||||
return {'verify': verify, 'proxies': proxies, 'stream': stream,
|
||||
'cert': cert}
|
||||
|
||||
def get_adapter(self, url):
|
||||
"""
|
||||
@@ -784,12 +699,13 @@ class Session(SessionRedirectMixin):
|
||||
|
||||
:rtype: requests.adapters.BaseAdapter
|
||||
"""
|
||||
for prefix, adapter in self.adapters.items():
|
||||
if url.lower().startswith(prefix.lower()):
|
||||
for (prefix, adapter) in self.adapters.items():
|
||||
|
||||
if url.lower().startswith(prefix):
|
||||
return adapter
|
||||
|
||||
# Nothing matches :-/
|
||||
raise InvalidSchema(f"No connection adapters were found for {url!r}")
|
||||
raise InvalidSchema("No connection adapters were found for '%s'" % url)
|
||||
|
||||
def close(self):
|
||||
"""Closes all adapters and as such the session"""
|
||||
@@ -799,7 +715,7 @@ class Session(SessionRedirectMixin):
|
||||
def mount(self, prefix, adapter):
|
||||
"""Registers a connection adapter to a prefix.
|
||||
|
||||
Adapters are sorted in descending order by prefix length.
|
||||
Adapters are sorted in descending order by key length.
|
||||
"""
|
||||
self.adapters[prefix] = adapter
|
||||
keys_to_move = [k for k in self.adapters if len(k) < len(prefix)]
|
||||
@@ -808,7 +724,7 @@ class Session(SessionRedirectMixin):
|
||||
self.adapters[key] = self.adapters.pop(key)
|
||||
|
||||
def __getstate__(self):
|
||||
state = {attr: getattr(self, attr, None) for attr in self.__attrs__}
|
||||
state = dict((attr, getattr(self, attr, None)) for attr in self.__attrs__)
|
||||
return state
|
||||
|
||||
def __setstate__(self, state):
|
||||
@@ -820,12 +736,7 @@ def session():
|
||||
"""
|
||||
Returns a :class:`Session` for context-management.
|
||||
|
||||
.. deprecated:: 1.0.0
|
||||
|
||||
This method has been deprecated since version 1.0.0 and is only kept for
|
||||
backwards compatibility. New code should use :class:`~requests.sessions.Session`
|
||||
to create a session. This may be removed at a future date.
|
||||
|
||||
:rtype: Session
|
||||
"""
|
||||
|
||||
return Session()
|
||||
91
requests/status_codes.py
Normal file
@@ -0,0 +1,91 @@
|
||||
# -*- coding: utf-8 -*-
|
||||
|
||||
from .structures import LookupDict
|
||||
|
||||
_codes = {
|
||||
|
||||
# Informational.
|
||||
100: ('continue',),
|
||||
101: ('switching_protocols',),
|
||||
102: ('processing',),
|
||||
103: ('checkpoint',),
|
||||
122: ('uri_too_long', 'request_uri_too_long'),
|
||||
200: ('ok', 'okay', 'all_ok', 'all_okay', 'all_good', '\\o/', '✓'),
|
||||
201: ('created',),
|
||||
202: ('accepted',),
|
||||
203: ('non_authoritative_info', 'non_authoritative_information'),
|
||||
204: ('no_content',),
|
||||
205: ('reset_content', 'reset'),
|
||||
206: ('partial_content', 'partial'),
|
||||
207: ('multi_status', 'multiple_status', 'multi_stati', 'multiple_stati'),
|
||||
208: ('already_reported',),
|
||||
226: ('im_used',),
|
||||
|
||||
# Redirection.
|
||||
300: ('multiple_choices',),
|
||||
301: ('moved_permanently', 'moved', '\\o-'),
|
||||
302: ('found',),
|
||||
303: ('see_other', 'other'),
|
||||
304: ('not_modified',),
|
||||
305: ('use_proxy',),
|
||||
306: ('switch_proxy',),
|
||||
307: ('temporary_redirect', 'temporary_moved', 'temporary'),
|
||||
308: ('permanent_redirect',
|
||||
'resume_incomplete', 'resume',), # These 2 to be removed in 3.0
|
||||
|
||||
# Client Error.
|
||||
400: ('bad_request', 'bad'),
|
||||
401: ('unauthorized',),
|
||||
402: ('payment_required', 'payment'),
|
||||
403: ('forbidden',),
|
||||
404: ('not_found', '-o-'),
|
||||
405: ('method_not_allowed', 'not_allowed'),
|
||||
406: ('not_acceptable',),
|
||||
407: ('proxy_authentication_required', 'proxy_auth', 'proxy_authentication'),
|
||||
408: ('request_timeout', 'timeout'),
|
||||
409: ('conflict',),
|
||||
410: ('gone',),
|
||||
411: ('length_required',),
|
||||
412: ('precondition_failed', 'precondition'),
|
||||
413: ('request_entity_too_large',),
|
||||
414: ('request_uri_too_large',),
|
||||
415: ('unsupported_media_type', 'unsupported_media', 'media_type'),
|
||||
416: ('requested_range_not_satisfiable', 'requested_range', 'range_not_satisfiable'),
|
||||
417: ('expectation_failed',),
|
||||
418: ('im_a_teapot', 'teapot', 'i_am_a_teapot'),
|
||||
421: ('misdirected_request',),
|
||||
422: ('unprocessable_entity', 'unprocessable'),
|
||||
423: ('locked',),
|
||||
424: ('failed_dependency', 'dependency'),
|
||||
425: ('unordered_collection', 'unordered'),
|
||||
426: ('upgrade_required', 'upgrade'),
|
||||
428: ('precondition_required', 'precondition'),
|
||||
429: ('too_many_requests', 'too_many'),
|
||||
431: ('header_fields_too_large', 'fields_too_large'),
|
||||
444: ('no_response', 'none'),
|
||||
449: ('retry_with', 'retry'),
|
||||
450: ('blocked_by_windows_parental_controls', 'parental_controls'),
|
||||
451: ('unavailable_for_legal_reasons', 'legal_reasons'),
|
||||
499: ('client_closed_request',),
|
||||
|
||||
# Server Error.
|
||||
500: ('internal_server_error', 'server_error', '/o\\', '✗'),
|
||||
501: ('not_implemented',),
|
||||
502: ('bad_gateway',),
|
||||
503: ('service_unavailable', 'unavailable'),
|
||||
504: ('gateway_timeout',),
|
||||
505: ('http_version_not_supported', 'http_version'),
|
||||
506: ('variant_also_negotiates',),
|
||||
507: ('insufficient_storage',),
|
||||
509: ('bandwidth_limit_exceeded', 'bandwidth'),
|
||||
510: ('not_extended',),
|
||||
511: ('network_authentication_required', 'network_auth', 'network_authentication'),
|
||||
}
|
||||
|
||||
codes = LookupDict(name='status_codes')
|
||||
|
||||
for code, titles in _codes.items():
|
||||
for title in titles:
|
||||
setattr(codes, title, code)
|
||||
if not title.startswith(('\\', '/')):
|
||||
setattr(codes, title.upper(), code)
|
||||
@@ -1,3 +1,5 @@
|
||||
# -*- coding: utf-8 -*-
|
||||
|
||||
"""
|
||||
requests.structures
|
||||
~~~~~~~~~~~~~~~~~~~
|
||||
@@ -5,16 +7,16 @@ requests.structures
|
||||
Data structures that power Requests.
|
||||
"""
|
||||
|
||||
from collections import OrderedDict
|
||||
import collections
|
||||
|
||||
from .compat import Mapping, MutableMapping
|
||||
from .compat import OrderedDict
|
||||
|
||||
|
||||
class CaseInsensitiveDict(MutableMapping):
|
||||
class CaseInsensitiveDict(collections.MutableMapping):
|
||||
"""A case-insensitive ``dict``-like object.
|
||||
|
||||
Implements all methods and operations of
|
||||
``MutableMapping`` as well as dict's ``copy``. Also
|
||||
``collections.MutableMapping`` as well as dict's ``copy``. Also
|
||||
provides ``lower_items``.
|
||||
|
||||
All keys are expected to be strings. The structure remembers the
|
||||
@@ -62,10 +64,14 @@ class CaseInsensitiveDict(MutableMapping):
|
||||
|
||||
def lower_items(self):
|
||||
"""Like iteritems(), but with all lowercase keys."""
|
||||
return ((lowerkey, keyval[1]) for (lowerkey, keyval) in self._store.items())
|
||||
return (
|
||||
(lowerkey, keyval[1])
|
||||
for (lowerkey, keyval)
|
||||
in self._store.items()
|
||||
)
|
||||
|
||||
def __eq__(self, other):
|
||||
if isinstance(other, Mapping):
|
||||
if isinstance(other, collections.Mapping):
|
||||
other = CaseInsensitiveDict(other)
|
||||
else:
|
||||
return NotImplemented
|
||||
@@ -85,10 +91,10 @@ class LookupDict(dict):
|
||||
|
||||
def __init__(self, name=None):
|
||||
self.name = name
|
||||
super().__init__()
|
||||
super(LookupDict, self).__init__()
|
||||
|
||||
def __repr__(self):
|
||||
return f"<lookup '{self.name}'>"
|
||||
return '<lookup \'%s\'>' % (self.name)
|
||||
|
||||
def __getitem__(self, key):
|
||||
# We allow fall-through here, so values default to None
|
||||
@@ -1,7 +0,0 @@
|
||||
-e .[socks]
|
||||
pytest>=2.8.0,<9
|
||||
pytest-cov
|
||||
pytest-httpbin==2.0.0
|
||||
httpbin~=0.10.0
|
||||
trustme
|
||||
wheel
|
||||
16
requirements.txt
Normal file
@@ -0,0 +1,16 @@
|
||||
-e .[socks]
|
||||
pytest>=2.8.0
|
||||
codecov
|
||||
pytest-httpbin==0.0.7
|
||||
pytest-mock
|
||||
pytest-cov
|
||||
pytest-xdist
|
||||
alabaster
|
||||
readme_renderer
|
||||
Sphinx<=1.5.5
|
||||
PySocks
|
||||
setuptools>=18.5
|
||||
docutils
|
||||
flake8
|
||||
tox
|
||||
detox
|
||||
19
setup.cfg
@@ -1,17 +1,2 @@
|
||||
[metadata]
|
||||
license_file = LICENSE
|
||||
provides-extra =
|
||||
socks
|
||||
use_chardet_on_py3
|
||||
requires-dist =
|
||||
certifi>=2017.4.17
|
||||
charset_normalizer>=2,<4
|
||||
idna>=2.5,<4
|
||||
urllib3>=1.21.1,<3
|
||||
|
||||
[flake8]
|
||||
ignore = E203, E501, W503
|
||||
per-file-ignores =
|
||||
src/requests/__init__.py:E402, F401
|
||||
src/requests/compat.py:E402, F401
|
||||
tests/compat.py:F401
|
||||
[bdist_wheel]
|
||||
universal = 1
|
||||
|
||||
142
setup.py
@@ -1,44 +1,23 @@
|
||||
#!/usr/bin/env python
|
||||
|
||||
import os
|
||||
import re
|
||||
import sys
|
||||
|
||||
from codecs import open
|
||||
|
||||
from setuptools import setup
|
||||
from setuptools.command.test import test as TestCommand
|
||||
from multiprocessing import cpu_count
|
||||
|
||||
CURRENT_PYTHON = sys.version_info[:2]
|
||||
REQUIRED_PYTHON = (3, 8)
|
||||
|
||||
if CURRENT_PYTHON < REQUIRED_PYTHON:
|
||||
sys.stderr.write(
|
||||
"""
|
||||
==========================
|
||||
Unsupported Python version
|
||||
==========================
|
||||
This version of Requests requires at least Python {}.{}, but
|
||||
you're trying to install it on Python {}.{}. To resolve this,
|
||||
consider upgrading to a supported Python version.
|
||||
|
||||
If you can't upgrade your Python version, you'll need to
|
||||
pin to an older version of Requests (<2.32.0).
|
||||
""".format(
|
||||
*(REQUIRED_PYTHON + CURRENT_PYTHON)
|
||||
)
|
||||
)
|
||||
sys.exit(1)
|
||||
|
||||
here = os.path.abspath(os.path.dirname(__file__))
|
||||
|
||||
class PyTest(TestCommand):
|
||||
user_options = [("pytest-args=", "a", "Arguments to pass into py.test")]
|
||||
user_options = [('pytest-args=', 'a', "Arguments to pass into py.test")]
|
||||
|
||||
def initialize_options(self):
|
||||
TestCommand.initialize_options(self)
|
||||
try:
|
||||
from multiprocessing import cpu_count
|
||||
|
||||
self.pytest_args = ["-n", str(cpu_count()), "--boxed"]
|
||||
except (ImportError, NotImplementedError):
|
||||
self.pytest_args = ["-n", "1", "--boxed"]
|
||||
self.pytest_args = ['-n', str(cpu_count()), '--boxed']
|
||||
|
||||
def finalize_options(self):
|
||||
TestCommand.finalize_options(self)
|
||||
@@ -51,82 +30,69 @@ class PyTest(TestCommand):
|
||||
errno = pytest.main(self.pytest_args)
|
||||
sys.exit(errno)
|
||||
|
||||
|
||||
# 'setup.py publish' shortcut.
|
||||
if sys.argv[-1] == "publish":
|
||||
os.system("python setup.py sdist bdist_wheel")
|
||||
os.system("twine upload dist/*")
|
||||
if sys.argv[-1] == 'publish':
|
||||
os.system('python setup.py sdist bdist_wheel')
|
||||
os.system('twine upload dist/*')
|
||||
sys.exit()
|
||||
|
||||
packages = ['requests']
|
||||
|
||||
requires = [
|
||||
"charset_normalizer>=2,<4",
|
||||
"idna>=2.5,<4",
|
||||
"urllib3>=1.21.1,<3",
|
||||
"certifi>=2017.4.17",
|
||||
]
|
||||
test_requirements = [
|
||||
"pytest-httpbin==2.0.0",
|
||||
"pytest-cov",
|
||||
"pytest-mock",
|
||||
"pytest-xdist",
|
||||
"PySocks>=1.5.6, !=1.5.7",
|
||||
"pytest>=3",
|
||||
'chardet>=3.0.2,<3.1.0',
|
||||
'idna>=2.5,<2.6',
|
||||
'urllib3>=1.21.1,<1.22',
|
||||
'certifi>=2017.4.17'
|
||||
|
||||
]
|
||||
test_requirements = ['pytest-httpbin==0.0.7', 'pytest-cov', 'pytest-mock', 'pytest-xdist', 'PySocks>=1.5.6, !=1.5.7', 'pytest>=2.8.0']
|
||||
|
||||
about = {}
|
||||
here = os.path.abspath(os.path.dirname(__file__))
|
||||
with open(os.path.join(here, "src", "requests", "__version__.py"), "r", "utf-8") as f:
|
||||
with open(os.path.join(here, 'requests', '__version__.py'), 'r', 'utf-8') as f:
|
||||
exec(f.read(), about)
|
||||
|
||||
with open("README.md", "r", "utf-8") as f:
|
||||
with open('README.rst', 'r', 'utf-8') as f:
|
||||
readme = f.read()
|
||||
with open('HISTORY.rst', 'r', 'utf-8') as f:
|
||||
history = f.read()
|
||||
|
||||
setup(
|
||||
name=about["__title__"],
|
||||
version=about["__version__"],
|
||||
description=about["__description__"],
|
||||
long_description=readme,
|
||||
long_description_content_type="text/markdown",
|
||||
author=about["__author__"],
|
||||
author_email=about["__author_email__"],
|
||||
url=about["__url__"],
|
||||
packages=["requests"],
|
||||
package_data={"": ["LICENSE", "NOTICE"]},
|
||||
package_dir={"": "src"},
|
||||
name=about['__title__'],
|
||||
version=about['__version__'],
|
||||
description=about['__description__'],
|
||||
long_description=readme + '\n\n' + history,
|
||||
author=about['__author__'],
|
||||
author_email=about['__author_email__'],
|
||||
url=about['__url__'],
|
||||
packages=packages,
|
||||
package_data={'': ['LICENSE', 'NOTICE'], 'requests': ['*.pem']},
|
||||
package_dir={'requests': 'requests'},
|
||||
include_package_data=True,
|
||||
python_requires=">=3.8",
|
||||
install_requires=requires,
|
||||
license=about["__license__"],
|
||||
license=about['__license__'],
|
||||
zip_safe=False,
|
||||
classifiers=[
|
||||
"Development Status :: 5 - Production/Stable",
|
||||
"Environment :: Web Environment",
|
||||
"Intended Audience :: Developers",
|
||||
"License :: OSI Approved :: Apache Software License",
|
||||
"Natural Language :: English",
|
||||
"Operating System :: OS Independent",
|
||||
"Programming Language :: Python",
|
||||
"Programming Language :: Python :: 3",
|
||||
"Programming Language :: Python :: 3.8",
|
||||
"Programming Language :: Python :: 3.9",
|
||||
"Programming Language :: Python :: 3.10",
|
||||
"Programming Language :: Python :: 3.11",
|
||||
"Programming Language :: Python :: 3.12",
|
||||
"Programming Language :: Python :: 3 :: Only",
|
||||
"Programming Language :: Python :: Implementation :: CPython",
|
||||
"Programming Language :: Python :: Implementation :: PyPy",
|
||||
"Topic :: Internet :: WWW/HTTP",
|
||||
"Topic :: Software Development :: Libraries",
|
||||
],
|
||||
cmdclass={"test": PyTest},
|
||||
classifiers=(
|
||||
'Development Status :: 5 - Production/Stable',
|
||||
'Intended Audience :: Developers',
|
||||
'Natural Language :: English',
|
||||
'License :: OSI Approved :: Apache Software License',
|
||||
'Programming Language :: Python',
|
||||
'Programming Language :: Python :: 2.6',
|
||||
'Programming Language :: Python :: 2.7',
|
||||
'Programming Language :: Python :: 3',
|
||||
'Programming Language :: Python :: 3.3',
|
||||
'Programming Language :: Python :: 3.4',
|
||||
'Programming Language :: Python :: 3.5',
|
||||
'Programming Language :: Python :: 3.6',
|
||||
'Programming Language :: Python :: Implementation :: CPython',
|
||||
'Programming Language :: Python :: Implementation :: PyPy'
|
||||
),
|
||||
cmdclass={'test': PyTest},
|
||||
tests_require=test_requirements,
|
||||
extras_require={
|
||||
"security": [],
|
||||
"socks": ["PySocks>=1.5.6, !=1.5.7"],
|
||||
"use_chardet_on_py3": ["chardet>=3.0.2,<6"],
|
||||
},
|
||||
project_urls={
|
||||
"Documentation": "https://requests.readthedocs.io",
|
||||
"Source": "https://github.com/psf/requests",
|
||||
'security': ['pyOpenSSL>=0.14', 'cryptography>=1.3.4', 'idna>=2.0.0'],
|
||||
'socks': ['PySocks>=1.5.6, !=1.5.7'],
|
||||
'socks:sys_platform == "win32" and (python_version == "2.7" or python_version == "2.6")': ['win_inet_pton'],
|
||||
},
|
||||
)
|
||||
|
||||
|
||||
@@ -1,184 +0,0 @@
|
||||
# __
|
||||
# /__) _ _ _ _ _/ _
|
||||
# / ( (- (/ (/ (- _) / _)
|
||||
# /
|
||||
|
||||
"""
|
||||
Requests HTTP Library
|
||||
~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
Requests is an HTTP library, written in Python, for human beings.
|
||||
Basic GET usage:
|
||||
|
||||
>>> import requests
|
||||
>>> r = requests.get('https://www.python.org')
|
||||
>>> r.status_code
|
||||
200
|
||||
>>> b'Python is a programming language' in r.content
|
||||
True
|
||||
|
||||
... or POST:
|
||||
|
||||
>>> payload = dict(key1='value1', key2='value2')
|
||||
>>> r = requests.post('https://httpbin.org/post', data=payload)
|
||||
>>> print(r.text)
|
||||
{
|
||||
...
|
||||
"form": {
|
||||
"key1": "value1",
|
||||
"key2": "value2"
|
||||
},
|
||||
...
|
||||
}
|
||||
|
||||
The other HTTP methods are supported - see `requests.api`. Full documentation
|
||||
is at <https://requests.readthedocs.io>.
|
||||
|
||||
:copyright: (c) 2017 by Kenneth Reitz.
|
||||
:license: Apache 2.0, see LICENSE for more details.
|
||||
"""
|
||||
|
||||
import warnings
|
||||
|
||||
import urllib3
|
||||
|
||||
from .exceptions import RequestsDependencyWarning
|
||||
|
||||
try:
|
||||
from charset_normalizer import __version__ as charset_normalizer_version
|
||||
except ImportError:
|
||||
charset_normalizer_version = None
|
||||
|
||||
try:
|
||||
from chardet import __version__ as chardet_version
|
||||
except ImportError:
|
||||
chardet_version = None
|
||||
|
||||
|
||||
def check_compatibility(urllib3_version, chardet_version, charset_normalizer_version):
|
||||
urllib3_version = urllib3_version.split(".")
|
||||
assert urllib3_version != ["dev"] # Verify urllib3 isn't installed from git.
|
||||
|
||||
# Sometimes, urllib3 only reports its version as 16.1.
|
||||
if len(urllib3_version) == 2:
|
||||
urllib3_version.append("0")
|
||||
|
||||
# Check urllib3 for compatibility.
|
||||
major, minor, patch = urllib3_version # noqa: F811
|
||||
major, minor, patch = int(major), int(minor), int(patch)
|
||||
# urllib3 >= 1.21.1
|
||||
assert major >= 1
|
||||
if major == 1:
|
||||
assert minor >= 21
|
||||
|
||||
# Check charset_normalizer for compatibility.
|
||||
if chardet_version:
|
||||
major, minor, patch = chardet_version.split(".")[:3]
|
||||
major, minor, patch = int(major), int(minor), int(patch)
|
||||
# chardet_version >= 3.0.2, < 6.0.0
|
||||
assert (3, 0, 2) <= (major, minor, patch) < (6, 0, 0)
|
||||
elif charset_normalizer_version:
|
||||
major, minor, patch = charset_normalizer_version.split(".")[:3]
|
||||
major, minor, patch = int(major), int(minor), int(patch)
|
||||
# charset_normalizer >= 2.0.0 < 4.0.0
|
||||
assert (2, 0, 0) <= (major, minor, patch) < (4, 0, 0)
|
||||
else:
|
||||
warnings.warn(
|
||||
"Unable to find acceptable character detection dependency "
|
||||
"(chardet or charset_normalizer).",
|
||||
RequestsDependencyWarning,
|
||||
)
|
||||
|
||||
|
||||
def _check_cryptography(cryptography_version):
|
||||
# cryptography < 1.3.4
|
||||
try:
|
||||
cryptography_version = list(map(int, cryptography_version.split(".")))
|
||||
except ValueError:
|
||||
return
|
||||
|
||||
if cryptography_version < [1, 3, 4]:
|
||||
warning = "Old version of cryptography ({}) may cause slowdown.".format(
|
||||
cryptography_version
|
||||
)
|
||||
warnings.warn(warning, RequestsDependencyWarning)
|
||||
|
||||
|
||||
# Check imported dependencies for compatibility.
|
||||
try:
|
||||
check_compatibility(
|
||||
urllib3.__version__, chardet_version, charset_normalizer_version
|
||||
)
|
||||
except (AssertionError, ValueError):
|
||||
warnings.warn(
|
||||
"urllib3 ({}) or chardet ({})/charset_normalizer ({}) doesn't match a supported "
|
||||
"version!".format(
|
||||
urllib3.__version__, chardet_version, charset_normalizer_version
|
||||
),
|
||||
RequestsDependencyWarning,
|
||||
)
|
||||
|
||||
# Attempt to enable urllib3's fallback for SNI support
|
||||
# if the standard library doesn't support SNI or the
|
||||
# 'ssl' library isn't available.
|
||||
try:
|
||||
try:
|
||||
import ssl
|
||||
except ImportError:
|
||||
ssl = None
|
||||
|
||||
if not getattr(ssl, "HAS_SNI", False):
|
||||
from urllib3.contrib import pyopenssl
|
||||
|
||||
pyopenssl.inject_into_urllib3()
|
||||
|
||||
# Check cryptography version
|
||||
from cryptography import __version__ as cryptography_version
|
||||
|
||||
_check_cryptography(cryptography_version)
|
||||
except ImportError:
|
||||
pass
|
||||
|
||||
# urllib3's DependencyWarnings should be silenced.
|
||||
from urllib3.exceptions import DependencyWarning
|
||||
|
||||
warnings.simplefilter("ignore", DependencyWarning)
|
||||
|
||||
# Set default logging handler to avoid "No handler found" warnings.
|
||||
import logging
|
||||
from logging import NullHandler
|
||||
|
||||
from . import packages, utils
|
||||
from .__version__ import (
|
||||
__author__,
|
||||
__author_email__,
|
||||
__build__,
|
||||
__cake__,
|
||||
__copyright__,
|
||||
__description__,
|
||||
__license__,
|
||||
__title__,
|
||||
__url__,
|
||||
__version__,
|
||||
)
|
||||
from .api import delete, get, head, options, patch, post, put, request
|
||||
from .exceptions import (
|
||||
ConnectionError,
|
||||
ConnectTimeout,
|
||||
FileModeWarning,
|
||||
HTTPError,
|
||||
JSONDecodeError,
|
||||
ReadTimeout,
|
||||
RequestException,
|
||||
Timeout,
|
||||
TooManyRedirects,
|
||||
URLRequired,
|
||||
)
|
||||
from .models import PreparedRequest, Request, Response
|
||||
from .sessions import Session, session
|
||||
from .status_codes import codes
|
||||
|
||||
logging.getLogger(__name__).addHandler(NullHandler())
|
||||
|
||||
# FileModeWarnings go off per the default.
|
||||
warnings.simplefilter("default", FileModeWarning, append=True)
|
||||
@@ -1,14 +0,0 @@
|
||||
# .-. .-. .-. . . .-. .-. .-. .-.
|
||||
# |( |- |.| | | |- `-. | `-.
|
||||
# ' ' `-' `-`.`-' `-' `-' ' `-'
|
||||
|
||||
__title__ = "requests"
|
||||
__description__ = "Python HTTP for Humans."
|
||||
__url__ = "https://requests.readthedocs.io"
|
||||
__version__ = "2.32.3"
|
||||
__build__ = 0x023203
|
||||
__author__ = "Kenneth Reitz"
|
||||
__author_email__ = "me@kennethreitz.org"
|
||||
__license__ = "Apache-2.0"
|
||||
__copyright__ = "Copyright Kenneth Reitz"
|
||||
__cake__ = "\u2728 \U0001f370 \u2728"
|
||||
@@ -1,94 +0,0 @@
|
||||
"""
|
||||
requests.compat
|
||||
~~~~~~~~~~~~~~~
|
||||
|
||||
This module previously handled import compatibility issues
|
||||
between Python 2 and Python 3. It remains for backwards
|
||||
compatibility until the next major version.
|
||||
"""
|
||||
|
||||
import importlib
|
||||
import sys
|
||||
|
||||
# -------------------
|
||||
# Character Detection
|
||||
# -------------------
|
||||
|
||||
|
||||
def _resolve_char_detection():
|
||||
"""Find supported character detection libraries."""
|
||||
chardet = None
|
||||
for lib in ("chardet", "charset_normalizer"):
|
||||
if chardet is None:
|
||||
try:
|
||||
chardet = importlib.import_module(lib)
|
||||
except ImportError:
|
||||
pass
|
||||
return chardet
|
||||
|
||||
|
||||
chardet = _resolve_char_detection()
|
||||
|
||||
# -------
|
||||
# Pythons
|
||||
# -------
|
||||
|
||||
# Syntax sugar.
|
||||
_ver = sys.version_info
|
||||
|
||||
#: Python 2.x?
|
||||
is_py2 = _ver[0] == 2
|
||||
|
||||
#: Python 3.x?
|
||||
is_py3 = _ver[0] == 3
|
||||
|
||||
# json/simplejson module import resolution
|
||||
has_simplejson = False
|
||||
try:
|
||||
import simplejson as json
|
||||
|
||||
has_simplejson = True
|
||||
except ImportError:
|
||||
import json
|
||||
|
||||
if has_simplejson:
|
||||
from simplejson import JSONDecodeError
|
||||
else:
|
||||
from json import JSONDecodeError
|
||||
|
||||
# Keep OrderedDict for backwards compatibility.
|
||||
from collections import OrderedDict
|
||||
from collections.abc import Callable, Mapping, MutableMapping
|
||||
from http import cookiejar as cookielib
|
||||
from http.cookies import Morsel
|
||||
from io import StringIO
|
||||
|
||||
# --------------
|
||||
# Legacy Imports
|
||||
# --------------
|
||||
from urllib.parse import (
|
||||
quote,
|
||||
quote_plus,
|
||||
unquote,
|
||||
unquote_plus,
|
||||
urldefrag,
|
||||
urlencode,
|
||||
urljoin,
|
||||
urlparse,
|
||||
urlsplit,
|
||||
urlunparse,
|
||||
)
|
||||
from urllib.request import (
|
||||
getproxies,
|
||||
getproxies_environment,
|
||||
parse_http_list,
|
||||
proxy_bypass,
|
||||
proxy_bypass_environment,
|
||||
)
|
||||
|
||||
builtin_str = str
|
||||
str = str
|
||||
bytes = bytes
|
||||
basestring = (str, bytes)
|
||||
numeric_types = (int, float)
|
||||
integer_types = (int,)
|
||||
@@ -1,134 +0,0 @@
|
||||
"""Module containing bug report helper(s)."""
|
||||
|
||||
import json
|
||||
import platform
|
||||
import ssl
|
||||
import sys
|
||||
|
||||
import idna
|
||||
import urllib3
|
||||
|
||||
from . import __version__ as requests_version
|
||||
|
||||
try:
|
||||
import charset_normalizer
|
||||
except ImportError:
|
||||
charset_normalizer = None
|
||||
|
||||
try:
|
||||
import chardet
|
||||
except ImportError:
|
||||
chardet = None
|
||||
|
||||
try:
|
||||
from urllib3.contrib import pyopenssl
|
||||
except ImportError:
|
||||
pyopenssl = None
|
||||
OpenSSL = None
|
||||
cryptography = None
|
||||
else:
|
||||
import cryptography
|
||||
import OpenSSL
|
||||
|
||||
|
||||
def _implementation():
|
||||
"""Return a dict with the Python implementation and version.
|
||||
|
||||
Provide both the name and the version of the Python implementation
|
||||
currently running. For example, on CPython 3.10.3 it will return
|
||||
{'name': 'CPython', 'version': '3.10.3'}.
|
||||
|
||||
This function works best on CPython and PyPy: in particular, it probably
|
||||
doesn't work for Jython or IronPython. Future investigation should be done
|
||||
to work out the correct shape of the code for those platforms.
|
||||
"""
|
||||
implementation = platform.python_implementation()
|
||||
|
||||
if implementation == "CPython":
|
||||
implementation_version = platform.python_version()
|
||||
elif implementation == "PyPy":
|
||||
implementation_version = "{}.{}.{}".format(
|
||||
sys.pypy_version_info.major,
|
||||
sys.pypy_version_info.minor,
|
||||
sys.pypy_version_info.micro,
|
||||
)
|
||||
if sys.pypy_version_info.releaselevel != "final":
|
||||
implementation_version = "".join(
|
||||
[implementation_version, sys.pypy_version_info.releaselevel]
|
||||
)
|
||||
elif implementation == "Jython":
|
||||
implementation_version = platform.python_version() # Complete Guess
|
||||
elif implementation == "IronPython":
|
||||
implementation_version = platform.python_version() # Complete Guess
|
||||
else:
|
||||
implementation_version = "Unknown"
|
||||
|
||||
return {"name": implementation, "version": implementation_version}
|
||||
|
||||
|
||||
def info():
|
||||
"""Generate information for a bug report."""
|
||||
try:
|
||||
platform_info = {
|
||||
"system": platform.system(),
|
||||
"release": platform.release(),
|
||||
}
|
||||
except OSError:
|
||||
platform_info = {
|
||||
"system": "Unknown",
|
||||
"release": "Unknown",
|
||||
}
|
||||
|
||||
implementation_info = _implementation()
|
||||
urllib3_info = {"version": urllib3.__version__}
|
||||
charset_normalizer_info = {"version": None}
|
||||
chardet_info = {"version": None}
|
||||
if charset_normalizer:
|
||||
charset_normalizer_info = {"version": charset_normalizer.__version__}
|
||||
if chardet:
|
||||
chardet_info = {"version": chardet.__version__}
|
||||
|
||||
pyopenssl_info = {
|
||||
"version": None,
|
||||
"openssl_version": "",
|
||||
}
|
||||
if OpenSSL:
|
||||
pyopenssl_info = {
|
||||
"version": OpenSSL.__version__,
|
||||
"openssl_version": f"{OpenSSL.SSL.OPENSSL_VERSION_NUMBER:x}",
|
||||
}
|
||||
cryptography_info = {
|
||||
"version": getattr(cryptography, "__version__", ""),
|
||||
}
|
||||
idna_info = {
|
||||
"version": getattr(idna, "__version__", ""),
|
||||
}
|
||||
|
||||
system_ssl = ssl.OPENSSL_VERSION_NUMBER
|
||||
system_ssl_info = {"version": f"{system_ssl:x}" if system_ssl is not None else ""}
|
||||
|
||||
return {
|
||||
"platform": platform_info,
|
||||
"implementation": implementation_info,
|
||||
"system_ssl": system_ssl_info,
|
||||
"using_pyopenssl": pyopenssl is not None,
|
||||
"using_charset_normalizer": chardet is None,
|
||||
"pyOpenSSL": pyopenssl_info,
|
||||
"urllib3": urllib3_info,
|
||||
"chardet": chardet_info,
|
||||
"charset_normalizer": charset_normalizer_info,
|
||||
"cryptography": cryptography_info,
|
||||
"idna": idna_info,
|
||||
"requests": {
|
||||
"version": requests_version,
|
||||
},
|
||||
}
|
||||
|
||||
|
||||
def main():
|
||||
"""Pretty-print the bug information as JSON."""
|
||||
print(json.dumps(info(), sort_keys=True, indent=2))
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
main()
|
||||
@@ -1,23 +0,0 @@
|
||||
import sys
|
||||
|
||||
from .compat import chardet
|
||||
|
||||
# This code exists for backwards compatibility reasons.
|
||||
# I don't like it either. Just look the other way. :)
|
||||
|
||||
for package in ("urllib3", "idna"):
|
||||
locals()[package] = __import__(package)
|
||||
# This traversal is apparently necessary such that the identities are
|
||||
# preserved (requests.packages.urllib3.* is urllib3.*)
|
||||
for mod in list(sys.modules):
|
||||
if mod == package or mod.startswith(f"{package}."):
|
||||
sys.modules[f"requests.packages.{mod}"] = sys.modules[mod]
|
||||
|
||||
if chardet is not None:
|
||||
target = chardet.__name__
|
||||
for mod in list(sys.modules):
|
||||
if mod == target or mod.startswith(f"{target}."):
|
||||
imported_mod = sys.modules[mod]
|
||||
sys.modules[f"requests.packages.{mod}"] = imported_mod
|
||||
mod = mod.replace(target, "chardet")
|
||||
sys.modules[f"requests.packages.{mod}"] = imported_mod
|
||||
@@ -1,128 +0,0 @@
|
||||
r"""
|
||||
The ``codes`` object defines a mapping from common names for HTTP statuses
|
||||
to their numerical codes, accessible either as attributes or as dictionary
|
||||
items.
|
||||
|
||||
Example::
|
||||
|
||||
>>> import requests
|
||||
>>> requests.codes['temporary_redirect']
|
||||
307
|
||||
>>> requests.codes.teapot
|
||||
418
|
||||
>>> requests.codes['\o/']
|
||||
200
|
||||
|
||||
Some codes have multiple names, and both upper- and lower-case versions of
|
||||
the names are allowed. For example, ``codes.ok``, ``codes.OK``, and
|
||||
``codes.okay`` all correspond to the HTTP status code 200.
|
||||
"""
|
||||
|
||||
from .structures import LookupDict
|
||||
|
||||
_codes = {
|
||||
# Informational.
|
||||
100: ("continue",),
|
||||
101: ("switching_protocols",),
|
||||
102: ("processing", "early-hints"),
|
||||
103: ("checkpoint",),
|
||||
122: ("uri_too_long", "request_uri_too_long"),
|
||||
200: ("ok", "okay", "all_ok", "all_okay", "all_good", "\\o/", "✓"),
|
||||
201: ("created",),
|
||||
202: ("accepted",),
|
||||
203: ("non_authoritative_info", "non_authoritative_information"),
|
||||
204: ("no_content",),
|
||||
205: ("reset_content", "reset"),
|
||||
206: ("partial_content", "partial"),
|
||||
207: ("multi_status", "multiple_status", "multi_stati", "multiple_stati"),
|
||||
208: ("already_reported",),
|
||||
226: ("im_used",),
|
||||
# Redirection.
|
||||
300: ("multiple_choices",),
|
||||
301: ("moved_permanently", "moved", "\\o-"),
|
||||
302: ("found",),
|
||||
303: ("see_other", "other"),
|
||||
304: ("not_modified",),
|
||||
305: ("use_proxy",),
|
||||
306: ("switch_proxy",),
|
||||
307: ("temporary_redirect", "temporary_moved", "temporary"),
|
||||
308: (
|
||||
"permanent_redirect",
|
||||
"resume_incomplete",
|
||||
"resume",
|
||||
), # "resume" and "resume_incomplete" to be removed in 3.0
|
||||
# Client Error.
|
||||
400: ("bad_request", "bad"),
|
||||
401: ("unauthorized",),
|
||||
402: ("payment_required", "payment"),
|
||||
403: ("forbidden",),
|
||||
404: ("not_found", "-o-"),
|
||||
405: ("method_not_allowed", "not_allowed"),
|
||||
406: ("not_acceptable",),
|
||||
407: ("proxy_authentication_required", "proxy_auth", "proxy_authentication"),
|
||||
408: ("request_timeout", "timeout"),
|
||||
409: ("conflict",),
|
||||
410: ("gone",),
|
||||
411: ("length_required",),
|
||||
412: ("precondition_failed", "precondition"),
|
||||
413: ("request_entity_too_large", "content_too_large"),
|
||||
414: ("request_uri_too_large", "uri_too_long"),
|
||||
415: ("unsupported_media_type", "unsupported_media", "media_type"),
|
||||
416: (
|
||||
"requested_range_not_satisfiable",
|
||||
"requested_range",
|
||||
"range_not_satisfiable",
|
||||
),
|
||||
417: ("expectation_failed",),
|
||||
418: ("im_a_teapot", "teapot", "i_am_a_teapot"),
|
||||
421: ("misdirected_request",),
|
||||
422: ("unprocessable_entity", "unprocessable", "unprocessable_content"),
|
||||
423: ("locked",),
|
||||
424: ("failed_dependency", "dependency"),
|
||||
425: ("unordered_collection", "unordered", "too_early"),
|
||||
426: ("upgrade_required", "upgrade"),
|
||||
428: ("precondition_required", "precondition"),
|
||||
429: ("too_many_requests", "too_many"),
|
||||
431: ("header_fields_too_large", "fields_too_large"),
|
||||
444: ("no_response", "none"),
|
||||
449: ("retry_with", "retry"),
|
||||
450: ("blocked_by_windows_parental_controls", "parental_controls"),
|
||||
451: ("unavailable_for_legal_reasons", "legal_reasons"),
|
||||
499: ("client_closed_request",),
|
||||
# Server Error.
|
||||
500: ("internal_server_error", "server_error", "/o\\", "✗"),
|
||||
501: ("not_implemented",),
|
||||
502: ("bad_gateway",),
|
||||
503: ("service_unavailable", "unavailable"),
|
||||
504: ("gateway_timeout",),
|
||||
505: ("http_version_not_supported", "http_version"),
|
||||
506: ("variant_also_negotiates",),
|
||||
507: ("insufficient_storage",),
|
||||
509: ("bandwidth_limit_exceeded", "bandwidth"),
|
||||
510: ("not_extended",),
|
||||
511: ("network_authentication_required", "network_auth", "network_authentication"),
|
||||
}
|
||||
|
||||
codes = LookupDict(name="status_codes")
|
||||
|
||||
|
||||
def _init():
|
||||
for code, titles in _codes.items():
|
||||
for title in titles:
|
||||
setattr(codes, title, code)
|
||||
if not title.startswith(("\\", "/")):
|
||||
setattr(codes, title.upper(), code)
|
||||
|
||||
def doc(code):
|
||||
names = ", ".join(f"``{n}``" for n in _codes[code])
|
||||
return "* %d: %s" % (code, names)
|
||||
|
||||
global __doc__
|
||||
__doc__ = (
|
||||
__doc__ + "\n" + "\n".join(doc(code) for code in sorted(_codes))
|
||||
if __doc__ is not None
|
||||
else None
|
||||
)
|
||||
|
||||
|
||||
_init()
|
||||
@@ -1,14 +1,13 @@
|
||||
# -*- coding: utf-8 -*-
|
||||
|
||||
"""Requests test package initialisation."""
|
||||
|
||||
import warnings
|
||||
|
||||
try:
|
||||
from urllib3.exceptions import SNIMissingWarning
|
||||
import urllib3
|
||||
from urllib3.exceptions import SNIMissingWarning
|
||||
|
||||
# urllib3 1.x sets SNIMissingWarning to only go off once,
|
||||
# while this test suite requires it to always fire
|
||||
# so that it occurs during test_requests.test_https_warnings
|
||||
warnings.simplefilter("always", SNIMissingWarning)
|
||||
except ImportError:
|
||||
# urllib3 2.0 removed that warning and errors out instead
|
||||
SNIMissingWarning = None
|
||||
# urllib3 sets SNIMissingWarning to only go off once,
|
||||
# while this test suite requires it to always fire
|
||||
# so that it occurs during test_requests.test_https_warnings
|
||||
warnings.simplefilter('always', SNIMissingWarning)
|
||||
|
||||